需先从 Hugging Face 手动下载 model.ckpt 并放到指定 checkpoints 目录才能推理;T2V 与 I2V 模型需分别下载到 base_512_v2 和 i2v_512_v1 目录;项目仅限个人/研究/非商业用途
VideoCrafter
AILab-CVC更新放缓开箱即用的视频扩散模型工具箱,支持文生视频和图生视频,重点解决高质量视频训练数据不足的问题。
VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models
VideoCrafter1发布于 2024-01-17 11:39 UTC5,114star +2 / 7 天415fork同步于 2026-11-10 11:36 UTC
conda create -n videocrafter python=3.8.5
conda activate videocrafter
pip install -r requirements.txt 硬件要求按 README 说明
README 未说明显存要求或 GPU 型号,仅建议用 Anaconda 创建 Python 3.8.5 环境
开源视频生成与编辑工具箱,提供文生视频和图生视频扩散模型
开箱即用的视频扩散模型工具箱,支持文生视频和图生视频,重点解决高质量视频训练数据不足的问题。
核心能力
- 支持通用文生视频生成,输入文本描述产出视频
- 支持通用图生视频生成,将静态图片动画化
- 提供 320x512 的 VideoCrafter2 检查点
- 附带本地 Gradio 演示界面
- 代码基于 Stable Diffusion 构建
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- VideoCrafter1最新正式版2024-01-17 · 2024-01-17 11:39 UTC
VideoCrafter1 Complete Version
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models

🔥🔥 Our dedicated high-resolution I2V model is released at: :point_right:DynamiCrafter!!!
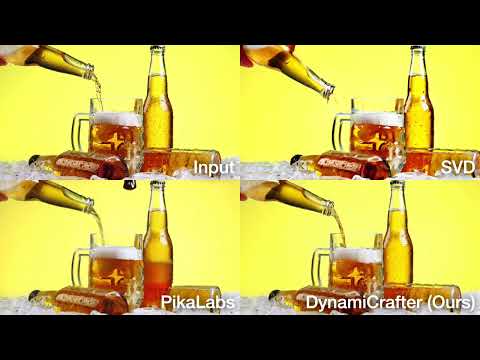
🔥The VideoCrafter2 Large improvements over VideoCrafter1 with limited data. Better Motion, Better Concept Combination!!!
Please Join us and create your own film on Discord/Floor33.
🎥 Exquisite film, produced by VideoCrafter2, directed by Human
🔆 Introduction
🤗🤗🤗 VideoCrafter is an open-source video generation and editing toolbox for crafting video content.
It currently includes the Text2Video and Image2Video models:
1. Generic Text-to-video Generation
Click the GIF to access the high-resolution video.
2. Generic Image-to-video Generation
:boom: You are highly recommended to try our dedicated I2V model DynamiCrafter: Higher resolution, Better Dynamics, More Coherence!!!
📝 Changelog
-
[2024.02.05]: 🔥🔥 Release new I2V model with the resolution of 640x1024 of VideoCrafter1/DynamiCrafter.
-
[2024.01.26]: Release the 512x320 checkpoint of VideoCrafter2.
-
[2024.01.18]: Release the VideoCrafter2 and Tech Report!
-
[2023.10.30]: Release VideoCrafter1 Technical Report!
-
[2023.10.13]: Release the VideoCrafter1, High Quality Video Generation!
-
[2023.08.14]: Release a new version of VideoCrafter on Discord/Floor33. Please join us to create your own film!
-
[2023.04.18]: Release a VideoControl model with most of the watermarks removed!
-
[2023.04.05]: Release pretrained Text-to-Video models, VideoLora models, and inference code.
⏳ Models
| T2V-Models | Resolution | Checkpoints |
|---|---|---|
| VideoCrafter2 | 320x512 | Hugging Face |
| VideoCrafter1 | 576x1024 | Hugging Face |
| VideoCrafter1 | 320x512 | Hugging Face |
| I2V-Models | Resolution | Checkpoints |
|---|---|---|
| VideoCrafter1 | 640x1024 | Hugging Face |
| VideoCrafter1 | 320x512 | Hugging Face |
⚙️ Setup
1. Install Environment via Anaconda (Recommended)
conda create -n videocrafter python=3.8.5
conda activate videocrafter
pip install -r requirements.txt
💫 Inference
1. Text-to-Video
- Download pretrained T2V models via Hugging Face, and put the
model.ckptincheckpoints/base_512_v2/model.ckpt. - Input the following commands in terminal.
sh scripts/run_text2video.sh
2. Image-to-Video
- Download pretrained I2V models via Hugging Face, and put the
model.ckptincheckpoints/i2v_512_v1/model.ckpt. - Input the following commands in terminal.
sh scripts/run_image2video.sh
3. Local Gradio demo
- Download the pretrained T2V and I2V models and put them in the corresponding directory according to the previous guidelines.
- Input the following commands in terminal.
python gradio_app.py
📋 Technical Report
😉 VideoCrafter2 Tech report: VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models
😉 VideoCrafter1 Tech report: VideoCrafter1: Open Diffusion Models for High-Quality Video Generation
😉 Citation
The technical report is currently unavailable as it is still in preparation. You can cite the paper of our image-to-video model and related base model.
@misc{chen2024videocrafter2,
      title={VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models},
      author={Haoxin Chen and Yong Zhang and Xiaodong Cun and Menghan Xia and Xintao Wang and Chao Weng and Ying Shan},
      year={2024},
      eprint={2401.09047},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}

@misc{chen2023videocrafter1,
      title={VideoCrafter1: Open Diffusion Models for High-Quality Video Generation},
      author={Haoxin Chen and Menghan Xia and Yingqing He and Yong Zhang and Xiaodong Cun and Shaoshu Yang and Jinbo Xing and Yaofang Liu and Qifeng Chen and Xintao Wang and Chao Weng and Ying Shan},
      year={2023},
      eprint={2310.19512},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}

@article{xing2023dynamicrafter,
      title={DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors},
      author={Jinbo Xing and Menghan Xia and Yong Zhang and Haoxin Chen and Xintao Wang and Tien-Tsin Wong and Ying Shan},
      year={2023},
      eprint={2310.12190},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}

@article{he2022lvdm,
      title={Latent Video Diffusion Models for High-Fidelity Long Video Generation},
      author={Yingqing He and Tianyu Yang and Yong Zhang and Ying Shan and Qifeng Chen},
      year={2022},
      eprint={2211.13221},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
🤗 Acknowledgements
Our codebase builds on Stable Diffusion. Thanks the authors for sharing their awesome codebases!
📢 Disclaimer
We develop this repository for RESEARCH purposes, so it can only be used for personal/research/non-commercial purposes.
Open-Sora
hpcaitech·Python
开源视频生成模型,用高效架构和训练方案降低高质量视频制作门槛,让普通开发者也能训练和部署文生视频模型。
视频生成+4视频生成
29921+23.1kv1.32026-04-09 01:52 UTC

Wan2.1
Wan-Video·Python
开源的大规模视频生成模型,支持高质量文生视频,为 AIGC 视频创作提供可用的生成能力。
视频生成+4视频生成
17413+114.0k2026-03-05 09:38 UTC
FramePack
lllyasviel·Python
让视频扩散模型在普通显卡上也能跑起来,通过帧打包技术大幅降低显存占用,实现实用的长视频生成。
视频生成+4视频生成
17351+61.7kwindows2025-10-16 01:28 UTC
CogVideo
zai-org·Python
开源文生视频和图生视频模型,CogVideoX 支持从文本或图片生成视频,适合搭建视频生成推理服务。
视频生成+4视频生成
13190+41.4kv1.02025-11-04 11:19 UTC