Full Changelog: https://github.com/OpenMined/PySyft/compare/v0.9.6b5...v0.9.6b6
PySyft
OpenMinedApache-2.0活跃维护在数据不离开对方服务器的前提下做数据科学,通过联邦学习、安全计算和密码学技术实现隐私保护建模。
Perform data science on data that remains in someone else's server
v0.9.6b6发布于 2025-04-13 12:44 UTC10,053star2,014fork同步于 2026-11-10 05:29 UTC
uv pip install "syft>=0.10.0" "syft-rds>=0.6.0"
uv pip install "syft>=0.10.0" "syft-rds>=0.6.0" "syft-bg>=0.3.12"
uv pip install -e . 硬件要求
README 没有说明硬件要求。
项目说明
这个项目的说明还在生成中,先参考下面「最近发版」和 README。
- v0.9.6b6pre-release最新正式版2025-04-13 · 2025-04-13 12:44 UTC
- v0.9.6b5pre-release2025-03-30 · 2025-03-30 12:39 UTC
查看更新说明
Full Changelog: https://github.com/OpenMined/PySyft/compare/v0.9.6b4...v0.9.6b5
- v0.9.6b4pre-release2025-03-23 · 2025-03-23 12:41 UTC
查看更新说明
Full Changelog: https://github.com/OpenMined/PySyft/compare/v0.9.6b3...v0.9.6b4
- v0.9.6b3pre-release2025-03-16 · 2025-03-16 12:40 UTC
查看更新说明
Full Changelog: https://github.com/OpenMined/PySyft/compare/v0.9.6b2...v0.9.6b3
- v0.9.6b2pre-release2025-02-23 · 2025-02-23 12:40 UTC
查看更新说明
Full Changelog: https://github.com/OpenMined/PySyft/compare/v0.9.6b1...v0.9.6b2
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
PySyft v2
syft0.10+ is the successor ofsyft-client.syftis the sync engine (import syft as sy); datasets and jobs live insyft-rds(from syft_rds import login_do, login_ds). If you depend on the legacy PySyft ≤0.9 API, pinsyft<0.10.



PySyft allows data scientists run computations which are reviewed and run by data owners on private data. Users securely communicate through cloud storage their organizations already use (Google Drive, Microsoft 365, etc.) or serverless p2p chnannels like webRTC. No new infrastructure required and all communication between be peers can be signed and encrypted.
Docs
- Workflow — End-to-end privacy-preserving data analysis workflow
- API Reference — All public client methods and properties
- Authentication & Setup — Google Cloud OAuth setup for local/Jupyter usage
- Background Services — Email notifications, running api calls, and TUI dashboard
- Connections — How the Google Drive transport layer works
- Permissions - Permissions for syft
- Enclaves - Enclaves with syft
Tutorials
- Double blind LLM evals in enclaves — a researcher evaluates a private model on a private benchmark inside an enclave, with neither side revealing its assets
- LLM user logs analysis — submit jobs against private LLM user logs and get back only the approved results (data owner notebook)
Features
- Privacy-preserving — Private data never leaves the data owner's machine; only approved results are shared
- Transport-agnostic — Works over Google Drive today, extensible to any file-based transport
- Offline-first — Full functionality even when peers are offline; changes sync when connectivity resumes
- Peer-to-peer with explicit auth — Data owners must approve each collaborator before any data flows
- Approved job execution — Jobs only run after approval from the data owner(s), the approval includes access to specific private data
- Dataset sharing with mock/private separation — Data scientists explore mock data, then submit jobs that run on the real thing
Quick Start
Before you start: this quick start assumes Google Colab, where login is a browser pop-up and works out of the box. On a local machine or in Jupyter you first need a Google Cloud OAuth token: follow docs/auth.md (about 15 minutes the first time), then pass it as token_path to login_do / login_ds. Each role needs its own Google account.
We assume two parties here, a Data Owner (DO) and a Data Scientist (DS), the DS wants to do an analysis on private data of the DO. For brevity we use code blocks, but in practice these would be distributed: each party executes their code on their own machine.
# Data scientist
uv pip install "syft>=0.10.0" "syft-rds>=0.6.0"
# Data owner (adds the background services)
uv pip install "syft>=0.10.0" "syft-rds>=0.6.0" "syft-bg>=0.3.12"
import syft as sy                          # sync engine + helpers (resolve_dataset_file_path, bug_report, ...)
from syft_rds import login_do, login_ds    # datasets + jobs (the Remote Data Science client)
# Colab: login is a browser pop-up, nothing to set up
# Local / Jupyter: create a token first, see docs/auth.md
do = login_do(email="[email protected]")  # local: add token_path="token_do.json"
ds = login_ds(email="[email protected]")  # second account; local: token_path="token_ds.json"

# Peer request & approve
ds.add_peer("[email protected]")
do.approve_peer_request("[email protected]")

# Create & sync dataset
do.create_dataset(
    name="census",
    mock_path="mock.txt", # create this and add some text
    private_path="private.txt", # create this and add some text
    users=["[email protected]"],
)
do.sync(); ds.sync()
datasets = ds.datasets.get_all()
Write an analysis.py that reads the dataset and produces a result in our case this is just the length of the data. Inside a job, resolve_dataset_file_path automatically resolves to the private data:
# analysis.py
import json
import syft as sy

data_path = sy.resolve_dataset_file_path("census")
with open(data_path, "r") as f:
    data = f.read()

with open("outputs/result.json", "w") as f:
    json.dump({"length": len(data)}, f)
Submit the job and retrieve results:
# Submit job
ds.submit_python_job(
    user="[email protected]",
    code_path="analysis.py",
    job_name="analysis",
)
ds.sync(); do.sync()

# Data owner Approves & runs job
do.jobs["[email protected]"]["analysis"].approve()
do.process_approved_jobs(share_outputs_with_submitter=True)
do.sync(); ds.sync()
result = open(ds.jobs["[email protected]"]["analysis"].output_paths[0]).read()
Packages
| Package | Description |
|---|---|
syft-rds | Remote Data Science client: login_do/login_ds, datasets, jobs |
syft-datasets | Dataset management and sharing |
syft-job | Job submission and execution |
syft-permissions | Permission system for Syft datasites |
syft-perms | User-facing permission API for Syft datasites |
syft-bg | Background services TUI dashboard for SyftBox |
syft-notebook-ui | Jupyter notebook display utilities |
Development
# Install in development mode
uv pip install -e .

# Run tests
just test-unit          # Unit tests (fast, mocked)
just test-integration   # Integration tests (slow, real API)
Built by OpenMined — building open-source technology for privacy-preserving data science and AI.
Support
For questions about PySyft, reach out via #support on Slack.
Community
Supported by the OpenMined Foundation, the OpenMined Community is an online network of over 17,000 technologists, researchers, and industry professionals keen to unlock 1000x more data in every scientific field and industry.
Contributors
OpenMined and Syft appreciates all contributors, if you would like to fix a bug or suggest a new feature, please reach out via Github or Slack!
About OpenMined
OpenMined is a non-profit foundation creating technology infrastructure that helps researchers get answers from data without needing a copy or direct access. Our community of technologists is building Syft.
Supporters
License
Apache License 2.0 Person icons created by Freepik - Flaticon

pyro
pyro-ppl·Python
基于 PyTorch 的深度概率编程库,用 Python 写贝叶斯模型,支持变分推断和 MCMC,适合做不确定性建模与生成模型研究。
概率编程+4科学计算 / 生物医药
9074+11.0k1.9.22026-10-05 18:42 UTC
MONAI
Project-MONAI·Python
基于 PyTorch 的医学影像深度学习工具包,提供数据加载、预处理、网络结构和评估等组件,帮研究者快速搭建医疗影像 AI 流程。
医学影像+4科学计算 / 生物医药
8830+41.7k1.6.12026-11-06 17:33 UTC
alphafold3-pytorch
lucidrains·Python
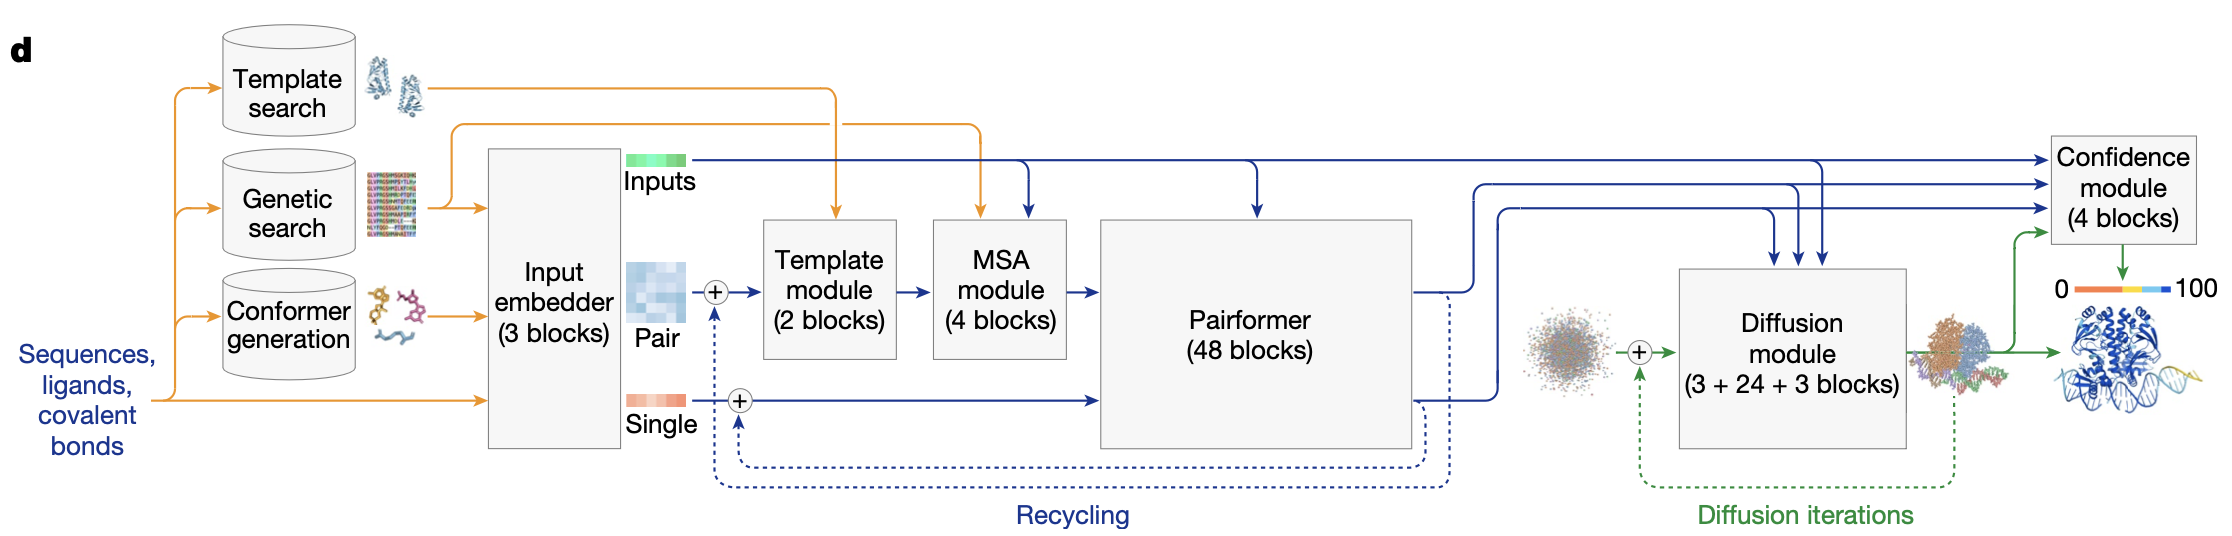
用 PyTorch 复现 DeepMind AlphaFold 3 的蛋白质结构预测模型,包含注意力机制与去噪扩散模块,方便研究和二次开发。
蛋白质结构预测+4科学计算 / 生物医药
17022330.7.122026-08-10 02:16 UTC