需先安装 BeautifulSoup4、requests、markdownify 等依赖,直接跑会报导入错误;输出目录由 -b 指定,未指定时注意默认落盘位置;爬取范围受 domain-match 与 base-path-match 开关影响,默认行为可能漏抓同域其他路径
markdown-crawler
paulpierreMIT更新放缓多线程网页爬虫,递归抓取整站并把每个页面转成 Markdown 文件,为 LLM RAG 准备干净的语料。
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page, designed for LLM RAG
v0.0.9发布于 2026-06-26 14:23 UTC480star53fork同步于 2026-11-07 07:29 UTC
pip install markdown-crawler
markdown-crawler -t 5 -d 3 -b ./markdown https://en.wikipedia.org/wiki/Morty_Smith 硬件要求按 README 说明
README 未说明,仅要求 Python 3.x 及 BeautifulSoup4、requests、markdownify 依赖,纯 CPU 运行
多线程递归爬站并把每页转成 Markdown 文件,专为 LLM RAG 文档预处理设计
多线程网页爬虫,递归抓取整站并把每个页面转成 Markdown 文件,为 LLM RAG 准备干净的语料。
核心能力
- 多线程并发爬取,加快整站抓取速度
- 支持断点续爬,从中断处继续抓取
- 可设置最大子级爬取深度
- 用 BeautifulSoup 解析 HTML 并保留表格图片
- 支持排除路径与自定义 Markdown 标题样式
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.0.9最新正式版2026-06-26 · 2026-06-26 14:23 UTC
What's New
This release resolves 6 open issues and introduces several community-requested features.
Fixed
- #7 —
UnicodeEncodeErroron non-ASCII content. All file writes now useencoding='utf-8'. - #8 — Bypass JavaScript checks. A browser-like
User-Agentheader is now sent on allrequests.getcalls. - #10 —
target_contentCSS selector handling. Nullhreflinks are now skipped inget_target_links. - #11 —
UnboundLocalErroringet_target_contentwhen no tags are found.main_contentis now initialized toNoneand checked beforestr()conversion.
Added
- #9 —
exclude_pathsparameter for URL filtering. Available incrawl(),get_target_links(),worker(),md_crawl(), and the CLI (-x/--exclude-paths). - #20 — Configurable
heading_stylefor markdownify (ATX,ATX_CLOSED,UNDERLINE,SETEXT). CLI flag:-s/--heading-style. - #17 — Proper
dependenciesinpyproject.toml(beautifulsoup4,markdownify,requests) enablinguvxsupport out of the box. - Comprehensive test suite — 60 tests with 95% coverage across
__init__.py(96%) andcli.py(88%). devoptional dependencies (pytest,pytest-cov) for contributors.
Changed
- Minimum Python version bumped to 3.8.
pyproject.tomlnow uses[project.scripts]instead of[tool.poetry.scripts].
Full changelog: https://github.com/paulpierre/markdown-crawler/blob/main/CHANGELOG.md
- #7 —
- markdown-crawler-0.0.8Markdown Crawler 0.0.82023-10-30 · 2023-10-30 11:45 UTC
查看更新说明
- Markdown Crawler 0.0.8
- Added link inclusion/exclusion support
- Migrated to markdownify for proper table support
- Bug fixes
- markdown-crawler-0.0.4markdown-crawl-0.0.42023-10-24 · 2023-10-24 20:06 UTC
查看更新说明
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
                |                                     |
 __ `__ \    _` |        __|   __|   _` | \ \  \   /  |   _ \   __|
 |   |   |  (   |       (     |     (   |  \ \  \ /   |   __/  |
_|  _|  _| \__._|      \___| _|    \__._|   \_/\_/   _| \___| _|

---------------------------------
markdown_crawler - by @paulpierre
---------------------------------
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page
https://github.com/paulpierre
https://x.com/paulpierre
📝 Overview
This is a multithreaded web crawler that crawls a website and creates markdown files for each page. It was primarily created for large language model document parsing to simplify chunking and processing of large documents for RAG use cases. Markdown by nature is human readable and maintains document structure while keeping a small footprint.
✨ Features include
- 🧵 Threading support for faster crawling
- ⏯️ Continue scraping where you left off
- ⏬ Set the max depth of children you wish to crawl
- 📄 Support for tables, images, etc.
- ✅ Validates URLs, HTML, filepaths
- ⚙️ Configure list of valid base paths or base domains
- 🚫 Exclude specific paths from crawling (
--exclude-paths)- 🎨 Configurable markdown heading style (
--heading-style)- 🌐 Browser-like User-Agent to bypass JS checks
- 🍲 Uses BeautifulSoup to parse HTML
- 🪵 Verbose logging option
- 👩💻 Ready-to-go CLI interface
- 🧪 Comprehensive test suite (95% coverage)
📦 What's New in v0.0.9
This release resolves 6 open issues and introduces several community-requested features:
| Issue | Fix |
|---|---|
| #7 | UnicodeEncodeError on non-ASCII content — UTF-8 encoding on all file writes |
| #8 | Bypass JavaScript checks — browser-like User-Agent header on all requests |
| #9 | Exclude paths from crawling — new --exclude-paths / -x CLI flag |
| #10 | target_content CSS selector handling — null href links now skipped |
| #11 | UnboundLocalError fix in get_target_content |
| #17 | Dependencies added to pyproject.toml for uvx support |
| #20 | Configurable heading_style for markdownify (ATX, UNDERLINE, etc.) |
Also includes a comprehensive test suite — 60 tests, 95% coverage. See the CHANGELOG.md for full details.
🏗️ Use cases
- RAG (retrieval augmented generation) - my primary usecase, use this to normalize large documents and chunk by header, pargraph or sentence
- LLM fine-tuning - Create a large corpus of markdown files as a first step and leverage
gpt-3.5-turboorMistral-7Bto extract Q&A pairs - Agent knowledge - Leverage this with autogen for expert agents, for example if you wish to reconstruct the knowledge corpus of a videogame or movie, use this to generate the given expert corpus
- Agent / LLM tools - Use this for online RAG learning so your chatbot continues to learn. Use SERP and scrape + index top N results w/ markdown-crawler
- many more ..
🚀 Get started
If you wish to simply use it in the CLI, you can run the following command:
Install the package
pip install markdown-crawler
Execute the CLI
markdown-crawler -t 5 -d 3 -b ./markdown https://en.wikipedia.org/wiki/Morty_Smith
To run from the github repo, once you have it checked out:
pip install .
markdown-crawler -t 5 -d 3 -b ./markdown https://en.wikipedia.org/wiki/Morty_Smith
Or use the library in your own code:
from markdown_crawler import md_crawl
url = 'https://en.wikipedia.org/wiki/Morty_Smith'
md_crawl(url, max_depth=3, num_threads=5, base_path='markdown')
⚠️ Requirements
- Python 3.x
- BeautifulSoup4
- requests
- markdownify
🔍 Usage
The following arguments are supported
usage: markdown-crawler [-h] [--max-depth MAX_DEPTH] [--num-threads NUM_THREADS] [--base-dir BASE_DIR] [--debug DEBUG]
                  [--target-content TARGET_CONTENT] [--target-links TARGET_LINKS] [--valid-paths VALID_PATHS]
                  [--exclude-paths EXCLUDE_PATHS] [--domain-match DOMAIN_MATCH] [--base-path-match BASE_PATH_MATCH]
                  [--heading-style HEADING_STYLE] [--links ]
                  base_url
📝 Example
Take a look at example.py for an example implementation of the library. In this configuration we set:
max_depthto 3. We will crawl the base URL and 3 levels of childrennum_threadsto 5. We will use 5 parallel(ish) threads to crawl the websitebase_dirtomarkdown. We will save the markdown files in themarkdowndirectoryvalid_pathsan array of valid relative URL paths. We will only crawl pages that are in this list and base pathtarget_contenttodiv#content. We will only crawl pages that have this HTML element using CSS target selectors. You can provide multiple and it will concatenate the resultsis_domain_matchtoFalse. We will only crawl pages that are in the same domain as the base URLis_base_path_matchtoFalse. We will include all URLs in the same domain, even if they don't begin with the base urlis_debugto True. We will print out verbose logging
And when we run it we can view the progress
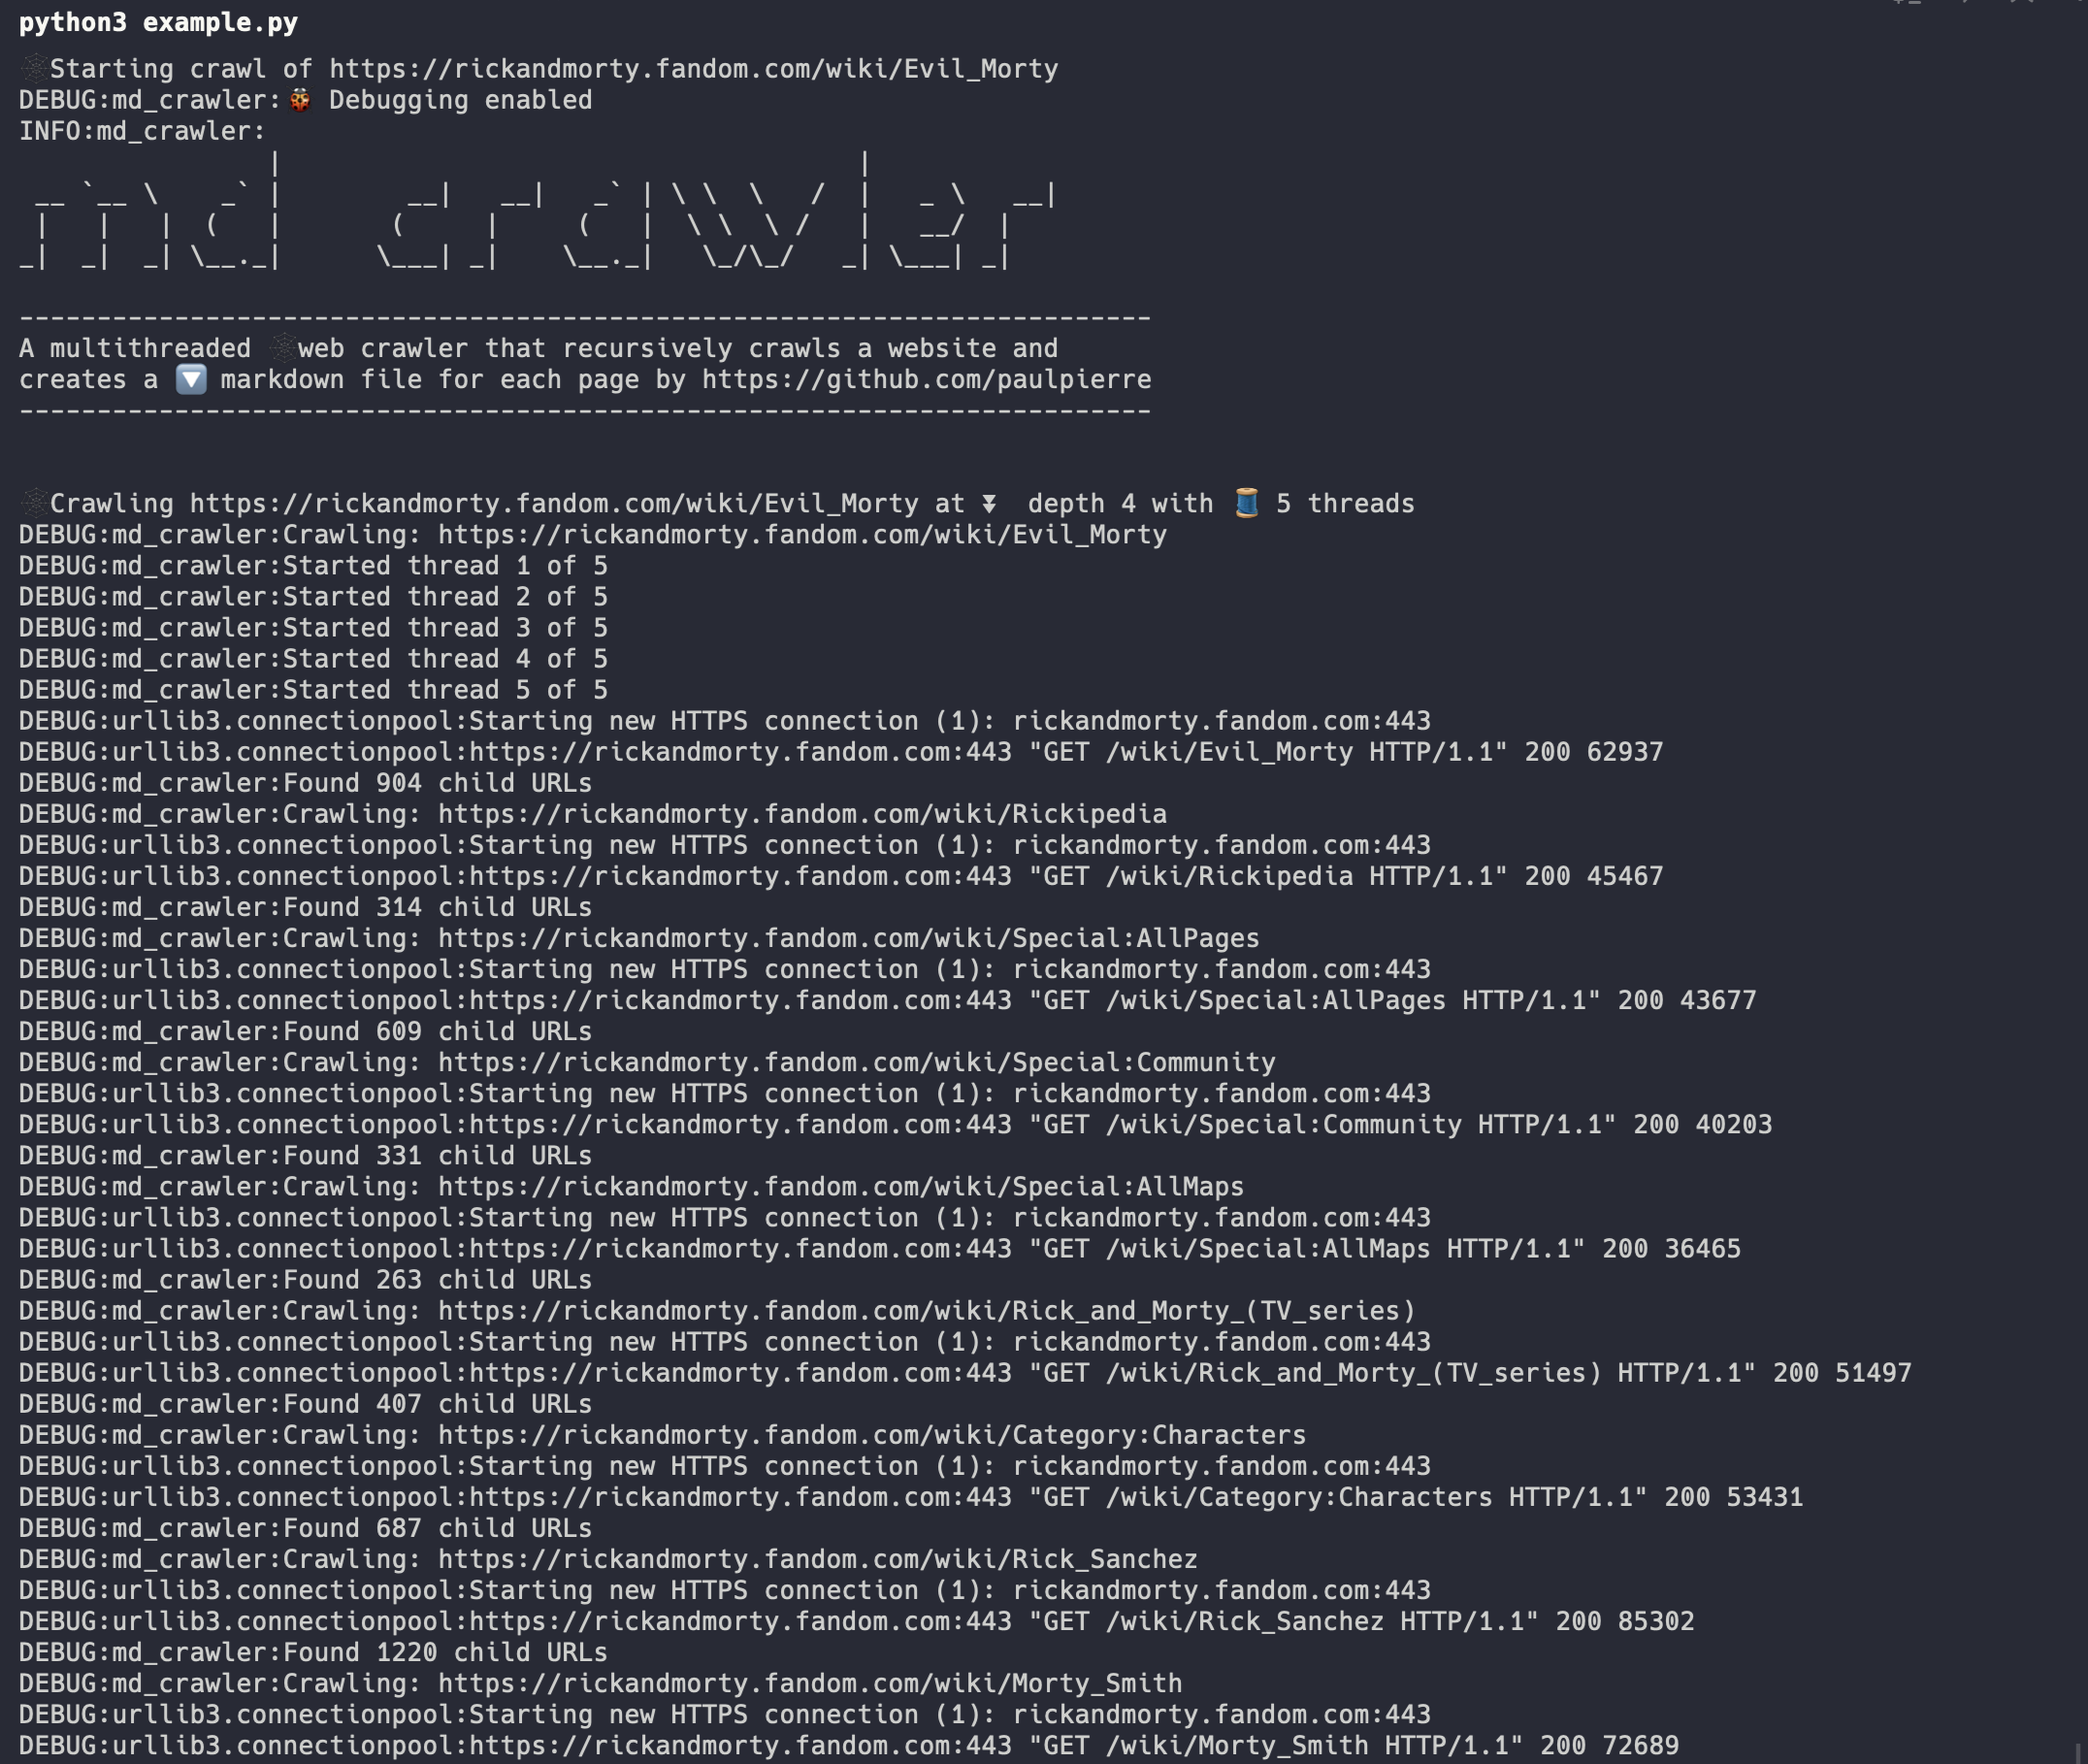
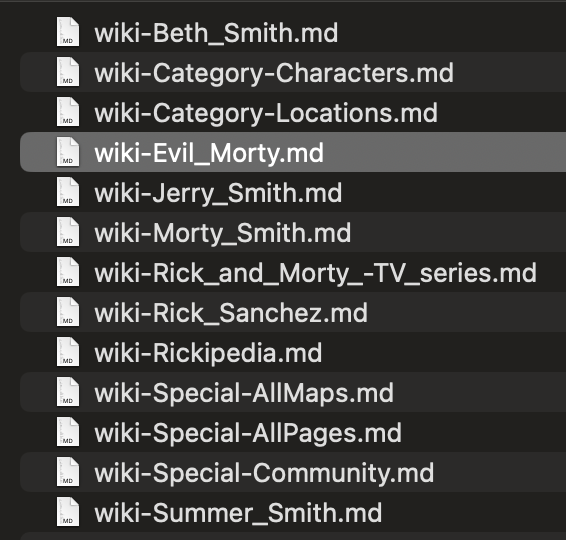
We can see the progress of our files in the markdown directory locally
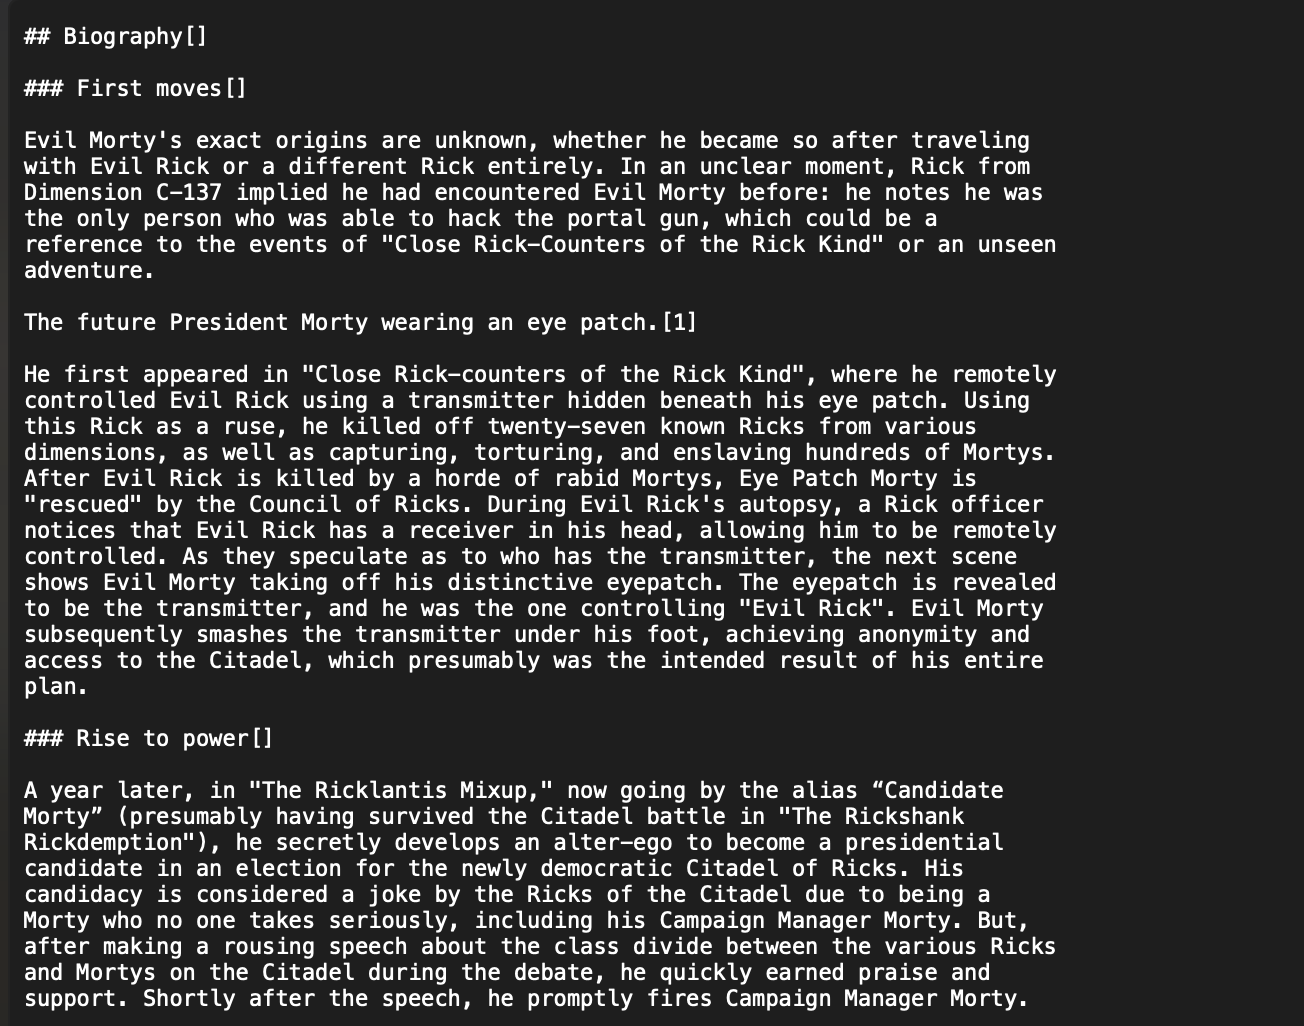
And we can see the contents of the HTML converted to markdown
❤️ Thanks
If you have any issues, please feel free to open an issue or submit a PR. You can reach me via DM on Twitter/X.
- Follow me on Twitter / X
- Give me a ⭐ on Github
⚖️ License
MIT License Copyright (c) 2023 Paul Pierre Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions: The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software. THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
markdownify credits
markdown_crawler makes use of markdownify by Matthew Tretter. The original source code can be found here. It is licensed under the MIT license.
langfuse
langfuse·TypeScript
开源 LLM 应用可观测与评估平台,能追踪调用链路、跑评测实验,帮团队定位问题并持续优化提示词和模型效果。
LLM 可观测+4LLM 可观测
37251+1274.2kv4.77.02026-11-10 11:19 UTC
signoz
SigNoz·TypeScript
基于 OpenTelemetry 的开源可观测性平台,把日志、指标和链路追踪集中到一处,提供 APM、分布式追踪和基础设施监控,帮团队快速定位线上问题。
可观测性+4LLM 可观测
32568+242.6kv0.149.02026-11-10 10:28 UTC

skywalking
apache·Java
分布式系统的应用性能监控平台,支持链路追踪、指标采集和日志分析,帮你在微服务架构下快速定位性能瓶颈。
应用性能监控+4LLM 可观测
24998+46.6kv11.1.02026-11-10 09:54 UTC

jaeger
jaegertracing·Go
CNCF 出品的分布式追踪平台,采集服务调用链路并做可视化分析,帮你在微服务和 LLM 应用里定位延迟与故障根因。
分布式追踪+4LLM 可观测
23393+73.2kv2.23.02026-11-10 06:28 UTC