需 Python 3.11+,且要先手动下载各模型 checkpoint 放到 original_models/ 才能导出;Windows 上 onnxsim 无预编译 wheel,导出并简化需装 [runtime-cpu,export] 或开启长路径支持;SAM3 推理需额外传 --text_prompt 或在 prompt JSON 写 text,否则默认用 "visual" 导致结果不稳定。
samexporter
vietanhdevMIT活跃维护把 SAM、MobileSAM、EfficientSAM、SAM 2/2.1 和 SAM 3 导出成 ONNX 模型,方便在任意平台跑可移植的图像分割,不用绑死原始框架。
Export and run SAM, MobileSAM, EfficientSAM, SAM 2/2.1, and SAM 3 as ONNX for portable image segmentation
v0.5.0发布于 2026-08-30 15:27 UTC433star47fork同步于 2026-11-07 07:30 UTC
pip install torch==2.10.0 torchvision==0.25.0 --index-url https://download.pytorch.org/whl/cpu
pip install "samexporter[runtime-cpu]" 硬件要求按 README 说明
README 未说明显存要求;MobileSAM 标注为在 CPU 上快,安装示例使用 CPU 版 PyTorch,SAM3 导出可用 --device auto 选择设备。
支持 Apple Silicon需要 CUDA支持 ROCm / AMD昇腾 / Ascend
把 SAM、MobileSAM、EfficientSAM、SAM2/2.1、SAM3 导出成 ONNX,用 ONNX Runtime 做可移植图像分割
把 SAM、MobileSAM、EfficientSAM、SAM 2/2.1 和 SAM 3 导出成 ONNX 模型,方便在任意平台跑可移植的图像分割,不用绑死原始框架。
核心能力
- 支持 SAM、MobileSAM、EfficientSAM、SAM2/2.1、SAM3 多系列模型导出
- 把编码器与解码器分别导出为 ONNX,并可生成量化版本
- EfficientSAM 直接复用官方拆分好的 ONNX 模型运行
- SAM3 支持文本提示,以及文本加矩形或点示例的开放词表分割
- 提供统一 inference 命令,按 sam_variant 切换运行时
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.5.0SAMExporter 0.5.0最新正式版2026-08-30 · 2026-08-30 15:27 UTC
SAMExporter 0.5.0 expands portable ONNX support and ships reviewed real-model evidence.
Highlights:
- EfficientSAM-Ti/S and complete MobileSAM encoder/decoder support
- latest pinned official SAM, SAM2/SAM2.1, and SAM3 sources
- corrected SAM1 aspect ratios/colors and SAM2 original-size mask quality
- SAM3 raw-head export, official-style mask NMS, prompt-focused selection, text examples, and flexible instance limits
- provider selection and extras for CPU, CUDA/TensorRT, OpenVINO, DirectML, QNN, CoreML, and other ONNX Runtime builds
- MIT-licensed packaged CLIP tokenizer with no forced CPU runtime dependency
- public validated models: https://huggingface.co/nrl-ai/samexporter-onnx-models
- full-resolution outputs and logs: https://github.com/vietanhdev/samexporter/tree/v0.5.0/visual_results
Validation: 42 tests pass on Python 3.11 and 3.13; real SAM ViT-B, MobileSAM, EfficientSAM-Ti, SAM2.1 Tiny, and SAM3 outputs were visually reviewed.
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
SAMExporter — SAM / EfficientSAM / MobileSAM / SAM2 / SAM3 → ONNX
Export and run Segment Anything, MobileSAM, EfficientSAM, Segment Anything 2 / 2.1, and Segment Anything 3 in ONNX Runtime for portable deployment.

Supported models:
| Model | Prompt types | Notes |
|---|---|---|
| SAM ViT-B / ViT-L / ViT-H | Point, Rectangle | Original Meta SAM |
| SAM ViT-B / ViT-L / ViT-H (quantized) | Point, Rectangle | Smaller, faster variants |
| MobileSAM | Point, Rectangle | Lightweight; fast on CPU |
| EfficientSAM-Ti / S | Point, Rectangle | Apache-2.0; official split ONNX models |
| SAM2 Tiny / Small / Base+ / Large | Point, Rectangle | Meta SAM 2 |
| SAM2.1 Tiny / Small / Base+ / Large | Point, Rectangle | Improved SAM 2 |
| SAM3 ViT-H | Text, Point, Rectangle | Open-vocabulary text-driven segmentation |
Installation
Requires Python 3.11+.
pip install torch==2.10.0 torchvision==0.25.0 --index-url https://download.pytorch.org/whl/cpu
pip install "samexporter[runtime-cpu]"
Note — Windows users: The optional
onnxsimmodel simplifier (used during ONNX export) has no pre-built wheel for Windows. If you plan to export models and want simplification, install with:pip install "samexporter[runtime-cpu,export]"or enable Windows Long Path support before installing.
From source
pip install torch==2.10.0 torchvision==0.25.0 --index-url https://download.pytorch.org/whl/cpu
git clone --recurse-submodules https://github.com/vietanhdev/samexporter
cd samexporter
pip install -e ".[runtime-cpu]"
The source checkout pins the official model repositories as submodules so an
upstream main branch cannot silently change an export:
| Family | Pinned official revision |
|---|---|
| SAM 1 | dca509fe793f601edb92606367a655c15ac00fdf |
| SAM 2 / 2.1 | 2b90b9f5ceec907a1c18123530e92e794ad901a4 |
| SAM 3 | 660a5e9e1b8b4c02c0ad97229b88a09a6e4ff5b7 |
These were the latest upstream main revisions checked on 2026-08-30. Export
commands prefer these checkouts and retain installed-package fallbacks for the
published wheel.
SAM / MobileSAM — Convert to ONNX
1. Download checkpoints
Place checkpoints in original_models/:
original_models/
  sam_vit_b_01ec64.pth
  sam_vit_l_0b3195.pth
  sam_vit_h_4b8939.pth
  mobile_sam.pt
Download links:
2. Export encoder
# SAM ViT-H (most accurate)
python -m samexporter.export_encoder \
    --checkpoint original_models/sam_vit_h_4b8939.pth \
    --output output_models/sam_vit_h_4b8939.encoder.onnx \
    --model-type vit_h \
    --quantize-out output_models/sam_vit_h_4b8939.encoder.quant.onnx \
    --use-preprocess

# SAM ViT-B (fastest)
python -m samexporter.export_encoder \
    --checkpoint original_models/sam_vit_b_01ec64.pth \
    --output output_models/sam_vit_b_01ec64.encoder.onnx \
    --model-type vit_b \
    --quantize-out output_models/sam_vit_b_01ec64.encoder.quant.onnx \
    --use-preprocess
3. Export decoder
python -m samexporter.export_decoder \
    --checkpoint original_models/sam_vit_h_4b8939.pth \
    --output output_models/sam_vit_h_4b8939.decoder.onnx \
    --model-type vit_h \
    --quantize-out output_models/sam_vit_h_4b8939.decoder.quant.onnx \
    --return-single-mask
Remove --return-single-mask to return multiple mask proposals.
Batch convert all SAM models:
bash convert_all_meta_sam.sh
bash convert_mobile_sam.sh
MobileSAM uses the same checkpoint for both halves of the export:
python -m samexporter.export_decoder \
    --checkpoint original_models/mobile_sam.pt \
    --output output_models/mobile_sam/mobile_sam.decoder.onnx \
    --model-type mobile \
    --return-single-mask
4. Run inference
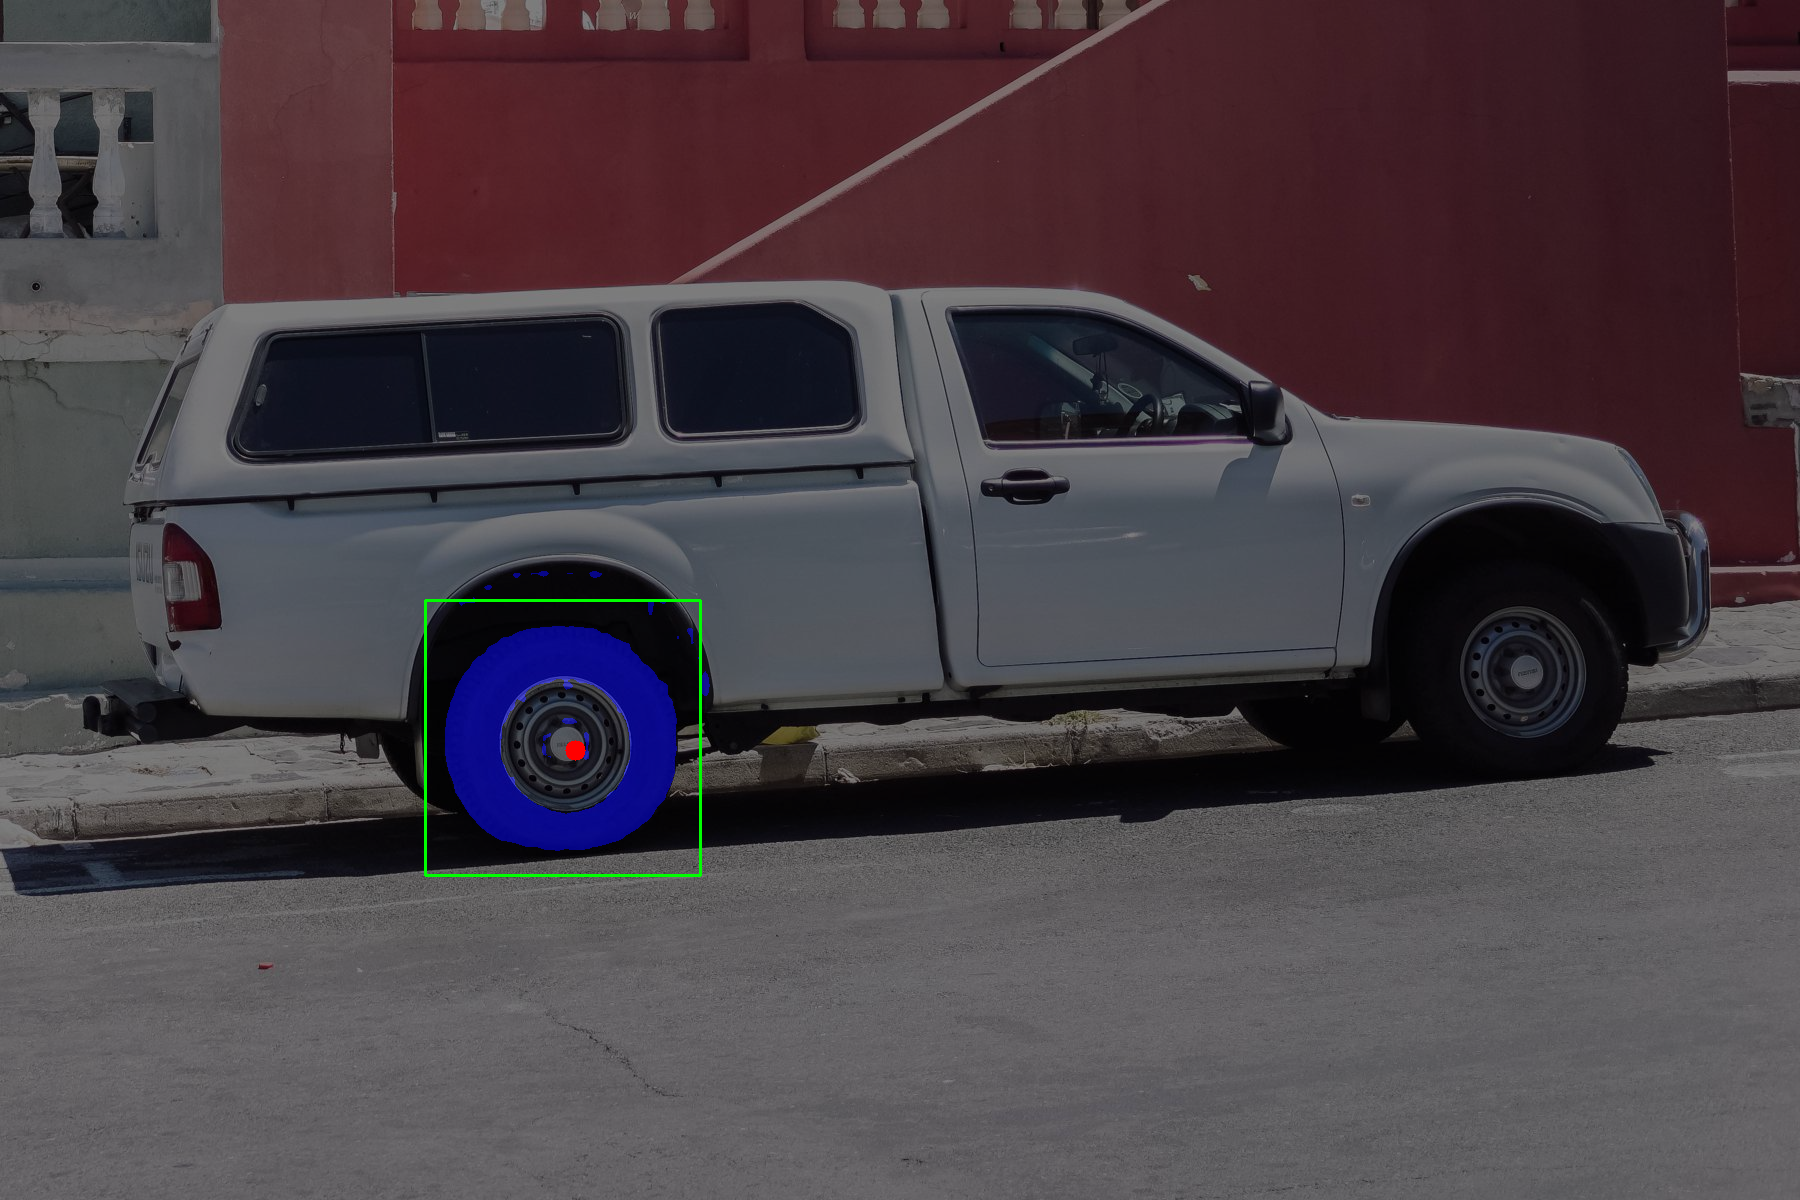
python -m samexporter.inference \
    --encoder_model output_models/sam_vit_h_4b8939.encoder.onnx \
    --decoder_model output_models/sam_vit_h_4b8939.decoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_prompt.json \
    --output output_images/truck.png \
    --show
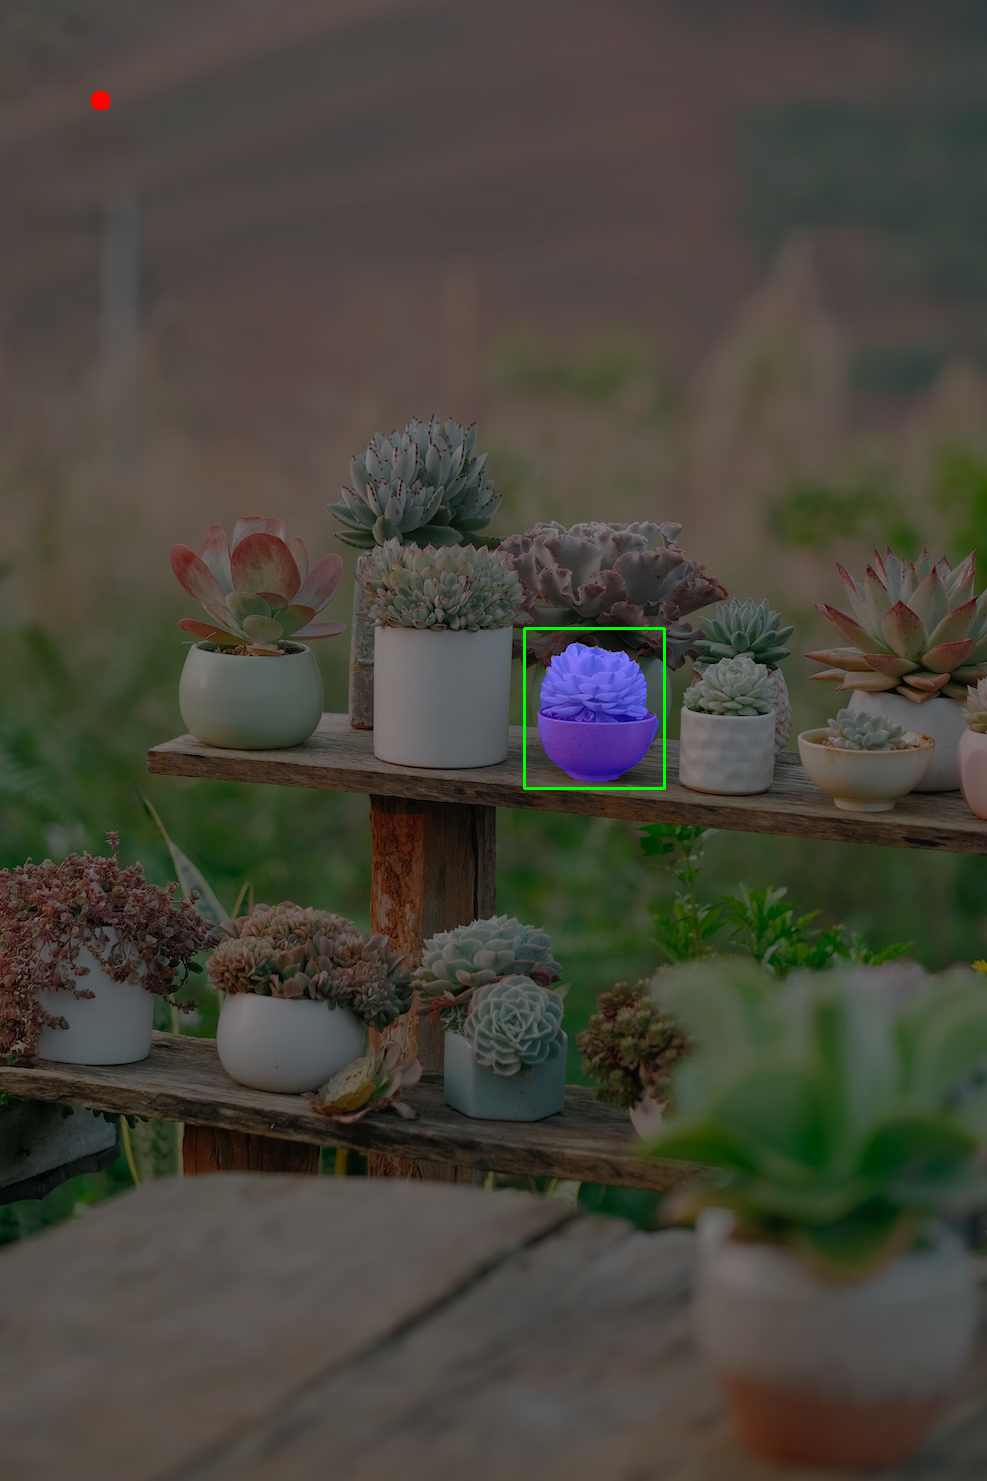
python -m samexporter.inference \
    --encoder_model output_models/sam_vit_h_4b8939.encoder.onnx \
    --decoder_model output_models/sam_vit_h_4b8939.decoder.onnx \
    --image images/plants.png \
    --prompt images/plants_prompt1.json \
    --output output_images/plants_01.png \
    --show
EfficientSAM — Run official ONNX models
EfficientSAM-Ti and EfficientSAM-S use a distinct lightweight architecture, so
select the efficient_sam runtime variant. The upstream project and models are
Apache-2.0 licensed.
Download the Ti encoder and decoder (about 40 MB combined):
mkdir -p output_models/efficient_sam
curl -L https://huggingface.co/yunyangx/EfficientSAM/resolve/main/efficientsam_ti_encoder.onnx \
    -o output_models/efficient_sam/efficientsam_ti_encoder.onnx
curl -L https://huggingface.co/yunyangx/EfficientSAM/resolve/main/efficientsam_ti_decoder.onnx \
    -o output_models/efficient_sam/efficientsam_ti_decoder.onnx
Run point or rectangle inference:
python -m samexporter.inference \
    --sam_variant efficient_sam \
    --encoder_model output_models/efficient_sam/efficientsam_ti_encoder.onnx \
    --decoder_model output_models/efficient_sam/efficientsam_ti_decoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_box.json \
    --output output_images/efficient_sam_truck.png
The same runtime accepts the EfficientSAM-S split ONNX pair by changing the two
model paths to efficientsam_s_encoder.onnx and efficientsam_s_decoder.onnx.
SAM2 / SAM2.1 — Convert to ONNX
1. Download checkpoints
cd original_models && bash download_sam2.sh
Or download manually:
original_models/
  sam2_hiera_tiny.pt
  sam2_hiera_small.pt
  sam2_hiera_base_plus.pt
  sam2_hiera_large.pt
  sam2.1_hiera_tiny.pt
  sam2.1_hiera_small.pt
  sam2.1_hiera_base_plus.pt
  sam2.1_hiera_large.pt
2. Install the pinned SAM2 PyTorch package
SAM2_BUILD_CUDA=0 pip install -e third_party/sam2
Omit SAM2_BUILD_CUDA=0 if you specifically need SAM2's optional CUDA
post-processing extension. It is not required for these image ONNX exports.
3. Export
# Single model example (SAM2 Tiny)
python -m samexporter.export_sam2 \
    --checkpoint original_models/sam2_hiera_tiny.pt \
    --output_encoder output_models/sam2_hiera_tiny.encoder.onnx \
    --output_decoder output_models/sam2_hiera_tiny.decoder.onnx \
    --model_type sam2_hiera_tiny

# SAM2.1 example
python -m samexporter.export_sam2 \
    --checkpoint original_models/sam2.1_hiera_tiny.pt \
    --output_encoder output_models/sam2.1_hiera_tiny.encoder.onnx \
    --output_decoder output_models/sam2.1_hiera_tiny.decoder.onnx \
    --model_type sam2.1_hiera_tiny
Batch convert all SAM2 / SAM2.1 models:
bash convert_all_meta_sam2.sh
4. Run inference
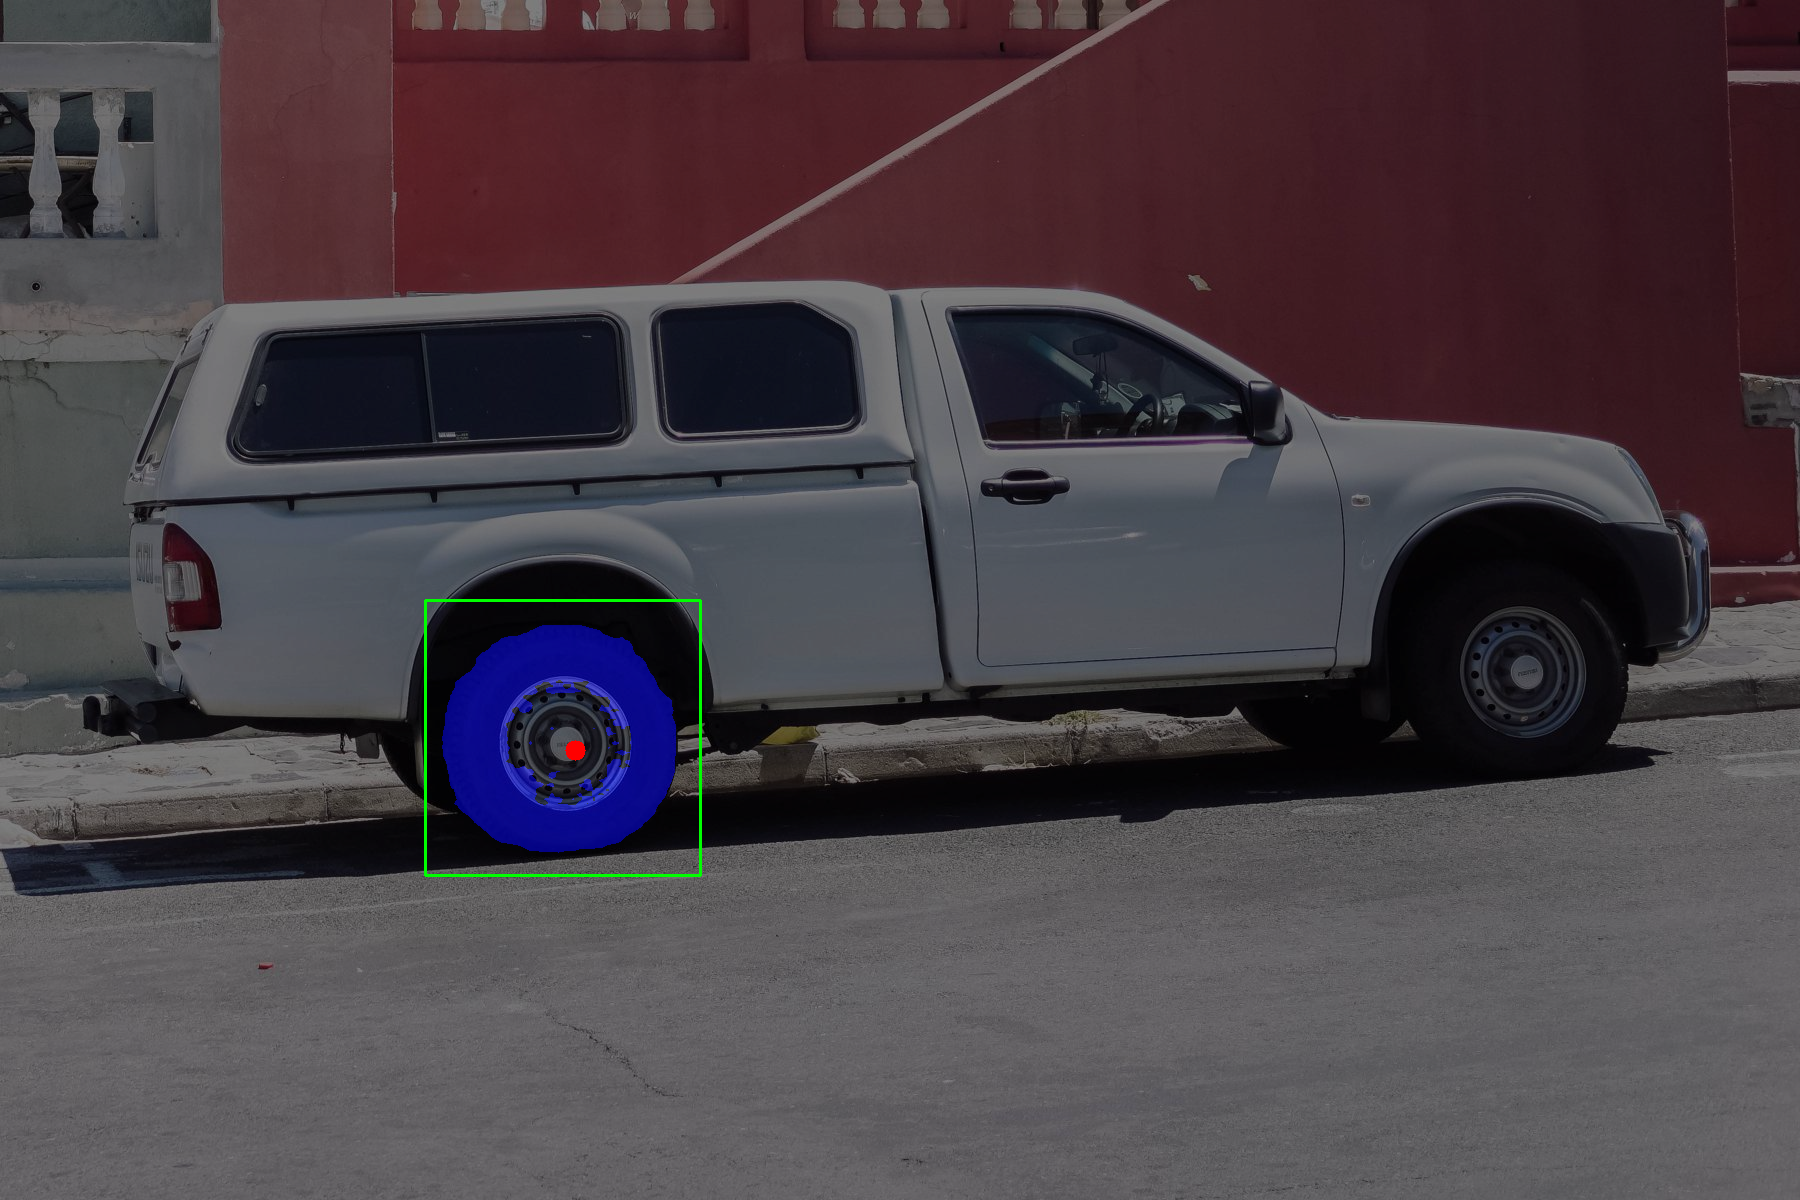
python -m samexporter.inference \
    --encoder_model output_models/sam2_hiera_tiny.encoder.onnx \
    --decoder_model output_models/sam2_hiera_tiny.decoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_prompt.json \
    --sam_variant sam2 \
    --output output_images/sam2_truck.png \
    --show
SAM3 — Convert to ONNX
SAM3 extends the SAM family with open-vocabulary, text-driven segmentation. In addition to point and rectangle prompts, it accepts text prompts (e.g., "truck", "person") to detect and segment objects without any prior training on those classes.
SAM3 exports into three separate ONNX models: an image encoder, a language (text) encoder, and a decoder.
Pre-exported ONNX models
NRL.ai publishes the real-model artifacts validated by this repository at
nrl-ai/samexporter-onnx-models.
The repository contains SAM ViT-B, MobileSAM, EfficientSAM-Ti, SAM 2.1 Tiny,
and SAM3, with checksums, source revisions, and a license in every family
directory.
hf download nrl-ai/samexporter-onnx-models \
    --include "sam3/*" \
    --local-dir output_models
Keep sam3_decoder.onnx.data beside sam3_decoder.onnx. The published bundle
was exported from facebook/sam3 revision
3c879f39826c281e95690f02c7821c4de09afae7 and source revision
660a5e9e1b8b4c02c0ad97229b88a09a6e4ff5b7.
Export from PyTorch (optional)
The pinned upstream SAM3 package supports Python 3.8 or newer and requires
NumPy <2 for source export. SAMExporter itself supports Python 3.11 through
3.13, so use any of those versions with NumPy >=1.26,<2 when exporting SAM3.
# Clone the SAM3 source (required for export only, not inference)
git submodule update --init sam3

# Install the pinned official SAM3 export dependencies
pip install -e sam3

# Export (add --simplify for ONNX simplification, requires [export] extra on Windows)
python -m samexporter.export_sam3 \
    --output_dir output_models/sam3 \
    --opset 18 \
    --device auto \
    --max-geometric-prompts 8
Pass --checkpoint /path/to/sam3.pt to use an already-downloaded official
checkpoint instead of consulting the Hugging Face cache.
Run inference
Text-only prompt (detects all instances matching the text):
python -m samexporter.inference \
    --sam_variant sam3 \
    --encoder_model output_models/sam3/sam3_image_encoder.onnx \
    --decoder_model output_models/sam3/sam3_decoder.onnx \
    --language_encoder_model output_models/sam3/sam3_language_encoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_sam3.json \
    --text_prompt "truck" \
    --output output_images/truck_sam3.png \
    --show
For broad concepts such as "plant", returning every visible matching object
is expected. Keep only the highest-confidence results when a compact preview is
more useful:
python -m samexporter.inference \
    --sam_variant sam3 \
    --encoder_model output_models/sam3/sam3_image_encoder.onnx \
    --decoder_model output_models/sam3/sam3_decoder.onnx \
    --language_encoder_model output_models/sam3/sam3_language_encoder.onnx \
    --image images/plants.png \
    --prompt images/plants_text.json \
    --text_prompt "plant" \
    --max_instances 5 \
    --output visual_results/runs/manual/sam3_plants_text_top5.png
Text + rectangle exemplar (text names the concept; the rectangle supplies a positive visual example):
python -m samexporter.inference \
    --sam_variant sam3 \
    --encoder_model output_models/sam3/sam3_image_encoder.onnx \
    --decoder_model output_models/sam3/sam3_decoder.onnx \
    --language_encoder_model output_models/sam3/sam3_language_encoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_sam3_box.json \
    --text_prompt "truck" \
    --output output_images/truck_sam3_box.png \
    --show
Text + point prompt:
python -m samexporter.inference \
    --sam_variant sam3 \
    --encoder_model output_models/sam3/sam3_image_encoder.onnx \
    --decoder_model output_models/sam3/sam3_decoder.onnx \
    --language_encoder_model output_models/sam3/sam3_language_encoder.onnx \
    --image images/truck.jpg \
    --prompt images/truck_sam3_point.json \
    --text_prompt "truck" \
    --output output_images/truck_sam3_point.png \
    --show
Note: Put a text mark in the prompt JSON or pass
--text_prompt. Without either, the model defaults to a generic"visual"token and results may be less predictable.
SAM3 geometry is a positive/negative concept exemplar, not a crop constraint.
It can find visually matching objects outside the supplied rectangle. In the
default --sam3_output_mode auto, a geometric prompt is treated as a selection:
duplicate queries are removed and the best mask overlapping the positive box or
point is returned. Use --sam3_output_mode all to preserve every matching
concept instance. Point marks are approximated as 1%-size exemplar boxes because
the PCS decoder ignores native point prompts; prefer text plus rectangles when
quality matters.
The default --sam3_nms_mode mask follows the official SAM3 mask-IoU NMS
behavior. --sam3_nms_mode box trades some fidelity for speed and
--sam3_nms_mode none exposes raw thresholded queries. Tune duplicate
suppression with --nms_threshold and score filtering with
--confidence_threshold.
New decoders accept zero to eight padded geometric marks by default. The
capacity is fixed inside ONNX because SAM3 geometry attention traces at a fixed
token count; re-export with a larger --max-geometric-prompts if needed. The
runtime validates the limit and masks unused slots.
New SAM3 exports keep raw query logits, presence score, masks, and boxes as ONNX
outputs. Confidence filtering and resize-to-original are performed at runtime,
so --confidence_threshold, original aspect ratio, and output dimensions are
not frozen during export. Multi-instance overlays use distinct colors, contours,
and instance numbers. The runtime also remains compatible with older
three-output exports.
Prompt JSON format
Prompts are JSON files containing a list of mark objects:
[
  {"type": "point",     "data": [x, y],           "label": 1},
  {"type": "rectangle", "data": [x1, y1, x2, y2]},
  {"type": "text",      "data": "object description"}
]
label: 1— foreground point;label: 0— background pointtype: "text"is specific to SAM3 (use--text_prompton the CLI instead for convenience)
Performance recommendations
Choose the model around the prompt and deployment constraint:
| Need | Recommended starting point | Why |
|---|---|---|
| Small CPU package / interactive clicks | EfficientSAM-Ti | Roughly 40 MB for the split ONNX pair; lowest setup cost |
| SAM-compatible lightweight encoder | MobileSAM | Reuses the familiar SAM prompt/decoder contract |
| Best original-SAM quality | SAM ViT-H | Largest and slowest SAM1 encoder, but the strongest original checkpoint |
| Better modern image masks | SAM2.1 Tiny first, then scale up | Tiny is the practical baseline; larger Hiera encoders trade latency and memory for capacity |
| Natural-language object discovery | SAM3 | Only choose it when text prompting is required; it loads image, language, and decoder models |
For interactive applications, encode each image once and cache the returned embedding. Re-run only the decoder as points or boxes change. On the local 8-core Intel i9-11950H using ONNX Runtime CPU, EfficientSAM-Ti took a median 966 ms to encode the 1800×1200 truck image and 42 ms per box decode (10 measured runs after warm-up). Treat these as a local baseline, not a portable benchmark.
Additional guidance:
- The runtime automatically orders every installed ONNX Runtime accelerator and keeps CPU last as a fallback. Recognized backends include TensorRT, CUDA, TensorRT RTX, MIGraphX/ROCm, OpenVINO, DirectML, CoreML, CANN, QNN, NNAPI, VSINPU, WebNN, WebGPU, XNNPACK, RKNPU, Vitis AI, ACL, ArmNN, and oneDNN. Availability depends on the ONNX Runtime package/build installed on the target machine.
- Install the one ONNX Runtime build intended for the target. The standard
onnxruntimewheel is CPU; NVIDIA CUDA/TensorRT usesonnxruntime-gpu, Intel OpenVINO usesonnxruntime-openvino, Windows DirectML usesonnxruntime-directml, and Qualcomm QNN usesonnxruntime-qnn. ONNX Runtime recommends keeping only one of its Python packages in an environment. Follow its installation matrix for platform-specific and custom provider builds. - Override provider order with
--providers tensorrt,cuda,cpu,--providers openvino,cpu, or theSAMEXPORTER_ONNX_PROVIDERSenvironment variable. Exact ONNX Runtime provider names are also accepted, and unavailable explicit providers fail early with the installed provider list. - TensorRT is usable through
TensorrtExecutionProvider. Dynamic models may incur engine-build/cache time; for repeatable deployment, configure the provider's engine cache and shape profiles or build fixed min/opt/max engines as demonstrated by EfficientViT-SAM upstream. When building a SAM decoder directly with TensorRT,orig_im_sizeis a shape tensor: configure its value profile withprofile.set_shape_input("orig_im_size", min_values, opt_values, max_values)in addition to ordinary dynamic tensor profiles. - Quantized
*.quant.onnxfiles primarily reduce storage and memory. Benchmark accuracy and latency on the target CPU—dynamic quantization is not guaranteed to accelerate convolution-heavy encoders. - Avoid ONNX simplification by default for large SAM2/SAM3 exports. It can increase file size and peak memory; enable it only after measuring the target runtime.
- Use box prompts for deterministic QA. A single positive point can validly select a sub-part, while a tight box better communicates the expected object extent.
- Keep image embeddings in memory, but release sessions or cached embeddings when processing large image queues; the encoders dominate memory consumption.
Reviewed overlays and their verification status are kept in
visual_results/README.md.
Running tests
pip install pytest
pytest tests/
For end-to-end model checks, first run bash download_all_models.sh, then:
bash test_comprehensive.sh
The bundled point and rectangle fixtures intentionally target visible objects in
both a landscape and a portrait image. Every generated image is retained under
visual_results/runs/ by default. Use SAMEXPORTER_RESULTS_DIR=/path/to/results
to redirect a run without losing its artifacts.
Adding more SAM variants
Good next candidates from the broader SAM ecosystem are:
| Variant | License | Integration path |
|---|---|---|
| EfficientViT-SAM | Apache-2.0 | Upstream provides separate encoder/decoder ONNX exporters; add an adapter for its normalized fixed-size encoder |
| HQ-SAM / HQ-SAM 2 | Apache-2.0 | Add HQ intermediate features and its custom mask decoder contract |
| MedSAM | Apache-2.0 | Reuse the SAM prompt contract with model-specific preprocessing and checkpoints |
| EdgeSAM | NTU S-Lab License 1.0 | Technically close to SAM, but review redistribution terms before bundling code or weights |
FastSAM is intentionally not a drop-in target here: it is detector-style rather than an encoder/prompt-decoder SAM contract, and its AGPL licensing needs a separate distribution decision. Prefer adapters that keep third-party model code optional and consume upstream ONNX files; this makes new integrations faster and keeps their licenses explicit.
The implementation was cross-checked against the official SAM mask
resize–crop–resize path, MobileSAM and EfficientSAM ONNX exporters, official
SAM2 preprocessing/contracts, EfficientViT-SAM's ONNX/TensorRT deployment, and
the MIT-licensed sam3-triton raw-head/post-processing split. Reference code is
used as design evidence only unless its license and attribution permit direct
integration.
AnyLabeling
This package was originally developed for the auto-labeling feature in AnyLabeling. However, it can be used independently for any ONNX-based deployment scenario.

License
MIT — see LICENSE for details.
References
- ONNX-SAM2-Segment-Anything: https://github.com/ibaiGorordo/ONNX-SAM2-Segment-Anything
- sam3-onnx: https://github.com/wkentaro/sam3-onnx

ultralytics
ultralytics·Python
YOLO 系列官方实现库,一套 PyTorch 代码覆盖目标检测、实例与语义分割、图像分类、姿态估计和目标跟踪,训练到部署全流程打通。
目标检测+4检测 / 分割
63270+8712kv8.4.2082026-11-10 09:31 UTC

yolov5
ultralytics·Python
基于 PyTorch 的目标检测全家桶,覆盖训练、推理、实例分割、图像分类和模型导出,开箱即用,适合快速落地视觉任务。
目标检测+4检测 / 分割
58258+517kv7.02026-11-07 16:59 UTC
pytorch-image-models
huggingface·Python
收录最全的 PyTorch 图像骨干网络合集,涵盖 ResNet、ViT、ConvNeXt 等主流模型,自带训练、评估、推理和导出脚本及预训练权重,省去自己搭网络和找权重的麻烦。
图像分类+4检测 / 分割
37272+75.2kv1.0.312026-11-07 23:22 UTC

detectron2
facebookresearch·Python
Detectron2 是 Facebook 开源的目标检测与分割平台,提供模块化架构和丰富预训练模型,方便快速搭建和训练视觉识别任务。
目标检测+4检测 / 分割
34980+57.9kv0.62026-10-27 09:21 UTC