TensorRT 引擎必须在目标 GPU 上导出且仅支持静态输入形状;TensorRT 引擎需以 batch 1 运行,批量推理结果不可靠;导出后端、SAM3、Gradio 需另装对应 extras,且 TensorRT 仅限 Linux。
D-FINE-seg
ArgoHAApache-2.0活跃维护一站式实时视觉训练与部署框架,覆盖目标检测、关键点估计、实例与语义分割,支持导出 TensorRT、ONNX、OpenVINO、CoreML 到边缘设备。
Real-time object detection, keypoint estimation, instance and semantic segmentation. Train, export (TensorRT, ONNX, OpenVINO, CoreML), deploy. Apache-2.0
v0.7.0发布于 2026-11-05 16:22 UTC225star +1 / 7 天38fork同步于 2026-11-11 00:02 UTC
pip install dfine-seg
pip install 'dfine-seg[all]' 硬件要求按 README 说明
README 未说明具体显存要求;支持 CUDA、MPS、CPU 推理(hw_bench 可选 cuda/mps/cpu);TensorRT 需在目标 GPU 上构建,C++ 核心面向机器人与 Jetson 板卡。
支持 Apple Silicon需要 CUDA多卡 / 张量并行
一个代码库统一实时检测、关键点、实例与语义分割,支持训练导出多后端部署
一站式实时视觉训练与部署框架,覆盖目标检测、关键点估计、实例与语义分割,支持导出 TensorRT、ONNX、OpenVINO、CoreML 到边缘设备。
核心能力
- 用 task 配置切换 detect/segment/sem_seg/kpts 四种任务
- 提供 N 到 X 五种模型尺寸与各任务预训练权重
- 支持 ONNX、TensorRT、OpenVINO、CoreML 多后端导出
- 提供 libdfine.so C++ 核心,融合 CUDA 前后处理
- 支持 RGB 加红外、深度、NIR 多通道输入训练
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.7.0最新正式版2026-11-05 · 2026-11-05 16:22 UTC
What's Changed
- Kpts by @ArgoHA in https://github.com/ArgoHA/D-FINE-seg/pull/85
Full Changelog: https://github.com/ArgoHA/D-FINE-seg/compare/v0.6.2...v0.7.0
- v0.6.2v0.6.2 - fix fine-tuning from COCO weights2026-10-24 · 2026-10-24 11:39 UTC
查看更新说明
Fixes IndexError when fine-tuning from COCO weights on a dataset with a class count other than 80 (regression in 0.6.0). Also includes the instance segmentation denoising loss fix and dependency security updates.
- v0.6.1v0.6.1 - fix pip install of TensorRT and OpenVINO on NVIDIA2026-10-16 · 2026-10-16 10:14 UTC
查看更新说明
Bug-fix release.
pip install 'dfine-seg[trt]'and[all]failed on Linux: thetensorrtmeta package pulled the deprecatednvidia-cuda-runtime-cu13stub, which refuses to build. The extra now depends ontensorrt-cu12==10.13.3.9directly (same TensorRT as before).- OpenVINO >= 2025.4 lists NVIDIA cards as
GPU, so the OpenVINO wrapper picked one and failed to compile. It now only auto-selects Intel GPUs, otherwise CPU; an explicitdevice=still wins.
- v0.6.0v0.6.0 - Cityscapes semantic segmentation weights2026-10-15 · 2026-10-15 22:02 UTC
查看更新说明
Cityscapes semantic segmentation weights for all five sizes, auto-downloaded with one line:
from dfine_seg import load_model
model = load_model("x", task="sem_seg")  # class names and 1024x2048 input come from the checkpoint
Cityscapes val, native 1024x2048 whole image, TensorRT 10.13 fp16, batch 1, RTX 5070 Ti:
model params (M) mIoU pixel acc e2e ms D-FINE-N 3.36 77.99 96.03 4.21 D-FINE-S 7.99 81.12 96.47 6.37 D-FINE-M 15.95 81.41 96.55 8.26 D-FINE-L 24.97 83.80 96.93 9.77 D-FINE-X 56.3 84.84 97.10 14.64 - v0.5.1What's new2026-10-11 · 2026-10-11 05:13 UTC
查看更新说明
Security update: hydra-core 1.3.5 -> 1.3.7
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
D-FINE-seg is a framework for real-time object detection, keypoint estimation, instance and semantic segmentation - one codebase, one config flag (task: detect | segment | sem_seg | kpts), five model sizes (N -> X).
See it run: dfine-seg.argoai.space - demos of all four tasks on real footage (off-road driving, mining, reefs, crowds, thermal cameras, radio astronomy), with the benchmarks behind them.
- End-to-end workflow - dataset prep -> training (DDP, EMA, AMP, mosaic) -> export (ONNX, TensorRT, OpenVINO, CoreML) -> benchmarked multi-backend inference
- Accuracy - Cityscapes semantic segmentation at native 1024x2048: D-FINE-seg-X reaches 84.84 mIoU at 14.6 ms end-to-end, the highest of 28 models - +1.26 mIoU over YOLO26-x, and +1.5 mIoU over Mask2Former Swin-L with 6.4x lower latency and a quarter of the params - and D-FINE-seg-L matches or beats YOLO26-x on every axis; also beats YOLO26 and RF-DETR on 640 Cityscapes detection & instance-seg F1, YOLO26 on TACO and VisDrone, and YOLO26s-pose on COCO person keypoints with S - 65.4 vs 62.7 AP at the same latency (TensorRT FP16, end-to-end protocol)
- Paper - D-FINE-seg: Object Detection and Instance Segmentation Framework with Multi-Backend Deployment
- Not a fork: the detection core follows the D-FINE paper; segmentation heads, training, export and inference are implemented from scratch.
One frame, three tasks, one config flag:
Highlights
- Instance segmentation head (
task: segment) - lightweight mask head: per-query mask embeddings dotted with shared 1/4-resolution features fused from the encoder outputs - Semantic segmentation head (
task: sem_seg) - the pretrained instance-seg feature fuser plus a small conv classifier: no queries, no NMS - Keypoint head (
task: kpts) - every detection also predicts K points with a presence and a visibility score each; a keypoint decoder refines the top detections with one token per point - Mask-aware training - box-cropped BCE + Dice (instance seg), CE + Dice with
ignore_index(semantic seg), mask costs in matching and mask supervision on denoising queries - train-time only, zero inference cost - Pretrained weights for every task - detection on COCO (plain and Objects365-pretrained), COCO instance segmentation, Cityscapes semantic segmentation, COCO person keypoints
- Multi-channel inputs - train on RGB + thermal / depth / NIR stacks (4-channel
.npy), not just RGB - Modern training stack - Muon optimizer, DDP, EMA, mosaic + affine augs, knowledge distillation, OneCycle, early stopping, rare-class sampling (LVIS repeat-factor), WandB, auto-batch size.
- C++ core -
libdfine.sofor all four tasks: TensorRT plus fused CUDA pre/postprocessing, no dependencies beyond CUDA and TensorRT, built to embed on robots and Jetson boards - a 1080p frame in under 1.6 ms with S (numbers) - Beyond the model - ByteTrack tracking, SAM3 auto-labeling, Gradio demo, INT8 quantization (OpenVINO / CoreML)
How it works - backbone, encoder and every task's decoder: docs/arch.md.
Quick Start
Installation
pip install dfine-seg           # inference + training
pip install 'dfine-seg[all]'    # + every export backend, SAM3, Gradio demo
Pretrained weights auto-download from Hugging Face on first use: detection on COCO (dfine_{n,s,m,l,x}_coco.pt, and dfine_{n,s,m,l,x}_obj2coco.pt - Objects365 pretraining, then COCO), COCO instance segmentation (dfine_seg_{n,s,m,l,x}_coco.pt), Cityscapes semantic segmentation (dfine_sem_{n,s,m,l,x}_cityscapes.pt), COCO person keypoints (dfine_kpts_s_coco.pt).
| Install | Adds | For |
|---|---|---|
pip install dfine-seg | torch, torchvision, opencv, hydra, wandb, albumentations, … | inference + training |
pip install 'dfine-seg[export]' | onnx, onnxruntime, openvino, nncf, coremltools | dfine export |
pip install 'dfine-seg[trt]' | tensorrt (Linux) | TensorRT engines - build on the target GPU |
pip install 'dfine-seg[label]' | transformers | SAM3 auto-labeling |
pip install 'dfine-seg[demo]' | gradio | the Gradio UI |
pip install 'dfine-seg[all]' | everything above | full setup |
Two-line predict:
from dfine_seg import load_model, read_image, Visualizer

model = load_model("s")                              # COCO detection, weights auto-downloaded
model = load_model("s", task="segment")              # COCO instance segmentation
model = load_model("x", task="sem_seg")              # Cityscapes semantic segmentation
model = load_model("s", task="kpts")                 # COCO person keypoints (17 points)
model = load_model("output/models/exp/model.pt")     # your checkpoint - size/task/classes/input size auto-detected, supports: .pt | .engine | .onnx | .xml

img = read_image("path/to/image.jpg")
out = model(img)[0]
print(out["boxes"], out["scores"], [model.names[int(i)] for i in out["labels"]])

drawn = Visualizer(model)(img, out)                  # annotated BGR copy - boxes, masks or a sem_seg overlay
load_model returns the same wrapper you would construct by hand (dfine_seg/infer/) - it resolves the weights and picks the backend. Extra keyword arguments pass straight through (load_model("s", conf_thresh=0.3)), model(img, conf_thresh=0.5) overrides that threshold for a single call (one float or a per-class list), output tensors stay on the device the model ran on, and those wrapper files remain self-contained enough to copy into your own app. Visualizer reads the class count and names off the model it is given, then draws whatever that model returned - boxes, instance masks or a dense label map - so one call covers every task (BGR uint8 in, BGR uint8 out).
To train from a pip install, materialize a config and go:
dfine init          # writes ./config.yaml - edit train.root and train.label_to_name
dfine split
dfine train         # Hydra overrides work: dfine train model_name=m train.epochs=100
From source (contributors)
git clone https://github.com/ArgoHA/D-FINE-seg.git
cd D-FINE-seg
uv sync
Prepare Your Data
Two annotation formats are supported: YOLO (default) and COCO JSON. Semantic segmentation uses PNG masks instead (see below).
YOLO format (default)
data/dataset/
├── images/    # all images: .jpg, .png, etc. (.npy for multi-channel - see below)
└── labels/    # all labels: one .txt per image (same filename stem)
Detection labels: class_id xc yc w h (normalized)
Segmentation labels: class_id x1 y1 x2 y2 ... xN yN (normalized polygon coordinates)
Keypoint labels (task: kpts): class_id xc yc w h x1 y1 v1 ... xK yK vK (normalized, the YOLO-pose format) - see Keypoints
Input types & channel order: 3-channel .jpg/.png (BGR, read via cv2.imread), 3-channel .npy (RGB, read via np.load), or 4-channel .npy (RGB+extras, e.g. RGB+thermal).
Semantic segmentation masks (task: sem_seg)
data/dataset/
├── images/    # same as YOLO layout
└── labels/    # one single-channel uint8 .png per image (same stem), pixel value = class id
Every pixel gets a class from label_to_name (background included). Pixels with value train.sem_seg.ignore_index (default 255) are excluded from loss and metrics and during inference 255 is the "background" or "ignored" class. dfine split works unchanged; keep_ratio: True is supported (letterbox pad is filled with ignore_index, so pad pixels don't supervise); coco_dataset: True is not supported for this task.
Released Cityscapes weights load with load_model("x", task="sem_seg") - names and input size come from the checkpoint. They are also a strong init for your own driving/outdoor data: point train.pretrained_model_path at one with a different label_to_name and the class heads re-initialize while the rest keeps the Cityscapes training (N from COCO detection weights, S/M/L/X from obj2coco). A model fine-tuned from them is still derived from Cityscapes and inherits its non-commercial terms (see License) - for commercial use, start from the COCO / obj2coco weights instead. Benchmark numbers and the full 28-model comparison: cityscapes-benchmark.
Keypoints (task: kpts)
Every object has a box and the same K points (train.kpts.shape: [K, 3]); classes without points fill all slots with 0 0 0. Boxes are required: every decoder stage is anchored on them. For point-only tasks (e.g. centers of small objects) use task: detect with fixed-size pseudo-boxes around each point - the box center is the point.
- YOLO (format above): a line with a different value count than
5 + K * Dis an error. Withshape: [K, 2]the flags are omitted:0 0means unlabeled, any other point is visible. - COCO JSON:
ann["keypoints"]([x, y, v] * K, absolute) andann["area"](the OKS scale; YOLO labels use0.53 * box area).dfine_seg/etl/coco2yolo.py(use_kpts=True) andyolo2coco.pyconvert both ways. - Flags:
v=0unlabeled,v=1labeled but occluded,v=2visible. Coordinates are learned from every labeled point (v > 0); points that augmentation moves off the image become unlabeled. - Two scores per point: presence - is the point labeled / locatable at all (trained on
v > 0, the points COCO OKS scores), and visible - is it directly seen, trained onv == 2vsv == 1over labeled points only, so read it asP(visible | present). The visible score needs[K, 3]labels that contain occluded points; without them it stays ~1 (a warning says so). train.kpts.flip_idxis required whenK > 1andleft_right_fliporup_down_flip> 0: after a flip, slotitakes the point from slotflip_idx[i]. A mirrored left eye is a right eye, so symmetric pairs must swap ([0, 2, 1, 4, 3, ...]for COCO,[1, 0]for two eyes); points without a mirror partner keep their slot ([0, 1]for head, tail). The config template ships COCO's person order next toshape: [17, 3]; set your own for other points.train.kpts.sigmas: per-point OKS tolerance, larger is more forgiving (COCO's 17 for K=17, else 0.07); they also scale the OKS loss and matching cost. Rule of thumb for custom points:σ ≈ 0.6 x r, whereris the error, as a fraction ofsqrt(box w x h), that should still score 0.5 (0.07 -> 12% of the box size).conf_threshis the presence threshold for drawing,dfine inferlabels andpresence_f1;visible_threshsplits drawn and written points into visible / occluded. Model outputs keep all K points with their scores, so filter them yourself, e.g.kpts[..., 2] >= conf_thresh.skeleton(zero-based pairs, drawing only) andnamesare stored in the checkpoint.- Released S weights:
load_model("s", task="kpts")- COCO person keypoints, also a ready init for your own person keypoint data. - Otherwise init from the detection weights;
train.kpts.freeze_except_kpt: Truetrains only the keypoint modules. - Metrics:
f1_kpt(OKS >= 0.5),mAP_50_95_kpt(COCO keypoint AP),kpt_px_err(mean error in original-image pixels),presence_f1,visible_acc, and boxmAP_50_95/f1;extended_metrics.csvadds precision / recall,mAP_50_kpt, mean OKS and PCK.
Multi-channel inputs (RGB + thermal / depth / NIR / …)
Set train.in_channels: 4 (3 or 4 supported) to train on RGB + one extra modality (thermal / depth / NIR). Stacks are .npy uint8 HWC arrays in images/ (RGB in planes 0-2, extras after) with YOLO labels as usual; a mismatched channel count is skipped with a warning. See dfine_seg/etl/m3fd_to_yolo.py for a ready-made RGB+thermal converter.
COCO JSON format
Place standard COCO JSON annotation files alongside your images folder. Splits are detected automatically by filename:
data/dataset/
├── images/       # all images
├── train.json    # COCO-format annotations for train split
├── val.json      # COCO-format annotations for val split
└── test.json     # (optional) COCO-format annotations for test split
Enable COCO mode by setting coco_dataset: True in your config (see below). No CSV split generation step is needed - the splits are read directly from the JSON files.
If you only have a single coco.json, run dfine split to produce train.json / val.json (and test.json when the ratios leave room) from it. It splits by image using the same split: ratios, seed and ignore_negatives as the YOLO path, keeps each image's annotations with it, and copies categories / info / licenses into every output.
Configure
Edit config.yaml - key settings:
task: detect  # detect | segment | sem_seg | kpts
exp_name: my_exp  # experiment name (used in output paths)
model_name: s  # n / s / m / l / x

train:
  root: /path/to/project  # project root, will be used for outputs
  data_path: /path/to/dataset  # folder with images/ and labels/ (YOLO) or *.json files (COCO)
  coco_dataset: False  # set True to use COCO JSON annotations (train.json / val.json / test.json)
  label_to_name:
    0: class_a
    1: class_b
  epochs: 75
  batch_size: 8
  img_size: [640, 640]  # (h, w)
Usage
| Command | What it does |
|---|---|
dfine init | write config.yaml from the packaged template (--task, --model, -d, --force) |
dfine split | create train/val CSV splits (test split if configured) |
dfine train | train the model |
dfine export | export to ONNX, TensorRT, OpenVINO, CoreML |
dfine bench | benchmark all exported models on the val set |
dfine infer | run on test folder, save visualizations + YOLO txt predictions |
dfine check-errors | compare predictions against GT, save only mismatches (FP/FN) |
dfine test-batching | find optimal batch size for your GPU |
dfine ov-int8 | INT8 accuracy-aware quantization for OpenVINO (can take hours) |
dfine trt-int8 | TensorRT INT8 calibration |
dfine main | train -> export -> bench in sequence (same as the bare make target) |
dfine demo | launch the Gradio UI (needs pip install 'dfine-seg[demo]') |
dfine predict | run a model on an image or folder, no config needed |
dfine hw_bench | measure Torch inference throughput on this device (cuda/mps/cpu); --batch to saturate a GPU |
dfine version | print the installed version |
Notes:
- Most commands read
config.yamland work off your trained run; exceptions —init(writes the config),predict,hw_bench,demo,version(no config needed). Every command's flags, defaults and examples:dfine <command> -h. - YOLO format:
dfine trainrequirestrain.csvandval.csvintrain.data_path(generated bydfine split). - COCO format: set
coco_dataset: True-train.jsonandval.jsonare loaded directly;dfine splitis only needed if you have a singlecoco.jsonto split. dfine inferruns Torch inference ontrain.path_to_test_dataand writes totrain.infer_path.infer/export/benchauto-pick the latest<exp_name>_<date>run undertrain.path_to_save.
Every dfine command also has a make alias (make train == dfine train), and any config key can be overridden inline:
dfine train exp_name=my_exp model_name=m train.epochs=100
Enable DDP (multi-GPU) by setting train.ddp.enabled: True and train.ddp.n_gpus: N in config. Then just run dfine train - it auto-launches with torchrun.
Training Features
| Feature | Description |
|---|---|
| Muon optimizer | Optional Newton–Schulz optimizer for encoder/decoder attention+MLP matrices |
| DDP | Multi-GPU distributed training with SyncBatchNorm |
| AMP | Automatic mixed precision (~40% less VRAM, ~15% faster) |
| EMA | Exponential moving average of weights |
| Gradient accumulation | Effective batch size = batch_size x b_accum_steps |
| Knowledge distillation | Set train.kd.teacher to a trained teacher's model.pt (same classes and channels). The frozen teacher adds its predictions to the student's loss. Start with a teacher one size up and 40% bigger input size. |
| Automatic batch size | train.batch_size: -1 probes a full training step (incl. the KD teacher) and targets ~70% of VRAM |
| Gradient clipping | Configurable max norm |
| Mosaic augmentation | 4-image mosaic with affine transforms (recommended for detection) |
| Albumentations | Rotation, flip, blur, noise, gamma, grayscale, coarse dropout, multiscale |
| OneCycleLR scheduler | Separate learning rates for backbone and head |
| Early stopping | Configurable patience |
| WandB integration | Automatic experiment tracking |
| Optimal threshold search | Auto-finds best confidence threshold after training |
| Background warm-up | Ignore background-only images for N initial epochs |
| Autoresearch loop | Research/execute loop for agents (semantic segmentation on Cityscapes), see experiments/program.md |
Export
| Format | Half Precision | Notes |
|---|---|---|
| ONNX | - | With optional fused postprocessor |
| TensorRT | FP16 | Must be exported on the target GPU. Static input shape only |
| OpenVINO | FP16, INT8 | Single export for FP32 or FP16 (pick during inference) and separate INT8 quantization script |
| CoreML | FP16, INT8 | Cross-platform export, inference on macOS / iOS. FP32 and INT8 exported by default |
Tip: FP16 is the best latency/accuracy trade-off for GPU (TensorRT) and CPU (OpenVINO). For Apple Silicon (CoreML), FP32 is faster.
Warning: run TensorRT engines at batch 1. On TRT 10.13.3.9 a batched engine does not compute batch elements independently - feeding four identical images through a single
execute_async_v3call returns four different results (score spread up to 0.20, and different labels), so a detection's score depends on what it happened to be batched with. Batch 1 is exact, and reproduces in raw TensorRT for FP16 and FP32 and for every optimization-profile shape, while torch and ONNX Runtime stay identical across slots (NVIDIA/TensorRT#4813).
After export, a parity self-check (export.parity, on by default) runs each backend on a shared input and writes one cosine per backend - over the sorted top-K detection scores vs torch - to parity.csv next to the weights.
For task: kpts the graph has one more output, kpts [B, K_top, num_kpts, 4]: x, y in input pixels plus the presence and visible scores, gathered with the same top-K as the boxes. ONNX, TensorRT, OpenVINO and CoreML carry it.
For task: sem_seg every backend gets the same fused-argmax graph: a single int32 sem_seg output [B, H, W] (label map at input resolution, no detection postprocessor), and parity compares per-pixel argmax agreement instead of score cosine.
Inference
Backends
Six inference backends in dfine_seg/infer/:
| Backend | Format | Devices |
|---|---|---|
| Torch | .pt | CUDA, MPS, CPU |
| TensorRT | .engine | CUDA |
| OpenVINO | .xml | CPU, iGPU |
| ONNX Runtime | .onnx | CUDA, CPU |
| CoreML | .mlpackage | macOS (GPU), iOS |
| LiteRT | .tflite | CPU, mobile / edge (Android), support paused |
Output contract: detection / instance segmentation wrappers return labels, boxes, scores (+ masks [N, H, W] for segment, + kpts [N, K, 4] for kpts: x, y in original image pixels, presence and visible scores, all K points returned); sem_seg wrappers return a sem_seg [H, W] label map at original image resolution. Exported with export.sem_seg_probs: True (or TorchModel(..., sem_seg_probs=True) for .pt), sem_seg graphs gain a second output and the wrappers also return sem_seg_probs [C, h, w] float32, the per-class softmax at 1/4 of the model input (letterbox pads included), and sem_seg_probs_tf, a 3x3 matrix mapping original-image pixel (x, y, 1) to probs-map pixel coordinates (compose with camera intrinsics as K' = tf @ K). Use it where per-class confidence matters, e.g. traversability cost maps or lidar / BEV fusion; the label map is unchanged. For sem_seg, dfine infer writes palette overlays + GT-style grayscale PNG label maps (crops and tracking are box-based and skipped).
Also provided:
Bytetrack- simple implementation of object trackerSAM3- text-promptable zero-shot segmentation for auto-labeling (multi-class: repeat--promptor pass"car, person";--classes FILEmaps each class to several synonym prompts;--task sem_segwrites dense class-id masks for semantic segmentation)- C++ core (
libdfine.so) for TensorRT engines, plus an NVDEC -> NVENC video app: cpp/README.md
Multi-Object Tracking
A simplified ByteTrack (Zhang et al., ECCV 2022) is included for persistent object tracking across video frames - uses constant-velocity motion prediction with EMA-smoothed velocity instead of a Kalman filter, blends IoU with centroid distance in the match cost, and does per-class matching by default.
Gradio Demo
dfine demo # == make demo (pip: pip install 'dfine-seg[demo]')
A web UI for running inference on uploaded images and videos (or a webcam snapshot). It starts on COCO detection s - no setup. The Model panel then swaps in any other model at runtime: a size preset, or a path/upload of your own .pt / .onnx / .engine / .xml, with a box for the class names. detect, segment and sem_seg checkpoints all render, and SAM3 is selectable as a second backend for text-promptable segmentation (prompts are comma- or newline-separated - each one becomes a class).
It serves on 0.0.0.0:7860 (LAN-reachable) and prints a warning on startup: the Model panel loads any path the browser sends, so anyone who can reach the port can load files off this machine. dfine demo --host 127.0.0.1 restores local-only.
Benchmarks
Semantic segmentation - Cityscapes at native 1024x2048
28 models from 5 families: the five D-FINE-seg sizes trained by us and 23 official Cityscapes checkpoints (YOLO26-sem, EfficientViT-Seg, SegFormer, Mask2Former), none of them retrained. Input is the whole 1024x2048 frame in one forward pass; each model runs its own framework's shipped pre- and postprocessing and is scored by one validator on the 500 val images. TensorRT fp16, batch 1, RTX 5070 Ti. e2e ms includes each framework's CPU pre- and postprocessing; engine ms is pure TensorRT execute. Full table, per-class IoU, protocol and every known asymmetry: cityscapes-benchmark.
| model | params (M) | mIoU | pixel acc | engine ms | e2e ms |
|---|---|---|---|---|---|
| D-FINE-seg-N | 3.36 | 77.99 | 96.03 | 3.02 | 4.21 |
| D-FINE-seg-S | 7.99 | 81.12 | 96.47 | 5.38 | 6.37 |
| D-FINE-seg-M | 15.95 | 81.41 | 96.55 | 7.42 | 8.26 |
| D-FINE-seg-L | 24.97 | 83.80 | 96.93 | 8.98 | 9.77 |
| D-FINE-seg-X | 56.3 | 84.84 | 97.10 | 14.18 | 14.64 |
| YOLO26x-sem | 40.13 | 83.58 | 96.79 | 10.37 | 13.58 |
| EfficientViT-L2 | 52.61 | 83.20 | 96.87 | 9.56 | 19.87 |
| Mask2Former-Swin-L | 215.46 | 83.33 | 96.91 | 64.51 | 94.07 |
| SegFormer-B5 | 84.61 | 81.41 | 96.62 | 38.81 | 42.12 |
- D-FINE-seg-X vs Mask2Former-Swin-L (the most accurate Mask2Former checkpoint): +1.51 mIoU, 4.5x lower engine latency, 6.4x lower end-to-end latency, about a quarter of the parameters. X has the highest mIoU and pixel accuracy of the 28 models.
- D-FINE-seg-L vs YOLO26x-sem (the most accurate YOLO26-sem checkpoint): +0.22 mIoU, +0.14 pixel acc, 13% lower engine latency, 28% lower end-to-end latency, 38% fewer parameters. One training seed and a small margin, so read it as "matches or beats".
- Cityscapes test (held-out 1525 images, official evaluation server): D-FINE-seg-X 83.23 vs YOLO26x-sem 82.10 mIoU - the val margin holds on test.
Cityscapes - vs YOLO26 and RF-DETR (fine-tuning)
500 Cityscapes val images at original 2048x1024, TensorRT 10.13 FP16, batch 1, RTX 5070 Ti - same protocol and latency columns as above, with confidence thresholds tuned per framework to maximize F1. Full protocol: cityscapes-benchmark.
Detection
| model | params (M) | input | conf | F1 | precision | recall | IoU | e2e ms | engine ms |
|---|---|---|---|---|---|---|---|---|---|
| D-FINE-seg S | 10.29 | 640x640 | 0.5 | 0.703 | 0.817 | 0.617 | 0.446 | 2.0 | 1.38 |
| YOLO26-M | 21.79 | 640x640 | 0.25 | 0.691 | 0.792 | 0.613 | 0.432 | 3.03 | 1.59 |
| RF-DETR-medium | 33.39 | 576x576 | 0.35 | 0.673 | 0.769 | 0.599 | 0.409 | 10.2 | 1.45 |
Instance segmentation
| model | params (M) | input | conf | F1 | precision | recall | IoU | e2e ms | engine ms |
|---|---|---|---|---|---|---|---|---|---|
| D-FINE-seg S | 11.87 | 640x640 | 0.5 | 0.661 | 0.748 | 0.592 | 0.375 | 3.09 | 1.9 |
| YOLO26-M | 26.98 | 640x640 | 0.25 | 0.599 | 0.688 | 0.53 | 0.312 | 5.32 | 2.05 |
| RF-DETR-seg-medium | 35.4 | 432x432 | 0.35 | 0.62 | 0.789 | 0.51 | 0.346 | 16.81 | 1.77 |
The 640 semantic segmentation comparison is superseded by the native-resolution results above. Metric definitions, the VisDrone and TACO benchmarks, COCO-style APs and the export-format comparisons: docs/benchmarks.md
C++ core
The C++ core on a 1920x1080 frame already on the GPU: preprocess, TensorRT fp16 and postprocess, results left on the GPU. S models at 640x640, RTX 5070 Ti, cpp/examples/bench.cpp. Async runs 4 execution contexts in parallel.
| detect | segment | sem_seg | kpts | |
|---|---|---|---|---|
| blocking, 1 slot | 1.100 ms (909 fps) | 1.580 ms (633 fps) | 1.281 ms (780 fps) | 1.465 ms (682 fps) |
| async, 4 slots | 0.657 ms (1522 fps) | 1.153 ms (867 fps) | 1.059 ms (944 fps) | 0.929 ms (1077 fps) |
Outputs
| Output | Location | Description |
|---|---|---|
| Models + logs | output/models/{exp_name}_{date}/ | Weights, training metrics, confusion matrix, F1 vs threshold plots, per-class metrics, bench metrics, calculated optimal threshold |
| Debug images | output/debug_images/ | Preprocessed training images (with augmentations) |
| Eval predictions | output/eval_preds/ | Val set predictions with GT (green) and preds (blue) |
| Bench images | output/bench_imgs/ | Predictions from all exported models |
| Infer | output/infer/ | Visualizations + YOLO txt annotations (sem_seg: overlays + PNG label maps) |
| Check errors | output/check_errors/ | FP and FN only - for finding mislabeled samples |
Result examples
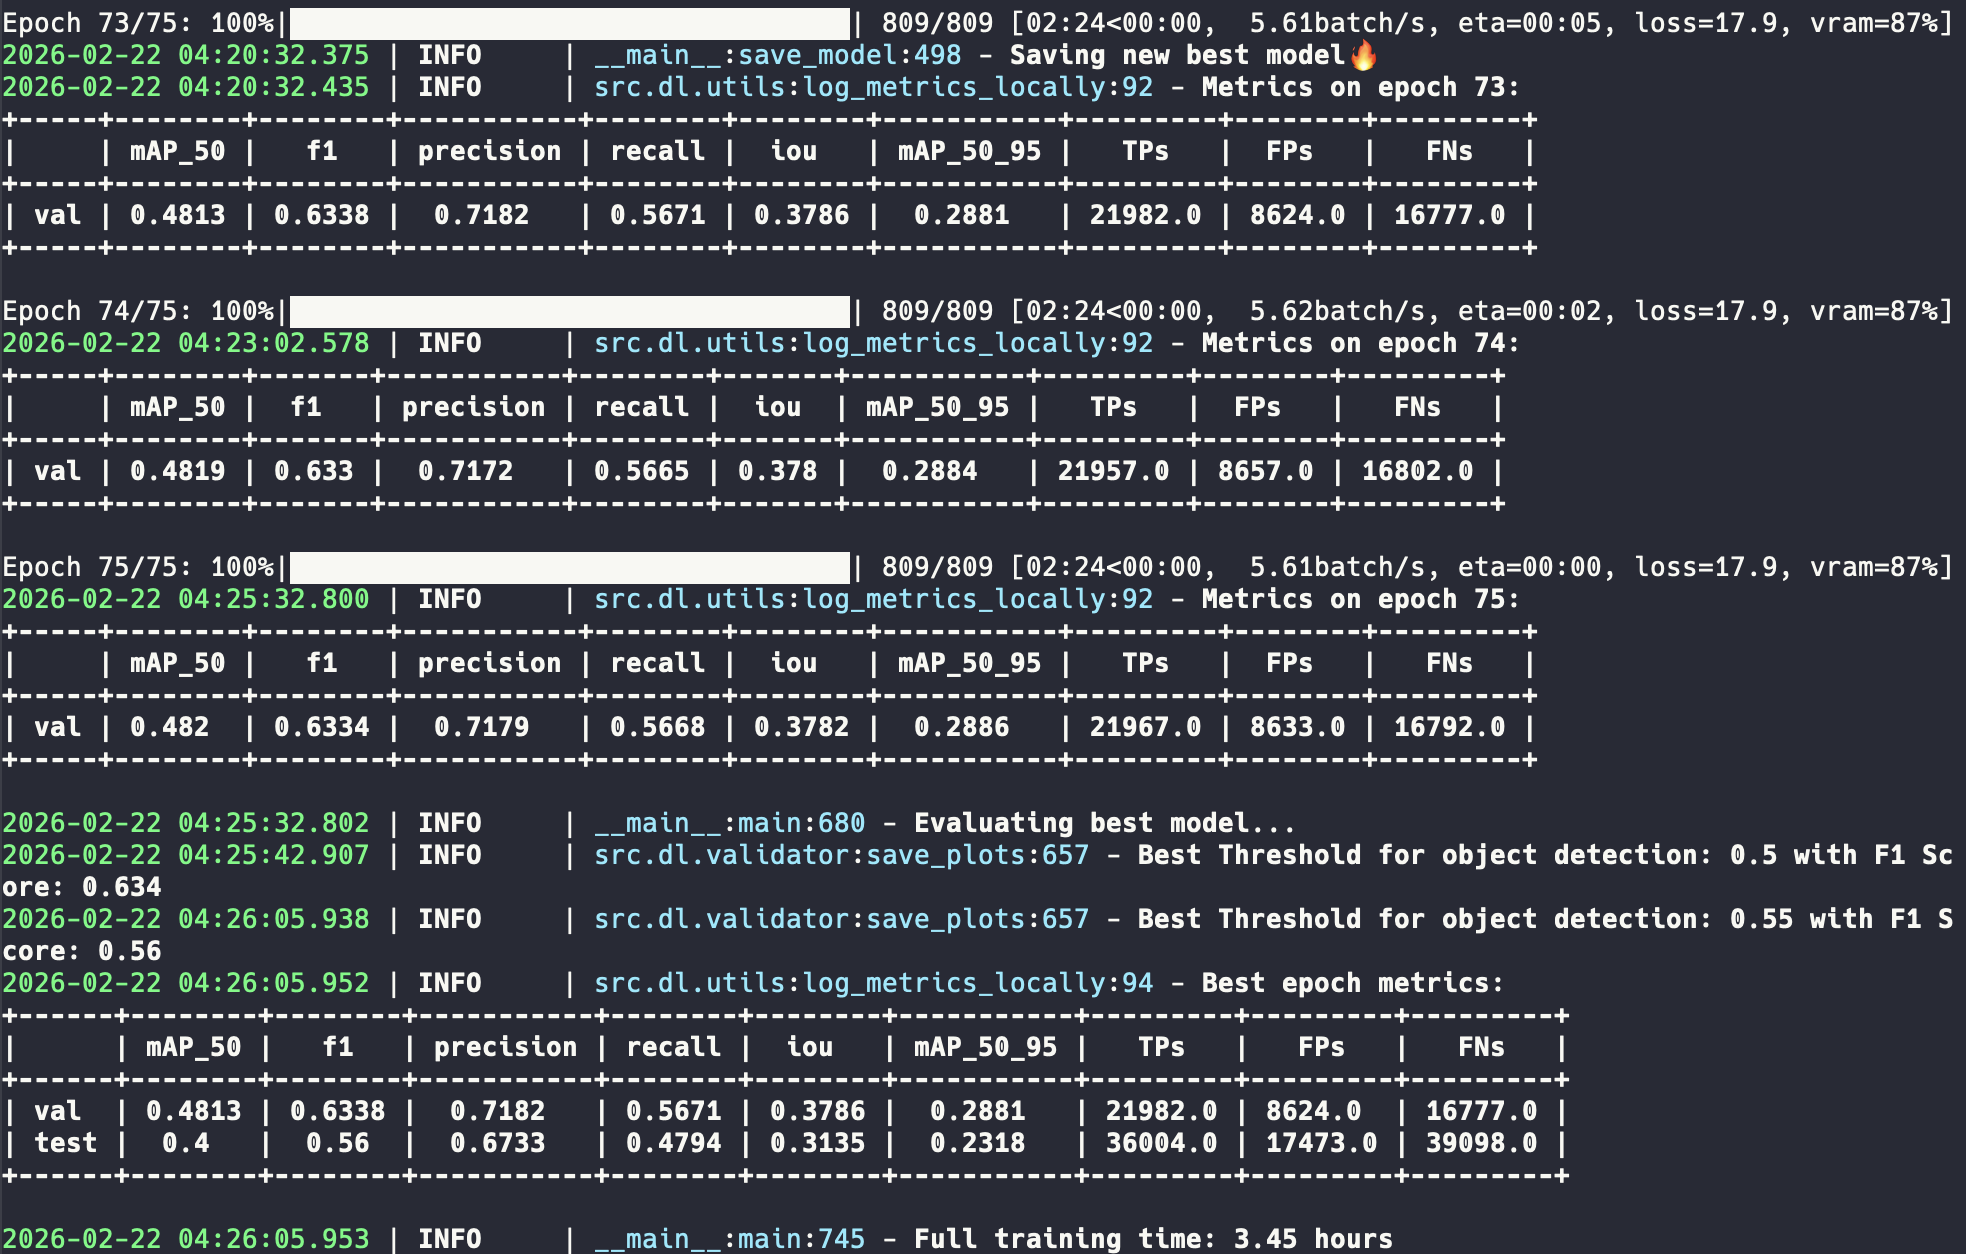
Training
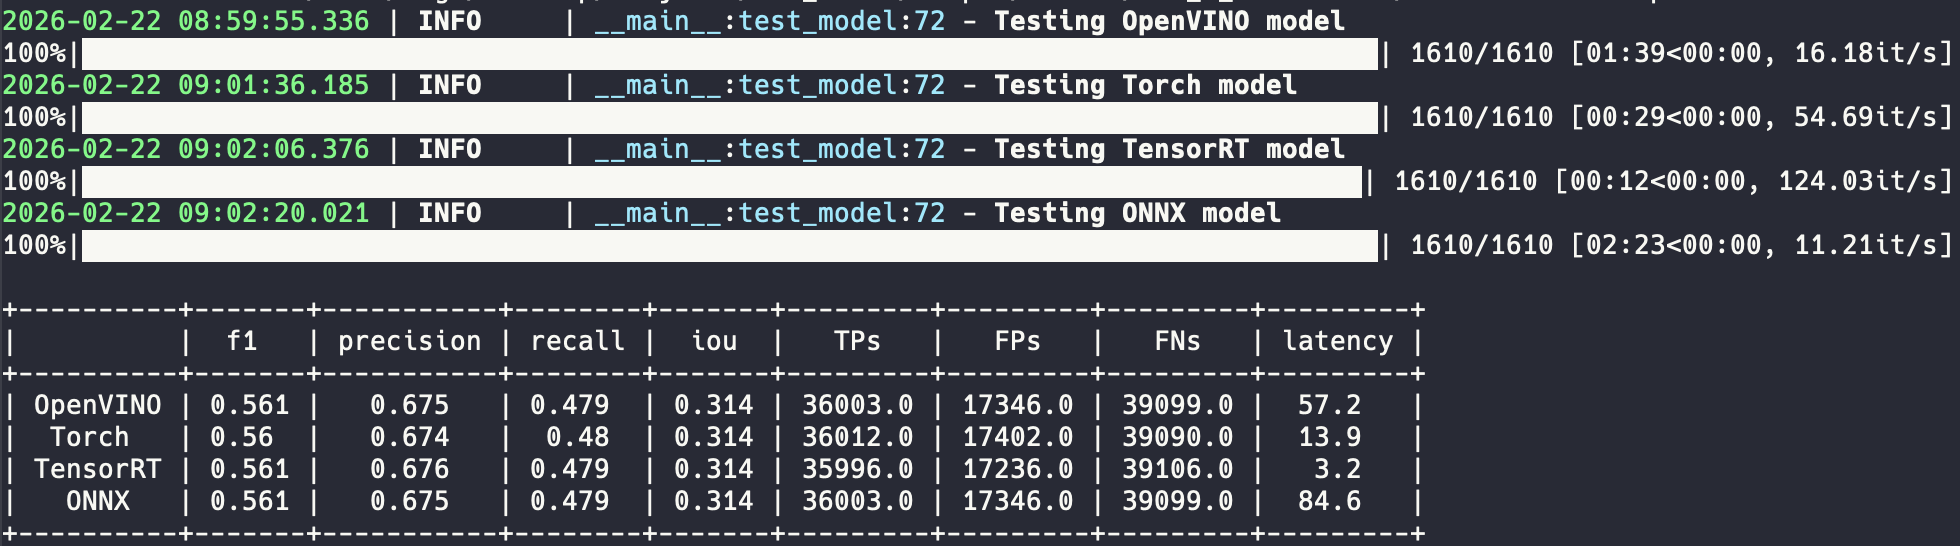
Benchmarking
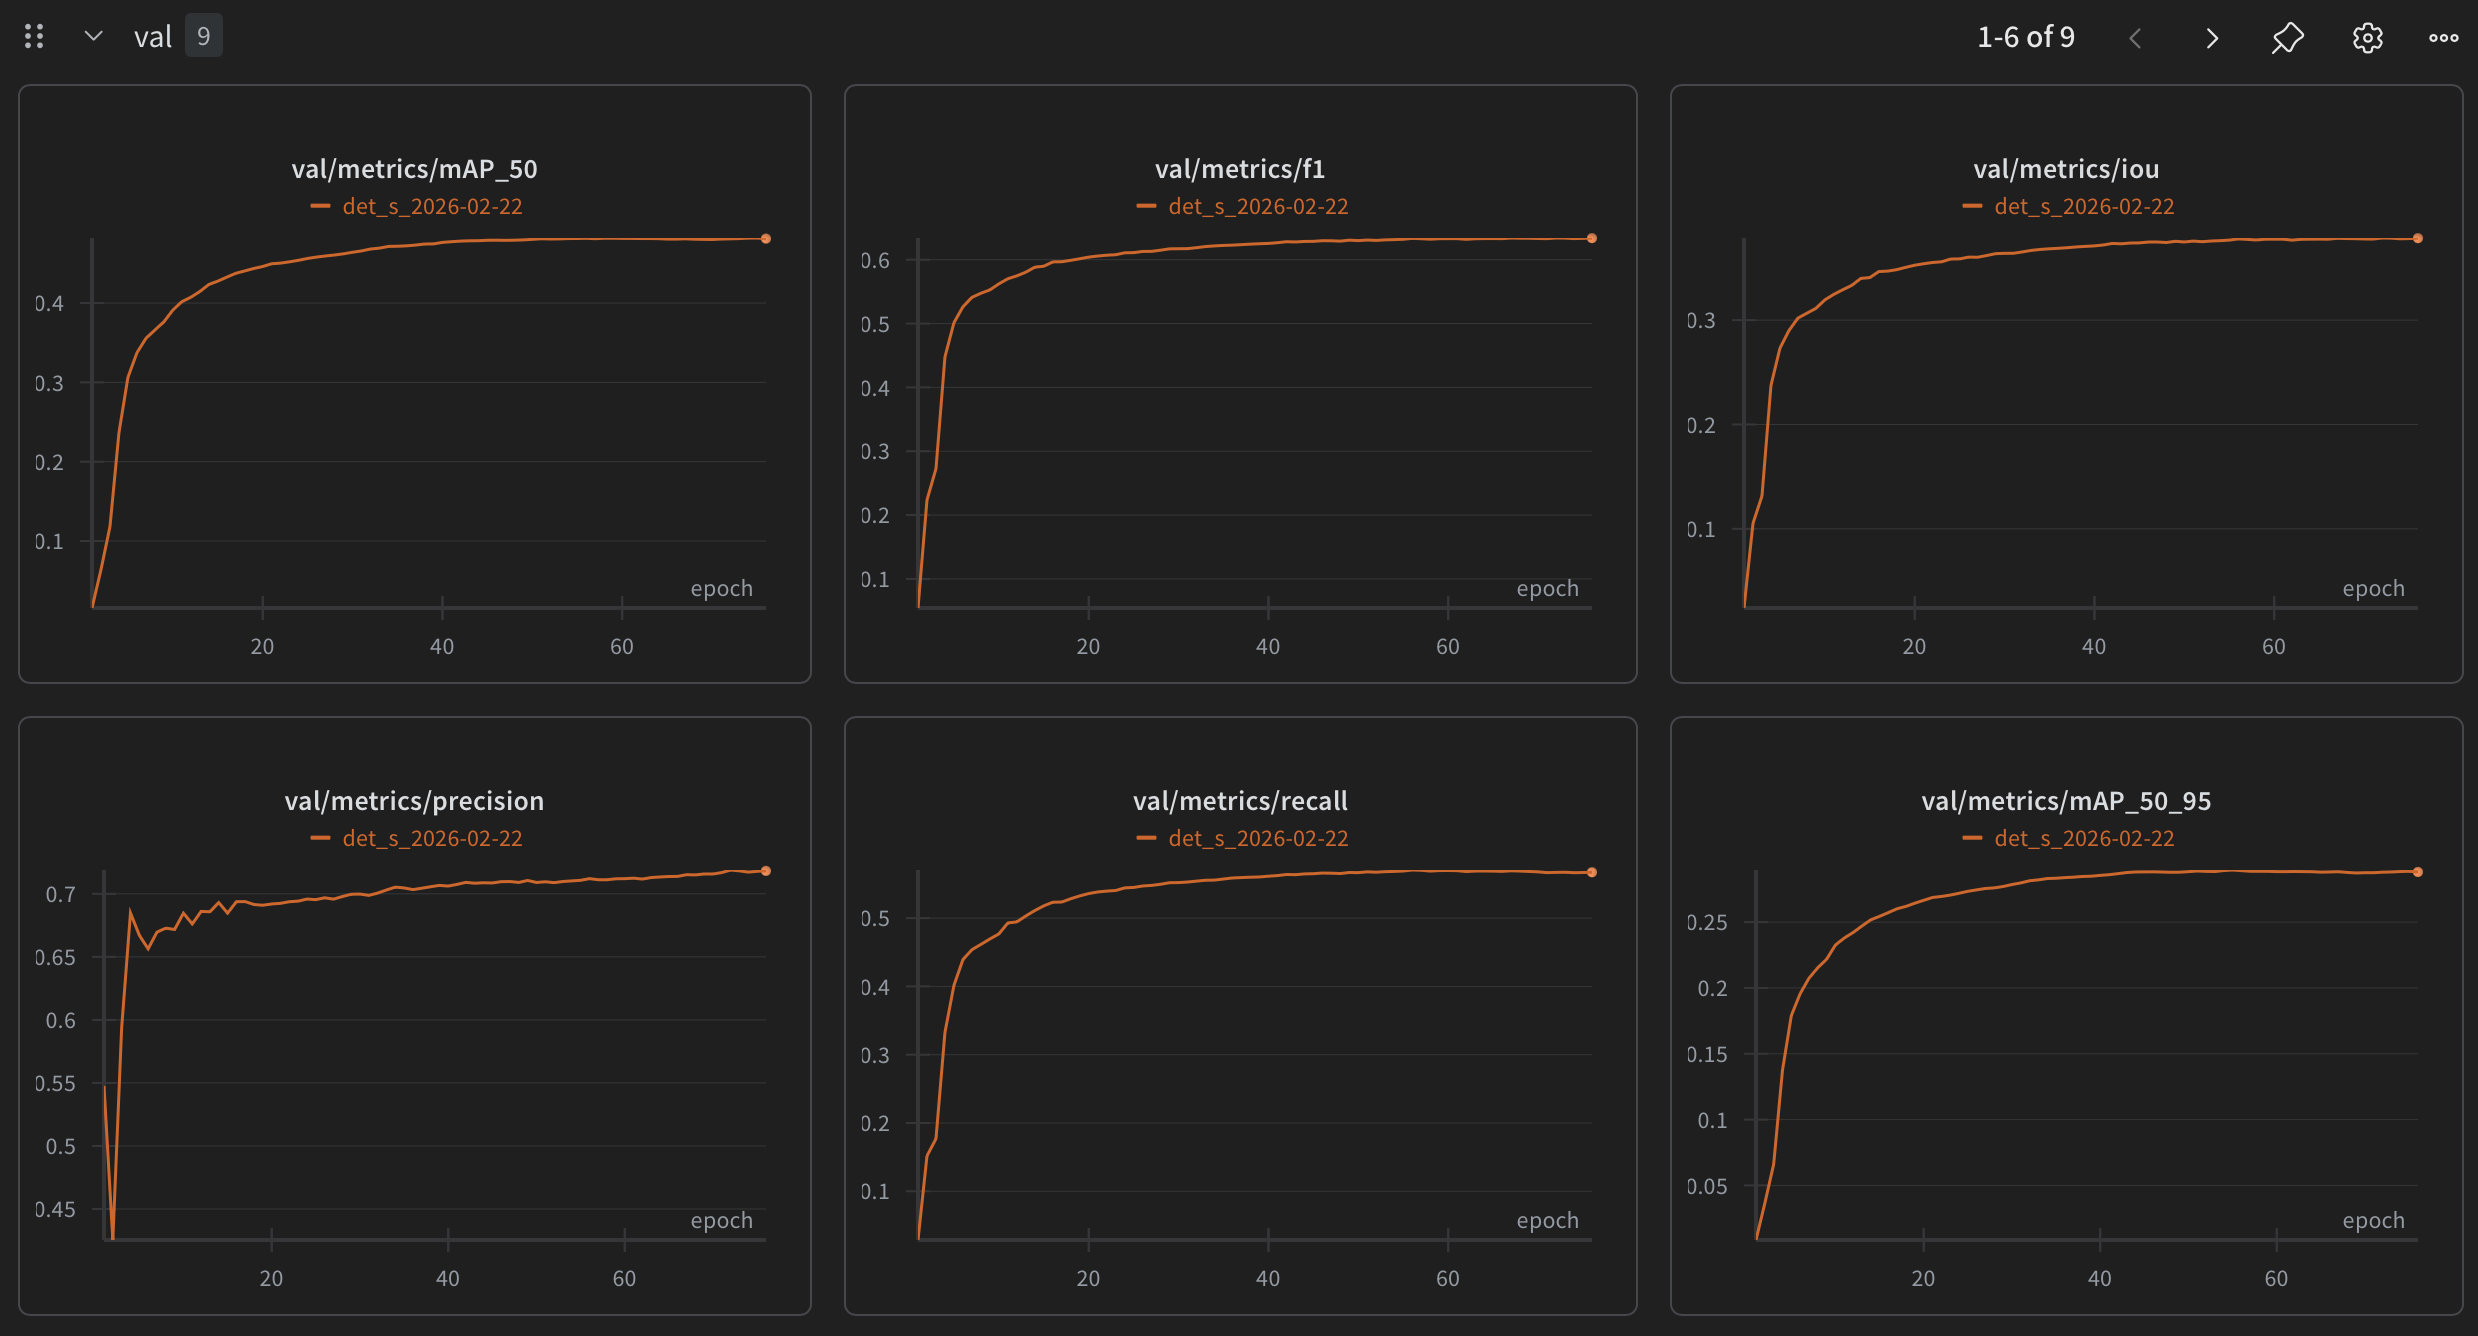
WandB dashboard
Inference
Contributing
Questions, bug reports and change proposals go to GitHub Issues. Read CONTRIBUTING.md before opening a pull request: changes are discussed in an issue first.
Citation
If you use D-FINE-seg in your research, please cite:
@article{saakyan2026dfineseg,
  title={D-FINE-seg: Object Detection and Instance Segmentation Framework with multi-backend deployment},
  author={Saakyan Argo and Solntsev Dmitry},
  eprint={2602.23043},
  journal={arXiv preprint arXiv:2602.23043},
  year={2026}
}
And the original D-FINE paper:
@misc{peng2024dfine,
      title={D-FINE: Redefine Regression Task in DETRs as Fine-grained Distribution Refinement},
      author={Yansong Peng and Hebei Li and Peixi Wu and Yueyi Zhang and Xiaoyan Sun and Feng Wu},
      year={2024},
      eprint={2410.13842},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
If you use the Cityscapes-trained semantic-segmentation weights, also cite the Cityscapes dataset:
@inproceedings{Cordts2016Cityscapes,
  title={The Cityscapes Dataset for Semantic Urban Scene Understanding},
  author={Cordts, Marius and Omran, Mohamed and Ramos, Sebastian and Rehfeld, Timo and Enzweiler, Markus and Benenson, Rodrigo and Franke, Uwe and Roth, Stefan and Schiele, Bernt},
  booktitle={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2016}
}
License
The code is licensed under the Apache 2.0 License.
The released Cityscapes semantic-segmentation weights (dfine_sem_{n,s,m,l,x}_cityscapes.pt) are derivative works of the Cityscapes dataset and inherit its terms of use: they may be distributed for non-commercial purposes such as academic research, teaching, scientific publications, or personal experimentation, but not for commercial gain. Train on your own data and the resulting model is yours to ship commercially - the code stays Apache-2.0 (no AGPL).
The COCO weights (detection, instance segmentation, person keypoints) are released under Apache-2.0. They were trained on COCO annotations (CC BY 4.0).
Acknowledgement
The detection core is based on the D-FINE paper and architecture. The mask head design follows the Mask DINO paradigm. Thank you to both teams for their excellent work.
Benchmarks in this project use the COCO, Cityscapes, VisDrone and TACO datasets. We thank the authors for making these datasets publicly available.

ultralytics
ultralytics·Python
YOLO 系列官方实现库,一套 PyTorch 代码覆盖目标检测、实例与语义分割、图像分类、姿态估计和目标跟踪,训练到部署全流程打通。
目标检测+4检测 / 分割入门
63283+10012kv8.4.2102026-11-10 23:12 UTC

yolov5
ultralytics·Python
基于 PyTorch 的目标检测全家桶,覆盖训练、推理、实例分割、图像分类和模型导出,开箱即用,适合快速落地视觉任务。
目标检测+4检测 / 分割
58260+717kv7.02026-11-07 16:59 UTC
pytorch-image-models
huggingface·Python
收录最全的 PyTorch 图像骨干网络合集,涵盖 ResNet、ViT、ConvNeXt 等主流模型,自带训练、评估、推理和导出脚本及预训练权重,省去自己搭网络和找权重的麻烦。
图像分类+4检测 / 分割
37274+95.2kv1.0.312026-11-07 23:22 UTC

detectron2
facebookresearch·Python
Detectron2 是 Facebook 开源的目标检测与分割平台,提供模块化架构和丰富预训练模型,方便快速搭建和训练视觉识别任务。
目标检测+4检测 / 分割
34981+67.9kv0.62026-10-27 09:21 UTC