模型权重需单独从 Hugging Face 下载,仓库不含 checkpoint;GPA-v1.5 的语音转换(VC)尚未实现,仅在路线图中;GPA-TTS 与 GPA-v1.5 是两套独立运行时,按需选择对应目录的文档。
GPA
AutoArkApache-2.0更新放缓一个超小型的通用音频模型,用同一套权重同时完成语音识别、语音合成和音色转换,省去为每种任务单独部署模型。
[AutoArk] GPA (General Purpose Audio) can do ASR, TTS and voice conversion with one tiny model!
暂无版本3,055star201fork同步于 2026-11-10 05:41 UTC
git clone https://github.com/AutoArk/GPA
cd GPA/GPA_1.5 硬件要求按 README 说明
README 未说明显存要求;GPA-TTS 明确针对本地 CPU 推理优化(Mac / Linux / 边缘设备),GPA-v1.5 主干需从 Hugging Face 下载权重。
一个 0.6B 自回归模型同时做 ASR 和 TTS,省去维护多套语音模型
一个超小型的通用音频模型,用同一套权重同时完成语音识别、语音合成和音色转换,省去为每种任务单独部署模型。
核心能力
- 用单个自回归 Transformer 统一语音识别与合成
- GPA-v1.5 提供原生 PyTorch 推理与微调流程
- 附带 ONNX Runtime 的 CLI、FastAPI 服务与浏览器 UI
- GPA-TTS 独立运行时支持零样本声音克隆
- 解码器可选 INT8/FP16/FP32 精度平衡质量与开销
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
暂无 release 数据(可能没有发版,或尚未同步)。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
GPA: One Model for Speech Recognition, Text-to-Speech, and Voice Conversion


-
🚀 2026.04.29: GPA-v1.5 is here! GPA v1.5 Delivers near-SOTA TTS and ASR performance—in a single unified model. Start here →
-
🚀 2026.04.29: GPA-v1.5 ONNX Runtime is now available! Run ASR/TTS through ONNX CLI tools, a FastAPI service, or the browser UI with the new GPA-v1.5 ONNX runtime guide and runtime asset bundle.
-
🆕 2026.04.07: GPA-TTS FP16/FP32 Decoder — Higher-quality decoder options now available! For users with extra compute headroom, FP16 and FP32 SparkDetokenizer decoders are now available alongside INT8, delivering more stable and higher-quality speech synthesis. Selectable at runtime via CLI, API, or Web UI. Details →
-
📌 2026.03.31: GPA-TTS — Standalone lightweight TTS runtime released! Extracted from GPA with INT8/INT4 quantization for edge deployment. Among the smallest open-source TTS runtimes with voice cloning support! Details →
-
📚 GPA-v1.0 docs have moved. The original GPA-0.3B-preview quick start, deployment, benchmark, and evaluation pages now live in docs/GPA-v1.0.md.
📖 Abstract
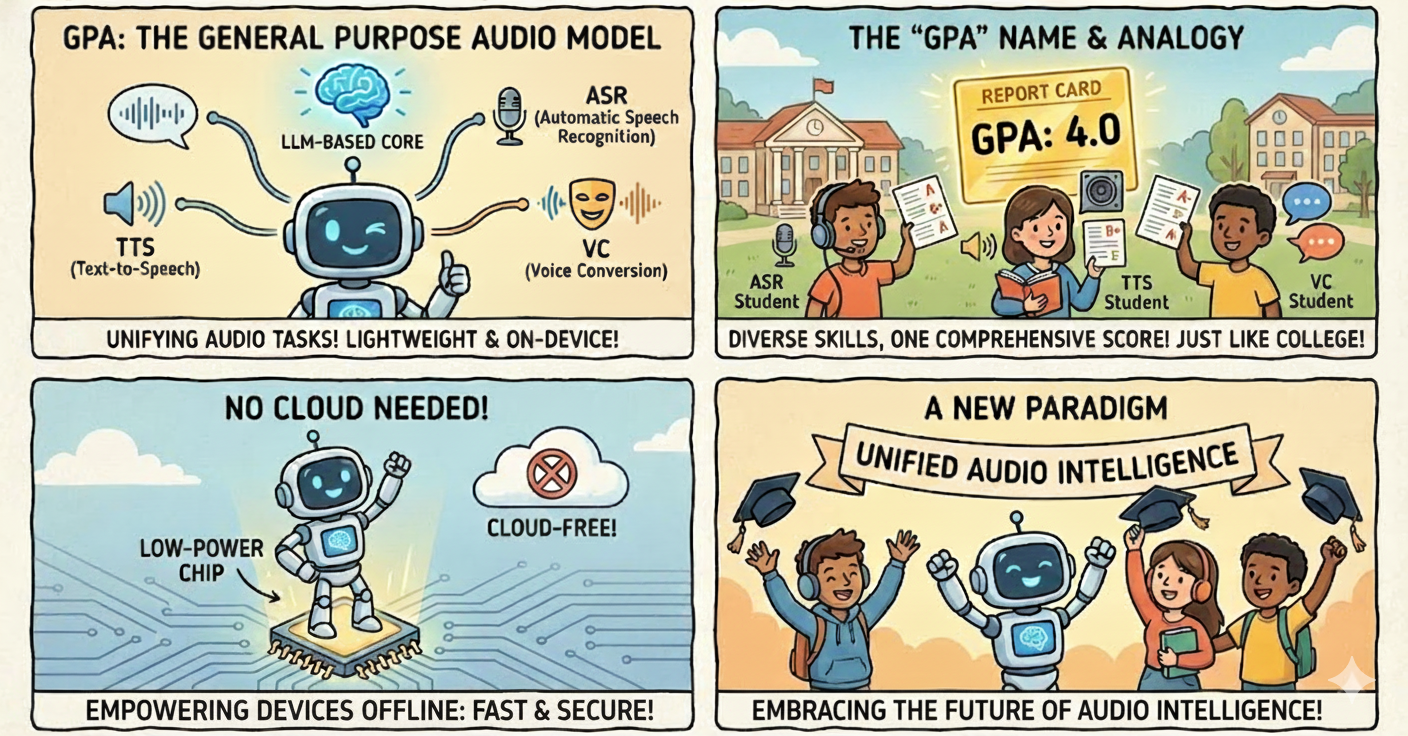
GPA stands for General Purpose Audio.
A student’s GPA unifies performance across diverse subjects—from Calculus to Gym—into a single metric. Likewise, our GPA model integrates the three core audio tasks—TTS, ASR, and Voice Conversion—into one auto-regressive transformer.
GPA-v1.5 now delivers near-SOTA performance on ASR and TTS in a single unified model, with VC support on the roadmap.
🗺️ Roadmap · 🚀 GPA-v1.5 Release · 🎙️ GPA-TTS · 🧭 GPA-v1.0 Archive · 📊 GPA-v1.5 Evaluation · 🔗 Citation
🗺️ Roadmap
| Category | Item | Status |
|---|---|---|
| Core Features | Unified LLM-based audio generation & understanding | ✅ |
| Native GPA-v1.5 Inference Pipeline | ✅ | |
| Native GPA-v1.5 Training Pipeline | ✅ | |
| GPA-v1.5 ONNX Runtime CLI/API/UI | ✅ | |
| GPA-v1.5 Interactive Demo | ⬜ | |
| GPA-v1.5 Basic Service Deployment (vLLM/FastAPI) | ⬜ | |
| Paper (ArXiv) | ✅ | |
| Model Releases | GPA-0.3B-preview | ✅ |
| GPA-v1.5 — major mainline release | ✅ | |
| GPA-TTS — Lightweight TTS runtime (INT8/FP16/FP32 + INT4 ONNX) | ✅ | |
| GPA-v1.5 Next Steps | Voice Conversion native path | ⬜ |
| Expanded deployment recipes | ⬜ | |
| Frameworks | torch | ✅ |
| vllm | ✅ | |
| llama-cpp | ✅ | |
| sglang | ✅ | |
| mlx-lm | ✅ | |
| rknn | ⬜ |
🚀 GPA-v1.5 Release!
GPA-v1.5 is the new mainline release of GPA: a larger, cleaner, more capable unified audio model for ASR and TTS, with native PyTorch workflows and ONNX runtime deployment now available.
| GPA-v1.5 | |
|---|---|
| Checkpoint | Open-sourced on Hugging Face |
| Native Inference | Direct PyTorch / Hugging Face execution for ASR and TTS |
| Native Training | Fine-tuning and continued training with Hugging Face Trainer |
| ONNX Runtime | CLI inference, FastAPI service, browser UI, voice registration, and runtime validation |
| Planned | Voice Conversion support in the native v1.5 path |
📖 GPA-v1.5 README → | 🏋️ Training Guide → | 🎧 Inference Guide → | ⚙️ ONNX Runtime Guide → | 🤗 Download from HuggingFace
🎙️ GPA-TTS: Edge-Ready Voice-Cloning TTS
We noticed that TTS is by far the most popular feature in our online demo. While GPA-v1.5 ships as a larger unified model, we extracted the TTS component into a standalone, self-contained runtime:
| GPA-TTS | |
|---|---|
| Quantization | Qwen INT4 + Detokenizer INT8 / FP16 / FP32 (ONNX Runtime) |
| Voice Cloning | Zero-shot, from a short reference audio |
| Decoder Precision | Selectable at runtime — INT8 (edge), FP16 (balanced), FP32 (highest quality) |
| Footprint | Among the smallest open-source TTS runtimes with cloning support |
| Optimized for | Local CPU inference (Mac / Linux / Edge) |
📖 GPA-TTS README → | 🤗 Download from HuggingFace
🧭 GPA-v1.0 Archive
The original GPA-0.3B-preview homepage has been preserved for users who still rely on the v1.0 quick start, deployment recipes, benchmarks, and evaluation tables.
| GPA-v1.0 | |
|---|---|
| Model | GPA-0.3B-preview |
| Docs | Original quick start, checkpoint download, inference, training, deployment, performance, and evaluation |
| Best for | Reproducing the initial release or maintaining existing v1.0 integrations |
| Downloads | Hugging Face and ModelScope links from the original release |
📖 GPA-v1.0 README → | 🤗 Hugging Face | 🤖 ModelScope
📊 GPA-v1.5 Evaluation Metric Results
TTS Evaluation Table
| Model | Open-Source | Model Size | test-zh CER (%) ↓ | test-zh Sim (%) ↑ | test-en WER (%) ↓ | test-en Sim (%) ↑ |
|---|---|---|---|---|---|---|
| Multi-Stage or NAR Methods | ||||||
| Human | - | - | 1.26 | 75.5 | 2.14 | 73.4 |
| Seed-TTS | ❌ | - | 1.12 | 79.6 | 2.25 | 76.2 |
| MiniMax-Speech | ❌ | - | 0.83 | 78.3 | 1.65 | 69.2 |
| F5-TTS | ✅ | 0.3B | 1.52 | 74.1 | 2.00 | 64.7 |
| CosyVoice2 | ✅ | 0.5B | 1.45 | 75.7 | 2.57 | 65.9 |
| FireRedTTS2 | ✅ | 1.5B | 1.14 | 73.2 | 1.95 | 66.5 |
| Index-TTS2 | ✅ | 1.5B | 1.03 | 76.5 | 2.23 | 70.6 |
| VibeVoice-1.5B | ✅ | 1.5B | 1.16 | 74.4 | 3.04 | 68.9 |
| VibeVoice-Realtime | ✅ | 0.5B | - | - | 2.05 | 63.3 |
| HiggsAudio-v2 | ✅ | 3B | 1.50 | 74.0 | 2.44 | 67.7 |
| VoxCPM | ✅ | 0.5B | 0.93 | 77.2 | 1.85 | 72.9 |
| GLM-TTS | ✅ | 1.5B | 1.03 | 76.1 | - | - |
| GLM-TTS RL | ✅ | 1.5B | 0.89 | 76.4 | - | - |
| Fun-CosyVoice3-0.5B-2512 | ✅ | 0.5B | 1.21 | 78.0 | 2.24 | 71.8 |
| Fun-CosyVoice3-0.5B-2512_RL | ✅ | 0.5B | 0.81 | 77.4 | 1.68 | 69.5 |
| One-Stage AR Methods | ||||||
| Spark TTS | ✅ | 0.5B | 1.20 | 66.0 | 1.98 | 57.3 |
| GPA-v1.5 | ✅ | 0.6B | 1.03 | 70.2 | 1.43 | 63.5 |
ASR Evaluation Table
Note: ASR results on LibriSpeech, AISHELL-1, test_Meeting, and test_Net. WER (%) is reported for LibriSpeech; CER (%) is reported for AISHELL-1. The additional test_Meeting and test_Net columns follow the corresponding benchmark metric used in our evaluation.
| Model | Model Size | LibriSpeech test-clean | LibriSpeech test-other | AISHELL-1 | test_Meeting | test_Net |
|---|---|---|---|---|---|---|
| Whisper-S | 0.24B | 3.43 | 7.63 | - | - | - |
| GPA-v1.5 | 0.6B | 2.78 | 5.02 | 2.83 | 7.40 | 6.49 |
| Fun-ASR-nano | 0.8B | 1.76 | 4.33 | 1.80 | 6.60 | 6.01 |
| FireRed-ASR | 1.1B | 1.84 | 4.52 | 0.54 | 4.95 | 4.94 |
| GLM-ASR-nano | 1.5B | 2.00 | 4.19 | 1.81 | 6.73 | - |
| GLM-ASR-nano* | 1.5B | 2.17 | 4.43 | 2.17 | 8.21 | 6.33 |
| Whisper-L | 1.55B | 1.86 | 3.43 | 4.72 | 18.39 | 11.89 |
| Kimi-Audio | - | 1.32 | 2.63 | 0.71 | 6.24 | 6.45 |
| Step-Audio2 | - | 1.17 | 2.42 | 0.63 | 4.75 | 4.67 |
| Seed-ASR | - | 1.58 | 2.84 | 0.68 | 5.69 | 4.66 |
| Seed-ASR* | - | 2.80 | 5.69 | 1.63 | 7.07 | 4.84 |
| Fun-ASR | 7.7B | 1.51 | 3.03 | 1.22 | 6.17 | 5.46 |
🔗 Citation
If you find GPA useful for your research or projects, please cite us:
@misc{cai2026unifyingspeechrecognitionsynthesis,
      title={Unifying Speech Recognition, Synthesis and Conversion with Autoregressive Transformers},
      author={Runyuan Cai and Yu Lin and Yiming Wang and Chunlin Fu and Xiaodong Zeng},
      year={2026},
      eprint={2601.10770},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2601.10770},
}

VoiceStudio
debpalash·Python
本地运行的 ElevenLabs 开源替代品,支持声音克隆、语音设计、视频配音、听写、转写和有声书制作,覆盖 646 种语言。
语音克隆+4语音推理
106379+325512kv0.5.72026-11-10 05:13 UTC

voicebox
jamiepine·Python
开源 AI 语音工作室,支持声音克隆、语音听写和语音生成,基于 Qwen3-TTS 与 Whisper,可在 CUDA 或 MLX 上本地运行。
语音克隆+4语音推理
60319+5667.6kv0.5.02026-10-07 01:17 UTC
whisper.cpp
ggml-org·C++
OpenAI Whisper 语音识别模型的 C/C++ 移植版,无需 Python 和 GPU 依赖,在普通 CPU 上就能跑语音转文字。
语音识别+4语音推理
55056+696.3kv1.9.52026-11-09 13:02 UTC
faster-whisper
SYSTRAN·Python
基于 CTranslate2 重实现的 Whisper 语音转文字推理引擎,通过量化与高效推理大幅提速并降低显存占用,适合本地部署转录。
语音识别+4语音推理
26633+612.2kv1.2.12026-11-06 17:24 UTC