仅支持 Windows,其他平台需自行改代码;需先装 Git LFS 与 Visual C++ Build Tools 才能拉取模型和编译依赖;有 GPU 想强制 CPU 安装需加 --force-cpu 参数。
VectorDB-Plugin
BBC-Esq活跃维护把本地文档和音视频文件建成向量库,用自然语言提问就能检索并回答,适合搭建私有 RAG 问答。
Program that lets you ask questions about your documents and audio or video files.
v10.1.0发布于 2026-10-18 13:13 UTC372star +1 / 7 天48fork同步于 2026-11-10 18:01 UTC
python -m venv .
.\Scripts\activate
python setup_windows.py
python gui.py 硬件要求按 README 说明
仅支持 Windows;需 Python 3.11–3.14。NVIDIA GPU 可选,GTX 16 系 / RTX 20 系及更新、驱动 580+ 可加速;无 GPU 时自动装 CPU 版并改用更小的模型。
纯 CPU 可运行
Windows 桌面工具,把文档、图片、音视频转成向量库,为本地或在线 LLM 提供 RAG 检索上下文
把本地文档和音视频文件建成向量库,用自然语言提问就能检索并回答,适合搭建私有 RAG 问答。
核心能力
- 支持 PDF、Office、图片、音频等十余种格式批量入库
- 图片自动生成描述、音频自动转写后再向量化
- 提问可打字或录音,检索相关片段后交给 LLM 作答
- 可接本地模型、Kobold、LM Studio 或 ChatGPT
- 可选文本转语音朗读回答
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v10.1.0最新正式版2026-10-18 · 2026-10-18 13:13 UTC
v10.1.0 — Add & Remove Documents
A feature release that lets you add and remove documents in an existing database, with new text-to-speech settings and smoother searching.
✨ Add and remove documents
- Add files or a whole folder to an existing database from the Manage Databases tab, skipping files it already has (6de77b6) (eba79ae) (50d1f43) (cb5ee31)
- Remove a single document from a database without rebuilding it (69ec0b2) (098f456) (0edaf6a) (20b00e0)
- Added and removed documents show up in searches right away (8d1301f) (f67b54f)
- The Manage Databases tab shows how many documents changed, and a new Rebuild index button folds them in (5929e3b) (f50a321) (24cc7aa)
- Adding files can be cancelled at any time without changing the database (eba79ae) (1d4a98f)
🛡️ Safer databases and backups
- Backups older than their database are flagged, with a button to update them (f76c9d1)
- Builds, backups, restores and document changes no longer run at the same time (ec71f26) (eba79ae)
- Each database keeps its creation date, and its file and chunk counts stay accurate after changes (22b8efe) (6429ebc)
🔊 Text-to-speech
- Text-to-speech backends can run on a chosen device and precision, shown on a card with their speed and memory use (7b20e1e) (8d34b79) (1967322) (db304d0)
- Precision updates: Kyutai and Kyutai Pocket use half precision on a GPU (1a1fdd6), Bark offers half precision (82615f2) (d0b0711), and ChatTTS is now offered only on GPU computers (9933bbe)
- Dropped settings: Kyutai Pocket's int8 option (561068f) and Kokoro's speed setting (db304d0)
- Chatterbox installs a stable release instead of the latest development code (f171c2a)
🖥️ Interface
- The Settings tab shows the vision model as a card beside its dropdown (c9d1313) (1d42d6e) (cd216ae)
- Setting notes now appear as tooltips, and a chunk size above the model's limit is highlighted (3171b80) (ea6dc31)
- Ask Jeeves has a new picture and a new poem (7451fed) (ed5fb0a)
- The main window is slightly taller, so the Settings tab fits without scrolling (fc2d4ce)
🐛 Smaller improvements and fixes
- Switching chat models no longer reloads the database, switching databases frees the old one, and Eject unloads both (94ff0d7) (6e005aa)
- The question stays in the box after asking, and a new search replaces the previous answer (f858d0b) (7406000)
- Audio with no speech now gives a warning instead of an empty transcript (d1538ac) (72eb9a1)
- Closing the program no longer shows an error (e3a06c3)
📖 Documentation
- The user guide and Ask Jeeves cover every new feature (7c2288f) (1979885) (268580b) (b5019b9) (c2a201d)
- The README now shows screenshots of the program (8cf188e) (94a4e40)
- The test suite is now included so contributors can check their changes (b2760ca)
- v10.0.02026-10-09 · 2026-10-09 01:59 UTC
查看更新说明
v10.0.0 — Rebuilt Interface & CPU-Only Mode
A major release: every tab is rebuilt as a modern page, the program now installs and runs without an NVIDIA GPU, the AI stack moves to PyTorch 2.14 and transformers 5, and dozens of fixes make database builds, OCR, search and speech more reliable.
🖥️ A rebuilt interface
- Every tab, the Ask Jeeves window and the Chat Backend Settings dialog were rebuilt as modern pages that share one theme and one set of tooltips and menus (0dd6d72)
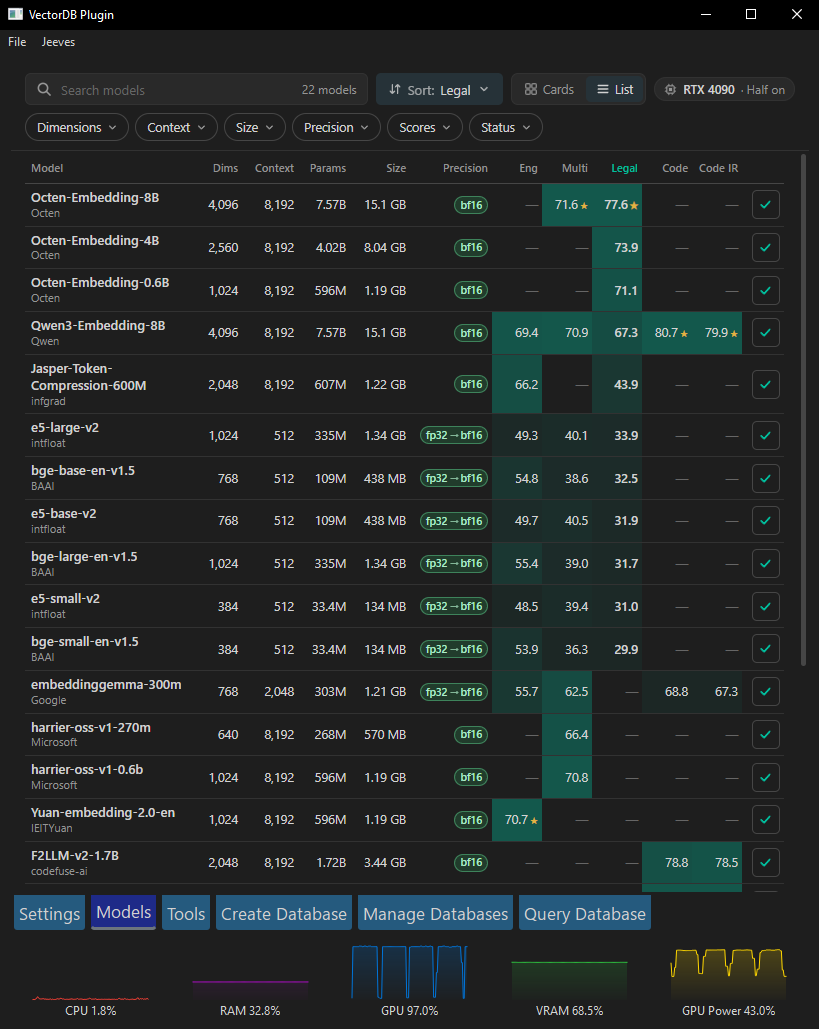
- The Models tab shows each embedding model as a card with its specs, benchmark scores, the precision it will run in on your computer and its own Download button, plus search, filters, sorting and a compact list view (ec0231a)
- The Settings tab fits on one screen, saves each change as you make it and checks values as you type (1a4b894)
- The Tools tab shows each tool's progress and results inside the tab, including a page-by-page OCR progress bar, and a sortable GPU list replaces the old chart (6251eb0)
- The Create Database tab lets you add and review files inside the tab, checks the database name as you type, runs the PDF check in the background and shows each build stage live with a log (e4bb37c)
- Tokenization now appears as its own build step between Splitting and Embedding (cb7b528)
- The Manage Databases tab lists every database with its size, file and chunk counts and backup status, opens or reveals the original files, and deletes, backs up or restores a database after a confirmation in the tab; its button for searching a database is now called Query (a791671)
- The Query Database tab streams answers into cards with their sources, scores and page numbers, shows each passage in Chunks only mode, and handles missing keys, speech, dictation and model ejecting in the tab instead of pop-ups (7ce207a)
- Ask Jeeves is now a chat-style window that keeps its familiar picture and shows sources, read-aloud and poems inline (d0d847d)
- Chat Backend Settings lists each backend with its status, saves changes as you make them, keeps keys masked, adds a key field for MiniMax and can test the connection to ChatGPT, LM Studio and Kobold (5e421a7)
- The user guide and the Ask Jeeves knowledge base were updated for every new tab, model and setting (3be4010)
💻 CPU-only mode
- The program now runs on computers without a supported NVIDIA GPU: the installer sets up the CPU version automatically (or when run with
--force-cpu), and at startup a GPU too old for the bundled PyTorch is skipped so the program runs on the CPU instead (c2313fc) - File transcription and InternVL vision models work on the CPU, Half precision no longer blocks CPU database builds, and a build with images is refused up front if the chosen vision model needs a GPU, instead of silently skipping the images (844208e)
- CPU installs offer only the chat, vision and embedding models that performed well in CPU benchmarks, and a saved GPU-only choice switches to Liquid-VL 480M or is refused with a clear message (d858cfd)
- CPU installs show speed notes and LM Studio tips, a failed text-to-speech run is reported in a dialog, and the README and guide explain CPU-only mode (f1373c3)
- The Models tab's CPU build-time estimates now cover the new embedding models (a54b2ac)
- On a GPU computer, choosing CPU for database creation now asks for confirmation instead of always being refused (47694a1)
✨ New models
- New embedding model: Jasper-Token-Compression-600M (b81783c)
- New embedding model: Yuan-embedding-2.0-en, a 596M English retrieval model (6ca0284)
- New embedding model: F2LLM-v2-1.7B, especially strong on code (b0e51f5)
- New embedding model: F2LLM-v2-4B, for GPU installs (3ab12ff)
- New embedding model: geevec-embeddings-1.0-lite (5f6514a)
- Each embedding model now lists its multilingual, English, legal and code retrieval benchmark scores instead of a rough rank (fdac033)
- Two new Whisper models in the Transcribe File tool, Whisper large-v3 turbo and Distil Whisper large-v3.5, each
- v9.4.02026-07-23 · 2026-07-23 12:58 UTC
查看更新说明
What's Changed
🔍 OCR
- Added a RapidOCR backend (PP-OCRv6) and made it the default engine in the OCR tool.
- Page-level OCR gating now considers text quality, layout, and imagery instead of just "is there any text."
- Rotated and inverted scans are detected and corrected automatically.
- Low-confidence, blank, and failed pages are surfaced as quality notes when the job finishes.
- Output is verified against the source, and one bad file no longer kills the batch.
🗄️ Database Creation
- The TileDB write now runs in an isolated subprocess, fixing heap-corruption crashes on large builds.
- Vector handoff is memmapped and sharded, so peak memory stays at roughly one batch.
- Failed builds clean up after themselves instead of leaving a half-written database behind.
- Cancelling a build now terminates the entire subprocess tree.
- Subprocess stages use UTF-8 I/O, so non-ASCII filenames no longer break logging.
🖥️ Interface
- Jeeves searches on a worker thread and no longer freezes the window.
- The staged-documents view was rebuilt on a lightweight model, removing filesystem-watcher stalls.
- Duplicate staging and image-processing jobs are now blocked while one is running.
- Settings input validation is clearer and tolerates locale number formatting.
⚙️ Configuration
- All config writes are atomic, so an interrupted save can't truncate
config.yaml. - Config loading preserves valid fields instead of discarding everything on one bad entry.
- Dialogs refuse to write when a read comes back empty, preventing accidental clobbering.
🕸️ Documentation Scraper
- Fixed scraper mappings for joblib, SQLAlchemy 2.0, and typing-inspection.
- Mintlify rendering handles indentation, inline components, and leftover MDX tags correctly.
- URLs are canonicalized, so the same page is no longer saved twice.
- Scrape counts and resume behavior are now accurate.
🧹 Fixes & Polish
- File extensions are normalized, so uppercase
.PDFfiles get proper metadata. - Text loaders try
cp1252beforelatin-1and no longer mix encodings mid-file. - Vision prompts use the correct tokens and decode only newly generated output.
- A failed model download no longer deletes an existing model directory.
- Microphone errors are reported safely across threads.
- v9.3.0v9.3.0 - the finale2026-06-05 · 2026-06-05 14:13 UTC
查看更新说明
Release Notes
This release brings a major refresh of the model lineup, a rebuilt Ask Jeeves assistant, a new MiniMax backend (credit to @octo-patch), and a large round of dependency upgrades and stability fixes. It's likely the last release before upgrading to
transformers5+, which will enable additional features but may deprecate certain models.🤖 Chat Models
New models
Model Details Phi 4 – 14b ➕ Excels at not hallucinating, essential for RAG Gemma 3 – 4b ➕ Excels at not hallucinating, essential for RAG Gemma 3 – 12b ➕ Excels at not hallucinating, essential for RAG Granite – 3b 🔄 Upgraded from Granite 3.3 → 4.1 Granite – 8b 🔄 Upgraded from Granite 3.3 → 4.1 LiquidAI – 1.2b 🔄 Updated to LFM2.5-1.2B-Instruct - Qwen 3 models now run in non-thinking mode for direct, concise answers. Research shows that "thinking" appreciably reduces quality for purposes of RAG.
Removed Models Deepseek R1 – 8b GLM4-Z1 – 9b GLM4-Z1 – 32b Seed Coder – 8b EXAONE Phi 4 Mini – 4b Qwen 3 – 4b (Thinking) Qwen 3 – 32b - All removed models are either too heavy for too low quality compared to newer models or require "thinking" (or both).
🧬 Embedding Models
New models
Model Details harrier-oss-v1-270m ➕ Great generalist and also excels at multilingual (~94 languages) harrier-oss-v1-0.6b ➕ Great generalist and also excels at multilingual (~94 languages) Octen-Embedding-0.6B ➕ Great generalist and also excels at legal, medical, finance, and code. Octen-Embedding-4B ➕Great generalist and also excels at legal, medical, finance, and code. Octen-Embedding-8B ➕ Great generalist and also excels at legal, medical, finance, and code. modernbert-embed-base_finetune_512 ➕ Excels at legal. modernbert-embed-base_finetune_8192 ➕ Excels at legal EmbeddingGemma ➕ Google, 300M — Strong and efficient generalist Removed Model Granite-30m-English Granite-125m-English inf-retriever-v1-1.5b inf-retriever-v1-7b arctic-embed-m-v2.0 arctic-embed-l-v2.0 - The removed models were essentially superseded by smaller models with at-par or better results.
👁️ Vision Models
New / updated models
Model Details [Liquid-VL – 480M - v9.2.02026-05-05 · 2026-05-05 18:41 UTC
查看更新说明
🎨 Theming Overhaul
- Replaced 25+ individual CSS files with a single template-based theming system using variable substitution
🤖 Chat Backend Improvements
- New unified Chat Backend Settings dialog (File menu) with tabs for ChatGPT, LM Studio, MiniMax, and Kobold
- Added support for OpenAI's GPT-5.4 and GPT-5.5 model families with verbosity and reasoning effort controls
- Live API cost panel displays input/cached/output pricing per model
- Migrated ChatGPT integration to OpenAI's Responses API for streaming
- Improved thinking-tag stripping in LM Studio chat to handle tags split across stream chunks
📚 Database & Document Processing
- Added support for
.htmfiles alongside existing.htmlingestion - Folder selection now prompts whether to include subdirectory files
- New Cancel button for in-progress database creation with automatic cleanup of partial files
- Enhanced info bar showing queued files, chunk size, overlap, and embedding precision in real-time
- Symlink creation now handles filename collisions via hash-based disambiguation
🕷️ Documentation Scraper
- New Resume capability for interrupted scrapes — pick up where you left off instead of starting over
- Added Mintlify scraper for
llms.txt-based documentation sites (including Model Context Protocol docs) - Rate-limit detection (HTTP 429) automatically pauses scrapes and persists state for later resumption
- Added scrapers for
curl_cffi,emoji,lxml,onnx,pyparsing, anduvdocumentation
🔧 UI Polish & Fixes
- Reorganized Database Query and Database Creation tabs with cleaner grid layouts
- Vector Models tab now allows re-downloading already-downloaded models with confirmation
- Voice recorder button now shows "Stop Recording" while active
- Submit Question button now styled green and set as default
- Removed unused chat history file writes and Jeeves context spinner
- Fixed search term filter tooltip (now correctly describes inclusion, not exclusion)
🐛 Bug Fixes
- Fixed TileDB search returning misaligned results when vector IDs don't match query order
- Fixed transcription and OCR worker processes to properly surface errors via exit codes
- Fixed PDF and audio file handles to use context managers, preventing resource leaks
- Fixed checkpoint saves to use atomic
os.replacewith retry on Windows permission errors - Removed dependency on LangChain in favor of internal
Documentclass
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
Create and search a vector database from a wide variety of file types and get more reliable responses from an LLM. This is commonly referred to as "retrieval augmented generation."
| Tool | Purpose |
|---|---|
| 🪟 Microsoft Windows | Only for Windows but open to pull requests |
| 🐍 Python 3.11–3.14 | Run the application |
| 🌿 Git | Clone / manage the repository |
| 🧲 Git LFS | Handle large model files |
| 🛠️ Visual C++ Build Tools | Required for compiling dependencies |
| 🎮 NVIDIA GPU (optional) | GTX 16-series / RTX 20-series or newer (driver 580+) for GPU acceleration; without one the program runs in CPU-only mode |
Install:
winget install Microsoft.VisualStudio.2022.BuildTools --silent --accept-source-agreements --accept-package-agreements --override "--wait --quiet --add Microsoft.VisualStudio.Component.VC.Tools.x86.x64 --add Microsoft.VisualStudio.Component.Windows11SDK.22621"
Verify installation:
Test-Path "C:\Program Files\Microsoft Visual Studio\2022\BuildTools\VC\Tools\MSVC"
Download the latest "release," extract, navigate to the src folder, and run the following commands:
python -m venv .
.\Scripts\activate
python setup_windows.py
python gui.py
[!TIP] The installer detects your hardware automatically. If no supported NVIDIA GPU is found, it installs the CPU-only version, which offers smaller models suited to running on a CPU. To force a CPU-only install on a computer that has a GPU, run
python setup_windows.py --force-cpuinstead.
Inputs → Processing → Vector Database
| 📂 Ingest | 📄 .pdf, .docx, .txt, .html, .htm, .md, .csv, .xls, .xlsx, .xlsm, .rtf, .eml, .msg 🖼️ .png, .jpg, .jpeg, .bmp, .gif, .tif, .tiff 🎵 .mp3, .wav, .m4a, .ogg, .wma, .flac |
| ⚙️ Process | 📝 Extract text from documents 🖼️ Generate descriptions from images 🎧 Transcribe speech from audio |
| 🧠 Store | All processed content is embedded and saved into the vector database for searching. |
Query → LLM → Output
| ❓ Ask | ⌨️ Type or 🎙️ record a question |
| 🧠 Retrieve | Relevant chunks are pulled from the vector database |
| 🤖 Generate | Sent to an LLM (Local Model, Kobold, LM Studio, or ChatGPT) |
| 💬 Respond | LLM returns an answer based on the context you provided |
| 🔊 Optional | Text-to-speech can read the response aloud |
[!NOTE] Instructions on how to use the program are being consolidated into the
Ask Jeevesfunctionality, which can be accessed from the "Ask Jeeves" menu option. Please create an issue if Jeeves is not working.
Feel free to report bugs or request enhancements by creating an issue on github and I will respond promptly.
I welcome all suggestions - both positive and negative. You can e-mail me directly at "[email protected]" or I can frequently be seen on the KoboldAI Discord server (moniker is vic49). I am always happy to answer any quesitons or discuss anything vector database related! (no formal affiliation with KoboldAI).
supabase
supabase·TypeScript
基于 Postgres 的一站式后端开发平台,提供专用数据库、认证、存储和向量检索能力,可替代 Firebase 快速搭建 Web、移动和 AI 应用。
Postgres+4向量化 / 重排服务
114745+12415kv1.26.082026-11-10 17:13 UTC

Langchain-Chatchat
chatchat-space·Python
基于 Langchain 和 ChatGLM、Qwen、Llama 等本地大模型搭建的知识库问答应用,支持 RAG 检索增强与 Agent 能力,可离线部署私有文档问答系统。
知识库问答+4向量化 / 重排服务
387136.3kv0.3.12025-11-10 09:27 UTC
WeKnora
Tencent·Go
把原始文档变成可查询的 RAG、自主推理 Agent 和自维护 Wiki 的开源 LLM 知识平台,适合搭建企业知识库与智能问答。
知识库+4向量化 / 重排服务
37103+3585.1kv0.9.02026-11-09 15:19 UTC

TencentDB-Agent-Memory
TencentCloud·TypeScript
把对话、文档和代码沉淀成聊天记忆、技能、LLM-Wiki、代码图谱四类可复用记忆资产,让多个 AI Agent 跨框架共享和治理长期记忆。
长期记忆+4向量化 / 重排服务
30746+1283.0kv2.0.32026-11-10 13:27 UTC