LLaVA 与 Qwen 两条路线环境不同,CUDA 分别为 12.1 和 12.4,需分别建 conda 环境;训练前须自行下载 llava-v1.5 预训练权重和 depth_anything_v2_vitl.pth 并按脚本转换;推理需额外指定 dinov2 权重路径,训练脚本中的 checkpoint 与超参路径要先手动修改。
NAUTILUS
H-EmbodVis更新放缓面向水下场景理解的大型多模态模型,能同时处理水下图像与文本,完成描述、问答等视觉语言任务,填补水下环境多模态研究的空白。
[NeurIPS 2025] NAUTILUS: A Large Multimodal Model for Underwater Scene Understanding
NautData发布于 2025-12-18 08:58 UTC377star29fork同步于 2026-11-07 07:31 UTC
git clone https://github.com/Chengnotwang/NAUTILUS.git
cd NAUTILUS
conda create -n nautilus_llava python=3.10 -y
conda activate nautilus_llava
cd LLaVA
pip install -e .
pip install flash-attn==2.6.3 --no-build-isolation 硬件要求按 README 说明
README 未说明显存要求;推理示例用 CUDA_VISIBLE_DEVICES=0 指定单卡,训练基于 7B 模型,需 NVIDIA GPU 并安装 flash-attn。
需要 CUDA
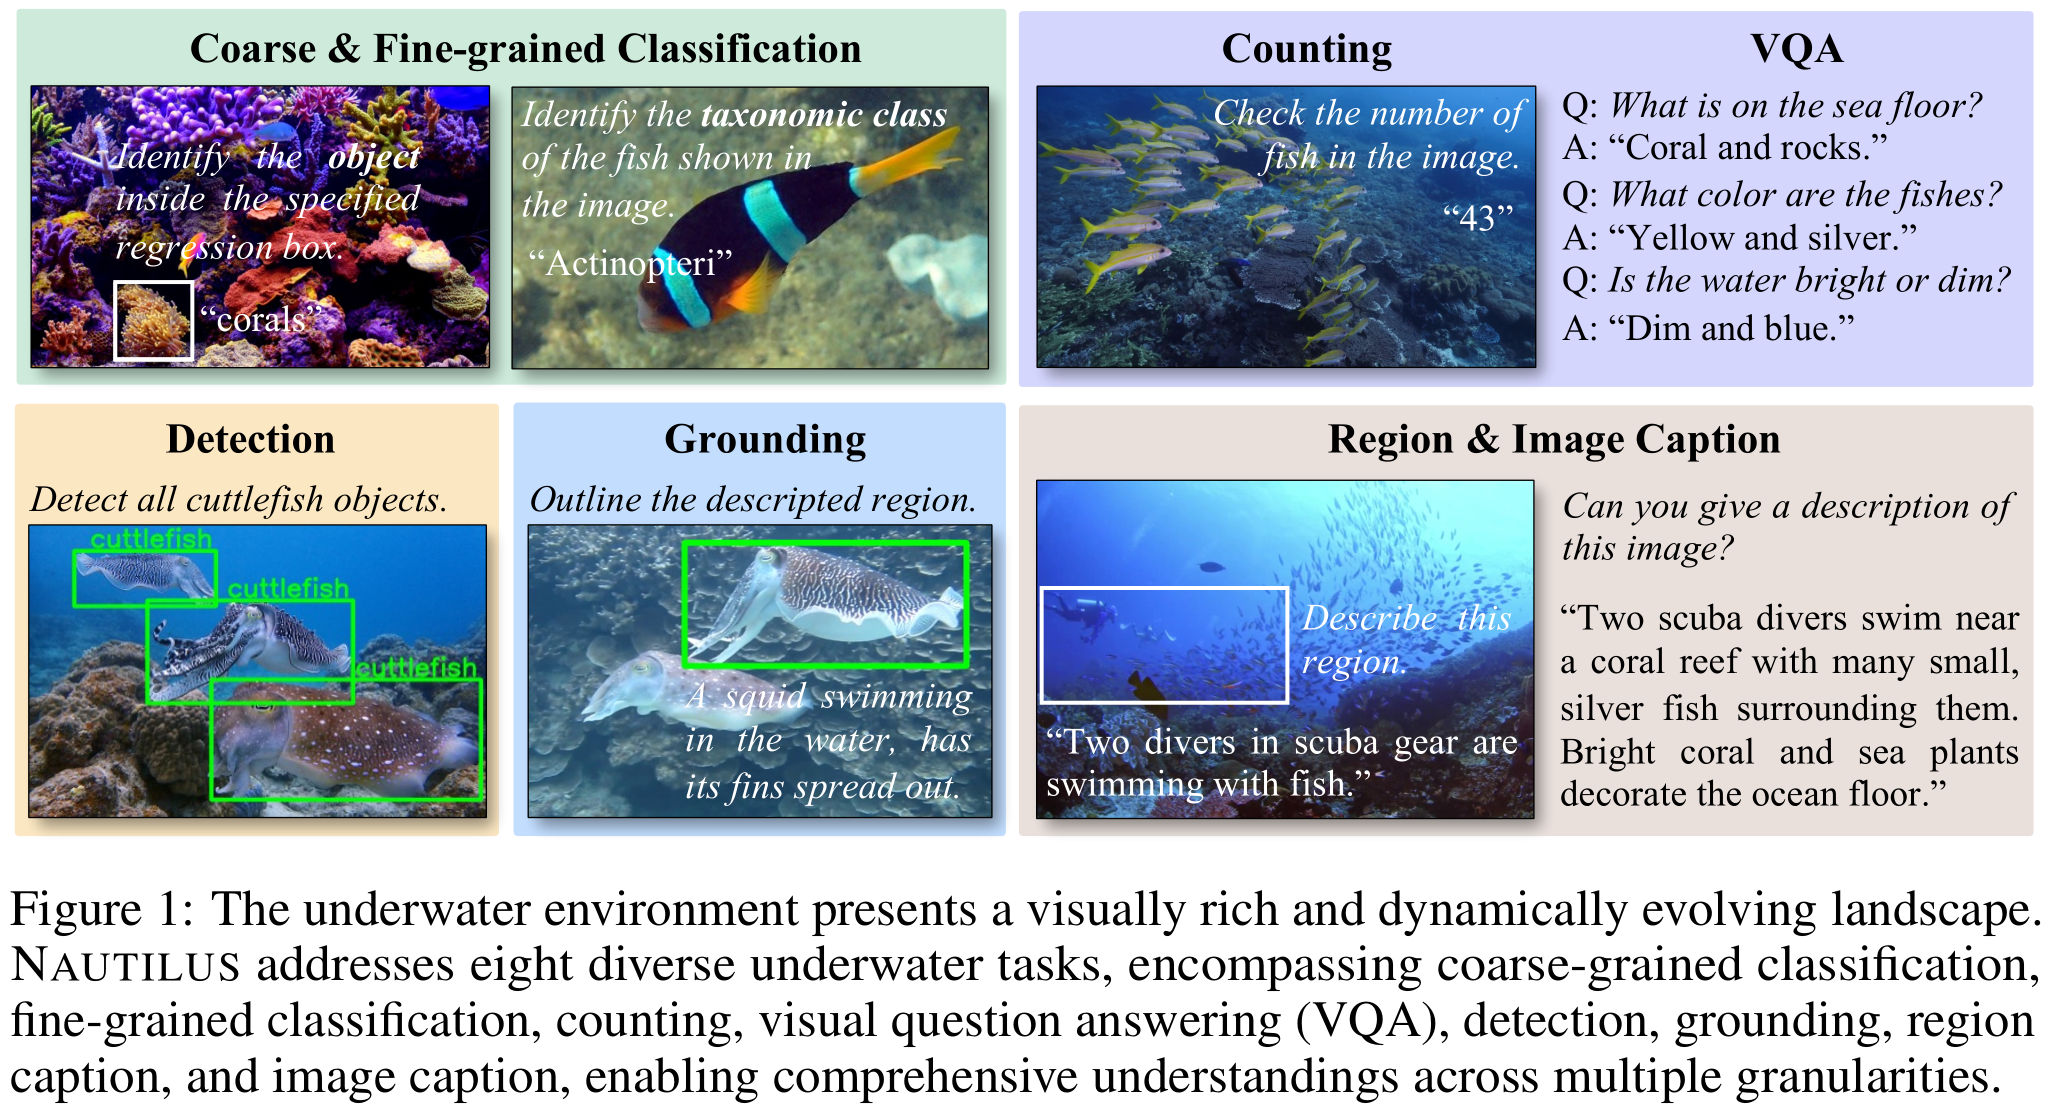
面向水下场景理解的大型多模态模型,支持分类、描述、定位、检测、VQA 等八项任务
面向水下场景理解的大型多模态模型,能同时处理水下图像与文本,完成描述、问答等视觉语言任务,填补水下环境多模态研究的空白。
核心能力
- 构建 145 万图文对的 NautData 水下指令数据集
- 首个覆盖图像、区域、物体三个层级的八任务水下 LMM
- 即插即用 VFE 模块按物理成像模型去后向散射并恢复光吸收
- 提供 LLaVA-1.5 与 Qwen2.5-VL 两套 7B 训练与推理代码
- 附带单样本推理脚本与评测脚本
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- NautDataFishNet dataset & Code最新正式版2025-12-18 · 2025-12-18 08:58 UTC
If you find the FishNet dataset is missing from your downloaded data, you can download split_fishnet* here.
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
Wei Xu1*, Cheng Wang1*, Dingkang Liang1, Zongchuang Zhao1, Xingyu Jiang1, Peng Zhang2, Xiang Bai1
1 Huazhong University of Science & Technology, 2 National University of Defense Technology
(*) Equal contribution.

News
[2025/10/30]Release the official version of NAUTILUS.[2025/09/18]NAUTILUS is accepted to NeurIPS 2025! 🥳🥳🥳
Contents
Introduction
Contributions
NAUTILUS contributes to three aspects:
- We construct NautData, a large-scale underwater instruction-following dataset containing 1.45 M image-text pairs, enabling developments and evaluations of underwater LMMs.
- We build the first eight-task underwater LMM NAUTILUS, achieving underwater scene understanding from image, region, and object levels. It empowers comprehensive underwater scene understanding through aggregating hierarchical scene information.
- We design a plug-and-play VFE module motivated by a physical underwater imaging model. It restores degraded information explicitly in the feature space. Experiments on renowned baselines demonstrate its effectiveness on all the annotated tasks.
Pipeline
NAUTILUS comprises an image encoder, a depth encoder, a vision-to-language projector, a Vision Feature Enhancement (VFE) module, and an LLM. The proposed VFE module performs feature-space enhancement guided by physical priors through two sequential steps: (1) removing backscattering and (2) restoring light absorption.
NAUTILUS Performance
Install
- Clone this repository and navigate to NAUTILUS folder
git clone https://github.com/Chengnotwang/NAUTILUS.git
cd NAUTILUS
-
Environment Setup for NAUTILUS (LLaVA)
Recommended Environment
- CUDA 12.1
- Python 3.10
# 1. Create a new conda environment
conda create -n nautilus_llava python=3.10 -y
conda activate nautilus_llava
# 2. Install requirements
cd LLaVA
pip install --upgrade pip  # enable PEP 660 support
pip install -e .
# 3. Install flash-attn
pip install flash-attn==2.6.3 --no-build-isolation
# If installation fails, install the pre-built wheel from [https://github.com/Dao-AILab/flash-attention/releases/tag/v2.6.3] instead:
pip install flash_attn-2.6.3+cu123torch2.1cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
-
Environment Setup for NAUTILUS (Qwen)
Recommended Environment
- CUDA 12.4
- Python 3.10
# 1. Create a new conda environment
conda create -n nautilus_qwen python=3.10 -y
conda activate nautilus_qwen
# 2. Install requirements
cd qwen-vl-finetune
pip install -r requirements.txt
# 3. Install flash-attn-2.7.3
pip install flash-attn==2.7.3 --no-build-isolation
# If installation fails, install the pre-built wheel from [https://github.com/Dao-AILab/flash-attention/releases/tag/v2.7.3] instead:
pip install flash_attn-2.7.3+cu12torch2.5cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
Dataset
For details on NautData and training / evaluation preparation, please refer to NautData.
Train
Dataset Preparation and Preprocessing
Ensure that the NautData is fully downloaded and the corresponding annotation files are correctly organized as described in the previous section. Once prepared, you can proceed with the training instructions below.
NAUTILUS (LLaVA)
-
Download llava-v1.5-mlp2x-336px-pretrain-vicuna-7b-v1.5 and depth_anything_v2_vitl.pth.
-
(Optional) Preprocess the
depth_anything_v2_vitl.pthweights intodino_vitl.pthby running the process_vitl_weight.py. Then, place the generated file in the directory specified in the finetuning script. -
Fine-tune NAUTILUS (LLaVA) with the provided script, in accordance with the instructions detailed below.
# Remove useless parameters and rename reamin parameters
python utils/process_vitl_weight.py --dav2-vitl "path to depth_anything_v2_vitl.pth" --dinov2-vitl "dinov2 only pth file"
conda activate nautilus_llava
cd LLavA
# Before training, please make sure to modify the path of the checkpoint and others hyper-parameters in the script
# Start training
bash scripts/nautilus_finetune/finetune_nautilus_lora.sh
NAUTILUS (Qwen)
-
We use the Qwen2.5-VL-7B-Instruct model in our experiments. You may also choose other Qwen2.5-VL variants if desired.
-
Verify that the annotation_path and data_path for Nautilus_Instruct are correctly configured in this file.
-
Run the NAUTILUS (Qwen) fine-tuning script.
conda activate nautilus_qwen
cd qwen-vl-finetune
# Make sure to modify the path and others hyper-parameters in the script
# Start training
bash scripts/nautilus_finetune/nautilus_sft_7b_lora.sh
Model Weights
Local Inference
NAUTILUS (LLaVA)
Single-Sample Inference for NAUTILUS (LLaVA)
cd LLaVA
CUDA_VISIBLE_DEVICES=0 python scripts/inference/inference.py --model-path "path to checkpoint" --dinov2-weight "path to dinov2" --image "path to image" --prompt "question"
# prompt default is "Describe the image"
NAUTILUS (Qwen)
Single-Sample Inference for NAUTILUS (Qwen)
cd qwen-vl-finetune
CUDA_VISIBLE_DEVICES=0 python scripts/inference.py --checkpoint "path to checkpoint" --image "path to image" --prompt "question"
# prompt default is "Describe the image"
Evaluation
We provide a simple evaluation script for evaluating the performance of NAUTILUS.
# for evaluation
bash eval/eval_nautilus_llava.sh # for Nautilus (LLaVA)
bash eval/eval_nautilus_qwen.sh # for Nautilus (Qwen)
Acknowledgement
Sincere acknowledgment to the amazing open-source community for their great contributions:
- LLaVA: for the excellent work and inspiring codebase.
- Qwen-2.5-VL: for the powerful open-source model and codebase (now updated to Qwen-3-VL).
- Depth AnythingV2: for the impressive work and for sharing their model weights with the community.
Citation
If you find this repository useful in your research, please consider giving a star ⭐ and a citation.
@inproceedings{xu2025nautilus,
        title={NAUTILUS: A Large Multimodal Model for Underwater Scene Understanding},
        author={Xu, Wei and Wang, Cheng and Liang, Dingkang and Zhao, Zongchuang and Jiang, Xingyu and Zhang, Peng and Bai, Xiang},
        booktitle={Advances in Neural Information Processing Systems},
        year={2025}
  }

MiniCPM-V
OpenBMB·Python
MiniCPM-V 是面壁智能开源的多模态视觉语言模型,能在手机、PC 等本地设备上完成看图、听音和对话交互,无需依赖云端。
多模态+4视觉语言模型
27119+342.1k202505272026-11-09 07:37 UTC

LLaVA
haotian-liu·Python
开源的多模态视觉指令微调模型,让 LLaMA 类大模型能看图对话,效果对标 GPT-4V,适合做图文问答和视觉助手。
视觉指令微调+4视觉语言模型
250752.8kv1.2.02024-08-12 09:52 UTC
screenpipe
screenpipe·Rust
持续录制电脑屏幕和音频,把日常工作流整理成可检索的记录,帮你找出值得自动化的环节,并为 AI 智能体提供上下文。
屏幕录制+4视觉语言模型
22323+642.3kapp-v2.7.1452026-11-10 00:40 UTC

Qwen3-VL
QwenLM·Jupyter Notebook
阿里云通义团队开源的多模态大模型系列,能同时理解图像和文本,用于视觉问答、图文推理等视觉语言任务。
多模态大模型+4视觉语言模型
20192+171.9k2026-01-30 04:47 UTC