Linux 上直接 pip install 会装数 GB 的 CUDA 版 PyTorch,纯 CPU 环境要先装 CPU 版 torch;部分模型族和导出后端需要额外 extras,如 rfdetr、onnx、tensorrt;预训练权重许可继承自原始来源,商用前需逐个查看 Hugging Face 模型卡。
libreyolo
LibreYOLOMIT活跃维护MIT 协议的开源计算机视觉库,支持目标检测、实例分割和姿态估计,兼容 ONNX 与 PyTorch,方便在边缘设备上训练和部署模型。
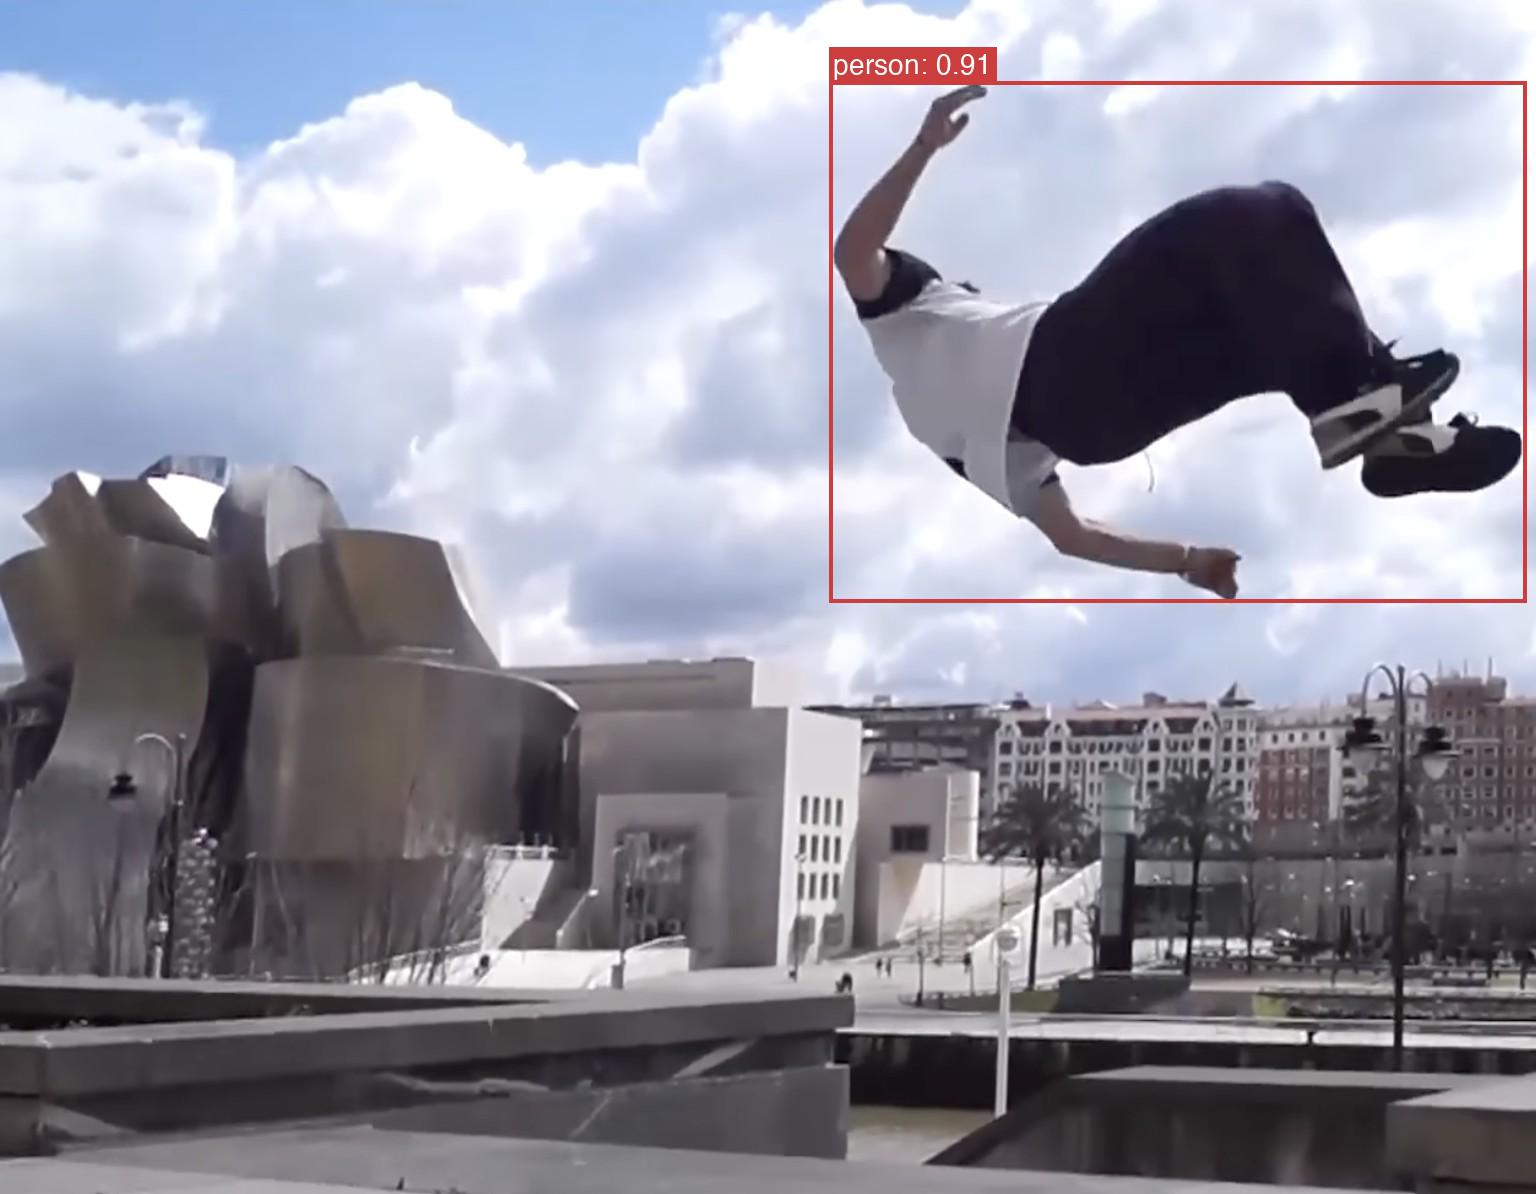
LibreYOLO is a MIT licensed open source computer vision library
v1.7.4发布于 2026-11-07 11:52 UTC1,005star +4 / 7 天69fork同步于 2026-11-10 17:53 UTC
pip install libreyolo
from libreyolo import LibreYOLO, SAMPLE_IMAGE
model = LibreYOLO("LibreYOLO9t.pt")
result = model(SAMPLE_IMAGE, save=True) 硬件要求按 README 说明
README 未说明具体显存要求;Linux x86_64 上默认安装会拉取 CUDA 版 PyTorch,无 NVIDIA GPU 需先装 CPU 版 torch。
纯 CPU 可运行支持 Apple Silicon需要 CUDA多卡 / 张量并行
MIT 许可的计算机视觉库,用一个 API 覆盖检测、分割、姿态、深度、OCR 等二十多种任务
MIT 协议的开源计算机视觉库,支持目标检测、实例分割和姿态估计,兼容 ONNX 与 PyTorch,方便在边缘设备上训练和部署模型。
核心能力
- 同一套三行 API 切换 checkpoint 即可跑不同任务
- 内置训练流程,支持多卡、LoRA、蒸馏和多种日志后端
- 支持导出 ONNX、TensorRT、OpenVINO、CoreML 等十二种格式
- 可直接读取摄像头、RTSP、视频、YouTube 和屏幕作为输入源
- 兼容常见 YOLO 格式数据集,已有流程改动很小
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v1.7.4最新正式版2026-11-07 · 2026-11-07 11:52 UTC
LibreYOLO v1.7.4, a patch release: extras no longer install an old LibreYOLO on Python 3.13 and 3.14, and install hints work in zsh (#1026).
Fixed
-
Extras no longer install an old LibreYOLO on Python 3.13 and 3.14. On Python 3.14,
pip install "libreyolo[all]"installed LibreYOLO 1.2.0,[tflite]1.2.0,[litert]1.3.1 and[executorch]1.7.0;[paddle]installed 1.4.0 on Python 3.13 and 3.14. A pinned dependency had no wheels for that Python, so pip went back through older releases until one resolved. Environment markers now skip those dependencies there, and the current release installs without that backend: the onnx2tf TFLite converter on 3.14 (it pins ai-edge-litert 2.1.2 and numpy 2.2.6; TFLite inference still installs), ExecuTorch 1.2 on 3.14, paddlepaddle 2.6.2 and X2Paddle on 3.13+,tensorrt-cu1210.16 on 3.14, and coremltools on 3.14. Using a skipped backend says which Python it needs. The dependency-resolution CI check now covers Python 3.14. -
Missing-extra messages quote the install command. Messages such as
pip install libreyolo[rfdetr]failed in zsh, the macOS default shell, which reads the brackets as a glob. All of them now readpip install "libreyolo[rfdetr]", including the hints inlibreyolo models. -
ONNX export without the
onnxextra points atpip install "libreyolo[onnx]". It suggesteduv sync --extra onnx, which only works in a repo clone, orpip install onnx, which leaves out onnxruntime and onnxsim.
Changed
- README: CPU-only install on Linux, a Hub example, and links that work on PyPI.
The README, also the PyPI page, shows how to install the CPU build of PyTorch on Linux to skip the CUDA wheels, shows
LibreYOLO("LibreYOLO/LibreYOLO9t"), and uses absolute links and image paths. Same in the Chinese README.
-
- v1.7.32026-11-07 · 2026-11-07 10:02 UTC
查看更新说明
LibreYOLO v1.7.3, a patch release that makes
LibreYOLO("owner/repo")load Hugging Face Hub models on a plainpip install libreyolo(#1020).Fixed
-
LibreYOLO("owner/repo")works on a plainpip install libreyolo.huggingface_hubis now a core dependency, so loading a model by its Hugging Face repo id no longer needs thehfextra. The extra still exists for pushing to the Hub and gated downloads. -
Loading
LibreYOLO/LibreYOLO9t,LibreYOLO/LibreYOLOXsand the other YOLO9 and YOLOX repos by repo id. These repos also hold a legacy lowercase checkpoint, so the loader stopped with "multiple checkpoints". When a repo holds several checkpoints, the one named after the repo is now chosen. -
A
libreyolo/folder in the working directory no longer hides Hub repo ids on macOS and Windows. The check for a localLibreYOLO/folder ignored case on those filesystems, so running from a folder containing a LibreYOLO clone madeLibreYOLO("LibreYOLO/<repo>")look for a local file.
Changed
- TFLite INT8 export quantizes once instead of twice.
onnx2tf -oiqtbuilds the integer model twice — float32 I/O, then int8 I/O — and only the second is shipped, although the I/O dtype does not change the calibrated scales.export(format="tflite", int8=True, ...)now builds the SavedModel with onnx2tf and runs a single in-processTFLiteConverterpass;int8_backend="onnx2tf"keeps the previous route, andint8_output_dtype="float32"writes float outputs for host-dequantizing runtimes (in-process backend only).
-
- v1.7.22026-11-03 · 2026-11-03 18:15 UTC
查看更新说明
LibreYOLO v1.7.2, a patch release that makes
pip install "libreyolo[all]"and the other extras install cleanly with pip and uv on Linux, Windows and macOS (#989).Changed
libreyolo[all]no longer includespaddle. (#989) X2Paddle needs ONNX 1.17 or earlier while the TFLite exporter inallneeds ONNX 1.20, so the two cannot share an environment. Installlibreyolo[paddle]on its own; Paddle export needs Python 3.10 or 3.11.
Fixed
-
pip install "libreyolo[all]"works on Python 3.12 and 3.13, Apple Silicon and Linux ARM. (#989) On Python 3.12 and newer thepaddleandtfliteextras inallpinned incompatible ONNX versions, so pip failed or fell back to an older LibreYOLO release. On macOS and Linux ARM,vlm,vlm-train,groundandallfailed ondecord, which ships wheels for Linux x86_64 and Windows only; it is now installed only there, the platforms where LocateAnything can run.tensorrt-cu12, which has no ARM wheels, is skipped on Linux ARM, where JetPack provides TensorRT. Loading LocateAnything where decord is not available now says so before downloading its weights, and Core AI export on Python 3.10 says it needs Python 3.11 instead of repeating the install command. Thanks @gboeer. -
Every extra installs without a compiler on Linux x86_64 and Windows, and on Apple Silicon with Python 3.12+. (#989) pip compiled three packages from source, which fails on a machine without the matching toolchain.
tensorrt(and soall) pulledpycuda, which needs the CUDA toolkit headers; it is gone. TensorRT export and inference never needed it, and INT8 calibration usescuda.bindings, which PyPI torch installs on Linux (elsewhere,pip install cuda-python).tflitepulledonnx-simplifier, a C++ build that duplicated theonnxsimmodule theonnxextra already provides; it is gone.coremlpulledcoremltoolson Windows and Linux ARM, where it has no wheels; it is now installed on macOS and Linux x86_64 only, and CoreML export elsewhere says so. Remaining source builds, all upstream: on Linux ARM,tflite(and soall) on Python 3.12+ compiles two packages onnx2tf pins exactly, andexecutorchcompiles coremltools;triton(and soall) compiles gevent on macOS with Python 3.10 or 3.11 (needs the Xcode command line tools) and on Linux ARM with Python 3.10. -
pip install "libreyolo[executorch]"gets a runtime that loads. (#989) ExecuTorch 1.2's compiled runtime is built against torch 2.11 but accepts any newer torch, so pip paired it with torch 2.15 and loading a.ptefailed withSymbol not foundinlibc10. The extra now pinstorch>=2.11,<2.12. -
MNN and ExecuTorch export work from a virtualenv that is not activated. (#989) Running the venv's python directly (an IDE run button, a Jupyter kernel,
venv/bin/python script.py) leftmnnconvertand ExecuTorch'sflatcoffPATH, so MNN export saidmnnconvertwas missing and ExecuTorch export could not startflatc. Both are now found in the environment's own scripts directory. -
A failing
import MNNon current Linux says why. (#989) MNN's Linux wheel asks for an executable stack, which glibc 2.41 and newer refuse (Ubuntu 25.04+, Fedora 42+), so MNN export and inference failed with "Install with: pip install libreyolo[mnn]" although MNN was installed. The error now names the cause and the workarounds:GLIBC_TUNABLES=glibc.rtld.execstack=2(glibc 2.42+) orpatchelf --clear-execstack. -
uv syncresolves from a source checkout. (#989) The dev group asked for pytest 9 while ExecuTorch 1.2 requires pytest below 9,coreai-torchwas requested on Python 3.10 although it needs 3.11, and extras that cannot share an environment (vlawithmolmo2ormarigold,executorchorpaddlewithtflite) were not declared as conflicts. A newDependency resolutionworkflow resolvesuv lockand every extra on Python 3.10 to 3.13 for Linux x86_64, Linux
- v1.7.12026-11-01 · 2026-11-01 23:22 UTC
查看更新说明
LibreYOLO v1.7.1, a patch release: unguarded training scripts run on macOS and Windows, and export fixes for TorchScript, OpenVINO, Paddle and ExecuTorch from the 1.7.0 test campaign.
Changed
-
RF-DETR PyTorch boxes are clipped to the image. (#980) Every exported backend (ONNX, TensorRT, OpenVINO, ExecuTorch, ...) clips RF-DETR boxes to the image, and upstream RF-DETR does since rf-detr#1168; PyTorch predict and val did not, so a box could extend past the picture. COCO val2017 mAP50-95 moves by +0.00003 to +0.00008 (n/s/m/l).
-
YOLO9-E2E TFLite export is validated. (#983) With onnx2tf 2.6.9 or newer and LiteRT 2.1.2, the trained LibreYOLO9E2Et checkpoint passes raw and public predict parity at a 128x128 canvas, so its tier moves from blocked to validated. Older onnx2tf versions, which change its predicted classes, are refused with an upgrade hint. YOLO9-P2 TFLite stays blocked.
-
The
executorchextra installs ExecuTorch 1.2. (#983)pip install libreyolo[executorch]could resolve ExecuTorch 1.0 with an older Torch; it now pins the validatedexecutorch>=1.2,<1.3.
Fixed
-
Unguarded
train()andval()scripts run on macOS and Windows. (#971) A call at the top level of a script, outsideif __name__ == "__main__":, now runs withworkers=0and logs one line on how to get parallel data loading back, instead of stopping with an error (#954). This applies under thespawnandforkserverstart methods; guarded scripts, notebooks, the CLI and Linuxforkkeep their workers. -
TorchScript exports of YOLO9, YOLO9-E2E and YOLO9-P2 run on any device. (#974) An export traced on CPU, the TorchScript default, failed on CUDA with "Expected all tensors to be on the same device": the head built its anchor grid inside the traced graph, which kept the trace device. The exporter now pins the grid as constants for the fixed export canvas, and
torch.jit.load(map_location=...)moves them with the weights. FP16 exports included. -
OpenVINO FP32 and INT8 exports keep full-precision weights. (#975)
openvino.save_modelcompresses weights to FP16 unless told otherwise, sohalf=Falseexports wrote FP16 weights. FP16 exports are unchanged. -
A failed Paddle export raises an error instead of ending the script. (#975) X2Paddle calls
exit(0)when its static-graph conversion fails, which ended the calling process as a success with no model written. On Python 3.12 and later, where paddlepaddle 2.6.2 cannot build that static graph, Paddle export now says so before converting. -
RF-DETR ExecuTorch programs load on Linux. (#979) The Linux ExecuTorch 1.2 runtime has no
aten::grid_sampler_2dkernel (the macOS one does), so RF-DETR detect, segment, pose and OBB.ptefiles failed to load with "Missing operator" (error 0x14). The exporter now decomposes grid sampling into primitives every runtime registers, as the Core AI exporter already does. -
A missing image directory says so. (#979) A data yaml whose
train/valfolder does not exist (a dataset that was never downloaded, a typo) raisedValueError: Unsupported path format; it now raisesFileNotFoundError: Image directory not found. -
LibreYOLO("LibreRFDETRn-sem.pt")loads by name. (#981) The only published DINOv2 semantic weight keeps its pre-split RF-DETR name; it loaded from a path, but auto-download stopped with "unable to determine size from filename". It now downloads and loads asLibreDINOv2semantic. -
Two instances of one LibreGen model can load at the same time. (#986) They share one weights directory, and the first loads could race on the download's completion marker: one instance read it half written, removed it and raised
FileNotFoundErroralthough the download had succeeded. Snapshot preparation is now serialized per directory and the marker is written atomically. -
The 3D generation knob error no longer lists
imgsz. (#970) Speridl
-
- v1.7.02026-10-31 · 2026-10-31 22:25 UTC
查看更新说明
LibreYOLO v1.7.0, image-to-3D and text-to-image generation with
LibreGen, the WeVisOne-VL VLM family, validation that explains more of its results, and YOLO9 training fixes.116 commits, 27 merged pull requests. Several changes alter training results, metrics or output paths you may compare against v1.6.0: read Changed and Breaking changes before upgrading. Full details in CHANGELOG.md and the upgrade guide.
Highlights
- Image to 3D with Speridlabs Idol (#964):
LibreGen("speridlabs-idol")("chair.jpg").save("chair.ply")turns one photo of an object into the whole object as 3D Gaussian splats (.plyor.splat). Ported from the SDK of Speridlabs, with Apache-2.0 code and weights; nothing gated, no login. Newgenerate3dtask. - Text to image (#933):
LibreGen("flux2-klein-4b")("a red fox"), with FLUX.2 klein 4B and SANA-Sprint 0.6B. Newgeneratetask, CLIlibreyolo generate, extralibreyolo[gen]. - WeVisOne-VL (#957): Tencent's 2B and 4B VLMs detect, point, segment, matte and read text through
LibreVLM. - Validation (#931): a confusion matrix on detect, segment and classify, per-class P/R/F1 curves on detect and segment, class-agnostic NMS in predict and val, and
top1/top5on classify results. - YOLO9 training fixes (#930, #939): fine-tunes no longer start with a randomly initialised PGI branch, gradients are clipped, labels are assigned in fp32, and label-assignment memory no longer grows with
max_labels. Existing checkpoints load and give bit-identical float outputs. - CLI (#930):
libreyolo train clip_max_norm=for the families whose recipe clips gradients.
Changed
- YOLO9-family training (#930): the gradient norm is clipped at 10, labels are assigned in fp32, and fine-tunes from the published weights no longer attach a randomly initialised PGI branch.
clip_max_norm=0turns clipping off. - YOLO9-m/c PGI branch (#930): the upstream CBLinear/CBFuse branch, so PGI training uses more memory; inference is unchanged.
perspective(#930) warps by corner displacement in every family with the shared affine warp, so the same value gives a different warp.- Mixup ratio (#930) is drawn from Beta(1, 1): default YOLOv7 training changes.
- CLI run folders (#946): EC, D-FINE, SegFormer, LingBot-Vision, V-JEPA 2 and YOLO9-P2 use their family run name.
name=exp(orname=yolo9_p2_exp) gives the old folder. - Confusion matrix plots (#931): counts in
confusion_matrix.png, the normalized plot inconfusion_matrix_normalized.png, detections counted at confidence 0.25. - Numbers that move: RTMDet-Ins keeps up to
max_detmasks, 300 by default, instead of at most 100 (#953); segmentation val treats box-only label rows as rectangle masks (#945);val(single_cls=True)scores a multiclass model's detections as one class (#938).
Breaking changes
- YOLO9-family checkpoints saved by 1.7.0 do not load in 1.6.x (#930). Older checkpoints load in 1.7.0.
- YOLO9 module, attribute and ONNX node names changed, with no aliases (#930): update code that reaches into
model.modeland Hailo end-node configs. libreyolo.validation.ConfusionMatrixis transposed (#931):matrix[predicted, true], defaultconf_thres=0.25.predict(agnostic_nms=True)raises where it is not supported (#931), and an unknown classifierinterpolationraises (#942).
Fixed
- A missing
libreyolo[rfdetr]extra is named instead of a misleading error (#965). - CLI training uses the SegFormer, LingBot-Vision and D-FINE recipes and loads RF-DETR segment checkpoints (#955).
- Unguarded
train()/val()scripts stop with one clear line instead of multiprocessing tracebacks (#954). libreyolo train device=0,1trains on several GPUs (#91
- Image to 3D with Speridlabs Idol (#964):
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
LibreYOLO
⭐ Support LibreYOLO. The best way to help is to star the repo. Feel free to open an issue if you encounter problems or have suggestions, and code contributions are very welcome (see CONTRIBUTING.md). If you want to contribute economically, that is very welcome: see the sponsorship program.


An MIT-licensed computer vision library. Detection, segmentation, pose, depth, OCR and a dozen more tasks behind one small API, with training and export included rather than sold separately. Reads common YOLO-format datasets, so existing workflows port over with minimal changes.
Install
pip install libreyolo
from libreyolo import LibreYOLO, SAMPLE_IMAGE

model = LibreYOLO("LibreYOLO9t.pt")
result = model(SAMPLE_IMAGE, save=True)
Models on the Hugging Face Hub load by repo id, on a plain install since 1.7.3:
LibreYOLO("LibreYOLO/LibreYOLO9t").
On Linux x86_64, pip install libreyolo pulls the CUDA build of PyTorch, several GB
of wheels. Without an NVIDIA GPU, install the CPU build of PyTorch first:
pip install torch torchvision --index-url https://download.pytorch.org/whl/cpu
pip install libreyolo
The base install covers YOLOv9 and the other core detectors, training, and
inference. Add an extra when you need a heavier family or an export backend.
Comma-separate to combine, for example pip install "libreyolo[rfdetr,hub-kernels]".
| Group | Extras |
|---|---|
| Export | onnx, tensorrt, openvino, coreml, coreai, tflite (alias litert), ncnn, mnn, paddle, executorch |
| Serving | triton |
| Models | rfdetr, vlm, sam, openvocab, clip, siglip2, eomt, midas, modus, sensenova, gaze, gen |
| Training | lora, plots, tensorboard, mlflow, wandb, comet, clearml, neptune, dvclive |
| Speed | fast-eval, hub-kernels |
| Sources | stream |
| Everything | pip install "libreyolo[all]" |
executorch, coreai and neptune are deliberately left out of all: they
pin torch or protobuf in ways that would drag the rest of the environment with
them. On Python versions an export backend publishes no wheels for (for
example tflite export and executorch on 3.14, paddle on 3.13+), the
extra skips that backend and still installs the current LibreYOLO. Full list
and per-backend notes in the
install guide.
git clone https://github.com/LibreYOLO/libreyolo.git
cd libreyolo
pip install -e .
A plain clone checks out release, the stable branch matching the published
package. For unreleased work, git checkout dev.
One API, twenty-two tasks
The same three lines run every task. Only the checkpoint changes.
from libreyolo import LibreYOLO

LibreYOLO("LibreYOLO9t.pt")("street.jpg", save=True)             # detection
LibreYOLO("LibreDeepLabv3mv3-sem.pt")("street.jpg", save=True)   # semantic segmentation
LibreYOLO("LibreHRNetw32-pose.pt")("street.jpg", save=True)      # pose
LibreYOLO("LibreMiDaSs-depth.pt")("street.jpg", save=True)       # depth
LibreYOLO("LibreFeyNobgl-matte.pt")("portrait.jpg", save=True)   # background removal
LibreYOLO("LibreRTDETRv2n-obb.pt")("aerial.jpg", save=True)      # oriented boxes
Sources are not just files. Point it at a webcam, an RTSP stream, a video, a directory, a YouTube URL or your screen:
libreyolo predict --model yolo9-t --source 0 --show          # webcam
libreyolo predict --model yolo9-t --source rtsp://camera/1   # network camera
libreyolo predict --model yolo9-t --source screen            # screen capture
What ships
| Task | Models |
|---|---|
| Detection | YOLOv9, RF-DETR, YOLOX, YOLO-NAS, D-FINE, DEIM, RT-DETR v1/v2/v4, RTMDet, PicoDet, PP-YOLOE, YOLOv7, EfficientDet, and the classics: DETR, Deformable DETR, DINO-DETR, LW-DETR, Faster R-CNN, RetinaNet, SSD, FCOS, CenterNet |
| Tiny objects | TinyFormer, Dome-DETR (aerial, drone, remote sensing) |
| Instance segmentation | RF-DETR, RTMDet, D-FINE, Mask R-CNN |
| Promptable segmentation | SAM, SAM 2, SAM 3, MobileSAM, EdgeTAM, PicoSAM3 |
| Semantic segmentation | SegFormer, PIDNet, PP-LiteSeg, U-Net, DeepLabv3, FCN, LingBot-Vision, DINOv2, EoMT |
| Panoptic segmentation | EoMT |
| Pose | RF-DETR, YOLO-NAS, HRNet, DEKR, EC |
| Oriented boxes | RF-DETR, RT-DETRv2, YOLO-NAS-R |
| 3D detection | WildDet3D, 3D-MOOD, FCOS3D, DetAny3D (separate runtime) |
| Classification | MobileNetV4, ConvNeXt, EfficientNetV2, ResNet, ViT, Swin, DeiT, VGG, AlexNet, CLIP, SigLIP2, DINOv2 |
| Depth | Depth Anything 3, Depth Anything V2, ZipDepth, MiDaS |
| Surface normals | MoGe-2 |
| Depth, normals and albedo | Marigold V2 |
| Edges | DexiNed, TEED |
| Embeddings | LibreFaceEmbedder, CLIP, SigLIP2, Perception Encoder (image, text, whole-video; also zero-shot classify), DINOv2 |
| Video embeddings | V-JEPA 2 (clip embedding and trainable classification probe), LeVJEPA (clip and patch embeddings; CC BY-NC 4.0 weights) |
| Body mesh | SAM 3D Body |
| Restoration | DDColor, HVI-CIDNet, LaMa, NAFNet, QuickSRNet, Real-ESRGAN, SwinIR |
| Background removal | BiRefNet, FeyNobg, BEN2, ViTMatte |
| OCR | PP-OCR |
| Point detection | FOMO, LocateAnything |
| Gaze | L2CS |
| Open vocabulary and VLMs | Grounding DINO, OWLv2, OmDet-Turbo, OV-DEIM, Florence-2, Kosmos-2, Qwen3-VL, InternVL3, LFM2-VL, North Micro Vision, SmolVLM2, Gemma 4, Moondream, Molmo2, WeVisOne-VL, MODUS |
| Robot actions (VLA) | SmolVLA, ACT, Diffusion Policy |
| Image generation | FLUX.2 klein, SANA-Sprint |
| 3D generation | Speridlabs Idol |
Per-family sizes, checkpoints and parity evidence live in the model reference.
Train
from libreyolo import LibreYOLO

model = LibreYOLO("LibreYOLO9t.pt")
model.train(data="dataset.yaml", epochs=100, imgsz=640)
libreyolo train --model yolo9-t --data dataset.yaml --epochs 100
Multi-GPU, LoRA, layer freezing, distillation, from-scratch training, and TensorBoard, MLflow, Weights & Biases, Comet, ClearML, Neptune and DVCLive logging are all supported. See the training guide.
Export and deploy
Twelve formats: ONNX, TorchScript, TensorRT, OpenVINO, CoreML, Core AI, TFLite (LiteRT), NCNN, MNN, RKNN, Paddle and ExecuTorch. Plus NVIDIA Triton serving and DeepStream config generation.
libreyolo export --model yolo9-t --format onnx
Support varies by family and task, see the export matrix.
Documentation
- Docs covers install, tasks, models, training, prediction, export and the CLI
- Benchmarks for independent numbers
- CHANGELOG.md for what changed
Sponsors
The code is written in free time. Training new models, such as LibreYOLO26 and MIT retrains of families with restrictive weights, costs rented GPU time, and the LibreYOLO Sponsorship Program pays for it. Companies get their logo here from $100 a month, and from $500 a month are named in every release and in the model card of every weight released while they sponsor. Hardware manufacturers can sponsor by sending a device.
No sponsors yet.
License
- Code: MIT License.
- Weights: pre-trained weights may inherit licensing from their original source, and not all of them are permissive. Check the license on the specific Hugging Face repo before you use one commercially. Every LibreYOLO Hugging Face model states its license.

ultralytics
ultralytics·Python
YOLO 系列官方实现库,一套 PyTorch 代码覆盖目标检测、实例与语义分割、图像分类、姿态估计和目标跟踪,训练到部署全流程打通。
目标检测+4检测 / 分割
63281+9812kv8.4.2082026-11-10 15:51 UTC

yolov5
ultralytics·Python
基于 PyTorch 的目标检测全家桶,覆盖训练、推理、实例分割、图像分类和模型导出,开箱即用,适合快速落地视觉任务。
目标检测+4检测 / 分割
58260+717kv7.02026-11-07 16:59 UTC
pytorch-image-models
huggingface·Python
收录最全的 PyTorch 图像骨干网络合集,涵盖 ResNet、ViT、ConvNeXt 等主流模型,自带训练、评估、推理和导出脚本及预训练权重,省去自己搭网络和找权重的麻烦。
图像分类+4检测 / 分割
37273+85.2kv1.0.312026-11-07 23:22 UTC

detectron2
facebookresearch·Python
Detectron2 是 Facebook 开源的目标检测与分割平台,提供模块化架构和丰富预训练模型,方便快速搭建和训练视觉识别任务。
目标检测+4检测 / 分割
34981+67.9kv0.62026-10-27 09:21 UTC