推荐使用 Python 3.11,README 称其比 3.12 更稳定;中国大陆用户建议改用阿里云镜像 registry.cn-hangzhou.aliyuncs.com/yongyang/llmcompression:pure-latest;导出量化模型后需搭配 VLLM、SGLang 等独立后端才能加速推理。
LightCompress
ModelTCApache-2.0更新放缓一站式大模型压缩工具箱,支持 LLM、VLM 和视频生成模型的量化与剪枝,覆盖 AWQ、SmoothQuant 等算法,并提供压缩后的评测与部署流程。
[EMNLP 2024 & AAAI 2026] A powerful toolkit for compressing large models including LLMs, VLMs, and video generative models.
v1.5.0发布于 2025-11-19 03:07 UTC754star83fork同步于 2026-11-07 07:30 UTC
docker pull llmcompression/llmc:pure-latest 硬件要求按 README 说明
README 提到 AWQ 和 RTN 量化 671B 的 DeepSeek 模型可在单张 80GB GPU 上运行,Llama3.1-405B 与 DeepSeek-R1-671B 的 PPL 评估可在单张 A100/H100/H800 上完成;未说明 CPU 运行与具体显存下限。
支持 Apple Silicon有 Docker 镜像
一站式压缩 LLM、VLM 和视频生成模型的工具包,支持量化与稀疏化并导出到主流推理后端
一站式大模型压缩工具箱,支持 LLM、VLM 和视频生成模型的量化与剪枝,覆盖 AWQ、SmoothQuant 等算法,并提供压缩后的评测与部署流程。
核心能力
- 支持量化、混合精度量化和结构化/非结构化稀疏
- 覆盖 AWQ、GPTQ、SmoothQuant、QuaRot 等 SOTA 算法
- 支持 VLM 的 token 削减与量化共 20 种算法
- 可导出真实 INT4/INT8/FP8 权重到 VLLM、SGLang 等后端
- 单张 A100/H100/H800 可量化 Llama3.1-405B 与 DeepSeek-R1-671B
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v1.5.0LightCompress v1.5.0最新正式版2025-11-19 · 2025-11-19 03:07 UTC
Support token reduction for VLM models.
- v1.4.0LLMC v1.4.02025-02-17 · 2025-02-17 05:40 UTC
查看更新说明
Support more models/algos.
- v1.3.0LLMC v1.3.02024-10-11 · 2024-10-11 11:43 UTC
这个版本没有写更新说明。
- v1.2.0LLMC v1.2.02024-08-16 · 2024-08-16 04:19 UTC
这个版本没有写更新说明。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。


[ English | 中文 ]
📢 Notice: This repository was formerly known as LLMC and has been renamed to LightCompress.
LightCompress is an off-the-shell tool designed for compressing aigc models(LLM, VLM, Diffusion ...), leveraging state-of-the-art compression algorithms to enhance efficiency and reduce model size without compromising performance. You can download the Docker image that can run LightCompress with the following command. Users in mainland China are recommended to use Alibaba Cloud Docker.
# docker hub: https://hub.docker.com/r/llmcompression/llmc
docker pull llmcompression/llmc:pure-latest

# aliyun docker: registry.cn-hangzhou.aliyuncs.com/yongyang/llmcompression:[tag]
docker pull registry.cn-hangzhou.aliyuncs.com/yongyang/llmcompression:pure-latest
Community: Discord Server, Tencent QQ Group.
Recommended Python Version: We recommend using Python 3.11 for local development and installation. This matches the project's Docker images and CI configuration, and is generally more stable than Python 3.12 for the current dependency set.
:fire: Latest News
-
Nov 9, 2025: 🍺🍺🍺 Our work LLMC+: Benchmarking Vision-Language Model Compression with a Plug-and-play Toolkit has been accepted by AAAI 2026.
-
August 13, 2025: 🚀 We have open-sourced our compression solution for vision-language models (VLMs), supporting over a total of 20 algorithms that cover both token reduction and quantization. This release enables flexible, plug-and-play compression strategies for a wide range of multimodal tasks. please refer to the documentation.
-
May 12, 2025: 🔥 We now fully support quantization for the
Wan2.1series of video generation models and provide export of truly quantized INT8/FP8 weights, compatible with the lightx2v inference framework. For details, please refer to the lightx2v documentation. -
Feb 07, 2025: 🔥 We now fully support quantization of large-scale
MOEmodels likeDeepSeekv3,DeepSeek-R1, andDeepSeek-R1-zerowith671Bparameters. You can now directly load FP8 weights without any extra conversion. AWQ and RTN quantization can run on a single 80GB GPU, and we also support the export of true quantized INT4/INT8 weights. -
Nov 20, 2024: 🔥 We now fully support the quantization of ✨
DeepSeekv2(2.5)and otherMOEmodels, as well as ✨Qwen2VL,Llama3.2, and otherVLMmodels. Supported quantization methods include ✅integer quantization, ✅floating-point quantization, and advanced algorithms like ✅AWQ, ✅GPTQ, ✅SmoothQuant, and ✅Quarot. -
Nov 12, 2024: 🔥 We have added support for 💥
static per-tensor activation quantizationacross various models and algorithms, covering ✅integer quantization and ✅floating-point quantization to further optimize performance and efficiency. Additionally, we now support exporting ✨real quantized modelsand using the VLLM and SGLang backends for inference acceleration. For more details, refer to the VLLM documentation and SGLang documentation. -
Sep 26, 2024: 🔥 We now support exporting 💥
FP8 quantized(E4M3, E5M2)models from 🚀LLMCto advanced inference backends such as VLLM and SGLang. For detailed usage, please refer to the VLLM documentation and SGLang documentation.
-
Sep 24, 2024: 🔥 We have officially released ✅INT4 and ✅INT8 models of ✨
Llama-3.1-405B, quantized using 🚀LLMCinsave_lightllmmode. You can download the model parameters here. -
Sep 23, 2024: 🔥 We now support exporting ✨
real quantized(INT4, INT8)models from 🚀LLMCto advanced inference backends such as VLLM, SGLang, AutoAWQ, and MLC-LLM for quantized inference deployment, enabling ✨reduced memory usageand ✨faster inference speeds. For detailed usage, please refer to the VLLM documentation, SGLang documentation, AutoAWQ documentation, and MLC-LLM documentation. -
Sep 09, 2024: 🔥 We provide some configs of our best practice towards superior performance (see Best Practice here).
-
Sep 03, 2024: 🔥 We support opencompass 🤗 to eval 🚀
LLMCmodel. Follow this doc and have a try! -
Aug 22, 2024: 🔥We support lots of small language models, including current SOTA SmolLM(see Supported Model List).
-
Aug 22, 2024: 🔥 Additionally, we also support down stream task evaluation through our modified lm-evaluation-harness 🤗. Specifically, people can first employ
save_transmode(seesavepart in Configuration) to save a weight modified model. After obtaining the transformed model, they can directly evaluate the quantized model referring to run_lm_eval.sh. More details can be found in here. -
Jul 23, 2024: 🍺🍺🍺 We release a brand new version benchmark paper:
LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit.
Ruihao Gong*, Yang Yong*, Shiqiao Gu*, Yushi Huang*, Chengtao Lv, Yunchen Zhang, Xianglong Liu📧, Dacheng Tao
(* denotes equal contribution, 📧 denotes corresponding author.)
-
Jul 16, 2024: 🔥We support Wanda/Naive(Magnitude) for llm sparsification and layer-wise mix bits quantization now!
-
Jul 14, 2024: 🔥We support rotation based quantization QuaRot now!
-
May 17, 2024: 🚀 We support some advanced large models, e.g., LLaVA, Mixtral, LLaMA V3 and Qwen V2 now. Have a try!
-
May 13, 2024: 🍺🍺🍺 We release our quantization benchmark paper:
Ruihao Gong*, Yang Yong*, Shiqiao Gu*, Yushi Huang*, Yunchen Zhang, Xianglong Liu📧, Dacheng Tao
(* denotes equal contribution, 📧 denotes corresponding author.)
We modularly and fairly benchmark the quantization techniques considering calibration cost, inference efficiency, and quantized accuracy. Near 600 experiments on diverse models and datasets provide three insightful takeaways on the calibration data, algorithm pipeline, and quantization configuration selection. Based on the takeaways, a best practice for the LLM PTQ pipeline is designed, to achieve the best accuracy and efficiency performance balance under various scenarios.
-
Mar 07, 2024: 🚀 We release the quantization part of a powerful and efficient LLM compression tool. Notably, our benchmark paper is coming soon😊.
🚀 Highlight Feature
-
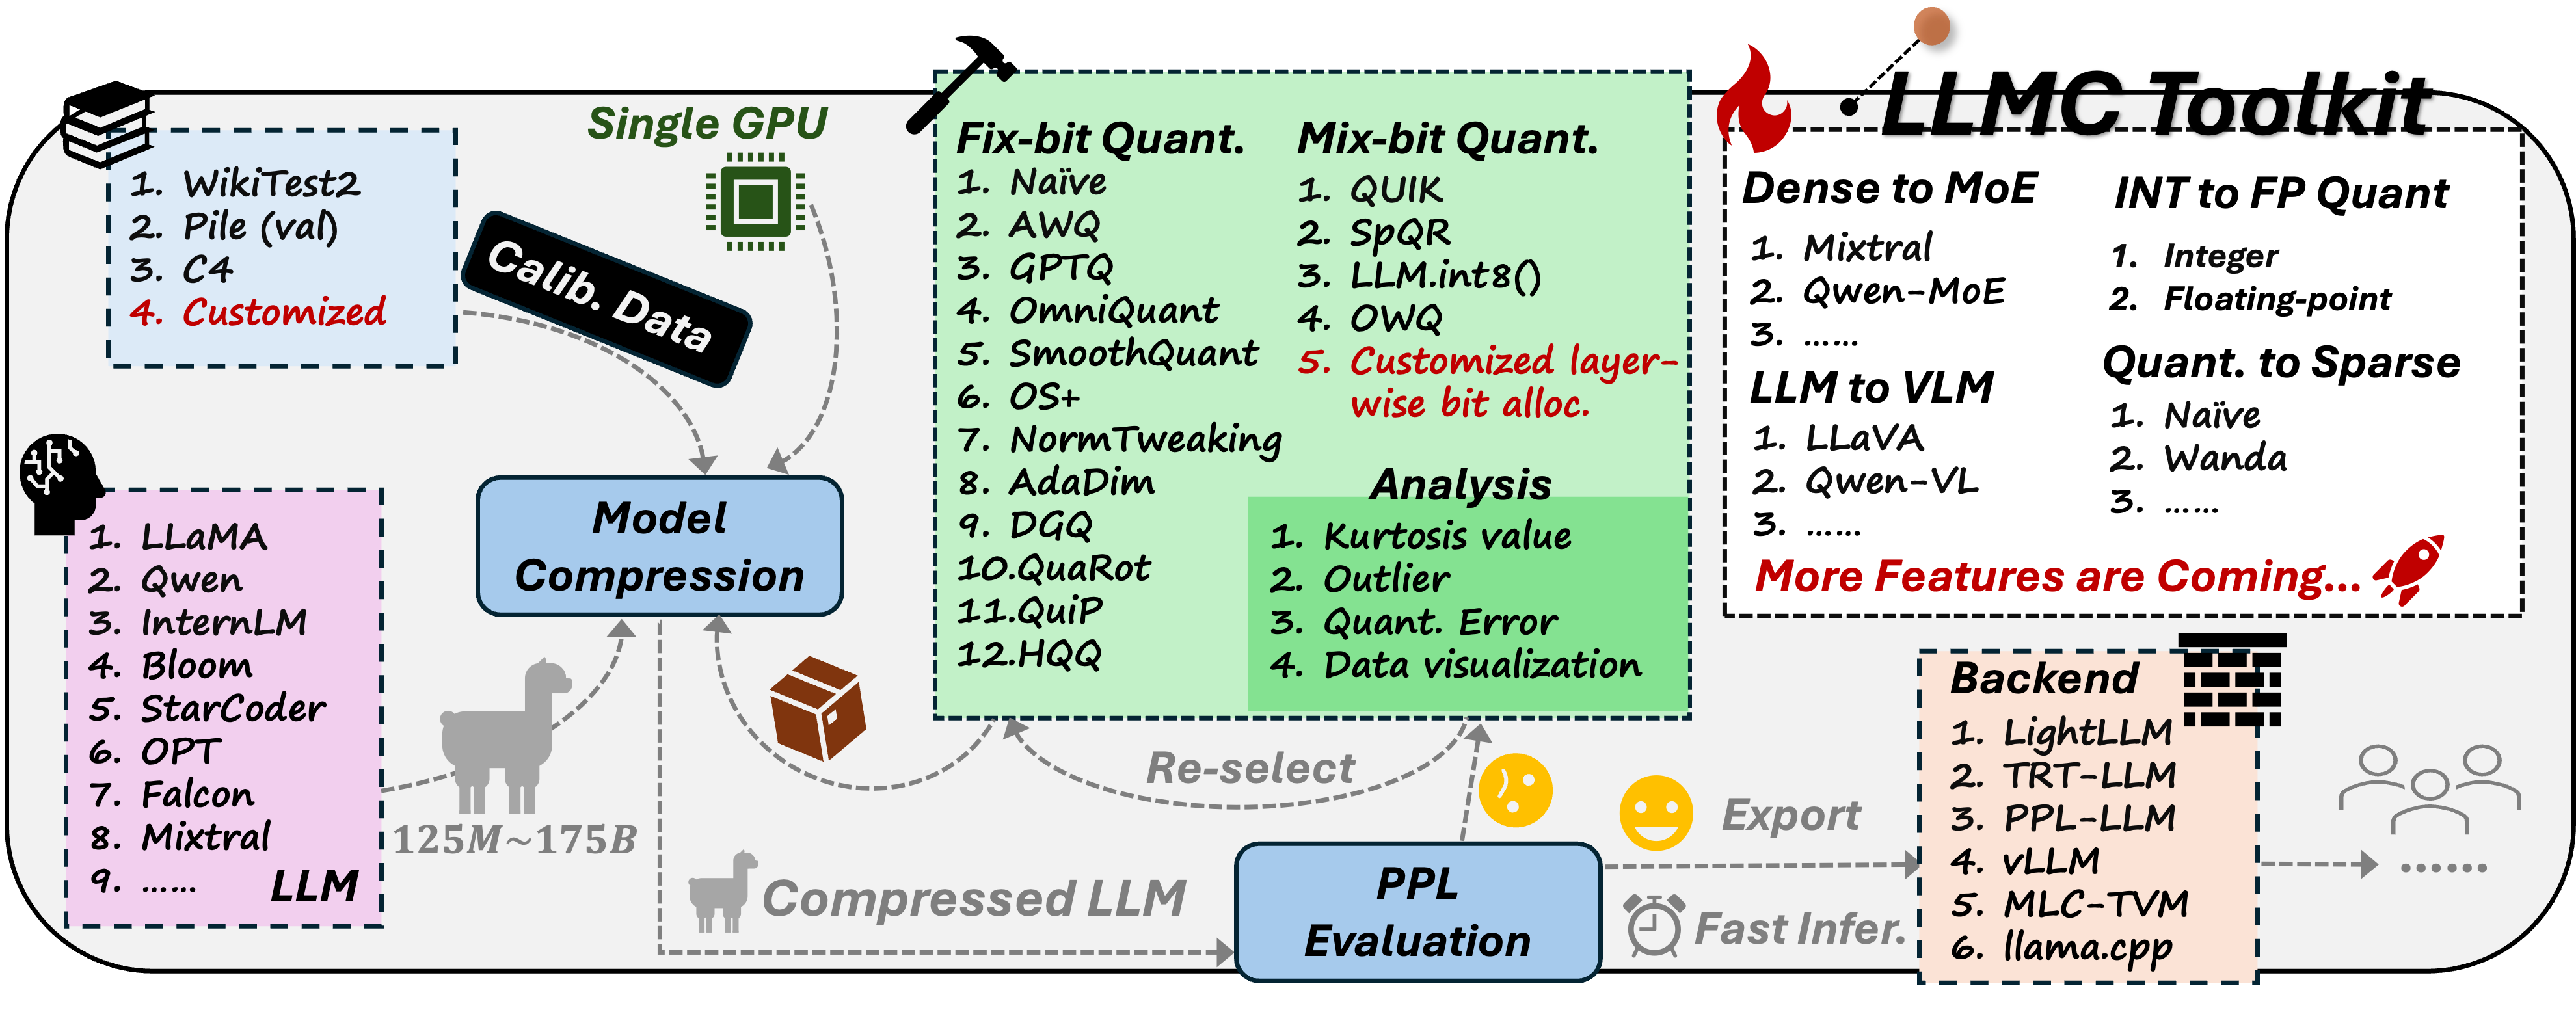
💥Comprehensive Algorithm Support: Provides a broad range of ✨
SOTA compression algorithms, including ✅quantization, ✅mixed-precision quantization, and ✅sparsity, while maintaining accuracy consistent with the original repositories. ✨Quantization best practices(see 🚀Best Practiceshere) are also available to ensure optimal performance and efficiency. -
💥Supported Formats: Supports both ✨
quantization(integer and floating-point) and ✨sparsity, specifically including ✅weight-activation, ✅weight-only, ✅mixed-precision quantization, as well as ✅structured and ✅unstructured sparsity. -
💥Wide Model Support: Offers support for a diverse array of ✨
LLM models, including ✅LLama, ✅Mistral, ✅InternLM2, ✅Qwen2, among others, as well as ✅MOE(DeepSeekv2, Deepseek-R1) and ✅VLM(Llama3.2-vision, Qwen2-vl) models (see Supported Model List). -
💥Multi-backend Compatibility: Seamlessly integrates with various backends for enhanced deployment flexibility. Multiple quantization settings and model formats are compatible with a wide range of backends and hardware platforms, such as ✅VLLM, ✅Sglang, ✅LightLLM, ✅MLC-LLM, and ✅AutoAWQ, making it highly versatile(see Section
Backendhere). -
💥Performance Efficiency: Enables quantization of large LLMs, such as ✨
Llama3.1-405Band ✨DeepSeek-R1-671B, with PPL evaluation on asingle A100/H100/H800 GPU.
⚙️ Usage
Please refer to the 🚀Quick Start section in the documentation.
:robot: Supported Model List
- ✅ Falcon
- ✅ InternLM2
- ✅ Mistral
- ✅ LLaMA V3
- ✅ Mixtral
- ✅ Qwen V2
- ✅ LLaVA
- ✅ InternLM2.5
- ✅ StableLM
- ✅ Gemma2
- ✅ Phi2
- ✅ Phi 1.5
- ✅ MiniCPM
- ✅ SmolLM
- ✅ DeepSeekv2.5
- ✅ LLaMA V3.2 Vision
- ✅ Qwen MOE
- ✅ Qwen2-VL
- ✅ InternVL2
You can add your own model type referring to files under llmc/models/*.py.
:bus: Supported Backend List
💡 Supported Algorithm List
Token Reduction
Quantization
- ✅ Naive
- ✅ AWQ
- ✅ GPTQ
- ✅ SmoothQuant
- ✅ OS+
- ✅ OmniQuant
- ✅ NormTweaking
- ✅ AdaDim
- ✅ QUIK
- ✅ SpQR
- ✅ DGQ
- ✅ OWQ
- ✅ LLM.int8()
- ✅ HQQ
- ✅ QuaRot
- ✅ SpinQuant (See this branch)
- ✅ TesseraQ
Pruning
🤝 Acknowledgments
We develop our code referring to the following repos:
- mit-han-lab/llm-awq
- mit-han-lab/smoothquant
- OpenGVLab/OmniQuant
- IST-DASLab/gptq
- ModelTC/Outlier_Suppression_Plus
- IST-DASLab/QUIK
- Vahe1994/SpQR
- ilur98/DGQ
- xvyaward/owq
- TimDettmers/bitsandbytes
- mobiusml/hqq
- spcl/QuaRot
- locuslab/wanda
- EleutherAI/lm-evaluation-harness
- facebookresearch/SpinQuant
- Intelligent-Computing-Lab-Yale/TesseraQ
🌟 Star History
✏️ Citation
If you find our toolkit or research paper useful or relevant to your research, please kindly cite our work:
@inproceedings{lv2026llmc+,
  title={Llmc+: Benchmarking vision-language model compression with a plug-and-play toolkit},
  author={Lv, Chengtao and Zhang, Bilang and Yong, Yang and Gong, Ruihao and Huang, Yushi and Gu, Shiqiao and Wu, Jiajun and Shi, Yumeng and Guo, Jinyang and Wang, Wenya},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={29},
  pages={24189--24197},
  year={2026}
}
@inproceedings{DBLP:conf/emnlp/GongYGHLZT024,
  author={Ruihao Gong and Yang Yong and Shiqiao Gu and Yushi Huang and Chengtao Lv and Yunchen Zhang and Dacheng Tao and Xianglong Liu},
  title={LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit},
  year={2024},
  cdate={1704067200000},
  pages={132-152},
  url={https://aclanthology.org/2024.emnlp-industry.12},
  booktitle={EMNLP (Industry Track)},
  crossref={conf/emnlp/2024i}
}