Python 需 64 位 3.10–3.14 版本;同一集合写入仅允许单进程,多进程只能并发读;中文分词虽已内置 Jieba 词典,但其他语言 SDK 需按各自仓库的安装指南单独配置。
pip install zvec 硬件要求按 README 说明
README 未说明显存或 GPU 要求;作为进程内库可运行在笔记本、服务器、CLI 工具乃至边缘设备,支持 Linux、macOS、Windows、Android、iOS。
阿里开源的进程内向量数据库,嵌入应用即可做低延迟相似度检索,无需部署服务
轻量级进程内向量数据库,主打极速检索,适合在本地为 RAG、语义搜索和 LLM 记忆等场景提供向量与全文检索能力。
核心能力
- 进程内库形态,无需服务器和配置即可开始检索
- 同时支持稠密与稀疏向量、多向量查询及多种索引
- 原生全文检索与向量、结构化过滤融合的混合查询
- WAL 预写日志保证进程崩溃或断电后数据不丢
- 多进程可并发读同一集合,写入为单进程独占
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.8.1最新正式版2026-11-06 · 2026-11-06 10:06 UTC
🚀 Zvec v0.8.1 Release Notes
📦 New Features
- PQ for HNSW and IVF: Added PQ4/PQ8 and optional OPQ, covering training, search, persistence, and subsequent updates. (#833)
- Broader platform support: Enabled RaBitQ on Linux, macOS, Android, and iOS ARM64, plus Intel Mac. DiskANN now supports Intel Mac and Windows ARM64. (#832, #874)
- Grouped search in the C API: Added grouped vector query and result-management APIs. (#845)
🚀 Performance Improvements
- Lower build memory: Reduced vector copying and temporary storage in DiskANN, IVF, and selected HNSW construction paths. (#853, #877, #879, #880)
- Faster search and construction: Improved Flat batch queries, HNSW construction, and FP16 distance calculation, and completed ARM NEON batch-distance kernels. (#862, #871, #856)
🐞 Key Fixes
- Strengthened read-only storage guarantees, fixing index modifications on read-only close, WAL recovery boundaries, and writable reopen behavior. (#834, #840, #870)
- Fixed HNSW RaBitQ scoring, missing external-vector handling, crashes after failed schema changes, and collection locks retained through inherited file descriptors. (#851, #861, #822, #859)
Upgrade note: Collections with pending WAL recovery must first be opened and closed in writable mode before being opened read-only. (#840)
Thanks to all contributors, and welcome to first-time contributors @ZoruaSama and @ilike314272!
Full Changelog:v0.8.0...v0.8.1
- v0.8.02026-10-21 · 2026-10-21 04:36 UTC
查看更新说明
🚀 Zvec v0.8.0 Release Notes
Zvec v0.8.0 brings faster queries, lower index build costs, and broader platform support. Quantizer and distance-kernel improvements benefit multiple formats and metrics, with major gains for INT4 and Linux ARM64. This release also reduces peak memory during IVF/DiskANN builds, accelerates HNSW RaBitQ construction, and makes Chinese FTS ready to use with embedded Jieba resources. Platform coverage expands across desktop and mobile, alongside fixes for concurrent reads, index rebuilding, and filtering correctness.
⚠️ Breaking Changes and Upgrade Notes
- Jieba global dictionary configuration removed: Default dictionaries and the HMM model are now embedded in native libraries. Python users must remove
init(jieba_dict_dir=...)and calls toset_default_jieba_dict_dir()/get_default_jieba_dict_dir(). The corresponding C configuration accessors, C default-directory APIs, and C++ global configuration field and registration APIs have also been removed. To override the main dictionary, use the field'sFtsIndexParam.extra_params.jieba_dict_dirorZVEC_JIEBA_DICT_DIR; field configuration takes precedence. Useuser_dict_pathto add business vocabulary. (#807)
📦 New Features
- Intel Mac and Windows ARM64 support: Added macOS x86_64 builds and Windows ARM64 support with MSVC. Release workflows now include Windows ARM64 SDK packages and native Python 3.11–3.14 wheels. (#713, #352, #824)
- DiskANN on Windows and mobile: Added asynchronous, unbuffered Windows reads through I/O completion ports and portable
preadsupport for Android and iOS. (#625, #656) - RaBitQ on Windows x86_64: Added Windows x86_64 support for RaBitQ indexes. (#780)
- Embedded Chinese FTS dictionary: Embedded the default Jieba dictionary and HMM model as LZ4-compressed resources for Python wheels and native SDKs. Parsed defaults are shared, while custom user dictionaries remain isolated between tokenizer instances. (#807)
- More flexible identifiers: Document IDs now accept valid UTF-8 up to 1,024 bytes, and collection names accept valid UTF-8 from 1 to 256 bytes, excluding prohibited control and separator characters. Field names retain their ASCII character set, expand to 64 bytes, and reject reserved internal names. (#756)
- Uniform quantization in collections: Added uniform UINT4 quantization and integrated uniform UINT4/UINT7/UINT8 quantizers with the database layer and HNSW. A shared quantization range avoids per-datapoint score reconstruction during queries, accelerating search. Using a shared min/max across all indexed points can increase quantization error and reduce recall. (#698, #754)
- Turbo PQ and FastScan: Added PQ-INT4 and a 4-bit PQ FastScan implementation with packed block scanning, together with SIMD and scalar distance kernels and precomputed residual distance tables for IVF. (#664)
- OPQ preprocessing: Added Optimized Product Quantization rotation to the Turbo framework and consolidated common training and serialization logic across PQ quantizers. (#717, #765)
- Shared page cache for vector indexes: Added buffer-backed storage and integrated HNSW, IVF, and DiskANN with a shared page cache. The implementation supports pinned reads, batched page access, and DiskANN direct-I/O fallback under cache pressure. ([#708](https://github.com/alibaba/
- Jieba global dictionary configuration removed: Default dictionaries and the HMM model are now embedded in native libraries. Python users must remove
- v0.8.0-beta2pre-release2026-10-20 · 2026-10-20 10:45 UTC
查看更新说明
What's Changed
- refactor: migrate index storage reads to MemoryBlock by @iaojnh in https://github.com/alibaba/zvec/pull/812
- perf(flat): isolate query metadata from segment cache locking by @egolearner in https://github.com/alibaba/zvec/pull/825
- ci: strip debug symbols from Android prebuilt SDK libraries by @chinaux in https://github.com/alibaba/zvec/pull/702
- fix(sqlengine): keep the exact FLOAT and DOUBLE bound in a forward filter by @jak-pan in https://github.com/alibaba/zvec/pull/818
New Contributors
- @jak-pan made their first contribution in https://github.com/alibaba/zvec/pull/818
Full Changelog: https://github.com/alibaba/zvec/compare/v0.8.0-beta...v0.8.0-beta2
- v0.8.0-betapre-release2026-10-19 · 2026-10-19 11:02 UTC
查看更新说明
What's Changed
- build(rabitq): upgrade to RaBitQ 0.7 modular targets by @gouyt13 in https://github.com/alibaba/zvec/pull/814
- perf(flat): batch segment locking to fix HNSW RaBitQ build regression by @JalinWang in https://github.com/alibaba/zvec/pull/813
- perf(search): output refined internal IDs directly by @luoxiaojian in https://github.com/alibaba/zvec/pull/821
- fix(ivf): support primary-key brute-force search for filtered queries by @iaojnh in https://github.com/alibaba/zvec/pull/816
- feat(fts): embed default Jieba resources with LZ4 by @egolearner in https://github.com/alibaba/zvec/pull/807
- ci: publish Windows ARM64 wheels and SDK by @JalinWang in https://github.com/alibaba/zvec/pull/824
New Contributors
- @gouyt13 made their first contribution in https://github.com/alibaba/zvec/pull/814
Full Changelog: https://github.com/alibaba/zvec/compare/v0.8.0-alpha...v0.8.0-beta
- v0.8.0-alphapre-release2026-10-16 · 2026-10-16 12:45 UTC
查看更新说明
What's Changed
- feat(tools): support turbo quantizer in core tool set by @richyreachy in https://github.com/alibaba/zvec/pull/684
- perf: batch convert docs to achieve acceleration by @zzlin237 in https://github.com/alibaba/zvec/pull/647
- feat: add Windows ARM64 (MSVC) build support by @Aanerud in https://github.com/alibaba/zvec/pull/352
- chore: update README to v0.7.0 by @chinaux in https://github.com/alibaba/zvec/pull/697
- feat(refine): support configurable flat storage types by @luoxiaojian in https://github.com/alibaba/zvec/pull/677
- perf: improve CRC32C and FP16 runtime dispatch by @richyreachy in https://github.com/alibaba/zvec/pull/700
- fix(build): fix /Z7 /Zi conflict in Debug on Windows by @JalinWang in https://github.com/alibaba/zvec/pull/692
- refactor(turbo): add AVX2/AVX512 SIMD kernels for distance by @richyreachy in https://github.com/alibaba/zvec/pull/687
- feat(turbo): add PQ int4 quantizers and PQFast FastScan support by @zzlin237 in https://github.com/alibaba/zvec/pull/664
- feat(diskann): Add Windows DiskANN support with asynchronous I/O by @iaojnh in https://github.com/alibaba/zvec/pull/625
- feat(turbo): add AVX-512 FP16 distance kernels by @richyreachy in https://github.com/alibaba/zvec/pull/710
- refactor(turbo): migrate neon distance kernels by @JalinWang in https://github.com/alibaba/zvec/pull/689
- feat:support macOS x64 builds by @Cuiyus in https://github.com/alibaba/zvec/pull/713
- feat(quantization): add uniform uint4 reformer/quantizer by @JalinWang in https://github.com/alibaba/zvec/pull/698
- feat(turbo): add SSE distance kernels by @richyreachy in https://github.com/alibaba/zvec/pull/718
- perf(vamana): use split contiguous packed layout by @luoxiaojian in https://github.com/alibaba/zvec/pull/701
- fix: suppress build warning by @richyreachy in https://github.com/alibaba/zvec/pull/720
- fix: synchronize flat cache and collection block switching by @richyreachy in https://github.com/alibaba/zvec/pull/726
- fix(db): synchronize reads of writing segment by @iaojnh in https://github.com/alibaba/zvec/pull/722
- refactor(diskann): adapt diskann to turbo quantizer by @richyreachy in https://github.com/alibaba/zvec/pull/678
- fix(core): IVF n_iters propagation to clusterer by @JalinWang in https://github.com/alibaba/zvec/pull/730
- perf(vamana): port search and prefetch optimizations by @luoxiaojian in https://github.com/alibaba/zvec/pull/727
- ci(deps): bump actions/setup-python from 6 to 7 by @dependabot[bot] in https://github.com/alibaba/zvec/pull/712
- feat(diskann): add Android and iOS support with portable pread I/O by @iaojnh in https://github.com/alibaba/zvec/pull/656
- fix(sqlengine): balance deep OR expression trees by @Cuiyus in https://github.com/alibaba/zvec/pull/694
- fix: preserve vector row mapping when rebuilding indexes with deleted rows by @zhourrr in https://github.com/alibaba/zvec/pull/731
- perf(vamana): optimize search state and fix medoid selection by @luoxiaojian in https://github.com/alibaba/zvec/pull/738
- feat(buffer): harden shared buffer pool core by @iaojnh in https://github.com/alibaba/zvec/pull/708
- fix(db): SIGSEGV when fetch/query race a segment switch; unblock reader concurrency by @YongqiYin in https://github.com/alibaba/zvec/pull/715
- perf(refine): optimize shared kernels and candidate handoff by @luoxiaojian in https://github.com/alibaba/zvec/pull/740
- fix(arm): enable neon fp16 kernels via march auto-detect and runtime dispatch by @richyreachy in https://github.com/alibaba/zvec/pull/723
- chore: enable modernize-use-equals-default and modernize-use-equals-delete by @egolearner in https://github.com/alibaba/zvec/pull/734
- fix: prevent overlapping prefix and suffix matches in LIKE by @egolearner in https://github.com/alibaba/zvec/pull/745
- ci(deps): bump softprops/action-gh-release from 2 to 3 by @dependabot[bot] in https://github.com/alibaba/zvec/pull/725
- perf(uint4): optimize AVX-512 distance and fix Vamana medo
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
Zvec is an open-source, in-process vector database — lightweight, lightning-fast, and designed to embed directly into applications. Battle-tested within Alibaba Group, it delivers production-grade, low-latency and scalable similarity search with minimal setup.
[!Important] 🚀 v0.8.0
- Broader platform support: Added Intel Mac and Windows ARM64 builds, wheels, and SDKs; extended DiskANN to Windows, Android, and iOS, and RaBitQ to Windows x86_64.
- Chinese FTS ready to use: Embedded the default Jieba dictionary and HMM model, so Chinese tokenization needs no separate dictionary files or path configuration.
- Lower index build costs: Reduced peak memory during IVF / DiskANN builds and merges, and accelerated HNSW RaBitQ construction through vector reuse and batched lookups. Build and nested training tasks now enforce configured thread limits more strictly.
- Faster distance computation: Extensively refactored quantizers and distance calculations to benefit multiple quantization types and metrics, with major improvements to INT4 kernels and Linux ARM64 performance.
- Faster search: Added faster Uniform quantizers and optimized Vamana graph layout and prefetching. Uniform quantization avoids per-point score reconstruction, though a shared min/max range can increase quantization error and reduce recall.
- Bug fixes and improvements: Added more flexible UTF-8 document IDs up to 1,024 bytes; fixed concurrent reads during segment switches, index rebuilding with deleted rows, and correctness issues in LIKE and floating-point range filters.
💫 Features
- Blazing Fast: Searches billions of vectors in milliseconds.
- Simple, Just Works: Install and start searching in seconds. Pure local, no servers, no config, no fuss.
- Dense + Sparse Vectors: Support dense and sparse embeddings, multi-vector queries, and a rich selection of vector index types that scale from memory to disk.
- Full-Text Search (FTS): Native keyword-based full-text search — query string fields with natural-language or structured expressions.
- Hybrid Search: Fuse vector similarity, full-text search, and structured filters in a single query for precise results.
- Durable Storage: Write-ahead logging (WAL) guarantees persistence — data is never lost, even on process crash or power failure.
- Concurrent Access: Multiple processes can read the same collection simultaneously; writes are single-process exclusive.
- Runs Anywhere: As an in-process library, Zvec runs wherever your code runs — notebooks, servers, CLI tools, or even edge devices.
📦 Installation
Zvec offers official SDKs across multiple languages:
| SDK | Install / Dependency | Source |
|---|---|---|
| Python | pip install zvec | Source |
| Node.js | npm install @zvec/zvec | Source |
| Go | Installation guide | Source |
| Rust | cargo add zvec-rust | Source |
| Java | org.zvec:zvec-java (Maven) | Source |
| Dart / Flutter | flutter pub add zvec | Source |
Python requires 64-bit Python 3.10–3.14; Java requires Java 8+.
Searching code or documents? Try zvec-grep (zg) — a local-first search CLI that unifies ripgrep, BM25, and vector search, built for humans and AI agents.
Prefer a visual tool? Try Zvec Studio to browse data and debug queries — no code required.
✅ Cross-Platform Support
Linux · macOS · Windows · Android · iOS
Zvec supports all major platforms — from servers and desktops to mobile devices. For more details, please see the platform support documentation.
🛠️ Building from Source
If you prefer to build Zvec from source, please check the Building from Source guide.
⚡ One-Minute Python Example
import zvec

# Define collection schema
schema = zvec.CollectionSchema(
    name="example",
    vectors=zvec.VectorSchema("embedding", zvec.DataType.VECTOR_FP32, 4),
)

# Create collection
collection = zvec.create_and_open(path="./zvec_example", schema=schema)

# Insert documents
collection.insert([
    zvec.Doc(id="doc_1", vectors={"embedding": [0.1, 0.2, 0.3, 0.4]}),
    zvec.Doc(id="doc_2", vectors={"embedding": [0.2, 0.3, 0.4, 0.1]}),
])

# Search by vector similarity
results = collection.query(
    zvec.Query(field_name="embedding", vector=[0.4, 0.3, 0.3, 0.1]),
    topk=10
)

# Results: list of {'id': str, 'score': float, ...}, sorted by relevance
print(results)
📈 Performance at Scale
Zvec delivers exceptional speed and efficiency, making it ideal for demanding production workloads.
For detailed benchmark methodology, configurations, and complete results, please see our Benchmarks documentation.
🤝 Join Our Community
| 💬 DingTalk | 🎮 Discord | X (Twitter) | |
|---|---|---|---|
 |  | ||
| Scan to join | Scan to join | Click to join | Click to follow |
❤️ Contributing
We welcome and appreciate contributions from the community! Whether you're fixing a bug, adding a feature, or improving documentation, your help makes Zvec better for everyone.
Check out our Contributing Guide to get started!
raylib
raysan5·C
用 C 写的轻量级游戏编程库,封装 OpenGL 等底层图形接口,让开发者不用折腾窗口、输入和渲染细节,专注写游戏逻辑,支持桌面、移动端和嵌入式平台。
游戏编程库+4IoT / 固件
35623+413.4k6.22026-11-10 08:11 UTC
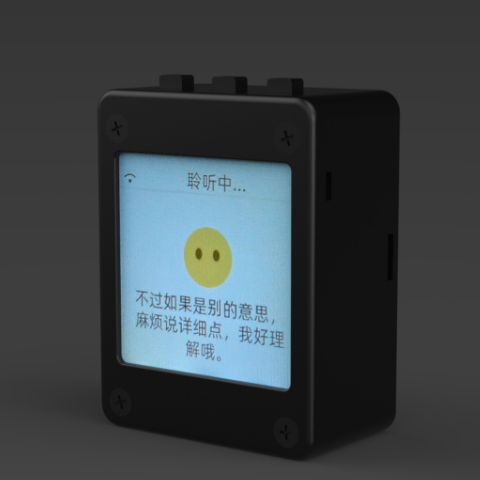
xiaozhi-esp32
78·C++
基于 MCP 协议、跑在 ESP32 上的聊天机器人固件,让单片机也能接入大模型对话与工具调用。
聊天机器人+4IoT / 固件
32984+1427.8kv2.5.22026-11-07 04:14 UTC
DeepSpeech
mozilla·C++
DeepSpeech is an open source embedded (offline, on-device) speech-to-text engine which can run in real time on devices ranging from a Raspberry Pi 4 to high power GPU servers.
IoT / 固件
267724.1k2025-06-19 12:52 UTC
Tasmota
arendst·C
给 ESP8266/ESP32 设备刷的替代固件,通过网页配置、OTA 升级和定时/规则自动化,用 MQTT、HTTP、串口或 KNX 实现完全本地控制。
ESP32+4IoT / 固件
24975+55.2kv16.0.02026-11-10 10:45 UTC