代码在 transformers 4.51.1 下测试,版本不符可能报错;需先从 HuggingFace 下载 DepthLM 权重或基座模型;受法律限制不直接发布整理好的数据,需用 prepare_data.sh 自行处理。
conda create -n DepthLM python=3.12
pip install -r requirements.txt 硬件要求按 README 说明
README 未说明显存与 GPU 型号要求;官方权重为 Pixtral 12B,训练基座示例为 Qwen2.5-VL-3B。
支持 Apple Silicon
用标准文本 SFT 让视觉语言模型直接输出度量深度,无需改架构或加回归头
DepthLM 的官方实现,用视觉语言模型做单目深度估计,把深度预测转成语言建模任务,在 ICLR 2026 入选 Oral。
核心能力
- 用纯文本 SFT 训练 VLM 做度量深度估计
- 无需密集预测头或回归/正则损失
- 单一 VLM 统一处理深度、速度、时间与相机位姿
- 支持 Qwen2.5-VL 与 Pixtral 两类基座模型
- 提供 iBims1 示例数据可直接跑通代码
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
暂无 release 数据(可能没有发版,或尚未同步)。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
[ICLR2026 Oral (top 1.2%)] DepthLM
Official implementation of "DepthLM: Metric Depth from Vision Language Models".
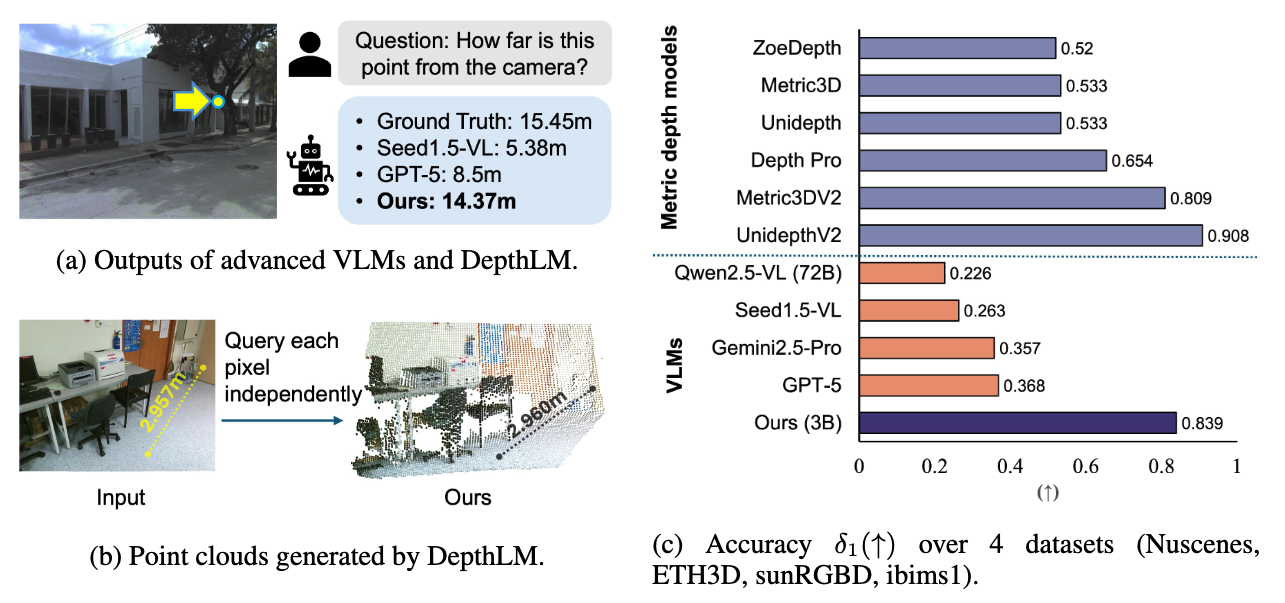
We show for the first time that VLMs can achieve comparable accuracy with pure vision models on metric depth estimation, with standard text-based SFT and no architecture chagne, i.e., no dense prediction head or regression/regularization loss is needed. Such simplicity allows DepthLM to train a unified VLM to handle various complex 3D understanding tasks such as speed or time estimation, and metric scale camera pose estimation, which require different architecture or hand-crafted pipelines in pure vision models.
Citation
If you find our code useful for your research, please consider citing:

@article{cai2025depthlm,
    title={DepthLM: Metric Depth from Vision Language Models},
    author={Cai, Zhipeng and Yeh, Ching-Feng and Hu, Xu and Liu, Zhuang and Meyer, Gregory and Lei, Xinjie and Zhao, Changsheng and Li, Shang-Wen and Chandra, Vikas and Shi, Yangyang},
    journal={arXiv preprint arXiv:2509.25413},
    year={2025},
}
Contact
Zhipeng Cai, Meta Inc, homepage: https://zhipengcai.github.io/, email: czptc2h at gmail dot com.
Prerequisites
- run
conda create -n DepthLM python=3.12 - run
pip install -r requirements.txt(the code is tested with transformers 4.51.1 version)
| Model | Link |
|---|---|
| DepthLM (Pixtral 12B) | Download 🤗 |
| DepthLM (3B) | (Coming soon!) |
| DepthLM (7B) | (Coming soon!) |
Data Preparation
- For each training/eval dataset, we curate them into
- A folder containing the images
- A jsonl file containing the corresponding camera intrinsics and 3D labels
- We provide example data from the iBims1 dataset at examples/ibims1 for quick code run without the need of data preparation. Other images/datasets can use the same code after finishing the data preparation steps.
- Due to legal reasons, we cannot directly release the curated data. However, we provide the data curation code to enable reproduction.
- Checkout each block in prepare_data.sh for the detailed data preparation steps on each dataset.
Eval
- run
bash eval.sh <path_to_your_model>
Training
- Download the base model you want to train from here. Our code currently supports Qwen2.5-VL and Pixtral, please see our paper for the corresponding hyper-parameters.
- run
bash train.sh <path_to_your_model> <output_path>
Results
Comparison with VLMs
Comparison with pure vision models
Point cloud visualization
Related project
Our follow up project VLM³ has been released! It extends the findings of DepthLM to diverse 3D vision tasks!
License
DepthLM is FAIR CC-BY-NC licensed, as found in the LICENSE file.

MiniCPM-V
OpenBMB·Python
MiniCPM-V 是面壁智能开源的多模态视觉语言模型,能在手机、PC 等本地设备上完成看图、听音和对话交互,无需依赖云端。
多模态+4视觉语言模型
27126+342.1k202505272026-11-09 07:37 UTC

LLaVA
haotian-liu·Python
开源的多模态视觉指令微调模型,让 LLaMA 类大模型能看图对话,效果对标 GPT-4V,适合做图文问答和视觉助手。
视觉指令微调+4视觉语言模型
250772.8kv1.2.02024-08-12 09:52 UTC
screenpipe
screenpipe·Rust
持续录制电脑屏幕和音频,把日常工作流整理成可检索的记录,帮你找出值得自动化的环节,并为 AI 智能体提供上下文。
屏幕录制+4视觉语言模型
22335+642.3kapp-v2.7.1452026-11-10 00:40 UTC

Qwen3-VL
QwenLM·Jupyter Notebook
阿里云通义团队开源的多模态大模型系列,能同时理解图像和文本,用于视觉问答、图文推理等视觉语言任务。
多模态大模型+4视觉语言模型
20190+171.9k2026-01-30 04:47 UTC