README 只给出 pip 安装包,未说明各示例的额外依赖与运行方式;GPT-NeoX 等大模型示例需按文档自行准备大显存环境;部分实现依赖 Triton、JAX 等可选后端,README 未说明安装方式。
annotated_deep_learning_paper_implementations
labmlaiMIT活跃维护用 PyTorch 逐行复现 60 多篇深度学习经典论文,代码旁配注释讲解,涵盖 Transformer、优化器、GAN、强化学习等,适合边读论文边对照实现学习。
🧑🏫 60+ Implementations/tutorials of deep learning papers with side-by-side notes 📝; including transformers (original, xl, switch, feedback, vit, ...), optimizers (adam, adabelief, sophia, ...), gans(cyclegan, stylegan2, ...), 🎮 reinforcement learning (ppo, dqn), capsnet, distillation, ... 🧠
暂无版本67,741star +27 / 7 天6,789fork同步于 2026-11-10 05:18 UTC
pip install labml-nn 硬件要求按 README 说明
README 未说明统一硬件要求;仅在 GPT-NeoX 示例中标注生成需 48GB GPU、微调需两张 48GB GPU。
用 PyTorch 复现 60+ 篇深度学习论文,代码与逐行注释并排展示,方便读懂算法细节
用 PyTorch 逐行复现 60 多篇深度学习经典论文,代码旁配注释讲解,涵盖 Transformer、优化器、GAN、强化学习等,适合边读论文边对照实现学习。
核心能力
- 覆盖 Transformer、GAN、扩散模型、强化学习等 60+ 论文实现
- 每个实现配逐行注释,网站并排渲染成可读笔记
- 提供 Triton Flash Attention、LoRA、LLM.int8() 等工程化实现
- 含 Adam、Sophia-G、AdaBelief 等优化器与各类归一化层
- 仓库持续维护,几乎每周新增论文实现
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
暂无 release 数据(可能没有发版,或尚未同步)。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
labml.ai Deep Learning Paper Implementations
Note: use the Annotated Implementation Skill with coding agents to implement any paper with annotations.
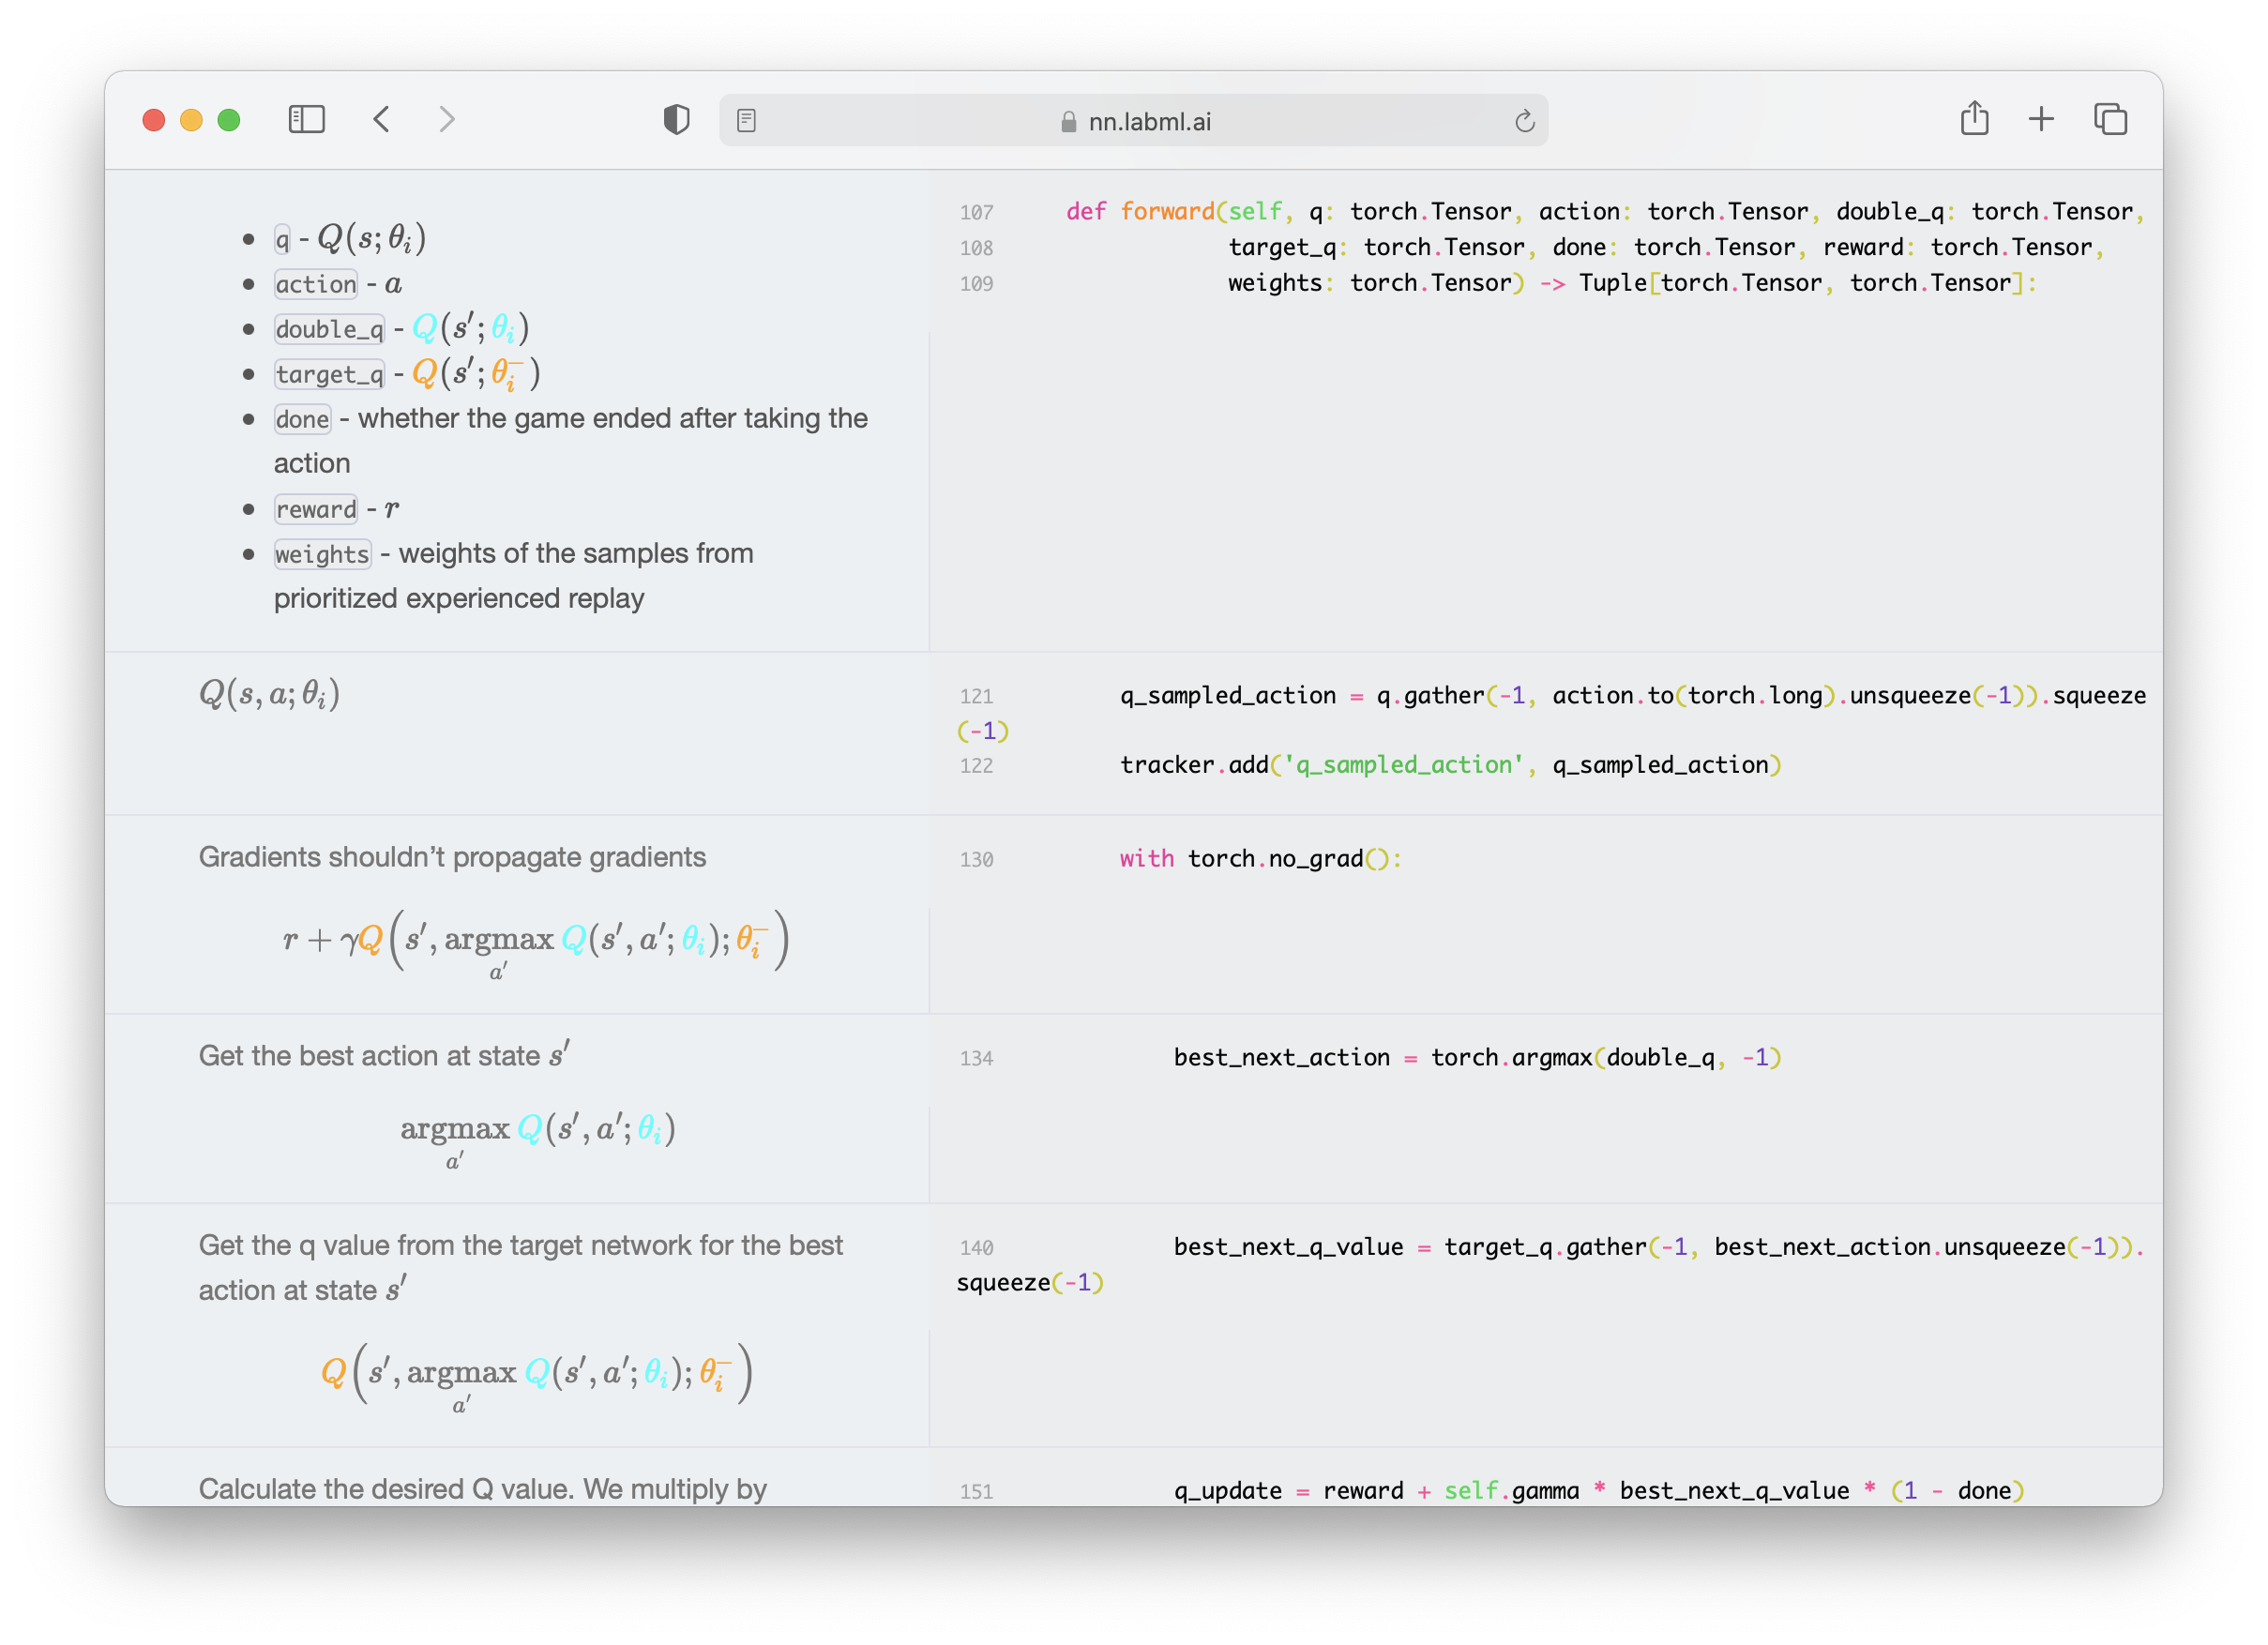
This is a collection of simple PyTorch implementations of neural networks and related algorithms. These implementations are documented with explanations,
The website renders these as side-by-side formatted notes. We believe these would help you understand these algorithms better.
We are actively maintaining this repo and adding new
implementations almost weekly.
Paper Implementations
✨ Transformers
- JAX implementation
- Multi-headed attention
- Triton Flash Attention
- Transformer building blocks
- Transformer XL
- Rotary Positional Embeddings
- Attention with Linear Biases (ALiBi)
- RETRO
- Compressive Transformer
- GPT Architecture
- GLU Variants
- kNN-LM: Generalization through Memorization
- Feedback Transformer
- Switch Transformer
- Fast Weights Transformer
- FNet
- Attention Free Transformer
- Masked Language Model
- MLP-Mixer: An all-MLP Architecture for Vision
- Pay Attention to MLPs (gMLP)
- Vision Transformer (ViT)
- Primer EZ
- Hourglass
✨ Low-Rank Adaptation (LoRA)
✨ Eleuther GPT-NeoX
✨ Diffusion models
- Denoising Diffusion Probabilistic Models (DDPM)
- Denoising Diffusion Implicit Models (DDIM)
- Latent Diffusion Models
- Stable Diffusion
✨ Generative Adversarial Networks
- Original GAN
- GAN with deep convolutional network
- Cycle GAN
- Wasserstein GAN
- Wasserstein GAN with Gradient Penalty
- StyleGAN 2
✨ Recurrent Highway Networks
✨ LSTM
✨ HyperNetworks - HyperLSTM
✨ ResNet
✨ ConvMixer
✨ Capsule Networks
✨ U-Net
✨ Sketch RNN
✨ Graph Neural Networks
✨ Counterfactual Regret Minimization (CFR)
Solving games with incomplete information such as poker with CFR.
✨ Reinforcement Learning
- Proximal Policy Optimization with Generalized Advantage Estimation
- Deep Q Networks with with Dueling Network, Prioritized Replay and Double Q Network.
✨ Optimizers
- Adam
- AMSGrad
- Adam Optimizer with warmup
- Noam Optimizer
- Rectified Adam Optimizer
- AdaBelief Optimizer
- Sophia-G Optimizer
✨ Normalization Layers
- Batch Normalization
- Layer Normalization
- Instance Normalization
- Group Normalization
- Weight Standardization
- Batch-Channel Normalization
- DeepNorm
✨ Distillation
✨ Adaptive Computation
✨ Uncertainty
✨ Activations
✨ Langauge Model Sampling Techniques
✨ Scalable Training/Inference
Installation
pip install labml-nn
unsloth
unslothai·Python
本地跑和训练大模型、扩散模型的图形界面,支持 GGUF、MLX 及 Qwen、DeepSeek、Gemma、FLUX 等主流模型,省去命令行配置的麻烦。
本地推理+4参数高效微调
79262+1277.4kv0.1.916-beta2026-11-10 05:16 UTC

airllm
lyogavin·Jupyter Notebook
单张 4GB 显存显卡就能跑 70B 甚至 2.8T 参数大模型的分层推理方案,通过逐层加载权重把显存需求压到极低,适合本地低配设备部署大模型。
大模型推理+4参数高效微调
42071+1874.3kv4.0.02026-11-09 06:18 UTC

self-llm
datawhalechina·Jupyter Notebook
面向中文用户的 Linux 环境大模型实战教程,手把手教你在本地微调(全参数/LoRA)和部署国内外开源 LLM 与多模态模型。
大模型微调+4参数高效微调
32739+143.2k2026-10-29 10:59 UTC
peft
huggingface·Python
用 LoRA、Adapter 等少量参数微调大模型和扩散模型,大幅降低显存与训练成本,是 Hugging Face 生态里做参数高效微调的标准库。
参数高效微调+4参数高效微调
21880+32.7kv0.21.22026-11-10 00:47 UTC