README 未给出依赖版本约束,需自行确认 PyTorch 兼容性;3D 模式需把 frame_kernel_size 设为大于 1;README 的 Todo 表明 3D 显存效率优化尚未完成
x-unet
lucidrainsMIT活跃维护实现带高效注意力的 U-Net,并融合最新研究改进,适合图像生成和分割任务的训练与微调。
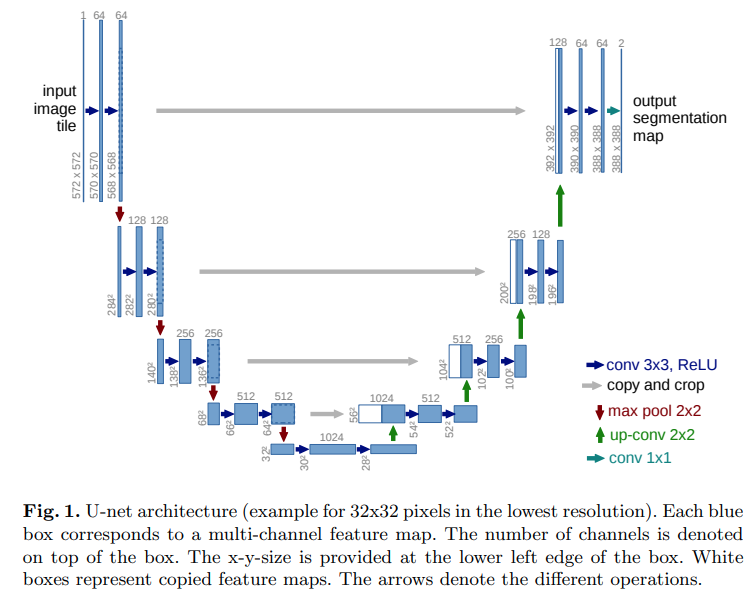
Implementation of a U-net complete with efficient attention as well as the latest research findings
0.4.0发布于 2024-05-03 17:21 UTC294star23fork同步于 2026-11-07 07:30 UTC
pip install x-unet 硬件要求按 README 说明
README 未说明显存或 GPU 型号要求;示例基于 PyTorch 张量,未提及 CPU 运行情况
带高效注意力和最新研究改进的 U-Net 实现,可直接嵌入 PyTorch 分割或生成流程
实现带高效注意力的 U-Net,并融合最新研究改进,适合图像生成和分割任务的训练与微调。
核心能力
- 支持嵌套 U-Net 深度与上采样特征图合并
- 用跨阶段注意力残差替代固定跳跃连接
- 通过 frame_kernel_size 支持 3D 视频与 CT/MRI 输入
- XAttnRes 可单独作为多尺度特征路由器使用
- 集成权重标准化与 QK 归一化等改进
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- 0.4.0最新正式版2024-05-03 · 2024-05-03 17:21 UTC
这个版本没有写更新说明。
- 0.3.12023-07-14 · 2023-07-14 14:41 UTC
这个版本没有写更新说明。
- 0.3.02023-01-05 · 2023-01-05 18:46 UTC
这个版本没有写更新说明。
- 0.2.12023-01-05 · 2023-01-05 17:16 UTC
这个版本没有写更新说明。
- 0.2.02023-01-04 · 2023-01-04 16:15 UTC
这个版本没有写更新说明。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
x-unet
Implementation of a U-net complete with efficient attention as well as the latest research findings
Install
$ pip install x-unet
Usage
import torch
from x_unet import XUnet

unet = XUnet(
    dim = 64,
    channels = 3,
    dim_mults = (1, 2, 4, 8),
    nested_unet_depths = (7, 4, 2, 1),     # nested unet depths, from unet-squared paper
    consolidate_upsample_fmaps = True,     # whether to consolidate outputs from all upsample blocks, used in unet-squared paper
    use_xattnres = True                    # enable cross-stage attention residuals
)

img = torch.randn(1, 3, 256, 256)
out = unet(img) # (1, 3, 256, 256)
You can also completely replace predetermined skip connections with learned cross-stage attention residuals:
unet = XUnet(
    dim = 64,
    channels = 3,
    dim_mults = (1, 2, 4, 8),
    use_xattnres = True,
    xattnres_replace_skips = True          # remove skip connections and rely purely on learned attention residuals
)
For 3d (video or CT / MRI scans)
import torch
from x_unet import XUnet

unet = XUnet(
    dim = 64,
    frame_kernel_size = 3,                 # set this to greater than 1
    channels = 3,
    dim_mults = (1, 2, 4, 8),
    nested_unet_depths = (5, 4, 2, 1),     # nested unet depths, from unet-squared paper
    consolidate_upsample_fmaps = True,     # whether to consolidate outputs from all upsample blocks, used in unet-squared paper
    weight_standardize = True,
    use_xattnres = True
)

video = torch.randn(1, 3, 10, 128, 128)    # (batch, channels, frames, height, width)
out = unet(video) # (1, 3, 10, 128, 128)
Or use XAttnRes standalone as a lightweight learned feature router across multi-scale stages:
import torch
from x_unet import XAttnRes

xattnres = XAttnRes(
    dim = 64,
    dim_ins = (32, 64, 128),
    heads = 1
)

x = torch.randn(1, 64, 32, 32)
history = [
    torch.randn(1, 32, 64, 64),
    torch.randn(1, 64, 32, 32),
    torch.randn(1, 128, 16, 16)
]

out = xattnres(x, history) # (1, 64, 32, 32)
Todo
- memory efficiency for 3d - reversible blocks, checkpointing, memory efficient unet
- offer option for axial convolutions (placing frame convolutions at end of the resnet chain)
Citations
@article{Ronneberger2015UNetCN,
    title   = {U-Net: Convolutional Networks for Biomedical Image Segmentation},
    author  = {Olaf Ronneberger and Philipp Fischer and Thomas Brox},
    journal = {ArXiv},
    year    = {2015},
    volume  = {abs/1505.04597}
}
@article{Qin2020U2NetGD,
    title   = {U2-Net: Going Deeper with Nested U-Structure for Salient Object Detection},
    author  = {Xuebin Qin and Zichen Vincent Zhang and Chenyang Huang and Masood Dehghan and Osmar R Zaiane and Martin J{\"a}gersand},
    journal = {ArXiv},
    year    = {2020},
    volume  = {abs/2005.09007}
}
@inproceedings{Henry2020QueryKeyNF,
    title   = {Query-Key Normalization for Transformers},
    author  = {Alex Henry and Prudhvi Raj Dachapally and Shubham Vivek Pawar and Yuxuan Chen},
    booktitle = {FINDINGS},
    year    = {2020}
}
@article{Qiao2019WeightS,
    title   = {Weight Standardization},
    author  = {Siyuan Qiao and Huiyu Wang and Chenxi Liu and Wei Shen and Alan Loddon Yuille},
    journal = {ArXiv},
    year    = {2019},
    volume  = {abs/1903.10520}
}
@article{Shleifer2021NormFormerIT,
    title   = {NormFormer: Improved Transformer Pretraining with Extra Normalization},
    author  = {Sam Shleifer and Jason Weston and Myle Ott},
    journal = {ArXiv},
    year    = {2021},
    volume  = {abs/2110.09456}
}
@article{Sunkara2022NoMS,
    title   = {No More Strided Convolutions or Pooling: A New CNN Building Block for Low-Resolution Images and Small Objects},
    author  = {Raja Sunkara and Tie Luo},
    journal = {ArXiv},
    year    = {2022},
    volume  = {abs/2208.03641}
}
@inproceedings{Woo2023ConvNeXtVC,
    title   = {ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders},
    author  = {Sanghyun Woo and Shoubhik Debnath and Ronghang Hu and Xinlei Chen and Zhuang Liu and In-So Kweon and Saining Xie},
    year    = {2023}
}
@article{Liu2026XAttnRes,
    title   = {XAttnRes: Cross-Stage Attention Residuals for Medical Image Segmentation},
    author  = {Xinyu Liu and Qing Xu and Zhen Chen},
    journal = {arXiv preprint arXiv:2604.03297},
    year    = {2026}
}
stable-diffusion-webui
AUTOMATIC1111·Python
基于 Gradio 的 Stable Diffusion 网页界面,把文生图、图生图、局部重绘等能力做成可视化操作面板,不用写代码就能跑图像生成。
图像生成+4图像生成进阶
165290+4431kv1.10.12026-03-02 07:00 UTC
ComfyUI
Comfy-Org·Python
基于节点图的扩散模型图形界面与后端,支持本地快速推理和 API 调用,方便搭建和调试图像生成工作流。
扩散模型+4图像生成进阶
146237+75117kv0.45.02026-11-11 05:07 UTC

OpenMontage
OpenMontageInc·Python
把 Claude、Cursor 等 AI 编程助手变成完整视频制作工作室,内置 12 条制作流水线和 100+ 工具,覆盖脚本、配音、图像生成到剪辑全流程。
视频制作+4图像生成硬核
79488+83411k2026-11-09 06:23 UTC

OpenMontage
calesthio·Python
把 Claude、Cursor 等 AI 编程助手变成完整的视频制作工作室,内置 12 条制作流水线和 100+ 工具,覆盖从生成到剪辑的全流程。
视频制作+4图像生成硬核
7786710k2026-11-03 17:42 UTC