- 夜间无人值守跑评审闭环:让一个模型产出、另一个模型复核,第二天早上收 diff 和评审意见,比手写多 agent 编排省掉调度层
- 选题发散阶段:给定一个具体研究方向,批量生成候选 idea 再人工筛,比在对话里逐个追问更容易留下可追溯的记录
- 已有 Claude Code / Codex 工作流想加研究环节:技能是 Markdown,直接放进现有 skills 目录,不用引入新运行时或新依赖
- 跨模型交叉验证:默认让 Codex 做评审方、执行方用别的模型,避免同一模型自评自过

Auto-claude-code-research-in-sleep
wanshuiyinMIT活跃维护 有专家点评一套纯 Markdown 的轻量技能包,让 Claude Code、Codex 等 LLM 智能体在无人值守时自主完成机器学习研究:跨模型评审、想法发现与实验自动化。
ARIS ⚔️ (Auto-Research-In-Sleep) — Lightweight Markdown-only skills for autonomous ML research: cross-model review loops, idea discovery, and experiment automation. No framework, no lock-in — works with Claude Code, Codex, OpenClaw, or any LLM agent.
v0.4.28发布于 2026-09-28 09:38 UTC18,985star +148 / 7 天1,539fork同步于 2026-11-10 23:26 UTC
专家点评
上手难度:进阶更新于 2026-11-11用纯 Markdown 技能文件把选题、实验、评审串成夜间流水线,顶替自研 agent 编排框架
适用场景
踩坑
- 默认评审链路依赖 Codex MCP,而 codex-cli 0.154.0 已移除 codex mcp-server,按旧文档装完会卡在注册这一步,需要走 Quick Start 步骤 2b 或换 ModelScope 等替代组合
- issue 里反复出现 skills-codex 目录版本落后于主线的反馈,说明多套技能副本(claude / codex 等)存在同步滞后,用 codex 分支前先确认它跟主技能目录是否一致
- /idea-discovery 对输入方向的具体程度敏感,给宽泛领域词得到的结果质量会明显下降,这一步的产出仍需人工判断,不能直接当结论用
同类对比
如果只是要单次对话内的 agent 编排,直接用 Claude Code 自带 skills 或 Codex 原生能力即可,不必引入这套;需要带状态、可观测、可重试的流水线时,应该看真正的编排框架而不是 Markdown 技能集。
claude
> /idea-discovery "your research direction" 硬件要求按 README 说明
README 未说明
支持 Apple Silicon
项目说明
由 README 自动翻译提炼纯 Markdown 的自主 ML 研究技能集,让 LLM 代理在睡眠中跑完选题、实验与论文评审
一套纯 Markdown 的轻量技能包,让 Claude Code、Codex 等 LLM 智能体在无人值守时自主完成机器学习研究:跨模型评审、想法发现与实验自动化。
核心能力
- 用 Markdown 技能定义跨模型评审循环,执行模型产出、独立模型复核
- 提供 /idea-discovery 从研究方向自动发现选题
- 用 /experiment-bridge 实现计划、部署并收集实验结果
- 用 /auto-review-loop 夜间完成评审、修改、再评审闭环
- 用 /research-pipeline 串起选题到成稿的端到端流程
容易踩的坑
codex-cli 0.154.0 移除了 codex mcp-server,已安装用户需按 Quick Start 步骤 2b 重新注册 MCP;默认评审依赖 Codex MCP,需另行配置或改用 ModelScope 等替代模型组合;/idea-discovery 需给出具体方向而非宽泛领域,否则效果差
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.4.28最新正式版2026-09-28 · 2026-09-28 09:38 UTC
What's Changed
- fix(aris-cli): honor Windows and macOS system proxies by @JasmineLCY in https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/401
Full Changelog: https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/compare/v0.4.27...v0.4.28
- v0.4.272026-09-18 · 2026-09-18 18:03 UTC
- v0.4.262026-09-16 · 2026-09-16 16:49 UTC
- v0.4.252026-09-16 · 2026-09-16 11:47 UTC
- dsh-aris-v0.1.1dsh-aris v0.1.1 — reviewer works on codex-cli 0.1542026-09-16 · 2026-09-16 07:00 UTC
查看更新说明
codex-cli 0.154 removed
codex mcp-server. dsh-aris 0.1.0 spawned it, so on 0.154+ the profile no longer starts. 0.1.1 runs the reviewer through ARIS's own bridge (mcp-servers/codex-exec/server.py, shipped in the package) overcodex exec— same tools, same results, all 82 skills unchanged,~/.codex/config.tomlstill the reviewer posture contract. Verified on codex-cli 0.153.4 and 0.154.0. Reviewer threads now survive a Harness restart.Update (npm):
dsh plugin --profile web add dsh-aris@latestthen restart the profile. Needs
python33.9 or newer on PATH; macOS's system Python is fine.Without npm — the same tarball:
dsh plugin --profile web add https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/releases/download/dsh-aris-v0.1.1/dsh-aris-0.1.1.tgzSetup and limits: README on the dsh-aris branch.
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
Auto-claude-code-research-in-sleep (ARIS ⚔️🌙)





🌱 ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.
💡 Use ARIS as a skill-based workflow in Claude Code / Codex CLI / Cursor / Trae / Antigravity / GitHub Copilot CLI / OpenClaw / DeepSeek Harness — enjoy any way you like!The executor drives, an independent model (Codex MCP by default) reviews. Alternative model combinations, including ModelScope-hosted models, need no Claude or OpenAI API.
📦 Those are the skills installed directly. Want it in one command? ARIS also ships as a standalone CLI and as plugins: 
🤝 SuperARIS — Your personal research agent with ARIS, powered by a team of agents.
Put ARIS workflows in the hands of a persistent team: your main agent coordinates, while engineering and writing run in parallel. Every member can read ARIS skills and project context on demand. Work directly with Codex on experiments and Gemini on ideas and writing, or choose an all-Codex team. The main agent follows up on deliverables; project files carry memory across sessions. Your existing MCP workers and independent reviewers stay in the loop.
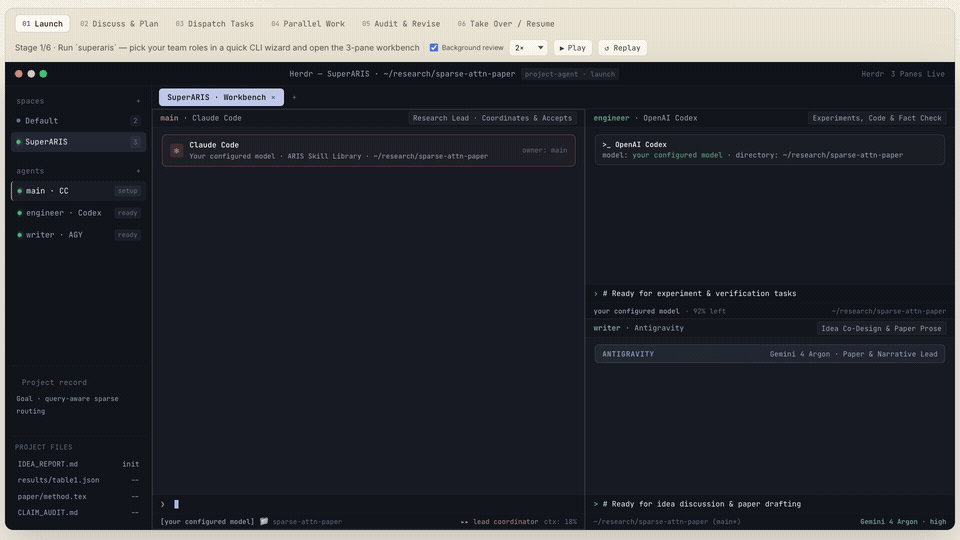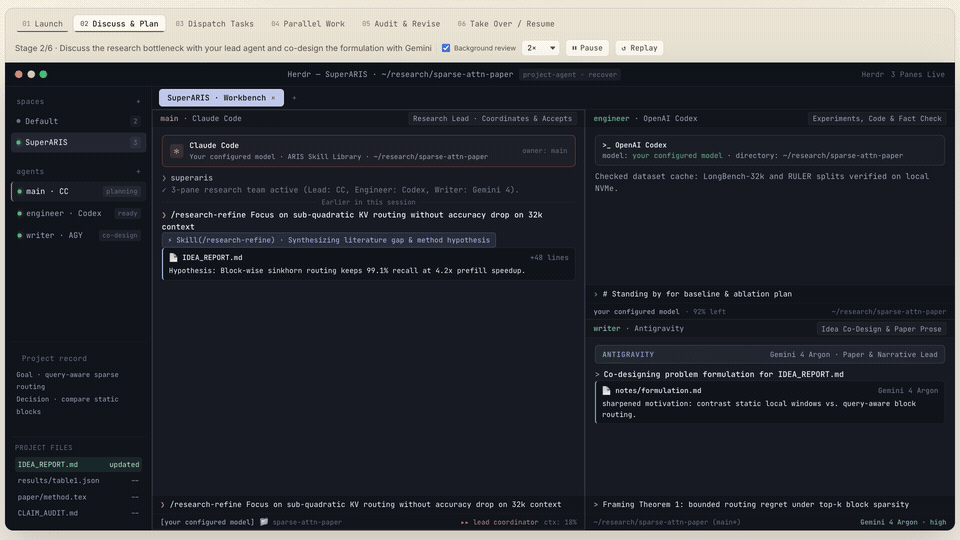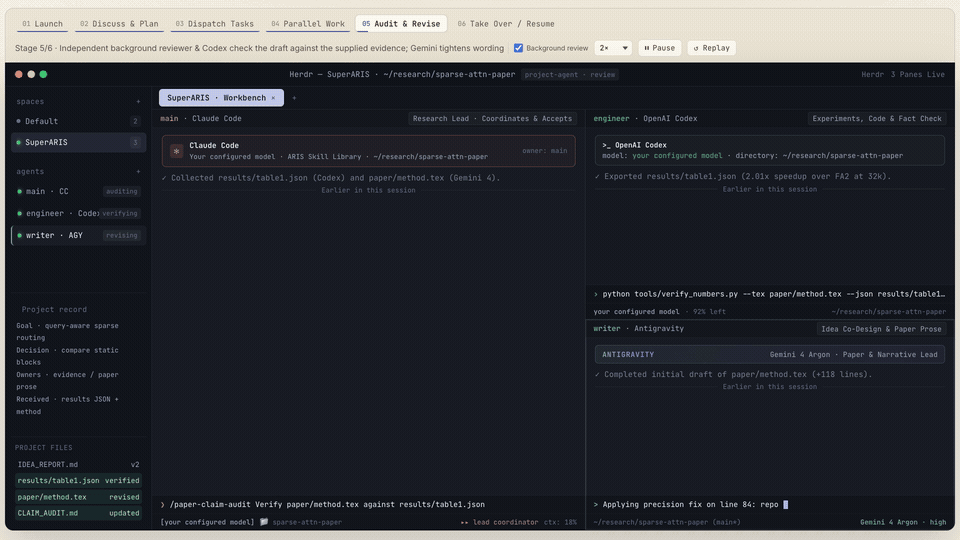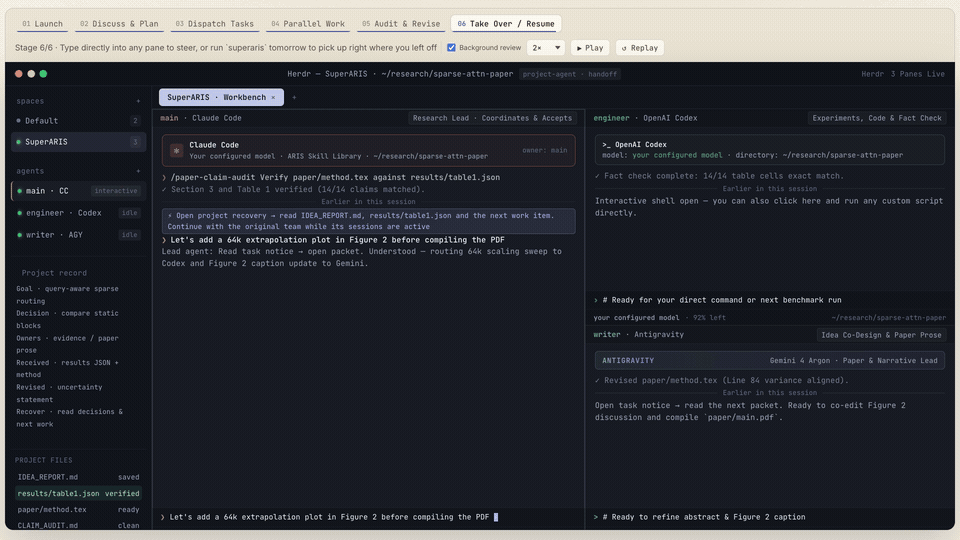
Demo preview · click to watch the full 1080p video (~21 seconds).
❗ 
codex mcp-server — the entry point every ARIS reviewer call used. No impact on ARIS: the codex MCP server is now ARIS's own bridge over codex exec (mcp-servers/codex-exec/), same tools, same results, all 82 skills unchanged, ultra and per-thread resume intact. One re-registration is all it takes — already installed? → Quick Start step 2b · new install → step 2 · what changed.
🧩 The ARIS family — same method, other jobs. One line each; the details live in their own repos.

CLAUDE.md / AGENTS.md against the four shapes agents over-defend in (Hashing, Edge cases, Rubrics, Overbuild), bounding what the agent proposes, never what it looks for. Anti-Autoresearch: 61 integrity signals into a deterministic, reviewer-ready report — fabrication forensics, not an AI-text detector.
/method-figure).
cd aris-monitor && ./run.sh. Many windows? Claude Fleet by @tianyilt is the full dashboard.
🔥 ARIS-Code CLI — 独立安装版 · English | ⬇️ Download · 
ARIS_REASONING_EFFORT works on the Anthropic channel, tool calls through {}-placeholder relays fixed, OS proxy honoured. v0.4.27: launching and quitting the REPL leaves no empty session file. v0.4.26: the fable alias and /model now point at Fable 5.1 (default stays Opus 5). v0.4.25: the Codex reviewer works again on codex-cli ≥ 0.154 (built-in codex exec bridge, nothing to register), /since takes you back to your last input, /resume lists sessions by index, Windows multi-line paste fixed (pending confirmation), 83 bundled skills on GPT-6-Astra.
📰 ARIS-Code v0.4.28 (2026-09) — latest: ARIS_REASONING_EFFORT works on the Anthropic channel (#446), tool calls through relays that send a {} placeholder no longer fail (#444), and the OS proxy on Windows / macOS is used without exporting HTTPS_PROXY (#401). v0.4.27: launching and quitting the REPL no longer leaves an empty session file, and /resume lists only sessions with messages (#439 follow-up). v0.4.26 made Fable 5.1 the fable alias and the first /model entry (the default executor stays Opus 5). v0.4.25 is the reviewer-bridge release: codex-cli 0.154 removed codex mcp-server, so every Codex review from ARIS-Code died on an updated codex. The reviewer now runs over a built-in codex exec bridge — no mcpServers.codex entry, old entries migrate in memory, thread records interoperate with ARIS's Python bridge. Also: /since replays everything after your last input (folded like the live display, /since full for complete output), /resume lists sessions with indices and shows where you stopped (#439), Windows multi-line paste no longer submits line by line (#430, pending confirmation), the Windows shim message carries the native installer (#428), and the bundle moves to 83 skills on GPT-6-Astra. Recent headliners: v0.4.24 — Claude 5 model refresh (Opus 5 default, Fable 5 tier, availability chain) and v0.4.23 — output folding. Caps a 24-release run (v0.4.5 → v0.4.28); per-release detail below. Credits: @GetIT-Sunday, @Anduin9527, @GO-player-hhy, @Jxy-yxJ, @screw-44, @StevenUST, @opposj, @ShijunLei-cn, @algojogacor, @YukinoshitaLove, @jinliye-2026, @SajimJC, @JasmineLCY.
v0.4.28 (2026-09-28) —
ARIS_REASONING_EFFORTnow works on the Anthropic channel (#446):low/medium/high/xhigh/maxfor the main session and subagents; unset, requests are unchanged.ARIS_MAX_TOKENSraises the output cap when a high effort runs into it.autoCompactEnabled: falsein settings turns automatic compaction off. 🐛 #444 tool calls through relays that send a{}placeholder no longer fail withinvalid tool input JSON. 🌐 System proxy on Windows / macOS is used without exportingHTTPS_PROXY(#401, by @JasmineLCY);NO_PROXY=*connects directly as before. Upgrading: if you already exportARIS_REASONING_EFFORT, have an OS proxy, or haveautoCompactEnabled: falsein settings, read the upgrade notes.v0.4.27 (2026-09-19) — launching and quitting the REPL no longer leaves an empty session file;
/resumelists only sessions with messages (#439 follow-up).v0.4.26 (2026-09-16) — Fable 5.1: the
fablealias now resolves toclaude-fable-5-1,/modellists Fable 5.1 first (Fable 5 stays selectable) and the system-prompt identity names it; the default executor remainsclaude-opus-5(the Mythos tier is $10/$50 vs Opus 5's $5/$25, so the default does not move). Savedexecutor_modelvalues are ids, not aliases, and are untouched. Pricing already matched onfable; a test pins 5.1. Tests unchanged (aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6). Codex MCP (gpt-6-astra xhigh) gate: GO.v0.4.25 (2026-09-16) — the reviewer-bridge release. codex-cli 0.154 removed
codex mcp-server, the entry point ARIS-Code'saris setuphad written into settings.json for every Codex review; on an updated codex every review call died. Built-incodex execbridge:mcp__codex__codex/codex-replyrun ascodex exec --jsonwith nothing to register — no settings entry, a legacycodex mcp-serverentry is migrated in memory (env,-cdefaults,requestTimeoutSecs, trust kept), an explicit Python-bridge entry is used as configured, thread records share~/.codex/state/codex-exec/threads/with the Python bridge, 1800 s budget forultraaudits,ARIS_CODEX_BRIDGE=0restores the old path;aris doctorprints the effective backend. Found on the way: the model never received a Codex result'sthreadId(it lives only instructuredContent), socodex-replycould not continue a thread — results now start with athreadId:line./since [full]replays the user's last input and everything after it with the live formatters (display only; after/resumeand in--resumebatch mode too); a dim hint after turns with ≥ 8 tool calls (ARIS_TURN_SUMMARY=0). #430 Windows consoles deliver no paste event, so each pasted line became its own Enter — lines are now merged into the input and never auto-submitted, Ctrl+C discards the rest (ARIS_PASTE_BURST=0; inferred from crossterm's source, pending confirmation on a Windows machine). #439/resumelists sessions with[n]indices and ages and accepts an index, a unique id prefix or a path; the last turn is replayed after loading. #428 the.cmd-shim message carries the official native installer one-liner. Bundle 81→83 (pin 3e49e63 → 4734364):/proof-orchestrator,/research-implement-feature, 32 helpers (+review_gate.py,copilot_native_evidence.py,idea_discovery_gate.py), repo-roottemplates/bundled; reviewer doctrine and system prompt on gpt-6-astra (fallback gpt-5.6-sol → gpt-5.5), explicit— reviewer:directives win,LlmReviewresults carryreviewer_model:so HTTP rounds report toreview_gate.pytruthfully; gpt-6-astra pricing tier $10/$50 (cache write $12.50, read $1). Tests: api 35+6 / aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6, all green; livecodex execfresh + resume roundtrip on codex-cli 0.154.0. Codex MCP (gpt-6-astra): ultra design gate (2 rounds), xhigh implementation gate per step (5/2/2/2 rounds), final whole-diff gate (2 rounds) → GO.v0.4.24 (2026-08-09) — the Claude 5 model refresh (#392, requested by @YukinoshitaLove). Explicit
--model claude-opus-5/claude-fable-5already passed through on every platform — this release makes them first-class. Default →claude-opus-5(main session, subagents,aris setup; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered chain walk (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise404 not_found_error, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks./modelpicker adds Fable 5 / Opus 5 / Sonnet 5; newfablealias. New Mythos-class pricing tier (fable/mythos= $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.v0.4.23 (2026-08-02) — the output-folding release (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). 🧹 Tool-output folding, display layer ONLY: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context,
--output-format jsonand/exportare untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. 🐛 Bash timeout now kills the command: a timed-out call reportedinterrupted: truewhile the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatchARIS_BASH_KILL_ON_TIMEOUT=0; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). 📦 Bundle 79→81 (pin 7182624 → 3e49e63):/integrity-forensics— the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and/web-debug-search, +tools/forensics_gate.py (29 helpers, 104 embedded resources). 🎁 Also: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that"numMatches": nullserializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green under a live proxy; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).v0.4.22 (2026-07-12) — the skills-resync + GPT-6-Astra release. 📦 Bundle resync (pin 7e3ab67 → 7182624, 93 commits): 79 bundled skills (+
meta-apply, +paper-poster-html;paper-posterretired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening —ARIS_SYNC_EXPECT_SHAguard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. 🎛 GPT-6-Astra two-tier reviewer alignment: the CLI's system-prompt nudge now passes the skills' explicitmodel: gpt-6-astra+ per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pinsapproval-policy: "never"+ explicitsandboxon every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display//reviewerare honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). 🐛 8 verified fixes: explicit--modelwas silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices;/modeland/setupre-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution);--output-format jsonnever prompts (locked by a real end-to-end binary test against a mock SSE server); Windowsaris loginfixed (PKCE randomness read /dev/urandom → getrandom); Windows command probing fixed (the PowerShell tool probed itself throughsh; now where.exe); codex.cmdshims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. 🖥 New windows-latest CI job (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.v0.4.21 (2026-06-28) — bug-fix patch: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). 🐛 Headline: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into
�— each HTTP body chunk wasfrom_utf8_lossy'd independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. A saved OpenAI/custom executor config no longer overrides a shell-setEXECUTOR_PROVIDER— the startup "shell-provided vars win" path had one ungated write that re-pointedEXECUTOR_PROVIDER=anthropic … aris …to OpenAI (wrong executor / model-not-found). An Anthropic stream truncated after content but before a terminal signal now hard-errors (premature_eof) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI#249guard; thestop_reason-only compat path is preserved, andARIS_ALLOW_EOF_WITHOUT_STOP=1opts a terminal-signal-less proxy back into the old behavior).grep_searchwithmultiline: truenow matches across lines in content mode (was silently empty —countmode already worked). MCP tool results carried only instructuredContent(emptycontent) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends withmessage_stop) was WebFetch-verified. Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) remain deferred.v0.4.20 (2026-06-19) — bug-fix patch: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). 🐛 Headline (#299): short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, but
finishthen cleared that whole line, erasing a short single-line reply. The REPL now finishes without clearing when the turn printed visible text (Clear(UntilNewLine)wipes only the spinner tail after the reply). Streamed multi-paragraph replies rendered glued ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). Markdown tables with CJK/fullwidth content misaligned — width now counts display cells (CJK = 2), not chars.aris "prompt"/aris setup(REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. Esc now actually closes the completion dropdown (it was recomputed right back).glob_searchreports the total matched count when truncated (not the capped 100, which made the model think a 1000-match glob had 100 files)./model's custom menu reads the effective env the executor uses, not stale on-disk config. Tests (CI mode): api 32 / runtime 205 / tools 67 / aris-cli 172 / commands 5, all green; +7 new; real-machine verified (short reply renders + "✔ Done"; paragraphs keep their blank lines). Codex MCP (gpt-5.5 xhigh): hunt → 3 review rounds (NO-GO → NO-GO → GO). Two latent-only candidates (Anthropic block-indexrouting, OpenAI multi-line SSE) deferred to a hardening pass.v0.4.19 (2026-06-14) — honesty / guardrails patch (theme from a Codex fresh-eyes audit; no behavior change for healthy setups). 🔴 MCP protocol-version negotiation guard — the stdio handshake requested
2025-03-26but never read the version the server negotiated back (a parsed-but-dead field), so a server agreeing on a version ARIS can't speak was silently accepted and latertools/list/tools/callran on an incompatible protocol with opaque failures. ARIS now validates the negotiated version against a supported set (2025-11-25/2025-06-18/2025-03-26/2024-11-05— stdio framing is identical across these) and, on an unsupported one, terminates the child + clears the slot + surfaces a clear per-server error (aris doctorshows it) — the "terminate when versions can't be agreed" behavior the MCP lifecycle spec requires. The request stays2025-03-26(proven againstcodex mcp-server), so healthy servers are unaffected — verified end-to-end: the real Codex MCP server still spawns + initializes + advertises its tools under the guard. 🧹 Papercuts: the OpenAI-family subagent fail-loud message dropped its stale "lands in v0.4.18" marker (now version-agnostic + actionable, still credential-free); OpenAI upstream error bodies are now truncated (500 chars) + credential-redacted (sk-…keys andBearer …tokens, via a substring scanner that catches the compact-JSON shape{"api_key":"sk-…"}a misconfigured proxy can reflect back) instead of splatted verbatim; the system-prompt hook-events summary now counts only the hooks the runtime actually executes (acommandhook with acommandstring), matching the parser. Tests (CI mode): api 32 / runtime 204 / tools 67 / aris-cli 167 / commands 5, all green; live smoke confirms the real Codex MCP server still initializes under the guard. Reviewed by Codex MCP (gpt-5.5 xhigh): design GO → impl NO-GO (compact-secret miss + command-string strictness) → GO after fixes.v0.4.18 (2026-06-14) — default model → Claude Opus 4.8, with corrected pricing and a safety net. The bump moves
DEFAULT_MODEL, theopusalias, the model picker,aris setup, and the subagent default toclaude-opus-4-8— with an availability fallback: if the account lacks 4.8 (the API returns404 not_found_error), ARIS auto-falls-back toclaude-opus-4-7for the session, rebuilds the system-prompt model identity so it stays coherent (the model is never told it's 4.8 while served 4.7), warns once, and retries — for the main session (text + JSON) and subagents. It fires only on that precise 404 (never 400/rate-limit/auth), latches against loops, and the text path rebuilds from a pre-turn snapshot so a retry never double-appends the user message; accounts with 4.8 are byte-identical to a plain bump. 💰 Pricing corrected (verified against Anthropic's published schedule; had been a 3–5× over-estimate): current Opus 4.5–4.8 =$5/$25(deprecated Opus 4/4.1 keep$15/$75, split by word-boundary so a futureopus-4-10isn't mis-tiered); Sonnet 4.x =$3/$15(decoupled from the generic unknown-model fallback, which stays$15/$75); Haiku was already correct. 🧹 Backlog:aris setupoption 10 pins the Codex MCP reviewer tomodel_reasoning_effort="xhigh"(deterministic for new setups, independent of~/.codex/config.toml; idempotent merge never clobbers an existing entry); a startup +aris doctormisconfig hint (#259) for a silently-ignored/misplaced config (malformed JSON, or a stray~/.aris/config.yaml— stderr-only soSessionStart/SessionEnd/… — deferred to a separate issue). Tests (CI mode): api 32 / runtime 202 / tools 67 / aris-cli 166 / commands 5, all green; a live one-shot smoke returnsmodel=claude-opus-4-8end-to-end. Reviewed by Codex MCP (gpt-5.5 xhigh) across the design + both implementation batches (design REWORK→GO, impl NO-GO→GO, batch-2 GO).v0.4.17 (2026-06-13) — the MCP release. Before v0.4.17,
mcpServersinsettings.jsonparsed, showed inaris doctor, and did nothing; now ARIS spawns each configured stdio server, runs the MCP handshake, discovers tools, and advertises them asmcp__<server>__<tool>on both provider paths (Anthropic + OpenAI-family), with end-to-end dispatch, soft per-server degradation, and an approval gate for untrusted MCP tools (external processes the sandbox can't cover;--allowedToolsnow acceptsmcp__names). 🆕 zero-API-key cross-model reviewer:aris setup→ option 10 (Codex MCP, ChatGPT subscription, no API key) writes an idempotentmcpServers.codexentry into the settings file the runtime actually reads (atomic write + backup, explicit consent beforetrust: true), with an optional API reviewer as fallback (ARIS_REVIEWER_PROVIDER=codex-mcp+ARIS_REVIEWER_FALLBACK_PROVIDER);/setupin-REPL rebuilds the system prompt + runtime so reviewer changes take effect without quitting. 🔴 Protocol fix the fakes couldn't catch: real-machine e2e againstcodex mcp-serverexposed that our stdio transport spoke LSP-styleContent-Length:framing while the MCP spec (and codex) use newline-delimited JSON-RPC — every fake-server test passed because the fakes spoke the same wrong dialect; writes are now NDJSON, reads auto-detect both, and the spec-mandatednotifications/initializedis sent afterinitialize(a select-based round-trip also closes the #286 large-request deadlock). Hooks: object-style Claude Code hooks preservematcher/timeout/async(anchored-regex matcher filtering; per-hook timeout, default 30 s kill = warning not deny). Long tail:ARIS_DISABLE_KEYCHAINgate, Anthropicstop_reasonclean-EOF symmetry (CL2), OpenAI tool-callindex-missing merge-by-id (OE6), slash commands enter history. Real-machine push-gate hardening (the zero-key reviewer's first run): codexcodex/eventnotification spam silenced by default (gated behindARIS_MCP_STDERR=inherit), the system prompt now tells the model not to pass amodelparameter to Codex (account default = gpt-5.5 + xhigh; arbitrary names are rejected by a ChatGPT account), and a Codex-MCP-primary-with-no-fallbackLlmReviewcall returns a clear "usemcp__codex__codex" message instead of a misleadingOPENAI_API_KEY/gpt-5.5error. Built with the v0.4.16 zero-regression methodology (24 new characterization tests; every deliberate flip annotated in-place). Tests (CI mode): runtime 199 / aris-cli 165 / tools 67 / api 30 / commands 5, all green. Reviewed phase-by-phase by Codex MCP (gpt-5.5 xhigh) across 17 rounds (7 NO-GOs all resolved). Subagent MCP routing (P8) + MCPprotocolVersionbump + hookasyncexecution deferred to v0.4.18.v0.4.16 (2026-05-30) — REPL UX + provider hardening, shipped under a zero-regression discipline: 64 characterization ("golden") tests locked the current provider-routing / pricing / reviewer / subagent / REPL behavior first, then stayed green through every change. Closes #274: command history now persists to
~/.config/aris/history(0600) and reloads on startup, with anARIS_NO_HISTORYkill-switch and a disk-only secret-skip (credential-looking lines stay in in-session history but never touch disk); bash-style Ctrl+R reverse incremental search (CJK display-width-aware single-line render; no existing key binding changed; no new dependency). Security: an OpenAI-family main session (Kimi / GLM / MiniMax / …) spawning a subagent previously silently billed the user's Anthropic OAuth/Keychain credential — it now fails loud with a clear, credential-free error; full OpenAI-family subagent routing is a cross-crate change deferred to v0.4.17. Groundwork (no behavior change): the 3 byte-identical word-boundary matchers consolidate into one canonicalruntime::word_match; new pureProviderFamilyclassifier (unwired). Tests (CI mode): runtime 164 / aris-cli 128 / tools 49 / commands 5, all green. Codex MCP (gpt-5.5 xhigh) reviewed each phase + a final integration pass.v0.4.15 (2026-05-29) — OpenAI-compatible streaming robustness hotfix. Closes #249: MiniMax (and other OpenAI-compatible providers / proxies) were effectively unusable because the clean-EOF completion check treated the
data: [DONE]SSE sentinel as the only authoritative signal. A non-emptychoices[].finish_reasonis the Chat Completions spec's terminal-chunk marker;[DONE]is a transport convention some compatible providers never emit (MiniMax sendsfinish_reason: "stop"then closes without[DONE]). The clean-EOF decision is now a pure, unit-testedstream_eof_action(...)that completes on EITHER[DONE]OR a non-emptyfinish_reason; reads are NOT stopped early at finish_reason (a trailinginclude_usageusage-only chunk is still consumed), genuine truncation still hard-errors, and a pre-output proxy abort still restarts. Coupled fixes: OE7 reads finish_reason before thedeltaguard (delta-less terminal choice); OE2 flushes pending tool calls on any non-empty finish_reason; OE4 surfaces a mid-stream error envelope as a hard error instead of silently dropping it; OE3 toleratesdata:{...}without the space after the colon. +5 unit tests (77→82) extract the previously-untested SSE completion logic into pure helpers. Anthropic SSE path untouched. Codex MCP (gpt-5.5 xhigh) 3 rounds (GO-WITH-NITS → GO-WITH-NITS → GO).v0.4.14 (2026-05-25) — Security-hygiene release closing the top items from the v0.4.13 codex audit (gpt-5.5 xhigh, 6/10 NEEDS-REWORK verdict). 🔴 S9 (P0) system-prompt config redaction — before v0.4.14,
render_config_section()dumped the mergedsettings.jsonverbatim into the system prompt sent to the LLM provider, leakingenv,mcpServers.<name>.headers.AuthorizationBearer tokens, hook command env, signed-URL query params, andapiKeyfields. New renderer whitelists top-level fields (model/permissionMode/theme/outputStyle/permissions/sandboxwith recursive redaction inside), redacts sensitive keys (apikey/token/secret/password/authorization/headers/env/_KEY/_SECRET/_TOKEN), replaces MCPcommandwith<configured>placeholder, reduces MCPurlto strict<scheme://host[:port]>origin (scheme allow-listhttp/https/ws/wss, ASCII host, digit-only port, IPv6 brackets), and drops hook command strings entirely. Regression test exercises 9 distinct leak surfaces; URL parser has its own targeted test for 7 smuggling attempts including port-position secret injection (codex round-3 catch). 🟡 P9 (P1): DeepSeekaris --helpnow points ataris setupoption 7 instead of an env-var path the resolver never honored. 🟡 M1/M2 (P1) doc:aris doctor+ README/README_CN gain experimental warning whenevermcpServers.len() > 0(full MCP tool dispatch lands v0.4.16). 🟢 C11 (P2) stream idle timeout — both AnthropicMessageStreamand the OpenAI SSE loop wrapresponse.chunk().awaitintokio::time::timeout(envARIS_STREAM_IDLE_TIMEOUT_SECS, default 120, clamp[10, 1800], 0/negative disables); closes the "aris hangs forever with no output" symptom when an upstream HTTPS proxy holds a connection without keepalives. Bundle: 77 skills (+1/wiki-enrichvia late same-day sync to main7e3ab67which also picks up upstreamcheck_ready.shawk + grep-c null-match fix), 54 helpers. Codex MCP 6 rounds (NO-GO + 4 → GO-WITH-NITS + 3 → NO-GO + port smuggling → GO → release metadata GO → sync GO).v0.4.13 (2026-05-25) — Residue-cleanup release closing every codex audit P1 carried since v0.4.10–v0.4.12, plus the long-tail regression tests. 🟡 v0.4.10 P1.D per-server MCP timeout —
mcpServers.<name>.requestTimeoutSecsoverride >MCP_REQUEST_TIMEOUT_SECSenv > 300s default (clamped 1..=1800), so one Codex MCP agent can run 5 min while filesystem MCP errors in 5 s. 🟡 v0.4.10 known limitation closed —McpStdioProcess::request()skips JSON-RPC notifications (id absent/null) and keeps reading until the correlated response. 🟢 meta_opt hook deploy viaaris init—tools/meta_opt/{log_event,check_ready}.shbundle into the binary;aris initwrites ARIS-namespacedaris-meta-opt-log-event.sh/aris-meta-opt-check-ready.shto~/.claude/hooks/(codex round-1 #1: never clobbers user hooks); settings.json merge idempotent, backups hard-fail, final rewrite atomic via tempfile + rename. 🧪 9 v0.4.12 targeted regression tests for sandbox.strictMode (3) + parse strictMode + provider_match pricing + has_word o-series + stream_options 400 + meaningful-content classification + premature-EOF retry truth table (codex round-1 #3 —should_retry_on_premature_eof()extracted to pure fn, 7-row test). Bundle: 76 skills, 54 helpers (+2 meta_opt scripts vs v0.4.12). Codex 3 rounds (NO-GO + 3 → NO-GO + metadata → GO).v0.4.12 (2026-05-22) — Bug-fix + small-feature release. #238
sandbox.strictModeopt-in config key; when set,SandboxConfig::resolve_request()ignores all five LLM-supplied overrides (dangerouslyDisableSandbox,namespaceRestrictions,isolateNetwork,filesystemMode,allowedMounts) — closes the gap where a tool call could silently bypass user sandbox policy.aris doctoradds a "Sandbox:" row; bash tool schema documents the strictMode semantics. #232auto-review-loop-llmupdated from legacydeepseek-chat/deepseek-reasoner(deprecate 2026-07-24; reasoner rejectstool_choice) todeepseek-v4-flash/deepseek-v4-pro. v0.4.10 audit P1 follow-ups: P1.A Anthropic stream retry gates onhas_emitted_meaningful_content(a stream that only sentMessageStartbefore EOF is retry-eligible); P1.Bsupports_reasoning_effort+ reviewer mirror use word-boundary match soopenai/o3-mini/proxy:o4route correctly; P1.Cstream_options.include_usage:trueproxy fallback retries once without on real 400 unknown-field errors; P2 pricing match precision viaprovider_match()soqwen3.6-plus/kimi-k2.5route correctly whilemy-kimi-clonedoes not. Skills sync (76 skills, 52 helpers):/interview-cheatsheet+/render-htmlnewly bundled;build.rsALLOWED_EXTSgainshtmlfor render-html templates;EXCLUDED_SKILL_PREFIXES→starts_with("skills-codex"). CI fetch-depth: 0 + origin/main fetch so drift-test ancestor check runs. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) over 4 rounds.v0.4.11 (2026-05-18) — Skills bundle refresh + sync infrastructure. The embedded skills set in the v0.4.10 binary had fallen behind main (~6 of 56 main
skills/commits had been cherry-picked); v0.4.11 syncs the full set and ships sync infrastructure so the gap can't silently reopen. Bundle: 65→74 user-facing skills, 34→49 helper resources. 10 new skills bundled:/citation-audit(fourth-layer bibliography audit),/experiment-queue(SSH multi-seed job queue with OOM retry),/kill-argument(two-thread adversarial review for theory papers),/resubmit-pipeline(W5: text-only port to a new venue),/paper-talk(end-to-end conference talk pipeline),/slides-polish(per-page Codex layout review),/overleaf-sync(two-way Overleaf Git-bridge),/gemini-search+/openalex(broader literature sources),/qzcli(Qizhi GPU jobs). 46 existing SKILL.md refreshed — most critically the canonical resolver chain rollout (closes real user incident where/research-wikiwas empty for a week from hardcodedtools/research_wiki.py), submission assurance gate + external verifier (/paper-writingPhase 6 now functions). tools/ goes 9→18: 9 baseline helpers refreshed (research_wiki.py315→767 lines with canonicalingest_paperAPI), 9 new helpers (extract_paper_style.py,figure_renderer.py,paper_illustration_image2.py,overleaf_{setup,audit}.sh,verify_wiki_coverage.sh,watchdog.py,experiment_queue/{build_manifest,queue_manager}.py). Newtools/sync_main_skills.shautomates main → bundle rsync with symlink pre-flight + codex-mirror prune +SKILLS_SOURCE_COMMITpinning. 3 new CI drift tests incrates/runtime/src/cache.rscover all 4 resolver layer patterns. Gemini MCP calls in/research-litand/gemini-searchnow passmodel: 'auto-gemini-3'(avoids silent downgrade to 2.5-pro on OAuth-personal capacity exhaustion). CLI runtime unchanged — codex-audit P1 follow-ups remain on v0.4.12 backlog. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) across 5 rounds (REQUEST CHANGES → APPROVE WITH NITS → NO-GO → GO → final GO).v0.4.10 (2026-05-17) — Stream + MCP reliability + multi-provider pricing. C6 whole-stream restart in Anthropic
MessageStream+ OpenAI SSE loop on chunk decode failure / premature EOF (ARIS_STREAM_RETRY, default 2, clamp 0..=5, fires only when nothing emitted yet — closes #228-style "error decoding response body" loop). M3 MCP stdio gains 300s defaulttokio::time::timeoutover send+read (overrideMCP_REQUEST_TIMEOUT_SECS, clamp 1..=1800);response.id ↔ request.idcorrelation;ensure_server_ready()try_wait()dead-process respawn;kill().awaiton all failure paths so the next call starts clean (closes #151 / #172 "Calling codex..." stalls). C8/P4 OpenAI streaming requests now sendstream_options.include_usage:true+ parsecached_tokens; Anthropic streaming mergesMessageStart.usage(input/cache) withMessageDelta.usage(output). C9 multi-provider pricing registry (15+ models, OpenAI cache_read = input × 0.1 corrects 5× generic overstatement, DeepSeek cache_hit/cache_miss tiers,has_word()boundary matcher forprovider/<model>slugs). 9 dead-code warnings cleared;aris setuphelp text synced with actual behaviour.v0.4.9 (2026-05-17) — Closes Codex v0.4.7 audit residuals (L1 TLS double-stack, L3 reasoning_cache compaction misalign, L4 reasoning replay unbounded). 2 new skills bundled (
/figure-spec+/paper-illustration-image2withscripts/subdirs, new Layer 0b =$ARIS_CACHE_DIR/skills/<name>/scripts/);research_wiki.pypromoted to sharedtools/(9+ callers); 5 more SKILL.md migrated to fallback chain.v0.4.8 (2026-05-17) — Skill helper subsystem rewrite. Bundled helpers extract to
~/.config/aris/cache/<version>/at startup; every Skill invocation surfaceshelperReportJSON + 4-layer resolver preamble;/skills exportcopies helpers; newintegration-contract.mdwith 6 failure policies; 8 shared helpers (arxiv/deepxiv/exa/S2/openalex/save_trace/verify_papers/verify_paper_audits) bundled;/research-lit+/deepxivmigrated. Plus 4 bug fixes: gpt-5.5+tools 400 on OpenAI; Custom reviewer reset; missingsignaturefield (#228);--versionBuild date hardcoded.v0.4.7 (2026-05-16) — DashScope Coding Plan 405 fixed (#159) via
native-tlsswitch (#225);reasoning_contentreplay for all reasoning models (OpenAI o1/o3/o4 / DeepSeek-R1 etc.), not just Kimi (#226); 600+ lines dead code cleanup +rustylinedep removed + "Claw Code" → "ARIS-Code" rebrand.v0.4.6 (2026-05-14) — 🚨 Two long-standing silent bugs fixed:
PermissionMode::Promptsilently allowed every tool (derived-Ordbug); system prompt hardcodedcurrent_date = "2026-03-31"made models reject post-cutoff data as future/prompt-injection. Plus Custom OpenAI-compatible provider (/setupoption 11) with dynamic/modelsdiscovery (@Anduin9527 #221 + #222).v0.4.5 (2026-05-13) — First-class reasoning-model support: thinking content blocks end-to-end (fixes #161) +
reasoning_effort='xhigh'for GPT-5.5 / o1 / o3 / o4 / DeepSeek-thinking. DeepSeek V4 Pro + Xiaomi MiMo + Qwen 3.6 + Doubao in/setup(options 7-10). Object-style hooks parser. Default model bumped to Claude Opus 4.7 + GPT-5.5. REPL input hardening (multi-line wrap / Cmd+V paste / CJK boundary). GitHub Actions CI. Credits: @GO-player-hhy (#186), @Jxy-yxJ (#171), @GetIT-Sunday (#216 partial).v0.4.4 (2026-04-20) — Setup UX + reviewer routing fixes (resolves #158, #162) |
/setupno longer forces Bearer for Anthropic + custom URL | Provider-aware proxy URL hints | Stale state no longer leaks across provider switches | LlmReview smart fallbackv0.4.3 (2026-04-17) — Third-party Anthropic-compat proxy support (Bedrock etc.) | Skip beta flags that proxies reject | Propagate custom base URL for
anthropicprovider | Credit @screw-44v0.4.2 (2026-04-17) — Auto-compaction corruption fix | Compaction summary preserved on OpenAI-compat executors | Shell-provided API keys no longer erased on launch
v0.4.1 (2026-04-15) — Plan mode (
/plan) | Cooperative Ctrl+C interrupt | Auto-retry (429/5xx/network) | Research Wiki 📚 (persistent knowledge base) | Self-Evolution 🧬 (/meta-optimize) | Local models (LM Studio/Ollama) | 62 skills syncedv0.3.11 (2026-04-13) — Reviewer Anthropic-compatible mode (Claude via proxy)
v0.3.9 (2026-04-11) — Proxy/custom base URL (CCSwitch) | Local models (LM Studio/Ollama) | Windows (experimental)
v0.3.5 (2026-04-08) — Research Wiki (persistent papers/ideas/experiments/claims + relationship graph) | Meta-Optimize self-evolution (analyze logs → propose SKILL.md patches)
v0.3.0 (2026-04-03) — Multi-file memory index | Rich task system (TodoWrite) |
/plan| Security hardeningv0.2.2 (2026-04-03) —
/planstep-by-step planning |/taskspersistent trackingv0.2.1 (2026-04-03) — Persistent Memory | Kimi K2.5 multi-turn fix | CJK cursor fix
v0.2.0 (2026-04-02) — Open source | Kimi + MiniMax + GLM support | Smart LlmReview routing | CI/CD
v0.1.0 (2026-04-02) — Initial release | Multi-executor & reviewer | 42 bundled skills


中文版 README | English
🌙 Let Claude Code do research while you sleep. Wake up to find your paper scored, weaknesses identified, experiments run, and narrative rewritten — autonomously.
🪶 Radically lightweight — no infrastructure, zero lock-in. The entire skill layer is plain Markdown files. No framework to learn, no database to maintain, no Docker to configure, no daemon to babysit. Every skill is a single
SKILL.mdreadable by any LLM — swap Claude Code for Codex CLI, OpenClaw, Cursor, Trae, Antigravity, Copilot CLI, Windsurf, or your own agent and the workflows still work. Fork it, rewrite it, adapt it to your stack.
💭 Why not self-play with a single model? Using Claude Code subagents or agent teams for both execution and review is technically possible, but tends to fall into local minima — the same model reviewing its own patterns creates blind spots.
Think of it like adversarial vs. stochastic bandits: a single model self-reviewing is the stochastic case (predictable reward noise), while cross-model review is adversarial (the reviewer actively probes weaknesses the executor didn't anticipate) — and adversarial bandits are fundamentally harder to game.
💭 Why two models, not more? Two is the minimum needed to break self-play blind spots, and 2-player games converge to Nash equilibrium far more efficiently than n-player ones. Adding more reviewers increases API cost and coordination overhead with diminishing returns — the biggest gain is going from 1→2, not 2→4.
Claude Code's strength is fast, fluid execution; Codex (GPT-6-Astra xhigh) is slower but more deliberate and rigorous in critique. These complementary styles — speed × rigor — produce better outcomes than either model talking to itself.
🧿 Want the strongest possible reviewer? Add
— reviewer: oracle-proto any skill to route reviews through GPT-5.5 Pro via Oracle MCP. Pro-level reasoning for proof verification, experiment auditing, and final stress tests. Works with API key or free browser mode. Setup →
Contents
- More Than Just a Prompt
- What's New · changelog
- Quick Start · install + first run
- Features
- Score Progression (Real Run)
- Community Showcase — Papers Built with ARIS
- Awesome Community Skills & Extensions
- Workflows · 13 named pipelines (W1 / W1.5 / W2 / W3 / W4 / W5 / W6 / Wiki / WM + Effort / Assurance / Oracle)
- Setup · prerequisites / install / update / usage / GPU server config
- Customization · per-skill config knobs
- Alternative Model Combinations · GLM / MiniMax / Kimi / etc.
- Community
- Citation
- Star History
- Acknowledgements
- License
1. 🎯 More Than Just a Prompt
These are full pipelines — you can also use each workflow independently. Already have an idea? Skip to Workflow 1.5. Have results? Jump to Workflow 3. Got reviews? Jump to Workflow 4. Want persistent memory? Enable Research Wiki. See Quick Start for all commands and Workflows for the full breakdown.
Basic mode — give ARIS a research direction, it handles everything:
/research-pipeline "factorized gap in discrete diffusion LMs"
🔥 Targeted mode — got a paper you want to improve? Give ARIS the paper + the code:
/research-pipeline "improve method X" — ref paper: https://arxiv.org/abs/2406.04329, base repo: https://github.com/org/project
ARIS reads the paper → finds its weaknesses → clones the codebase → generates ideas that specifically fix those weaknesses with that code → runs experiments → writes your paper. Like telling a research assistant: "read this paper, use this repo, find what's missing, and fix it."
Mix and match:
ref paperonly = "what can be improved?",base repoonly = "what can I build with this code?", both = "improve this paper using this code."
🛠️ Build a feature — already know what to build?
/research-implement-feature "add KV-cache reuse to the decoder" — base repo: https://github.com/org/project
Spine first, then one feature at a time, each with a runnable check. Every choice the request left open is written to an assumption ledger before the code that depends on it, and a different model family then reads the raw diff for the ones that went undeclared. It reports "the checks passed", never "the method works". Contributed by @heroarmor.
🔥 Rebuttal mode — reviews just dropped? Don't panic. ARIS reads every concern, builds a strategy, and drafts a rebuttal that's grounded, structured, and under the character limit:
/rebuttal "paper/ + reviews" — venue: ICML, character limit: 5000
Three safety gates — rebuttal will NOT finalize if any fails:
- 🔒 No fabrication — every claim maps to paper/review/user-confirmed result
- 🔒 No overpromise — every promise is user-approved
- 🔒 Full coverage — every reviewer concern is tracked
Two outputs: PASTE_READY.txt (exact char count, paste to venue) + REBUTTAL_DRAFT_rich.md (extended version for manual editing).
| Parameter | Default | What it does |
|---|---|---|
venue | ICML | Target venue (ICML/NeurIPS/ICLR/CVPR/ACL/AAAI/ACM) |
character limit | — | Required. Hard character limit for rebuttal text |
quick mode | false | Stop after parsing + strategy (Phase 0-3). See what reviewers want before drafting |
auto experiment | false | Auto-run supplementary experiments via /experiment-bridge when reviewers ask for new evidence |
max stress test rounds | 1 | How many times GPT-6-Astra xhigh stress-tests the draft |
max followup rounds | 3 | Per-reviewer follow-up round limit |
After acceptance — your paper is in, now prepare the presentation:
/paper-slides "paper/"     # → Beamer PDF + PPTX + speaker notes + Q&A prep
/paper-poster-html "paper/" # → measurement-gated HTML/CSS poster → print-ready PDF
💡 From idea to paper to podium — one toolchain. 🌱
2. 📢 What's New
⚠️ For updates to ARIS bundled skills, run
bash tools/smart_update.sh --apply(Codex:smart_update_codex.sh). For external components, follow the setup linked in their entry.
-
2026-11-04 — 🔎 Community spotlight: Absent Author — an evidence catalog and two skills for author self-checks and reviewer screening of AI-assisted papers. Meet the project →
-
2026-11-01 — ⏱️ Goal Pulse for Codex Goals — HERO's Goal Pulse keeps long Goals moving with bilingual reminders every 30 minutes. On Goal start, resume, or takeover of an active Goal, the main agent reads and enables it for the current thread by default; no separate request is needed. Supports compatible Codex app-server setups on macOS/Linux. Setup and behavior; HERO maintains the single implementation.
Full Chinese reminder sent by the timer:
中文:以最快的有效速度持续推进当前 Goal,不允许磨洋工、偷懒、空转,或拿计划和汇报代替执行。
worker/子代理一交付完整产物,立即读取、核验,并推进到下一项已授权的验收或交接步骤,不得搁置或等整批。
同一卡点连续两轮无实质进展,主代理立即接管具体缺口或重新拆分,同时推进其它独立任务。
复用已有成果与有效验证,砍掉重复检查、无收益的 corner case 和包装。
不得降低原目标、难度和验收标准,不得越过授权和预算;直接行动,无需专门回复本提醒。
-
2026-11-01 — ✍️ Let Gemini or another configured model draft your paper — the new Model Worker MCP supports model and reasoning-effort selection through Antigravity, Grok, or Claude Code, with file reading, writing, and same-session revision. Both complete Claude Code and Codex skill packs support the split: the main agent grounds the facts and narrative, the writer drafts the prose, and the reviewer is selected separately. Without an external writer, the main agent writes directly. HERO and the launch principle guide planning, drafting, and revision: lead with contributions and evidence, state necessary conditions where they a