还需额外安装 bug 修复版 AutoGPTQ(ChenMnZ/AutoGPTQ-bugfix),否则无法做真实量化;运行前要先用 git lfs 克隆 act_shifts 和 act_scales,或自行运行 generate_act_scale_shift.py 生成;真实量化受 AutoGPTQ 内核限制,仅权重量化只省显存但推理更慢。
OmniQuant
OpenGVLabMIT更新放缓一种简单又强大的大模型量化技术,通过可学习权重裁剪和等价变换,在保持精度的同时把 LLM 压到低比特,方便部署推理。
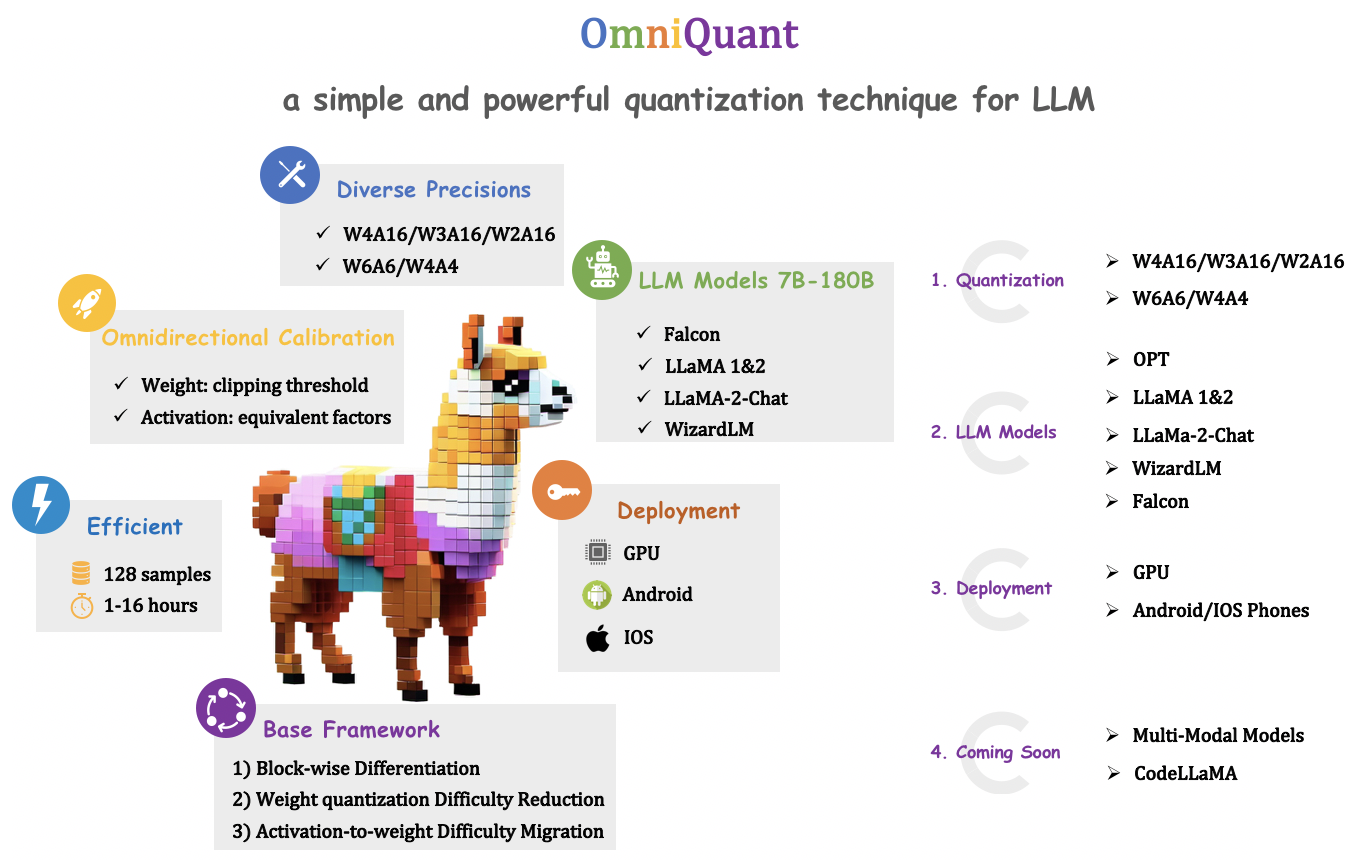
[ICLR2024 spotlight] OmniQuant is a simple and powerful quantization technique for LLMs.
v0.0.1发布于 2023-08-25 08:46 UTC968star93fork同步于 2026-11-07 07:30 UTC
conda create -n omniquant python=3.10 -y
conda activate omniquant
git clone https://github.com/OpenGVLab/OmniQuant.git
cd OmniQuant
pip install --upgrade pip
pip install -e . 硬件要求按 README 说明
README 未给出统一显存要求;提到 Falcon-180b 量化后可在单张 A100 80GB 上推理,MLC-LLM 部署覆盖 NVIDIA、AMD、Intel GPU 及手机端。
多卡 / 张量并行
ICLR2024 spotlight 的 LLM 量化算法,支持权重与权重激活量化,并附带预训练量化参数
一种简单又强大的大模型量化技术,通过可学习权重裁剪和等价变换,在保持精度的同时把 LLM 压到低比特,方便部署推理。
核心能力
- 支持 W4A16/W3A16/W2A16 仅权重量化与 W6A6/W4A4 权重激活量化
- 用可学习权重裁剪 LWC 与可学习等价变换 LET 做校准
- 提供 LLaMA/OPT/Falcon/Mixtral 等预训练 OmniQuant 参数可直接复用
- 借助 AutoGPTQ 内核实现真实量化以降低显存占用
- 配套 MLC-LLM 示例可在 GPU 与手机端部署 W3A16g128 模型
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.0.1Android App最新正式版2023-08-25 · 2023-08-25 08:46 UTC
这个版本没有写更新说明。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models


 🔥🔥🔥

OmniQuant is a simple and powerful quantization technique for LLMs. The current release supports:
- OmniQuant algorithm for accurate weight-only quantization (
W4A16/W3A16/W2A16) and weight-activation quantization (W6A6,W4A4) - Pre-trained Omniquant model zoo for LLMs (
LLaMA-1&2,LLaMA-2-Chat,OPT,Falcon,Mixtral-7Bx8; load to generate quantized weights). - A out-of-the-box case that leverages MLC-LLM to run LLaMa-2-Chat (7B/13B) with W3A16g128 quantization on GPUs and mobile phones.
News
- [2025/11] 🔥 We open-source INT vs. FP, a framework to compare low-bit integer and float-point formats, including MXFP8/MXFP6/MXFP4/NVFP4 and MXINT8/MXINT6/MXINT4/NVINT4.
- [2025/05] 🔥 We explore the Scaling Law for Quantization-Aware Training, which offers insights and instruction for LLMs QAT.
- [2024/10] 🔥 We release a new weight-activation quantization algorithm, PrefixQuant, which proposed an efficient method to isolate sink token (token-wise outlier).
- [2024/7] 🔥 We release a new quantization algorithm, EfficientQAT, which realizes quantization-aware training in a time-efficient and memory-efficient manner. Additionally, EfficientQAT is the current SoTA of uniform quantization.
- [2024/1] 🌟 Our OmniQuant paper has been accepted for a Spotlight presentation at ICLR 2024 (only top 5% out of over 7200 submissions)! 🎉 Cheers!
- [2023/12] 🔥 We provide support for Mixtral-8x7B. OmniQuant is capable of achieving near-lossless 4-bit quantization with Mixtral-8x7B-v0.1, which reduces the memory requirement from 87GB to 23GB.
- [2023/09] 🔥 We have expanded support for Falcon. OmniQuant efficiently compresses Falcon-180b from 335G to 65G, with minimal performance loss. Furthermore, this compression allows for Falcon-180b inference on a single A100 80GB GPU. For details, refer to runing_falcon180b_on_single_a100_80g.

Contents
Install
conda create -n omniquant python=3.10 -y
conda activate omniquant
git clone https://github.com/OpenGVLab/OmniQuant.git
cd OmniQuant
pip install --upgrade pip
pip install -e .
We also leverage the kernel from AutoGPTQ to achieve real quantization. So you should also install the bug-fixed AutoGPTQ as follows::
git clone https://github.com/ChenMnZ/AutoGPTQ-bugfix
pip install -v .
OmniQuant Model Zoo
We provide pre-trained Omniquant model zoo for multiple model families, including LLaMa-1&2, LLaMa-2-Chat, OPT.
You can download the pre-trained OmniQuant parameters you need at Huggingface.
The detailed support list:
| Models | Sizes | W2A16 | W2A16g128 | W2A16g64 | W3A16 |
|---|---|---|---|---|---|
| LLaMA | 7B/13B/30B/65B | ✅ | ✅ | ✅ | ✅ |
| LLaMA-2 | 7B/13B/70B | ✅ | ✅ | ✅ | ✅ |
| OPT | 125m/1.3B/2.7B/6.7B/13B/30B/66B | ✅ | ✅ | ✅ | ✅ |
| Models | Sizes | W3A16g128 | W4A16 | W4A16g128 | W6A6 | W4A4 |
|---|---|---|---|---|---|---|
| LLaMA | 7B/13B/30B/65B | ✅ | ✅ | ✅ | ✅ | ✅ |
| LLaMA-2 | 7B/13B/70B | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | 125m/1.3B/2.7B/6.7B/13B/30B/66B | ✅ | ✅ | ✅ | ✅ | ✅ |
| LLaMA-2-Chat | 7B/13B | ✅ |
Usage
We provide full script to run OmniQuant in ./scripts/. We use LLaMa-7B as an example here:
- Obtain the channel-wise scales and shifts required for initialization:
conda install git git-lfs
git lfs install
git clone https://huggingface.co/ChenMnZ/act_shifts
git clone https://huggingface.co/ChenMnZ/act_scales
Optional, we also offer the script that you can generate channel-wise scales and shifts by yourself:
python generate_act_scale_shift.py --model /PATH/TO/LLaMA/llama-7b
- Weight-only quantization
# W3A16
CUDA_VISIBLE_DEVICES=0 python main.py \
--model /PATH/TO/LLaMA/llama-7b  \
--epochs 20 --output_dir ./log/llama-7b-w3a16 \
--eval_ppl --wbits 3 --abits 16 --lwc

# W3A16g128
CUDA_VISIBLE_DEVICES=0 python main.py \
--model /PATH/TO/LLaMA/llama-7b  \
--epochs 20 --output_dir ./log/llama-7b-w3a16g128 \
--eval_ppl --wbits 3 --abits 16 --group_size 128 --lwc
- weight-activation quantization
# W4A4
CUDA_VISIBLE_DEVICES=0 python main.py \
--model /PATH/TO/LLaMA/llama-7b  \
--epochs 20 --output_dir ./log/llama-7b-w4a4 \
--eval_ppl --wbits 4 --abits 4 --lwc --let \
--tasks piqa,arc_easy,arc_challenge,boolq,hellaswag,winogrande
-
reproduce evaluation results of our paper
1) download the pretrained OmniQuant parameters you want through Huggingface.
2) set epoch as 0 and inference with resume, take LLaMa-7B with W3A16g128 quantization as an example:
CUDA_VISIBLE_DEVICES=0 python main.py \
--model /PATH/TO/LLaMA/llama-7b  \
--epochs 0 --output_dir ./log/test \
--eval_ppl --wbits 3 --abits 16 --group_size 128 --lwc \
--resume /PATH/TO/Pretrained/Parameters
More detailed and optional arguments:
--model: the local model path or huggingface format.--wbits: weight quantization bits.--abits: activation quantization bits.--group_size: group size of weight quantization. If no set, use per-channel quantization for weight as default.--lwc: activate the Learnable Weight Clipping (LWC).--let: activate the Learnable Equivalent Transformation (LET).--lwc_lr: learning rate of LWC parameters, 1e-2 as default.--let_lr: learning rate of LET parameters, 5e-3 as default.--epochs: training epochs. You can set it as 0 to evaluate pre-trained OmniQuant checkpoints.--nsamples: number of calibration samples, 128 as default.--eval_ppl: evaluating the perplexity of quantized models.--tasks: evaluating zero-shot tasks.--resume: loading pre-trained OmniQuant parameters.--multigpu: to inference larger network on multiple GPUs--real_quant: real quantization, which can see memory reduce. Note that due to the limitations of AutoGPTQ kernels, the real quantization of weight-only quantization can only lead memory reduction, but with slower inference speed.--save_dir: saving the quantization model for further exploration.
Runing Quantized Models with MLC-LLM
MLC-LLM offers a universal deployment solution suitable for various language models across a wide range of hardware backends, encompassing iPhones, Android phones, and GPUs from NVIDIA, AMD, and Intel.
We compile the OmniQuant's quantization models through MLC-LLM and offer an out-of-the-box case here. You can see smaller gpu memory usage and inference speedup. Detailed instructions can be found in in runing_quantized_models_with_mlc_llm.ipynb.
Specially, we also deploy the aforementioned two quantized models into mobile phones through MLC-LLM. You can download the Android app by simply clicking the button below:
This app includes three models, LLaMa-2-7B-Chat-Omniquant-W3A16g128asym, LLaMa-2-13B-Chat-Omniquant-W3A16g128asym, and LLaMa-2-13B-Chat-Omniquant-W2A16g128asym. They require at least 4.5G, 7.5G, and 6.0G free RAM, respectively. Note that 2bit quantization has worse performance compared to 3bit quantization as shown in our paper. The inclusion of 2-bit quantization is just an extreme exploration about deploy LLM in mobile phones. Currently, this app is in its demo phase and may experience slower response times, so wait patiently for the generation of response. We have tested this app on Redmi Note 12 Turbo (Snapdragon 7+ Gen 2 and 16G RAM), some examples are provided below:
- LLaMa-2-7B-Chat-Omniquant-W3A16g128asym
- LLaMa-2-13B-Chat-Omniquant-W3A16g128asym
- LLaMa-2-13B-Chat-Omniquant-W2A16g128asym
We also have tested this app on iPhone 14 Pro (A16 Bionic and 6G RAM), some examples are provided below:
- LLaMa-2-7B-Chat-Omniquant-W3A16g128asym
Results
- OmniQuant achieve SoTA performance in weight-only quantization

- OmniQuant achieve SoTA performance in weight-activation quantization

- OmniQuant is generalize, also obatins excellent performance in instruction-tuned models with GPT-4 evaluation

- MLC-LLM can obtain really speedup and memory saving for W4A16/W3A16/W2A16 quantization

Related Project
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
GPTQ: Accurate Post-training Compression for Generative Pretrained Transformers
RPTQ: Reorder-Based Post-Training Quantization for Large Language Models
Citation
If you use our OmniQuant approach in your research, please cite our paper:
@article{OmniQuant,
  title={OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models},
  author={Shao, Wenqi and Chen,Mengzhao and  Zhang, Zhaoyang and Xu, Peng and Zhao, Lirui and Li, Zhiqian and Zhang, Kaipeng Zhang, and Gao, Peng, and Qiao, Yu, and Luo, Ping},
  journal={arXiv preprint arXiv:2308.13137},
  year={2023}
}
headroom
headroomlabs-ai·Python
在工具输出、日志、文件和 RAG 片段进入 LLM 前先做压缩,编码 Agent 省约 20% token,JSON 省 60-95%,答案不变。提供库、代理和 MCP 服务器三种用法。
上下文压缩+4量化
79264+2196.2kv0.43.12026-11-10 05:09 UTC

llmfit
AlexsJones·Rust
一条命令就能从数百个模型和供应商里筛出适合你硬件配置的本地大模型,省去逐个试跑和查显存的麻烦。
本地推理+4量化
38868+1412.5kv1.1.202026-11-09 21:31 UTC
PaddleNLP
PaddlePaddle·Python
基于飞桨的 NLP 与大模型开发库,提供丰富模型库,覆盖 BERT、ERNIE、LLaMA 等,支持分布式训练、压缩和文档智能等任务。
大模型开发库+4量化
12987+13.0krl-v1.0.02026-05-23 02:54 UTC

bitsandbytes
bitsandbytes-foundation·Python
让大模型在普通显卡上跑起来的 PyTorch 量化库,支持 8-bit 和 4-bit 权重压缩,也是 QLoRA 微调背后的核心依赖。
量化+4量化
85369420.50.22026-11-02 14:36 UTC