GRPO 的 accuracy_reward 依赖 math-verify,需额外执行 pip install trl[math_verify];trl.experimental 下的功能不稳定,可能随时变更或移除;示例代码需从 Hugging Face Hub 下载模型和数据集,需保证网络与缓存空间。
pip install trl 硬件要求按 README 说明
README 未给出具体显存要求;支持单 GPU 到多节点集群,可通过 ROCm 在 AMD Instinct GPU 上运行,也支持 AWS Trainium。
支持 ROCm / AMD
Hugging Face 出品的后训练库,用 SFT、DPO、GRPO 等方法微调大模型
用强化学习训练 Transformer 语言模型的全流程库,覆盖 SFT、奖励建模到 PPO/DPO 等 RLHF 算法,省去自己拼训练管线。
核心能力
- 提供 SFTTrainer、DPOTrainer、GRPOTrainer、KTOTrainer、RewardTrainer 等训练器
- 基于 Accelerate 支持 DDP、DeepSpeed ZeRO、FSDP 分布式训练
- 集成 PEFT 与 LoRA/QLoRA,量化后在有限硬件上训练大模型
- 集成 Unsloth 优化内核加速训练
- 提供 trl sft/dpo/kto 命令行接口,无需写代码即可微调
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v1.17.1最新正式版2026-10-30 · 2026-10-30 14:15 UTC
What's Changed
- Keep a parenthesis inside an LFM2.5 tool-call argument from closing the call by @albertvillanova in https://github.com/huggingface/trl/pull/7942
Full Changelog: https://github.com/huggingface/trl/compare/v1.17.0...v1.17.1
- v1.17.02026-10-29 · 2026-10-29 15:51 UTC
查看更新说明
Features
🔥 Mistral Large 4: fine-tune a 1T-parameter model on one node
TRL now supports
mistralai/Mistral-Large-4-1T-A52B: 1T parameters, 52B active. The new LoRA example fine-tunes it withSFTTraineron a single 8×B300 node, on top of its FP8 weights: the experts are split 8 ways with token dispatch, everything else is sharded across the 8 GPUs at load time by transformers'DistributedConfig, and LoRA trains attention and the dense and shared-expert MLPs.Measured: 32.7k tokens per step in ~8 s, 142 GiB per GPU, with packing and assistant-only loss on reasoning conversations.
https://github.com/user-attachments/assets/5aa86ec7-6444-4bed-bfdc-0445e99bea0d
training_args = SFTConfig( model_init_kwargs={ "dtype": "auto", # keep the FP8 weights "distributed_config": DistributedConfig(fsdp_size=8, ep_size=8), }, packing=True, assistant_only_loss=True, ... ) trainer = SFTTrainer(model="mistralai/Mistral-Large-4-1T-A52B", args=training_args, peft_config=LoraConfig(...), ...)assistant_only_loss=Trueworks out of the box: TRL ships a training chat template that matches the released checkpoint's, including itsreasoning_effortlevels (low,medium,high). Needstransformers>=5.22.0,peft>=0.21.0andaccelerate>=1.15.0.- Add Mistral Large 4 by @qgallouedec in https://github.com/huggingface/trl/pull/8017
- Sync the Mistral Large 4 chat template with the released checkpoint by @albertvillanova in https://github.com/huggingface/trl/pull/8018
🎯 Unbiased importance sampling under top-k, top-p and min-p
vLLM normalizes its log-probabilities over the tokens left after
top_k,top_pandmin_pfiltering, while the trainer normalized over the whole vocabulary. Every sampled token's log-ratio was off by the log of the probability mass the filter kept, so the vLLM importance sampling ratio was biased towards 0 (around 1e-4 instead of 1 withtop_p=0.9). The trainers now normalize over the candidate set each token was sampled from, following Keep Sampling Mask from DeepSeek-V3.2.- AsyncGRPO: renormalize log-probs over the top-k/top-p candidate set by @AmineDiro in https://github.com/huggingface/trl/pull/7627
- GRPO: renormalize log-probs over the top-k/top-p candidate set (vLLM colocate mode, vLLM >= 0.28; server mode will follow) by @albertvillanova in https://github.com/huggingface/trl/pull/7866
- Require
top_kwithmin_pin AsyncGRPO so the importance sampling ratio stays unbiased by @albertvillanova in https://github.com/huggingface/trl/pull/7937 - Track the support maximum in the chunked log-prob kernel, so a far-below-max candidate set no longer gives a log-probability of 0 and non-finite gradients, by @kashif in https://github.com/huggingface/trl/pull/7983
💥 What this changes for you. vLLM bounds the candidate set it returns with
top_k, so with vLLM and the importance sampling correction on (the default),GRPOConfignow raises whentop_p < 1.0ormin_p > 0.0is set withouttop_k > 0. Settop_k(e.g.top_k=512), orvllm_importance_sampling_correction=False.⚖️ Score centering is the default AsyncGRPO objective
AsyncGRPO's old log-probs are the vLLM sampler's, so its ratio mixes staleness with the numerical mismatch between the server and the trainer. With an FP8 sampler and a bf16 trainer, the clipped objective collapses: reward goes from 0.60 to 0.34 (FP8 weights) or 0.10 (FP8 weights + KV cache) by step 300, against 0.71 with a bf16 sampler.
[Score centering](htt
- v1.16.02026-10-15 · 2026-10-15 18:00 UTC
查看更新说明
Features
🛠️ TRL now trains on AWS Trainium
The fused LM head from v1.15 is what made Neuron tractable; the remaining gaps are closed here. There is a guide to go with it.
Neuron recompiles once per input shape, so an unpadded run stalls about a minute on every new sequence length.
pad_to_multiple_ofnow defaults to"auto": 128 on Neuron,Noneelsewhere, so nothing changes on GPU. Trainium2, Qwen3-0.6B SFT, 20 steps: 130 s with the default against 260 s without.- Add a guide for training on AWS Trainium by @qgallouedec in https://github.com/huggingface/trl/pull/7729
- Default
pad_to_multiple_ofto"auto"by @qgallouedec in https://github.com/huggingface/trl/pull/7724 - Run the fused LM head and distillation kernels on devices without Triton by @qgallouedec in https://github.com/huggingface/trl/pull/7669
- Report the Neuron device in
trl envand telemetry by @qgallouedec in https://github.com/huggingface/trl/pull/7672 - Support any accelerator in activation offloading by @qgallouedec in https://github.com/huggingface/trl/pull/7670
🌳 Tree attention for AsyncGRPO
AsyncGRPO now packs every micro-batch row as a prefix tree instead of a flat sequence. Multi-turn and multi-generation rollouts repeat a lot of prefix: on a shared prompt, those tokens used to be forwarded once per row. Tree packing forwards them once.
rollout 0:  [ prompt ] [ completion A ]              prompt ──┬── completion A ── later turn
rollout 1:  [ prompt ] [ completion B ]        =>             └── completion B
rollout 2:  [ prompt ] [ completion A ] [ … ]
Chains without a fork collapse into segments, and each segment's queries attend to the K/V gathered along its root-to-segment path in a single FA3 varlen call. No mask tensor: every layer except attention runs once per unique token, and only K/V is duplicated along shared prefixes.
Qwen3-1.7B, 32K tokens per rollout, forward + backward:
layout packing ratio sequence packing tree packing peak GiB shared prompt 1.00 8677 ms 8737 ms (0.99×) 35.2 → 35.2 shared prompt 2.29 8266 ms 4341 ms (1.90×) 35.2 → 18.0 shared prompt 3.37 8179 ms 2755 ms (2.97×) 35.2 → 13.6 nested fork 1.60 8557 ms 6217 ms (1.38×) 35.2 → 23.8 nested fork 3.56 8172 ms 2635 ms (3.10×) 35.2 → 13.5 There is no
packingoption to choose: with nothing shared a tree row is exactly the old sequence packing, at a ~1% cost.by @AmineDiro in https://github.com/huggingface/trl/pull/7328
Muse Spark Open
Support for
meta-models/Muse-Spark-Open-816B-A42B: the tiny-model script, coverage in the VLM tests (SFT, DPO, KTO, chat-template utils, fused LM head), and a LoRA SFT example on 8 nodes of 8×H100 withDistributedConfig(fsdp_size=64, ep_size=8), token dispatch and packing. Measured at 14.2 s/step, 131k tokens/step, 40.2 GB per GPU.Needs
transformers>=5.20.0; the adapter save additionally needs transformers#49500 with peft 0.21.2.by @qgallouedec in https://github.com/huggingface/trl/pull/7536
AMD GPUs in the async trainers
- Support AMD GPUs in the async GRPO and async distillation trainers by @Abdennacer-Badaoui in https://github.com/huggingface/trl/pull/7689
- Hide the GPU from the async rollout worker on ROCm by @Abdennacer-Badaoui in https://github.com/huggingface/trl/pull/7685
Tool-call arguments typed by the tool's JSON schema
parse_responsenow receives the tools, so tool-call arguments come back typed from the tool's own schema instead of whatever the raw parse pr - v1.15.02026-10-08 · 2026-10-08 19:26 UTC
查看更新说明
Features
⚡ Fused LM head: up to 6.9× longer sequences on the same GPU
SFT, DPO, KTO, GRPO, RLOO and Distillation now score tokens with a fused LM head: a Triton kernel projects the hidden states through the LM head in tiles and reduces to per-token log-probs and entropy directly, so the
[batch, seq, vocab]logits tensor is never built. It is on by default, there is nothing to turn on.Max trainable sequence length (gemma-3-1b, 262k vocabulary, 79 GiB of GPU memory, bf16, batch size 1, gradient checkpointing, sdpa):
Trainer v1.14.2 v1.15.0 DPO 10,240 59,392 5.80× KTO (batch size 2) 9,216 63,488 6.89× GRPO (scoring only) 28,672 114,688 4.00× RLOO (scoring only) 23,552 100,352 4.26× SFT ( loss_type="nll")20,480 107,520 5.25× SFT (default chunked_nll)107,520 107,520 1.00× At 8,192 tokens, peak memory drops 52% to 82% and steps are 2.3% to 10.9% faster:
Trainer Peak GiB v1.14.2 → v1.15.0 Tokens/s DPO 48.97 → 12.00 (-75.5%) 1.035× KTO 64.91 → 11.98 (-81.5%) 1.045× GRPO 24.15 → 10.30 (-57.4%) 1.023× RLOO 29.28 → 14.02 (-52.1%) 1.029× SFT ( nll)30.33 → 8.87 (-70.7%) 1.029× The gain is largest for small models with large vocabularies. SFT's previous default (
chunked_nll) already avoided full logits, so it is unchanged. Scoring needs Triton on a GPU (Linux with CUDA, ROCm or XPU).💥 What this changes for you. The full-logits scoring path, the
use_liger_kernelchunked path and_forward_redirectionare gone from GRPO, RLOO, DPO and KTO:- A PEFT adapter on
lm_headnow raises. Usemodules_to_save=["lm_head"]instead. use_liger_kernel=Trueis deprecated in these four trainers and will be removed in v2.0.0. Liger's layer kernels still apply, butfused_linear_cross_entropyis forced toFalse(it would replace the fused head) and setting it explicitly raises. Usemodel_init_kwargs={"use_kernels": True}.- In DPO and KTO,
compute_metricsandcompute_loss(..., return_outputs=True)still receive the full logits, from an extra forward pass taken only when they are used. Both warn that this is deprecated and will be removed in v2.0.0.
Nothing else the trainers logged is lost: the kernel gained
log_sum_sq_probs(WPO weighting),mean_logits(logits/chosen,logits/rejected) andis_top1(DPO'smean_token_accuracy) as opt-in outputs, each checked against the full logits in tests.1× B300 with the PyTorch allocator capped at 79 GiB (about an H100 80GB's usable memory),
google/gemma-3-1b-ptbuilt from its config with random bf16 weights, lr 1e-6, AdamW, synthetic token ids at exact length. Max length: one fresh process per attempt, 2 training steps, doubling from 8k then bisection to 1024 tokens, arms interleaved round-robin in the same job. Throughput: 12 steps, first 2 discarded, median of 3 A/B/A/B repeats in the same job. Noise floor (A vs A) is 0.1% to 0.8%, below every gap reported. GRPO/RLOO replace generation with fixed random completions, so only scoring is measured.Not measured: H100 hardware itself, flash-attention (sdpa only), real generation, multi-GPU.
- Compute the chunked log-probabilities with a Triton kernel by @qgallouedec in https://github.com/huggingface/trl/pull/7386
- Add an opt-in fused LM head to the patched forward by @qgallouedec in https://github.com/huggingface/trl/pull/7387
- 💥 Score GRPO and RLOO tokens with the fused LM head by @qgallouedec in https://github.com/huggingface/trl/pull/7389
- 💥 Score DPO and KTO tokens with the fused LM head by @qgall
- A PEFT adapter on
- v1.14.22026-10-06 · 2026-10-06 20:30 UTC
查看更新说明
Patch release fixing two cases of silently wrong training and three crashes.
Worth calling out: #7505 affects GRPO, RLOO and Distillation on the default generation path (
use_vllm=False). Models that end a turn with an id only their generation config declares (Gemma 3/4, Phi-3.5, ...) did not stop at the end of the turn, and everything generated after it was trained on, up tomax_completion_length. The only visible sign wascompletions/clipped_ratioclose to 1. With vLLM, generation stopped correctly but the metrics were still wrong, andmask_truncated_completions=Truedropped every finished completion. Runs on models whose tokenizer eos is their only end-of-turn id are unchanged.What's Changed
- Keep the DFT loss finite on a batch with no trainable tokens by @albertvillanova in https://github.com/huggingface/trl/pull/7471
- Fix
precompute_ref_log_probsunder FSDP with no reference model by @qgallouedec in https://github.com/huggingface/trl/pull/7507 - Fix: Start the completion where the tokenized prompt and prompt+completion diverge by @qgallouedec in https://github.com/huggingface/trl/pull/7463
- End completions on every eos id the model declares in GRPO, RLOO and Distillation by @albertvillanova in https://github.com/huggingface/trl/pull/7505
- Guard the requests and urllib3 imports in the vLLM client by @qgallouedec in https://github.com/huggingface/trl/pull/7545
Full Changelog: https://github.com/huggingface/trl/compare/v1.14.1...v1.14.2
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
TRL - Transformers Reinforcement Learning
🎉 What's New
🔥 Mistral Large 4: Fine-tune Mistral Large 4 with SFTTrainer on a single node of 8 B300s, on top of its FP8 weights. See the LoRA example.
🚀 Training on AMD GPUs: TRL's trainers now run on AMD Instinct GPUs through PyTorch's ROCm build.
🔥 Beam: Fine-tune Beam with SFTTrainer on a single node of 8 B300s. See the LoRA example.
🔥 Muse Spark Open: Fine-tune Muse Spark Open with SFTTrainer, sharded across your GPUs at load time. See the 8-node LoRA example.
🚀 Training on AWS Trainium: TRL's trainers now run on AWS Trainium through TorchNeuron, PyTorch's native Neuron backend.
Overview
TRL is a cutting-edge library designed for post-training foundation models using advanced techniques like Supervised Fine-Tuning (SFT), Group Relative Policy Optimization (GRPO), and Direct Preference Optimization (DPO). Built on top of the 🤗 Transformers ecosystem, TRL supports a variety of model architectures and modalities, and can be scaled-up across various hardware setups.
Highlights
-
Trainers: Various fine-tuning methods are easily accessible via trainers like
SFTTrainer,GRPOTrainer,DPOTrainer,KTOTrainerand more. -
Efficient and scalable:
- Leverages 🤗 Accelerate to scale from single GPU to multi-node clusters using methods like DDP and DeepSpeed.
- Full integration with 🤗 PEFT enables training on large models with modest hardware via quantization and LoRA/QLoRA.
- Integrates 🦥 Unsloth for accelerating training using optimized kernels.
-
Command Line Interface (CLI): A simple interface lets you fine-tune with models without needing to write code.
Installation
Python Package
Install the library using pip:
pip install trl
From source
If you want to use the latest features before an official release, you can install TRL from source:
pip install git+https://github.com/huggingface/trl.git
Repository
If you want to use the examples you can clone the repository with the following command:
git clone https://github.com/huggingface/trl.git
Quick Start
For more flexibility and control over training, TRL provides dedicated trainer classes to post-train language models or PEFT adapters on a custom dataset. Each trainer in TRL is a light wrapper around the 🤗 Transformers trainer and natively supports distributed training methods like DDP, DeepSpeed ZeRO, and FSDP.
SFTTrainer
Here is a basic example of how to use the SFTTrainer:
from trl import SFTTrainer
from datasets import load_dataset

dataset = load_dataset("trl-lib/Capybara", split="train")

trainer = SFTTrainer(
    model="Qwen/Qwen2.5-0.5B",
    train_dataset=dataset,
)
trainer.train()
GRPOTrainer
GRPOTrainer implements the Group Relative Policy Optimization (GRPO) algorithm that is more memory-efficient than PPO and was used to train Deepseek AI's R1. accuracy_reward needs math-verify, which you can install with pip install trl[math_verify].
from datasets import load_dataset
from trl import GRPOTrainer
from trl.rewards import accuracy_reward

dataset = load_dataset("trl-lib/DeepMath-103K", split="train")

trainer = GRPOTrainer(
    model="Qwen/Qwen2.5-0.5B-Instruct",
    reward_funcs=accuracy_reward,
    train_dataset=dataset,
)
trainer.train()
[!NOTE] For reasoning models, use the
reasoning_accuracy_reward()function for better results.
DPOTrainer
DPOTrainer implements the popular Direct Preference Optimization (DPO) algorithm that was used to post-train Llama 3 and many other models. Here is a basic example of how to use the DPOTrainer:
from datasets import load_dataset
from trl import DPOTrainer

dataset = load_dataset("trl-lib/ultrafeedback_binarized", split="train")

trainer = DPOTrainer(
    model="Qwen/Qwen3-0.6B",
    train_dataset=dataset,
)
trainer.train()
KTOTrainer
KTOTrainer implements the Kahneman-Tversky Optimization (KTO) algorithm, which aligns models from simple binary (desirable / undesirable) feedback rather than paired preferences. Here is a basic example of how to use the KTOTrainer:
from datasets import load_dataset
from trl import KTOTrainer

dataset = load_dataset("trl-lib/kto-mix-14k", split="train")

trainer = KTOTrainer(
    model="Qwen/Qwen3-0.6B",
    train_dataset=dataset,
)
trainer.train()
RewardTrainer
Here is a basic example of how to use the RewardTrainer:
from trl import RewardTrainer
from datasets import load_dataset

dataset = load_dataset("trl-lib/ultrafeedback_binarized", split="train")

trainer = RewardTrainer(
    model="Qwen/Qwen2.5-0.5B-Instruct",
    train_dataset=dataset,
)
trainer.train()
Command Line Interface (CLI)
You can use the TRL Command Line Interface (CLI) to quickly get started with post-training methods like Supervised Fine-Tuning (SFT) or Direct Preference Optimization (DPO):
SFT:
trl sft --model_name_or_path Qwen/Qwen2.5-0.5B \
    --dataset_name trl-lib/Capybara \
    --output_dir Qwen2.5-0.5B-SFT
DPO:
trl dpo --model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
    --dataset_name argilla/Capybara-Preferences \
    --output_dir Qwen2.5-0.5B-DPO
KTO:
trl kto --model_name_or_path Qwen/Qwen2.5-0.5B-Instruct \
    --dataset_name trl-lib/kto-mix-14k \
    --output_dir Qwen2.5-0.5B-KTO
Read more about CLI in the relevant documentation section or use --help for more details.
Development
If you want to contribute to trl or customize it to your needs make sure to read the contribution guide and make sure you make a dev install:
git clone https://github.com/huggingface/trl.git
cd trl/
pip install -e .[dev]
Experimental
A minimal incubation area is available under trl.experimental for unstable / fast-evolving features. Anything there may change or be removed in any release without notice.
Example:
from trl.experimental.new_trainer import NewTrainer
Read more in the Experimental docs.
Citation
@software{vonwerra2020trl,
  title   = {{TRL: Transformers Reinforcement Learning}},
  author  = {von Werra, Leandro and Belkada, Younes and Tunstall, Lewis and Beeching, Edward and Thrush, Tristan and Lambert, Nathan and Huang, Shengyi and Rasul, Kashif and Gallouédec, Quentin},
  license = {Apache-2.0},
  url     = {https://github.com/huggingface/trl},
  year    = {2020}
}
License
This repository's source code is available under the Apache-2.0 License.
verl
verl-project·Python
面向大模型后训练的强化学习框架,用混合编程模型把 RLHF 训练流程编排得灵活又高效,方便扩展和跑大规模实验。
强化学习+4后训练 / RLHF
24182+194.9kv0.9.12026-11-10 06:37 UTC
OpenRLHF
OpenRLHF·Python
基于 Ray 的高性能 RLHF 训练框架,支持 PPO、DAPO、REINFORCE++ 等算法与 vLLM 推理加速,可扩展地完成大模型和视觉语言模型的对齐后训练。
RLHF+4后训练 / RLHF
10147+11.1kv0.11.22026-11-03 03:17 UTC
PaLM-rlhf-pytorch
lucidrains·Python
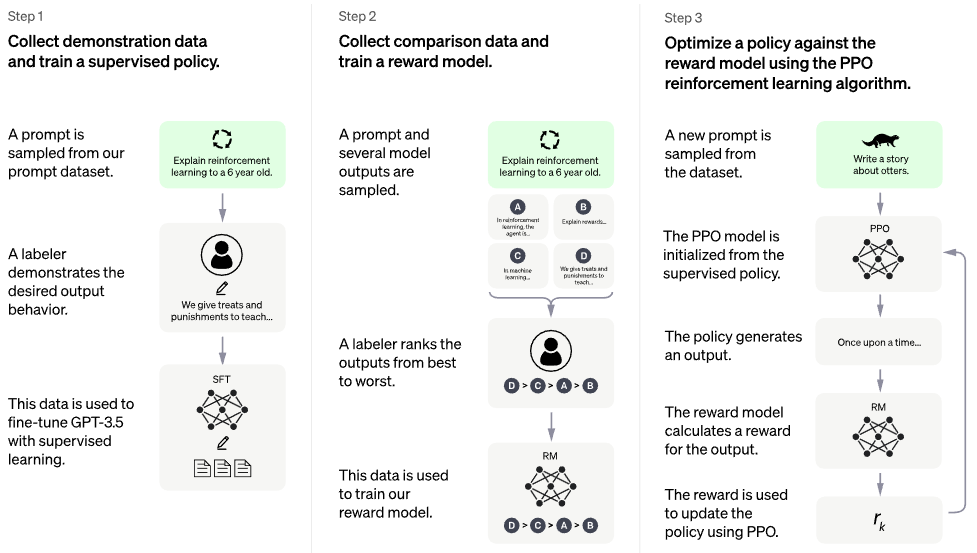
在 PaLM 架构上实现 RLHF 人类反馈强化学习,复现 ChatGPT 式训练流程,适合研究大模型对齐与强化学习微调。
RLHF+4后训练 / RLHF
78636660.7.12026-09-20 15:27 UTC
MedicalGPT
shibing624·Python
用 ChatGPT 同款流程训练医疗大模型,覆盖增量预训练、有监督微调、RLHF、DPO、ORPO、GRPO 全链路,开箱即可复现。
医疗大模型+4后训练 / RLHF
5890+28042.7.02026-09-15 13:46 UTC