recipe 目录已迁到独立仓库 verl-recipe 并作为 submodule,需先执行 git submodule update --init --recursive recipe;各 recipe 子目录的 REQUIRED_VERL.txt 指定了配套 verl 版本(tag 或固定 SHA),版本不匹配容易跑不通;experimental 下的 transfer_queue、fully_async_policy 等模块需通过 verl.experimental.{module} 引用。
pip install verl@git+<repo>@<sha>(具体安装步骤见官方 Installation 文档) 硬件要求按 README 说明
README 未说明具体显存要求;社区博客提到可在 4 张 AMD Instinct GPU 上跑完全异步 DAPO 训练,也有在 64 张 H800 上训练万亿参数模型 GRPO LoRA 的案例。
支持 ROCm / AMD昇腾 / Ascend多卡 / 张量并行
字节 Seed 开源的大模型强化学习后训练框架,用混合控制器编排 PPO/GRPO 等 RL 数据流
面向大模型后训练的强化学习框架,用混合编程模型把 RLHF 训练流程编排得灵活又高效,方便扩展和跑大规模实验。
核心能力
- 用混合控制器编程模型,几行代码搭出 GRPO、PPO 数据流
- 模块化 API 解耦计算与数据依赖,可接 FSDP、Megatron-LM、vLLM、SGLang
- 支持灵活设备映射,把模型放到不同 GPU 集合上以提升资源利用率
- 用 3D-HybridEngine 做 actor 模型重分片,降低训练与生成切换的通信开销
- 可直接对接 HuggingFace 上的主流模型
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.9.1最新正式版2026-09-20 · 2026-09-20 07:24 UTC
Highlights
Trainer
Unified V1 trainer
separate_asynccan now lend idle trainer GPUs to generation: once a step's prompts are submitted, the trainer keeps its replicas in rollout mode until the replay buffer holds enough sampleable groups, driven by an adaptive starvation threshold. Gated behindtrainer.v1.separate_async.enable_switch, off by default (#7373).- V0-style fully-async semantics for the V1 async trainers (#7884):
actor_rollout_ref.hybrid_engine=Falseunderseparate_async(rollout served exclusively by the standalone pool), fractionalnum_warmup_batches(e.g.1.5),max_off_policy_threshold=nullto disable off-policy version control entirely, and the V0-compatible__num_turns__metric. All knobs are opt-in and default to the previous behavior. - Dynamic micro-batch packing now enforces
max_token_lenstrictly instead of treatingceil(total_len / max_token_len)as the micro-batch count — a bound the Karmarkar-Karp split could legitimately exceed (#7553). - DAPO group filtering reads the canonical pre-KL reward from
rm_scoresandalgorithm.filter_groups.metricdefaults toreward, so dynamic sampling only needsalgorithm.filter_groups.enable=True(#7792). trainer.checkpoint_callback_classnames a user-definedCheckpointCallbackwhoseon_savehook fires after every checkpoint save, mirroring the HuggingFaceTrainerCallbackevent — an extension point for uploads, model registries and retention policies without forking the trainer (#7513).- Async correctness: skip V1 async warmup after an inflight reissue (#7762), count failed validation sessions in accuracy (#7781), reject requests arriving behind a closed gate instead of parking them (#7912), and keep synthetic padding safe under context parallelism (#7593).
verl/experimental/fully_async_policyandverl/experimental/one_step_off_policyare deprecated by V1 trainer and will be moved to verl-recipe in next release.
FSDP
- Liger Kernel v0.8.2's
LigerFusedLinearScaledCrossEntropyFunctionreplaces the experimental fused linear PPO output head when Liger is installed: 13.5% faster actor updates (0.02803 → 0.02424 ms/token, four H100 seeds) and 5.6% lower actor peak memory (35.68 → 33.70 GiB). Without Liger the existing chunked implementation is unchanged (#7461). - Non-blocking FSDP2 model transfers (#7347), configurable deferred gradient sync (#7458), and a fix for the model merger concatenating replicated buffers (#7610).
- New
fsdpturbobackend engine (#7362), with its e2e test moved from GPU to NPU (#7633). - Qwen3.5-2B on-policy distillation script (#7605) and an updated Qwen3.5-35B GRPO example at 2K prompt / 6K response (#7678).
Megatron
- Qwen3.5 GRPO training script for the MindSpeed-Bridge and Megatron backends (#7335).
- VLM THD input padded to TP/CP alignment before the SP scatter (#7702), plus the NPU TND attention-mask shape fix (#7372).
- R2 router replay is now model-scoped and opt-in (#7805); the earlier THD-packed variant (#7106) was reverted in #7786.
- DDP gradient dtype aligned with optimizer precision (#7485) and sequence-mean loss allowed together with per-token normalization (#7915).
- The
mindspeedllmbackend engine was removed (#7374) and the Megatron Lite doc reframed as a Megatron Agent Compose preview (#7537).
VeOmni
- DeepSeek-V4 QAT bf16 fake-quant training (#7577) and gpt-oss expert parallelism (#7397).
async_activation_offloadconfig (#7724) androuted_expertsstored astorch.int16to cut its memory footprint (#7407).
Rollout
vLLM
- Pluggable router: the load balancer moves out of
llm_server.pyintoverl/workers/rollout/router.pybehind aRequestLoadBalancerprotocol and aget_router_handle()factory.rollout.router_config_pathloads an external router plugin from YAML byrouter_classFQN with Hydradefaultscomposition andpkg://URIs; with no config the built-in sticky-session
- v0.9.02026-08-14 · 2026-08-14 07:55 UTC
查看更新说明
v0.9.0
Highlights
Training
Megatron
- DeepSeek-V4 GRPO end-to-end with Megatron-Bridge actor/ref, vLLM rollout and FP8/MXFP4 weight transfer (#6473), plus a contiguous context-parallel layout (#7221) and CP fixes that make long-context DeepSeek-V4 runnable (#7297).
- Megatron Lite (
mlite) backend for DeepSeek-V4, GLM-5 and Kimi-K2.5/K2.6, with 256-GPU GRPO launchers (#6791, #7091). - Muon optimizer support via Megatron-Core
TensorParallelMuon, with AdamW fallback for non-2D params and an opt-inmuon_match_adamw_update_rmsscale (#7120). - Dynamic context parallel scheduling: each packed micro-batch picks a smaller local CP group when sequences don't need the full CP size (#6555).
- Megatron chunk entropy (#6446) and fused logprob/entropy migrated from a
GPTModel.forwardmonkey-patch to the Megatronoutput_processorhook (#6933). - Packed-sequence throughput work: BSHD micro-batches padded to the mini-batch max seq_len (#6901) and bucketed packed sequence lengths (#7358).
- Checkpoint manager rewrite with YAML checkpoint config APIs (#6014); optimizer states and DDP grad buckets aligned with model precision (#6526).
VeOmni
- DeepSeek-V4 support (#7242) and GPT-OSS weight preservation without expert parallelism (#7243).
- Weight-refit extra memory reduced from
O(E)toO(E/ep_size)by replacing the expertall_gatherwith sequential intra-EP broadcasts (#6612). pad_to_lengthbucketing for packed micro-batches, collapsing dynamic shapes so torch.compile / Triton / DeepGEMM autotune cost is paid once instead of every step (#7272).- EP-aware sharded delta export for fused expert stacks (#7085), DSD optimizer checkpoint state backfill (#7283), and the missing config surface in
veomni.yaml(#6505).
FSDP
- Per-unit LoRA summon with FSDP1/FSDP2 compatibility and strip-modules support (#6512);
save_lora_onlycheckpoints (#7061). - Chunked gather-logsumexp for top-K distillation loss to avoid OOM at long context (#6593) and deferred gradient sync during accumulation (#7095).
- FSDP2 weight export skips the whole-shard staging round trip (#7005).
Rollout
vLLM
- Prefill-Decode disaggregated rollout (
rollout.name=vllm_pd) routing GRPO rollouts across 1 prefill + N decode engines over NIXL or Mooncake (#6243). - Full determinism for vLLM rollout and reward-model inference, so two identical runs produce bitwise-aligned reward curves (#6572).
- DeepSeek-V4 FP8/MXFP4 linear and MoE weight refit fixes, with the quantized weight-sync paths split per scheme (#7224).
- Weight-sync restructuring (#7179), non-contiguous weight handling in bucketed transfer (#6919), and MTP drafter weights preserved across hybrid sleep (#6661).
SGLang
- ROCm backend support out of the box via AITER attention/kernel defaults injected through the platform layer (#6664).
- FP8 ignored-layer support for Qwen3.x GatedDeltaNet (#6906, #6915).
- LoRA correctness: SGLang stays LoRA-free when
model.lora.merge=True(#7234); NCCL buffer race guard in_compact_for_bucket(#7139).
CheckpointEngine
- New
delta_shardedcheckpoint engine for disaggregated async training: each actor rank byte-diffs its own shard against a pinned shard-sized CPU snapshot, sparsely gathers only the changed(position, value)pairs, and the rollout side applies them in place through the stock custom-weight-loader hook — no rank ever holds a full-model snapshot (#6974). - Measured steady-state
update_weightsspeedups vs full NCCL broadcast (H100, GSM8K GRPO, V1separate_async, SGLang rollout): 2.4x at Qwen2.5-7B, 1.9x at 32B, 3.1x at 72B. - Generalized beyond flat
Shard(0): block placements (Shard(k), multi-Shard meshes, manual splits) plus a backend-owned HF export contract (#7144), VeOmni FSDP2+EP (#7085), Megatron-Bridge param mappings covering TP+EP and hybrid-Mamba (#7181), an
- v0.8.02026-06-01 · 2026-06-01 11:24 UTC
查看更新说明
Highlights
Training
Megatron
- Megatron-FSDP mode for the Megatron backend (#5423).
- Dynamic context parallel (#5057) and CP for BSHD format (#5826).
- Checkpoint save as HF PEFT format (#5575).
- Qwen3.5 MTP SFT/RL (#5898)
- NVFP4 (W4A16) QAT training via ModelOpt (#5254) with QAT documentation (#5861).
VeOmni
- VeOmni engine for on-policy distillation (#6072) with native critic support (#6453) and native
return_log_probspath (#6184). - MoE router replay (R2/R3) support (#6325) and MoE load-balance monitoring (#6470).
- Qwen3.5 SP, GRPO demos for Qwen3-VL-30B-MOE / Qwen3.5-122b-a10b / Qwen3.5-30b (#6061, #5275, #6264, #6323).
Hardware / NPU
- NPU support for Liger-Kernel (#6244).
- Expandable segments (#5795, #6346).
- MXFP8 rollout on Ascend 950 (#5756).
Rollout
vLLM
- Split large weights into chunks in NCCL/NIXL checkpoint engine (#6091).
- MooncakeStoreConnector with hard-reset on weight update (#6373).
- Upgrade stable version to vllm==0.20.2 (#6393).
SGLang
- LoRA support for SGLang rollouts (merge + native adapter paths) (#5564).
- SGLang Prefill-Decode disaggregated rollout (#6117).
- Upgrade stable version to sglang==0.5.12 (#6435).
TensorRT-LLM
- Async RL for TRT-LLM rollout, including inter-node support (#5631, #5992).
On-Policy Distillation (OPD)
- End-to-end on-policy distillation support across FSDP, Megatron and VeOmni backends (#5041).
- Text and multimodal, single/multiple teachers (#6051), sync (#5997) and fully-async (#6056) trainers.
- Reverse KL loss and forward top-k KL loss, with a fused top-K distillation kernel (#6511) and overlap metrics (#6469).
- Docs: https://verl.readthedocs.io/en/latest/algo/opd.html
Trainer
Sync Trainer
- New sync trainer with TransferQueue to decouple control flow and data flow in the single controller (#5401).
- Up to 2x speedup in multimodal training with 128 GPUs, see TransferQueue blog post.
- Support multiple trajectories output for each agent loop.
- TBD: Fully async trainer with TransferQueue will be in next release.
Fully Async Trainer
- Reuse trainer worker group for hybrid rollout during validation (#6076).
- Online policy distillation in fully async training (#6056).
- Qwen3-VL-30B-A3B and Qwen3-VL-8B fully async GRPO training scripts (#6131, #6006).
Agentic RL Training
- New project verl-project/uni-agent for building, running, and training general agents at scale.
- Support coding, search, GUI agent RL training.
Tools & Reward
- Simpler function-based tool registration (#6189) with per-sample tool environment routing (#5978) and Gemma4 tool parser (#6406).
- Multi-step support in skip_rollout v2 (#5556) and improved error messages for malformed tool calls (#6055).
Breaking Changes
- Deprecate legacy FSDP and Megatron workers, migrate to the unified engine abstraction (#5604, #6067).
- Deprecate
verl/interactions(#6074). - Move
LLMServerManagerout ofAgentLoopManager(#6129). - Migrate Diffusion RL stack to
verl-omni(#6200) andexperimental/vlato a standaloneverl-vlarepository (#6162). - Remove curriculum sampler + dynamic dataset + tool examples (#6302).
main_ppo.pyis deprecated with a warning in favor ofmain_ppo_sync.py(#6384).
What's Changed
- [ci] feat: add profiling tests to vLLM ci by @Gary-cjy in https://github.com/verl-project/verl/pull/5215
- [config] fix: sync chat_template from tokenizer to processor for multimodal base models (e.g. Qwen3.5) by @khazic in https://github.com/verl-project/verl/pull/5612
- [rollout] fix: DP > 1 hang with vllm rollout when training dense or MoE(EP=1) model by @NascentAscension in https://github.com/verl-project/verl/pull/5609
- [
- v0.7.12026-03-16 · 2026-03-16 03:18 UTC
查看更新说明
Highlight
Model Engine
Megatron
- Support R3 router replay with vllm and sglang https://github.com/verl-project/verl/pull/4840 https://github.com/verl-project/verl/pull/4986 https://github.com/verl-project/verl/pull/5185
- Support MTP training in SFT/RL https://github.com/verl-project/verl/pull/4981 https://github.com/verl-project/verl/pull/4936
- LoRA training enhancement with megatron-bridge: actor/ref share, LoRA adapter only refit, etc https://github.com/verl-project/verl/pull/4673 https://github.com/verl-project/verl/pull/4632
- Support Qwen3.5 series training with mbridge https://github.com/verl-project/verl/pull/5381
VeOmni
- New veomni training backend with FSDP+SP+EP https://github.com/verl-project/verl/pull/4882
torchtitan
- New torchtitan training backend with FSDP+TP+PP+CP+EP, roadmap: https://github.com/verl-project/verl/issues/5306
Rollout Engine
vLLM
- Separate model runner from training process and refit weights by cuda ipc https://github.com/verl-project/verl/pull/4280
- FP8 rollout enhancement
- Upgrade to vllm==0.17.0
SGLang
- Support router replay
- FP8 rollout enhancement
- Upgrade to sglang==0.5.9
TensorRT-LLM
- New tensorrt-llm rollout backend, roadmap: https://github.com/verl-project/verl/issues/5042
Checkpoint Engine
- Add checkpoint engine manager https://github.com/verl-project/verl/pull/5031
- Add hccl, kimi checkpoint engine backend https://github.com/verl-project/verl/pull/4885 https://github.com/verl-project/verl/pull/4954
Trainer
- one-step-off/fully async trainer refactor with verl-core
- Unify checkpoint engine https://github.com/verl-project/verl/pull/5029
- Unify partial rollout agent loop with auto resume https://github.com/verl-project/verl/pull/5487
- Ascend NPU support for one-step-off/fully async
What's Changed
- [ci] feat: add npu unit test by @yyyy2000 in https://github.com/verl-project/verl/pull/4626
- [recipe] fix: workaround for making the one-step off-policy recipe compatible with IPv6 environments on Ascend NPU by @ji-huazhong in https://github.com/verl-project/verl/pull/4782
- [fsdp] feat: integrate PrefixGrouper for GRPO training acceleration by @kevssim in https://github.com/verl-project/verl/pull/4368
- [rollout] fix: use model_dump() for proper Pydantic serialization in token2text by @yurekami in https://github.com/verl-project/verl/pull/4706
- [doc] chore: Change the name of npu unit test workflow by @yyyy2000 in https://github.com/verl-project/verl/pull/4800
- [model] feat: support per sample temperature in trainer by @vermouth1992 in https://github.com/verl-project/verl/pull/4787
- [tool] fix: add tools in single_turn_agent by @Junxiao-Zhao in https://github.com/verl-project/verl/pull/4798
- [recipe] feat: migrate
recipeto the dedicated repoverl-recipeas a submodule by @tongyx361 in https://github.com/verl-project/verl/pull/4795 - [model] fix: fix temp dtype by @vermouth1992 in https://github.com/verl-project/verl/pull/4813
- [vllm, sglang, rollout] fix: Fix a mistake when running run_qwen3_vl-30b-megatron.sh with latest verl and vllm0.12 by @cboss6 in https://github.com/verl-project/verl/pull/4810
- [ckpt] feat: add checkpoint-engine abstraction by @wuxibin89 in https://github.com/verl-project/verl/pull/4775
- [doc, ci] fix: Update Ascend doc and fix e2e_ascend CI by @FightingZhen in https://github.com/verl-project/verl/pull/4816
- [trainer] feat: VeOmniEngine supports qwen3_vl ulysses by @A1waysBeenHere in https://github.com/verl-project/verl/pull/4806
- [doc] chore: fix checkpoint engine image link by @wuxibin89 in https://github.com/verl-project/verl/pull/4821
- [hardware] fix: automatically set device for SFT case by @A1waysBeenHere in https://github.com/verl-project/verl/pull/4828
- [data] feat: TransferQueue - Update TransferQueue version and docs by @0oshowero0 in https://github.com/verl-project/verl/pull/4829
- [doc] Update docs
- v0.7.02026-01-05 · 2026-01-05 10:17 UTC
查看更新说明
v0.7 release
Blog post: verl 0.7 release blog
Highlight
Model Engine
- Integrate Megatron-Bridge and support LoRA/PEFT, see blog post: How We Build Trillion Parameter Reasoning RL with 10% GPUs
- Support experimental fp8 training for megatron backend
- Support new model for megatron backend: GPT-OSS, Qwen3-Next
- Comprehensive support for new mode engine, FSDP and Megatron engine are production ready.
- Dispatch tensordict with nested tensor instead of padded DataProto
- Add TrainingWorker that resembles Tinker-like API
- Add VLM support for model engine, SFT and RL trainer
- Add model engine based critic model
- Implement ActorRolloutRefWorker by TrainingWorker, support different backend in one worker
- New VeOmni engine added, still in alpha status.
Rollout Engine
- Remove SPMD rollout mode
- Support blockwise fp8 rollout for vllm and sglang; support online quant for vllm with torchao
- Experimental router replay support for vllm
- Optimize multi-modal data fetch and preprocess, support video input
- Upgrade to vllm==0.12.0; sglang==0.5.6
Reward
- Support hybrid reward scenarios, including generative, discriminative, rule-based rewards, and their combinations.
- Refactor reward models into server mode, supporting both colocated and standalone deployments.
- Introduce new reward managers to handle more complex scenarios, limited mode for request rate control and remote mode for CPU-intensive tasks.
Algorithm
Recipe
- [NEW] VLA: add experimental support for VLA model
- [NEW] rhymerl: History Rhymes: Accelerating LLM Reinforcement Learning with RhymeRL
- TransferQueue: support multiple data partition and optimize tensor zero-copy serialization
- One-step-off-policy/Fully async: optimize weight synchronization by checkpoint engine with bucket and pipeline support.
What's Changed
- [data] fix: MultiturnSFTDataset handle messages with list args in tool call by @gongyisheng in https://github.com/volcengine/verl/pull/4125
- [ci, doc] feat: Update Ascend Dockerfile and docker build workflow to 8.3.RC1 version by @FightingZhen in https://github.com/volcengine/verl/pull/4123
- [data] fix: fix global_seqlen metric by @conver334 in https://github.com/volcengine/verl/pull/4129
- [ci] fix: Optimize ascend docker build workflow and dockerfile to solve OOM problem by @FightingZhen in https://github.com/volcengine/verl/pull/4137
- [ci] fix: fix error limiting MindSpeed cloning depth to one by @FightingZhen in https://github.com/volcengine/verl/pull/4140
- [ci] feat: specify torch and torch_npu version into ascend dockerfile by @FightingZhen in https://github.com/volcengine/verl/pull/4141
- [ci] fix: move torch and torch_npu install order in ascend dockerfile to ensure installed version correct by @FightingZhen in https://github.com/volcengine/verl/pull/4142
- [ci] fix: Correct version relationship between torch and torchvision in ascend dockerfile by @FightingZhen in https://github.com/volcengine/verl/pull/4143
- [doc] chore: Add one_step_off_policy support doc of Ascend NPU by @baymax591 in https://github.com/volcengine/verl/pull/4151
- [rollout] fix: resource pool name in standalone mode by @PeterSH6 in https://github.com/volcengine/verl/pull/4149
- [ci] feat: Update e2e_ascend CI image to 8.3.RC1 version, remove weekly validation workflow by @FightingZhen in https://github.com/volcengine/verl/pull/4146
- [doc] chore: add pytorch conference materials by @hongpeng-guo in https://github.com/volcengine/verl/pull/4161
- [rollout] fixup load_format=dummy update_weights not do process_weight… by @Anna
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。


verl is a flexible, efficient and production-ready RL training library for large language models (LLMs).
verl is the open-source version of HybridFlow: A Flexible and Efficient RLHF Framework paper.
verl is flexible and easy to use with:
-
Easy extension of diverse RL algorithms: The hybrid-controller programming model enables flexible representation and efficient execution of complex post-training dataflows. Build RL dataflows such as GRPO, PPO in a few lines of code.
-
Seamless integration of existing LLM infra with modular APIs: Decouples computation and data dependencies, enabling seamless integration with existing LLM frameworks, such as FSDP, Megatron-LM, vLLM, SGLang, etc
-
Flexible device mapping: Supports various placement of models onto different sets of GPUs for efficient resource utilization and scalability across different cluster sizes.
-
Ready integration with popular HuggingFace models
verl is fast with:
-
State-of-the-art throughput: SOTA LLM training and inference engine integrations and SOTA RL throughput.
-
Efficient actor model resharding with 3D-HybridEngine: Eliminates memory redundancy and significantly reduces communication overhead during transitions between training and generation phases.
News
- [2026/08] verl-vla
v0.1.0is released: a unified VLA post-training framework for human-in-the-loop data collection, supervised fine-tuning, and reinforcement learning across simulators, real robots, and distributed cloud-edge resources, built on top of verl. - [2026/08] VeRL-Tinker is released: keep the Tinker Cookbook loop you know, and run SFT, RL, and distillation on verl-managed GPU workers you control; read the blog here.
- [2026/08] VeRL-Omni
v0.2.0is released: faster diffusion RL, rebuilt Qwen3-Omni multimodal training (DPO & GSPO), plus LTX-2.3, Qwen-Image-Edit support and more. - [2026/07] RL-Insight is released: online observability for reinforcement learning training. RL-Insight connects training-side metrics, RL state traces, and service dashboards across distributed rollout and optimization workloads.
- [2026/06] verl-SpeCo is pre-released: a co-training framework for speculative decoding across RL training and inference, keeping draft models aligned during training and reusable for accelerated serving, built on top of verl.
- [2026/05] uni-agent is released: a unified agent framework to build, run, and train LLM agents at scale, built on top of verl.
- [2026/05] VeRL-Omni is pre-released: a unified RL stack for diffusion and omni-modal model post-training built on top of verl. Read the blog post for details.
- [2026/05] verl's zero-mismatch HuggingFace rollout vexact is released: with batch-invariant kernels, shared model definition with FSDP, and out-of-box examples compatible with VeOmni.
- [2026/04] verl's Megatron backend LoRA and router replay support is showcased at PyTorch Conference Europe 2026.
- [2026/03] verl is presented at NVIDIA GTC26: session#1, session#2
- [2026/01] verl has been migrated to the verl-project
- [2026/01] verl first meetup was successfully held in Shanghai on 01/10, hosted by Volcengine and NVIDIA, the slides has been uploaded to verl-data.
- [2026/01] The
recipedirectory has been migrated to a dedicated repository: verl-recipe and added as a submodule. See https://github.com/verl-project/verl/pull/4795. It can be used as it was aftergit submodule update --init --recursive recipe. Note thattransfer_queue,fully_async_policy,one_step_off_policyandvlaare kept underverl/experimentalsince they are planned to be merged into the main library. Use them throughverl.experimental.{module}. - [2025/12] Mind Lab successfully used verl and Megatron-bridge to train GRPO Lora for Trillion-parameter model on 64 H800 - See their techblog.
- [2025/10] verl is presented in the PyTorch Conference 2025.
- [2025/08] verl is presented in the PyTorch Expert Exchange Webinar. Slides available.
- [2025/07] The ReTool recipe is fully open sourced. Blog
- [2025/07] The first verl meetup will be held at ICML Vancouver on July 16th! Please join us if you are at ICML! (onsite only)
- [2025/06] verl with Megatron backend enables large MoE models such as DeepSeek-671B and Qwen3-235B.
- [2025/03] DAPO is the open-sourced SOTA RL algorithm that achieves 50 points on AIME 2024 based on the Qwen2.5-32B pre-trained model, surpassing the previous SOTA achieved by DeepSeek's GRPO (DeepSeek-R1-Zero-Qwen-32B). DAPO's training is fully powered by verl and the reproduction code is available in
recipe/daponow.
Key Features
- FSDP, FSDP2 and Megatron-LM for training.
- vLLM, SGLang and HF Transformers for rollout generation.
- Compatible with Hugging Face Transformers and Modelscope Hub: Qwen3.5, Qwen3, Qwen-2.5, Llama3.1, Gemma2, DeepSeek-LLM, etc
- Supervised fine-tuning.
- Reinforcement learning with PPO, GRPO, GSPO, ReMax, REINFORCE++, RLOO, PRIME, DAPO, DrGRPO, KL_Cov & Clip_Cov etc.
- Support model-based reward and function-based reward (verifiable reward) for math, coding, etc
- Support vision-language models (VLMs) and multi-modal RL with Qwen2.5-vl, Kimi-VL
- Multi-turn with tool calling
- LLM alignment recipes such as Self-play preference optimization (SPPO)
- Flash attention 2, sequence packing, sequence parallelism via DeepSpeed Ulysses, LoRA, Liger-kernel (
USE_LIGER=1). - Scales up to 671B models and hundreds of GPUs with expert parallelism
- Multi-gpu LoRA RL support to save memory.
- Experiment tracking with wandb, swanlab, mlflow and tensorboard.
- Hardware Support: Supports NVIDIA, AMD, Huawei Ascend
Getting Started
Documentation
Quickstart:
- Installation
- Quickstart
- Programming Guide & Tech Talk (in Chinese)
- PPO in verl
- GRPO in verl
Running a PPO example step-by-step:
- Prepare Data for Post-Training
- Implement Reward Function for Dataset
- PPO Example Architecture
- Config Explanation
Reproducible algorithm baselines:
Algorithm recipes (recipe/):
- Optional workflows and baselines live under
recipe/. Each recipe subdirectory includes a smallREQUIRED_VERL.txtfile describing the intendedverlinstall: pinned recipes use a tag or fixed git SHA; rolling recipes record an explicitVERL_COMMIT(and related submodule / recipe-folder SHAs) so you canpip install verl@git+…@<sha>without guessing. Seerecipe/README.mdfor the full index and links.
For code explanation and advance usage (extension):
-
PPO Trainer and Workers
-
Advanced Usage and Extension
Blogs from the community
- Hands-on: Launch verl Fully Async DAPO Training on 4 AMD Instinct GPUs with AMD Developer Cloud
- When Reasoning Models Break Tokenization: The Hidden Complexity of Multiturn Training
- verl deployment on AWS SageMaker
- verl x SGLang Multi-turn Code Walkthrough
- Optimizing SGLang Memory Usage in verl
- SGLang, verl, OpenBMB and Tsinghua University: Pioneering End-to-End Multi-Turn RLHF
- Reinforcement Learning from Human Feedback on AMD GPUs with verl and ROCm Integration
- veMLP x verl :玩转强化学习训练
- 使用 verl 进行 GRPO 分布式强化学习训练最佳实践
- HybridFlow verl 原文浅析
- 最高提升 20 倍吞吐量!豆包大模型团队发布全新 RLHF 框架,现已开源!
Performance Tuning Guide
The performance is essential for on-policy RL algorithm. We have written a detailed performance tuning guide to help you optimize performance.
Upgrade to vLLM >= v0.8.2
verl now supports vLLM>=0.8.2 when using FSDP as the training backend. Please refer to this document for the installation guide and more information. Please avoid vllm 0.7.x, which contains bugs that may lead to OOMs and unexpected errors.
Use Latest SGLang
SGLang is fully supported with verl, and SGLang RL Group is working extensively on building unique features, including multi-turn agentic RL, VLM RLHF, server-based RL, and partial rollout. Please refer to this document for the installation guide and more information.
Upgrade to FSDP2
verl is fully embracing FSDP2! FSDP2 is recommended by torch distributed team, providing better throughput and memory usage, and is composible with other features (e.g. torch.compile). To enable FSDP2, simply use verl main and set the following options:
actor_rollout_ref.ref.strategy=fsdp2
actor_rollout_ref.actor.strategy=fsdp2
critic.strategy=fsdp2
Furthermore, FSDP2 cpu offloading is compatible with gradient accumulation. You can turn it on to save memory with actor_rollout_ref.actor.fsdp_config.offload_policy=True. For more details, see https://github.com/verl-project/verl/pull/1026
AMD Support (ROCm Kernel)
verl runs on AMD ROCm GPUs (MI300X / MI325X / MI355X) with FSDP, FSDP2, and Megatron trainer backends, and vLLM as the validated inference engine (SGLang support is in progress). See the AMD ROCm quick-start guide for container bring-up, environment verification, and training examples.
Citation and acknowledgement
If you find the project helpful, please cite:
- HybridFlow: A Flexible and Efficient RLHF Framework
- A Framework for Training Large Language Models for Code Generation via Proximal Policy Optimization
@article{sheng2024hybridflow,
  title   = {HybridFlow: A Flexible and Efficient RLHF Framework},
  author  = {Guangming Sheng and Chi Zhang and Zilingfeng Ye and Xibin Wu and Wang Zhang and Ru Zhang and Yanghua Peng and Haibin Lin and Chuan Wu},
  year    = {2024},
  journal = {arXiv preprint arXiv: 2409.19256}
}
verl is inspired by the design of Nemo-Aligner, Deepspeed-chat and OpenRLHF. The project is adopted and contributed by Bytedance, Anyscale, LMSys.org, Alibaba Qwen team, Shanghai AI Lab, Tsinghua University, UC Berkeley, UCLA, UIUC, University of Hong Kong, ke.com, All Hands AI, ModelBest, JD AI Lab, Microsoft Research, StepFun, Amazon, LinkedIn, Meituan, Camel-AI, OpenManus, Xiaomi, NVIDIA research, Baichuan, RedNote, SwissAI, Moonshot AI (Kimi), Baidu, Snowflake, Skywork.ai, JetBrains, IceSword Lab, and many more.
Awesome Projects Built with verl
Welcome to register your awesome project build with verl for other developers' reference!
- TinyZero: a reproduction of DeepSeek R1 Zero recipe for reasoning tasks
- SkyThought: RL training for Sky-T1-7B by NovaSky AI team.
- simpleRL-reason: SimpleRL-Zoo: Investigating and Taming Zero Reinforcement Learning for Open Base Models in the Wild
- Easy-R1: Multi-modal RL training framework
- RandOpt: Neural Thickets: Diverse Task Experts Are Dense Around Pretrained Weights
- OpenManus-RL: LLM Agents RL tuning framework for multiple agent environments.
- rllm: async RL training with verl-pipeline
- RAGEN: a general-purpose reasoning agent training framework
- Search-R1: RL with reasoning and searching (tool-call) interleaved LLMs
- ReSearch: Learning to Reason with Search for LLMs via Reinforcement Learning
- Skywork-OR1: Skywork open reaonser series
- ToRL: Scaling tool-integrated RL
- Absolute Zero Reasoner: A no human curated data self-play framework for reasoning
- verl-agent: A scalable training framework for long-horizon LLM/VLM agents, along with a new algorithm GiGPO
- RL-Factory: An easy and efficient RL post-training framework for Agentic Learning
- ReTool: ReTool: reinforcement learning for strategic tool use in LLMs. Code release is in progress...
- verl-tool: An unified and easy-to-extend tool-agent training framework based on verl
- PRIME: Process reinforcement through implicit rewards
- MemAgent: MemAgent: Reshaping Long-Context LLM with Multi-Conv RL based Memory Agent
- POLARIS: A Post-training recipe for scaling RL on Advanced Reasoning models
- GUI-R1: GUI-R1: A Generalist R1-style Vision-Language Action Model For GUI Agents
- DeepRetrieval: RL Training of Search Agent with Search/Retrieval Outcome
- Code-R1: Reproducing R1 for Code with Reliable Rewards
- DeepResearcher: Scaling deep research via reinforcement learning in real-world environments
- VAGEN: Training VLM agents with multi-turn reinforcement learning
- RM-R1: RL training of reasoning reward models
- Dr. MAS: Stable end-to-end RL post-training for multi-agent LLM systems
- LUFFY: Learning to Reason under Off-Policy Guidance
- DeepMath: DeepMath-103K data and series models for math reasoning
- PACS: Implicit Actor Critic Coupling via a Supervised Learning Framework for RLVR
- Entropy Mechanism of RL: The Entropy Mechanism of Reinforcement Learning for Large Language Model Reasoning
- LLaSA-TTS-GRPO: TTS fine-tuning with GRPO optimization based on LLASA models
- PF-PPO: Policy Filtration for PPO based on the reliability of reward signals for more efficient and robust RLHF.
- RACRO: Build multi-modal reasoning models via decoupling it into query-conditioned captioning and text-only reasoning
- Agent Lightning: A flexible and extensible framework that enables seamless agent optimization for any existing agent framework.
- VTool-R1: VLMs Learn to Think with Images via Reinforcement Learning on Multimodal Tool Use.
- Kimina-Prover-RL: Training pipeline for formal theorem proving, based on a paradigm inspired by DeepSeek-R1.
- RL-PLUS: Countering Capability Boundary Collapse of LLMs in Reinforcement Learning with Hybrid-policy Optimization.
- rStar2-Agent: Using reinforcement learning with multi-step tool-calling for math tasks, rStar2-Agent-14B reaches frontier-level math reasoning in just 510 RL training steps
- Vision-SR1: Self-Rewarding Vision-Language Model via Reasoning Decomposition
- SimpleVLA-RL: SimpleVLA-RL: A Simple yet Effective Vision-Language Action Model for Reinforcement Learning
- Table-R1: Table-R1: Inference-Time Scaling for Table Reasoning
- Revisual-R1: Revisual-R1: Advancing Multimodal Reasoning From Optimized Cold Start to Staged Reinforcement Learning
- ARES: ARES: Multimodal Adaptive Reasoning via Difficulty-Aware Token-Level Entropy Shaping
- Meta-Bandit-LLM: Meta-Bandit-LLM: Long-horizon multiturn interactive training for meta-bandit agents
- PokeeResearch: PokeeResearch: State-of-the-art 7B DeepResearch Agent that leverages web search and content reading capabilities to answer complex questions using the most up-to-date information available online.
- Search Self-play: Pushing the Frontier of Agent Capability without Supervision
- OneThinker: All-in-one Reasoning Model for Image and Video
- OpenTinker: Democratizing Agentic Reinforcement Learning as a Service
- FlowRL: Matching reward distributions via flow balance for diverse exploration and generalizable reasoning
- Logic-RL: a reproduction of DeepSeek R1 Zero on 2K Tiny Logic Puzzle Dataset.
- Seed-Coder: RL training of Seed-Coder boosts performance on competitive programming
- all-hands/openhands-lm-32b-v0.1: A strong, open coding agent model, trained with multi-turn fine-tuning
- s3 Efficient Yet Effective Search Agent Training via RL
- Rec-R1: Bridging Generative Large Language Models and Recommendation Systems via Reinforcement Learning
- Explore RL Data Scaling: Exploring Data Scaling Trends and Effects in Reinforcement Learning from Human Feedback
- FIRE: Flaming-hot initiation with regular execution sampling for large language models
- DQO: Enhancing multi-Step reasoning abilities of language models through direct Q-function optimization
- ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models
- cognition-engineering: Test time scaling drives cognition engineering.
- Trust Region Preference Approximation: A simple and stable reinforcement learning algorithm for LLM reasoning.
- AdaRFT: Efficient Reinforcement Finetuning via Adaptive Curriculum Learning
- critic-rl: LLM critics for code generation
- self-rewarding-reasoning-LLM: self-rewarding and correction with generative reward models
- DeepEnlighten: Reproduce R1 with social reasoning tasks and analyze key findings
- MetaSpatial: Reinforcing 3D Spatial Reasoning in VLMs for the Metaverse
- PURE: Credit assignment is the key to successful reinforcement fine-tuning using process reward model
- cognitive-behaviors: Cognitive Behaviors that Enable Self-Improving Reasoners, or, Four Habits of Highly Effective STaRs
- deepscaler: iterative context scaling with GRPO
- DAPO: the fully open source SOTA RL algorithm that beats DeepSeek-R1-zero-32B
- NoisyRollout: Reinforcing Visual Reasoning with Data Augmentation
- SPEAR: Self-imitation with Progressive Exploration for Agentic Reinforcement Learning (ICLR 2026)
- RuleReasoner: RuleReasoner: Reinforced Rule-based Reasoning via Domain-aware Dynamic Sampling (ICLR 2026)
- MetaphorStar: Image Metaphor Understanding and Reasoning with End-to-End Visual Reinforcement Learning
- DART-GUI: a decoupled agentic RL framework for Computer Use Agents, achieving ~2× training speedup and ~5× environment utilization!
- Rethinking OPD: Rethinking On-Policy Distillation of Large Language Models: Phenomenology, Mechanism, and Recipe


Contribution Guide
About ByteDance Seed Team
Founded in 2023, ByteDance Seed Team is dedicated to crafting the industry's most advanced AI foundation models. The team aspires to become a world-class research team and make significant contributions to the advancement of science and society. You can get to know Bytedance Seed better through the following channels👇
We are HIRING! Send us an email if you are interested in internship/FTE opportunities in RL for agents.
trl
huggingface·Python
用强化学习训练 Transformer 语言模型的全流程库,覆盖 SFT、奖励建模到 PPO/DPO 等 RLHF 算法,省去自己拼训练管线。
强化学习+4后训练 / RLHF
19708+223.1kv1.17.12026-11-10 17:00 UTC
OpenRLHF
OpenRLHF·Python
基于 Ray 的高性能 RLHF 训练框架,支持 PPO、DAPO、REINFORCE++ 等算法与 vLLM 推理加速,可扩展地完成大模型和视觉语言模型的对齐后训练。
RLHF+4后训练 / RLHF
10147+11.1kv0.11.22026-11-03 03:17 UTC
PaLM-rlhf-pytorch
lucidrains·Python
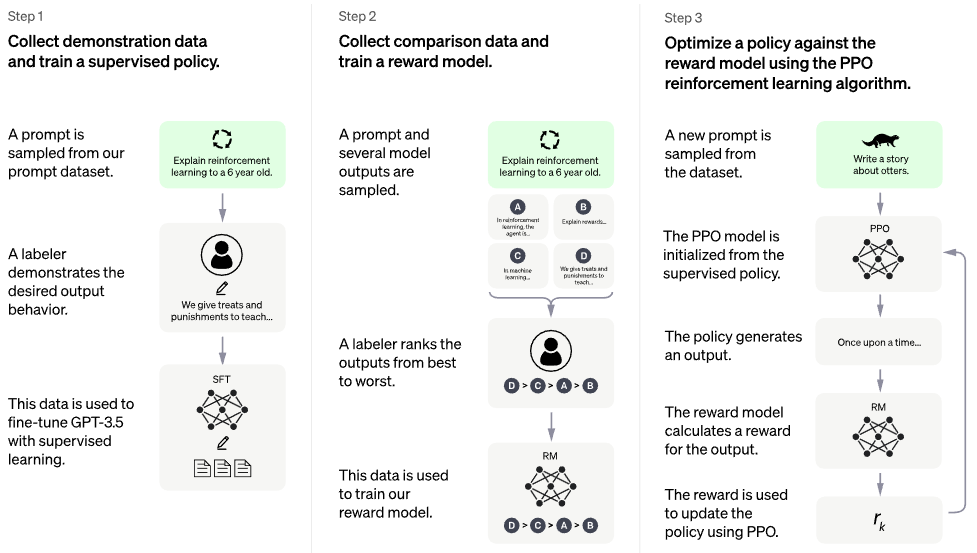
在 PaLM 架构上实现 RLHF 人类反馈强化学习,复现 ChatGPT 式训练流程,适合研究大模型对齐与强化学习微调。
RLHF+4后训练 / RLHF
78636660.7.12026-09-20 15:27 UTC
MedicalGPT
shibing624·Python
用 ChatGPT 同款流程训练医疗大模型,覆盖增量预训练、有监督微调、RLHF、DPO、ORPO、GRPO 全链路,开箱即可复现。
医疗大模型+4后训练 / RLHF
5891+38042.7.02026-09-15 13:46 UTC