依赖版本锁得较死(torch 1.13.1、torchaudio 0.13.1、librosa 0.8.1),且需按 CUDA 11.6 与 Python 3.10 选对应 k2 wheel;lhotse 需从 GitHub 源码安装最新版而非 pip 版本;icefall 需 clone 后设置 PYTHONPATH,且需系统安装 espeak-ng。
vall-e
lifeitengApache-2.0长期未更新用 PyTorch 复现 VALL-E 零样本语音合成,只需几秒参考音频就能克隆音色朗读任意文本。
PyTorch implementation of VALL-E(Zero-Shot Text-To-Speech), Reproduced Demo https://lifeiteng.github.io/valle/index.html
v1.0发布于 2023-04-14 07:00 UTC2,220star326fork同步于 2026-11-07 07:30 UTC
pip install torch==1.13.1 torchaudio==0.13.1 --extra-index-url https://download.pytorch.org/whl/cu116
apt-get install espeak-ng
pip install phonemizer==3.2.1 pypinyin==0.48.0
git clone https://github.com/lifeiteng/valle.git
cd valle
pip install -e . 硬件要求按 README 说明
README 说明可在单张 24GB 显存的 GPU 上训练 LibriTTS 模型;未说明 CPU 运行或其他 GPU 型号。
多卡 / 张量并行
VALL-E 的 PyTorch 非官方实现,单卡即可训练零样本 TTS 模型
用 PyTorch 复现 VALL-E 零样本语音合成,只需几秒参考音频就能克隆音色朗读任意文本。
核心能力
- 用 PyTorch 复现 VALL-E 零样本语音合成
- 支持在单张 GPU 上训练 AR 与 NAR 模型
- 提供 prefix_mode 0/1/2/4 控制 NAR 声学提示
- 附 LibriTTS 与 AISHELL-1 中英文训练推理示例
- 基于 lhotse manifests 支持自定义数据集
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v1.0VALL-E 1.0: Reproduce the results of the paper, Train larger models, and greatly improve the speed of token extraction.最新正式版2023-04-14 · 2023-04-14 07:00 UTC
VALL-E 1.0 Release notes
- Reproducted Demo https://lifeiteng.github.io/valle/index.html
- Traning commands egs/libritts#demo
- Inference valle/run.sh#L68
- Support Two stages training #59
- Support Mandarin #85 Thanks @zhaomingwork
- Speedup Encodec AudioTokenizer #81 #88 Thanks @guokr233
- Thanks reviewer @zjwang21
- Reproducted Demo https://lifeiteng.github.io/valle/index.html
- v0.4.0Greatly improved accuracy and Fix GPU memory increase during training2023-03-02 · 2023-03-02 13:28 UTC
查看更新说明
- improved AR Top10 accuracy use default optim scheduler and base_lr
- Fix GPU memory increase during training
- v0.1.0Train VALL-E on a single GPU!pre-release2023-02-18 · 2023-02-18 13:18 UTC
这个版本没有写更新说明。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
Language : 🇺🇸 | 🇨🇳
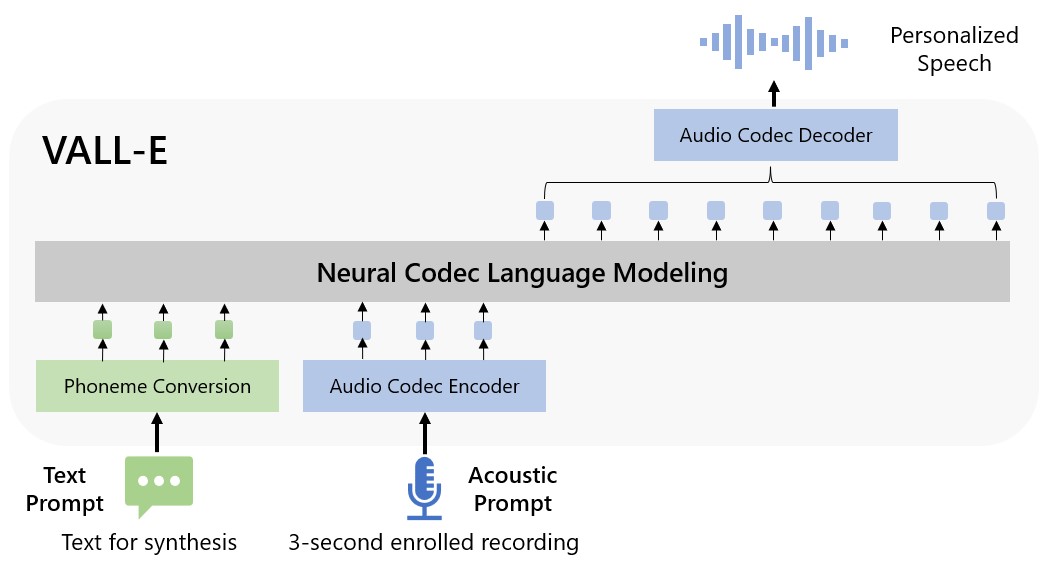
An unofficial PyTorch implementation of VALL-E(Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers).
We can train the VALL-E model on one GPU.

Demo
Broader impacts
Since VALL-E could synthesize speech that maintains speaker identity, it may carry potential risks in misuse of the model, such as spoofing voice identification or impersonating a specific speaker.
To avoid abuse, Well-trained models and services will not be provided.
Install Deps
To get up and running quickly just follow the steps below:
# PyTorch
pip install torch==1.13.1 torchaudio==0.13.1 --extra-index-url https://download.pytorch.org/whl/cu116
pip install torchmetrics==0.11.1
# fbank
pip install librosa==0.8.1

# phonemizer pypinyin
apt-get install espeak-ng
## OSX: brew install espeak
pip install phonemizer==3.2.1 pypinyin==0.48.0

# lhotse update to newest version
# https://github.com/lhotse-speech/lhotse/pull/956
# https://github.com/lhotse-speech/lhotse/pull/960
pip uninstall lhotse
pip uninstall lhotse
pip install git+https://github.com/lhotse-speech/lhotse

# k2
# find the right version in https://huggingface.co/csukuangfj/k2
pip install https://huggingface.co/csukuangfj/k2/resolve/main/cuda/k2-1.23.4.dev20230224+cuda11.6.torch1.13.1-cp310-cp310-linux_x86_64.whl

# icefall
git clone https://github.com/k2-fsa/icefall
cd icefall
pip install -r requirements.txt
export PYTHONPATH=`pwd`/../icefall:$PYTHONPATH
echo "export PYTHONPATH=`pwd`/../icefall:\$PYTHONPATH" >> ~/.zshrc
echo "export PYTHONPATH=`pwd`/../icefall:\$PYTHONPATH" >> ~/.bashrc
cd -
source ~/.zshrc

# valle
git clone https://github.com/lifeiteng/valle.git
cd valle
pip install -e .
Training&Inference
-
English example examples/libritts/README.md
-
Chinese example examples/aishell1/README.md
-
Prefix Mode 0 1 2 4 for NAR Decoder
Paper Chapter 5.1 "The average length of the waveform in LibriLight is 60 seconds. During training, we randomly crop the waveform to a random length between 10 seconds and 20 seconds. For the NAR acoustic prompt tokens, we select a random segment waveform of 3 seconds from the same utterance."- 0: no acoustic prompt tokens
- 1: random prefix of current batched utterances (This is recommended)
- 2: random segment of current batched utterances
- 4: same as the paper (As they randomly crop the long waveform to multiple utterances, so the same utterance means pre or post utterance in the same long waveform.)
# If train NAR Decoders with prefix_mode 4
python3 bin/trainer.py --prefix_mode 4 --dataset libritts --input-strategy PromptedPrecomputedFeatures ...
LibriTTS demo Trained on one GPU with 24G memory
cd examples/libritts

# step1 prepare dataset
bash prepare.sh --stage -1 --stop-stage 3

# step2 train the model on one GPU with 24GB memory
exp_dir=exp/valle

## Train AR model
python3 bin/trainer.py --max-duration 80 --filter-min-duration 0.5 --filter-max-duration 14 --train-stage 1 \
      --num-buckets 6 --dtype "bfloat16" --save-every-n 10000 --valid-interval 20000 \
      --model-name valle --share-embedding true --norm-first true --add-prenet false \
      --decoder-dim 1024 --nhead 16 --num-decoder-layers 12 --prefix-mode 1 \
      --base-lr 0.05 --warmup-steps 200 --average-period 0 \
      --num-epochs 20 --start-epoch 1 --start-batch 0 --accumulate-grad-steps 4 \
      --exp-dir ${exp_dir}

## Train NAR model
cp ${exp_dir}/best-valid-loss.pt ${exp_dir}/epoch-2.pt  # --start-epoch 3=2+1
python3 bin/trainer.py --max-duration 40 --filter-min-duration 0.5 --filter-max-duration 14 --train-stage 2 \
      --num-buckets 6 --dtype "float32" --save-every-n 10000 --valid-interval 20000 \
      --model-name valle --share-embedding true --norm-first true --add-prenet false \
      --decoder-dim 1024 --nhead 16 --num-decoder-layers 12 --prefix-mode 1 \
      --base-lr 0.05 --warmup-steps 200 --average-period 0 \
      --num-epochs 40 --start-epoch 3 --start-batch 0 --accumulate-grad-steps 4 \
      --exp-dir ${exp_dir}

# step3 inference
python3 bin/infer.py --output-dir infer/demos \
    --checkpoint=${exp_dir}/best-valid-loss.pt \
    --text-prompts "KNOT one point one five miles per hour." \
    --audio-prompts ./prompts/8463_294825_000043_000000.wav \
    --text "To get up and running quickly just follow the steps below." \

# Demo Inference
https://github.com/lifeiteng/lifeiteng.github.com/blob/main/valle/run.sh#L68

Troubleshooting
- SummaryWriter segmentation fault (core dumped)
- LINE
tb_writer = SummaryWriter(log_dir=f"{params.exp_dir}/tensorboard") - FIX https://github.com/tensorflow/tensorboard/pull/6135/files
file=`python -c 'import site; print(f"{site.getsitepackages()[0]}/tensorboard/summary/writer/event_file_writer.py")'` sed -i 's/import tf/import tensorflow_stub as tf/g' $file - LINE
Training on a custom dataset?
- prepare the dataset to
lhotse manifests- There are plenty of references here lhotse/recipes
python3 bin/tokenizer.py ...python3 bin/trainer.py ...
Contributing
- Parallelize bin/tokenizer.py on multi-GPUs
Citing
To cite this repository:
@misc{valle,
  author={Feiteng Li},
  title={VALL-E: A neural codec language model},
  year={2023},
  url={http://github.com/lifeiteng/vall-e}
}
@article{VALL-E,
  title     = {Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers},
  author    = {Chengyi Wang, Sanyuan Chen, Yu Wu,
               Ziqiang Zhang, Long Zhou, Shujie Liu,
               Zhuo Chen, Yanqing Liu, Huaming Wang,
               Jinyu Li, Lei He, Sheng Zhao, Furu Wei},
  year      = {2023},
  eprint    = {2301.02111},
  archivePrefix = {arXiv},
  volume    = {abs/2301.02111},
  url       = {http://arxiv.org/abs/2301.02111},
}
Star History
whisper
openai·Python
OpenAI 开源的通用语音识别模型,基于大规模弱监督训练,支持多语言转写、翻译和语种识别,开箱即用。
语音识别+4语音
112335+19814kv202506252026-08-31 17:19 UTC
GPT-SoVITS
RVC-Boss·Python
只需 1 分钟语音数据就能训练出高质量 TTS 模型,支持少样本音色克隆,适合快速定制个性化语音合成。
语音合成+4语音
64691+2516.8k20250606v2pro2026-11-09 13:59 UTC
Real-Time-Voice-Cloning
CorentinJ·Python
用 5 秒语音样本克隆音色,实时合成任意文本的语音,基于 PyTorch/TensorFlow 的说话人编码与声码器流水线。
语音克隆+4语音
60235+59.4k2026-03-09 10:31 UTC

VoxCPM
OpenBMB·Python
无需分词器的多语言语音合成模型,支持创意音色设计和逼真声音克隆,可直接从文本生成自然语音。
语音合成+4语音
42181+10374.8k2.0.32026-11-09 07:36 UTC