需自行从 nuScenes、Ego4D 官方渠道下载图像数据,并按格式软链接到 data/xx 目录;完整预训练数据标签暂未公开,仅提供部分数据和参考检查点;推理需修改 advqa_t5_elm.yaml 将 evaluate 设为 True 后复用 scripts/train.sh
ELM
OpenDriveLab长期未更新面向自动驾驶场景的视觉语言基础模型,通过多模态理解把驾驶画面转成可推理的语义描述,为端到端驾驶提供感知与决策支持。
[ECCV 2024] Embodied Understanding of Driving Scenarios
暂无版本208star14fork同步于 2026-11-07 07:31 UTC
conda create -n elm python=3.8
conda activate elm
pip install salesforce-lavis 硬件要求按 README 说明
README 未说明
面向自动驾驶场景的具身语言模型,用语言提示理解长时序驾驶场景
面向自动驾驶场景的视觉语言基础模型,通过多模态理解把驾驶画面转成可推理的语义描述,为端到端驾驶提供感知与决策支持。
核心能力
- 基于语言提示理解空间与时间维度的长时序驾驶场景
- 扩展多种新任务以发挥大语言模型在具身设定下的能力
- 提供微调代码、参考检查点与标签生成工具包
- 提供问答评测脚本 scripts/qa_eval.py 评估生成答案
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
暂无 release 数据(可能没有发版,或尚未同步)。
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。
[!IMPORTANT] 🌟 Stay up to date at opendrivelab.com!
ELM: Embodied Understanding of Driving Scenarios
Revive driving scene understanding by delving into the embodiment philosophy

Yunsong Zhou, Linyan Huang, Qingwen Bu, Jia Zeng, Tianyu Li, Hang Qiu, Hongzi Zhu, Minyi Guo, Yu Qiao, and Hongyang Li
- Presented by OpenDriveLab and Shanghai AI Lab
- :mailbox_with_mail: Primary contact: Yunsong Zhou ( [email protected] )
- arXiv paper | Blog TODO | Slides
- CVPR 2024 Autonomous Driving Challenge - Driving with Language
Highlights
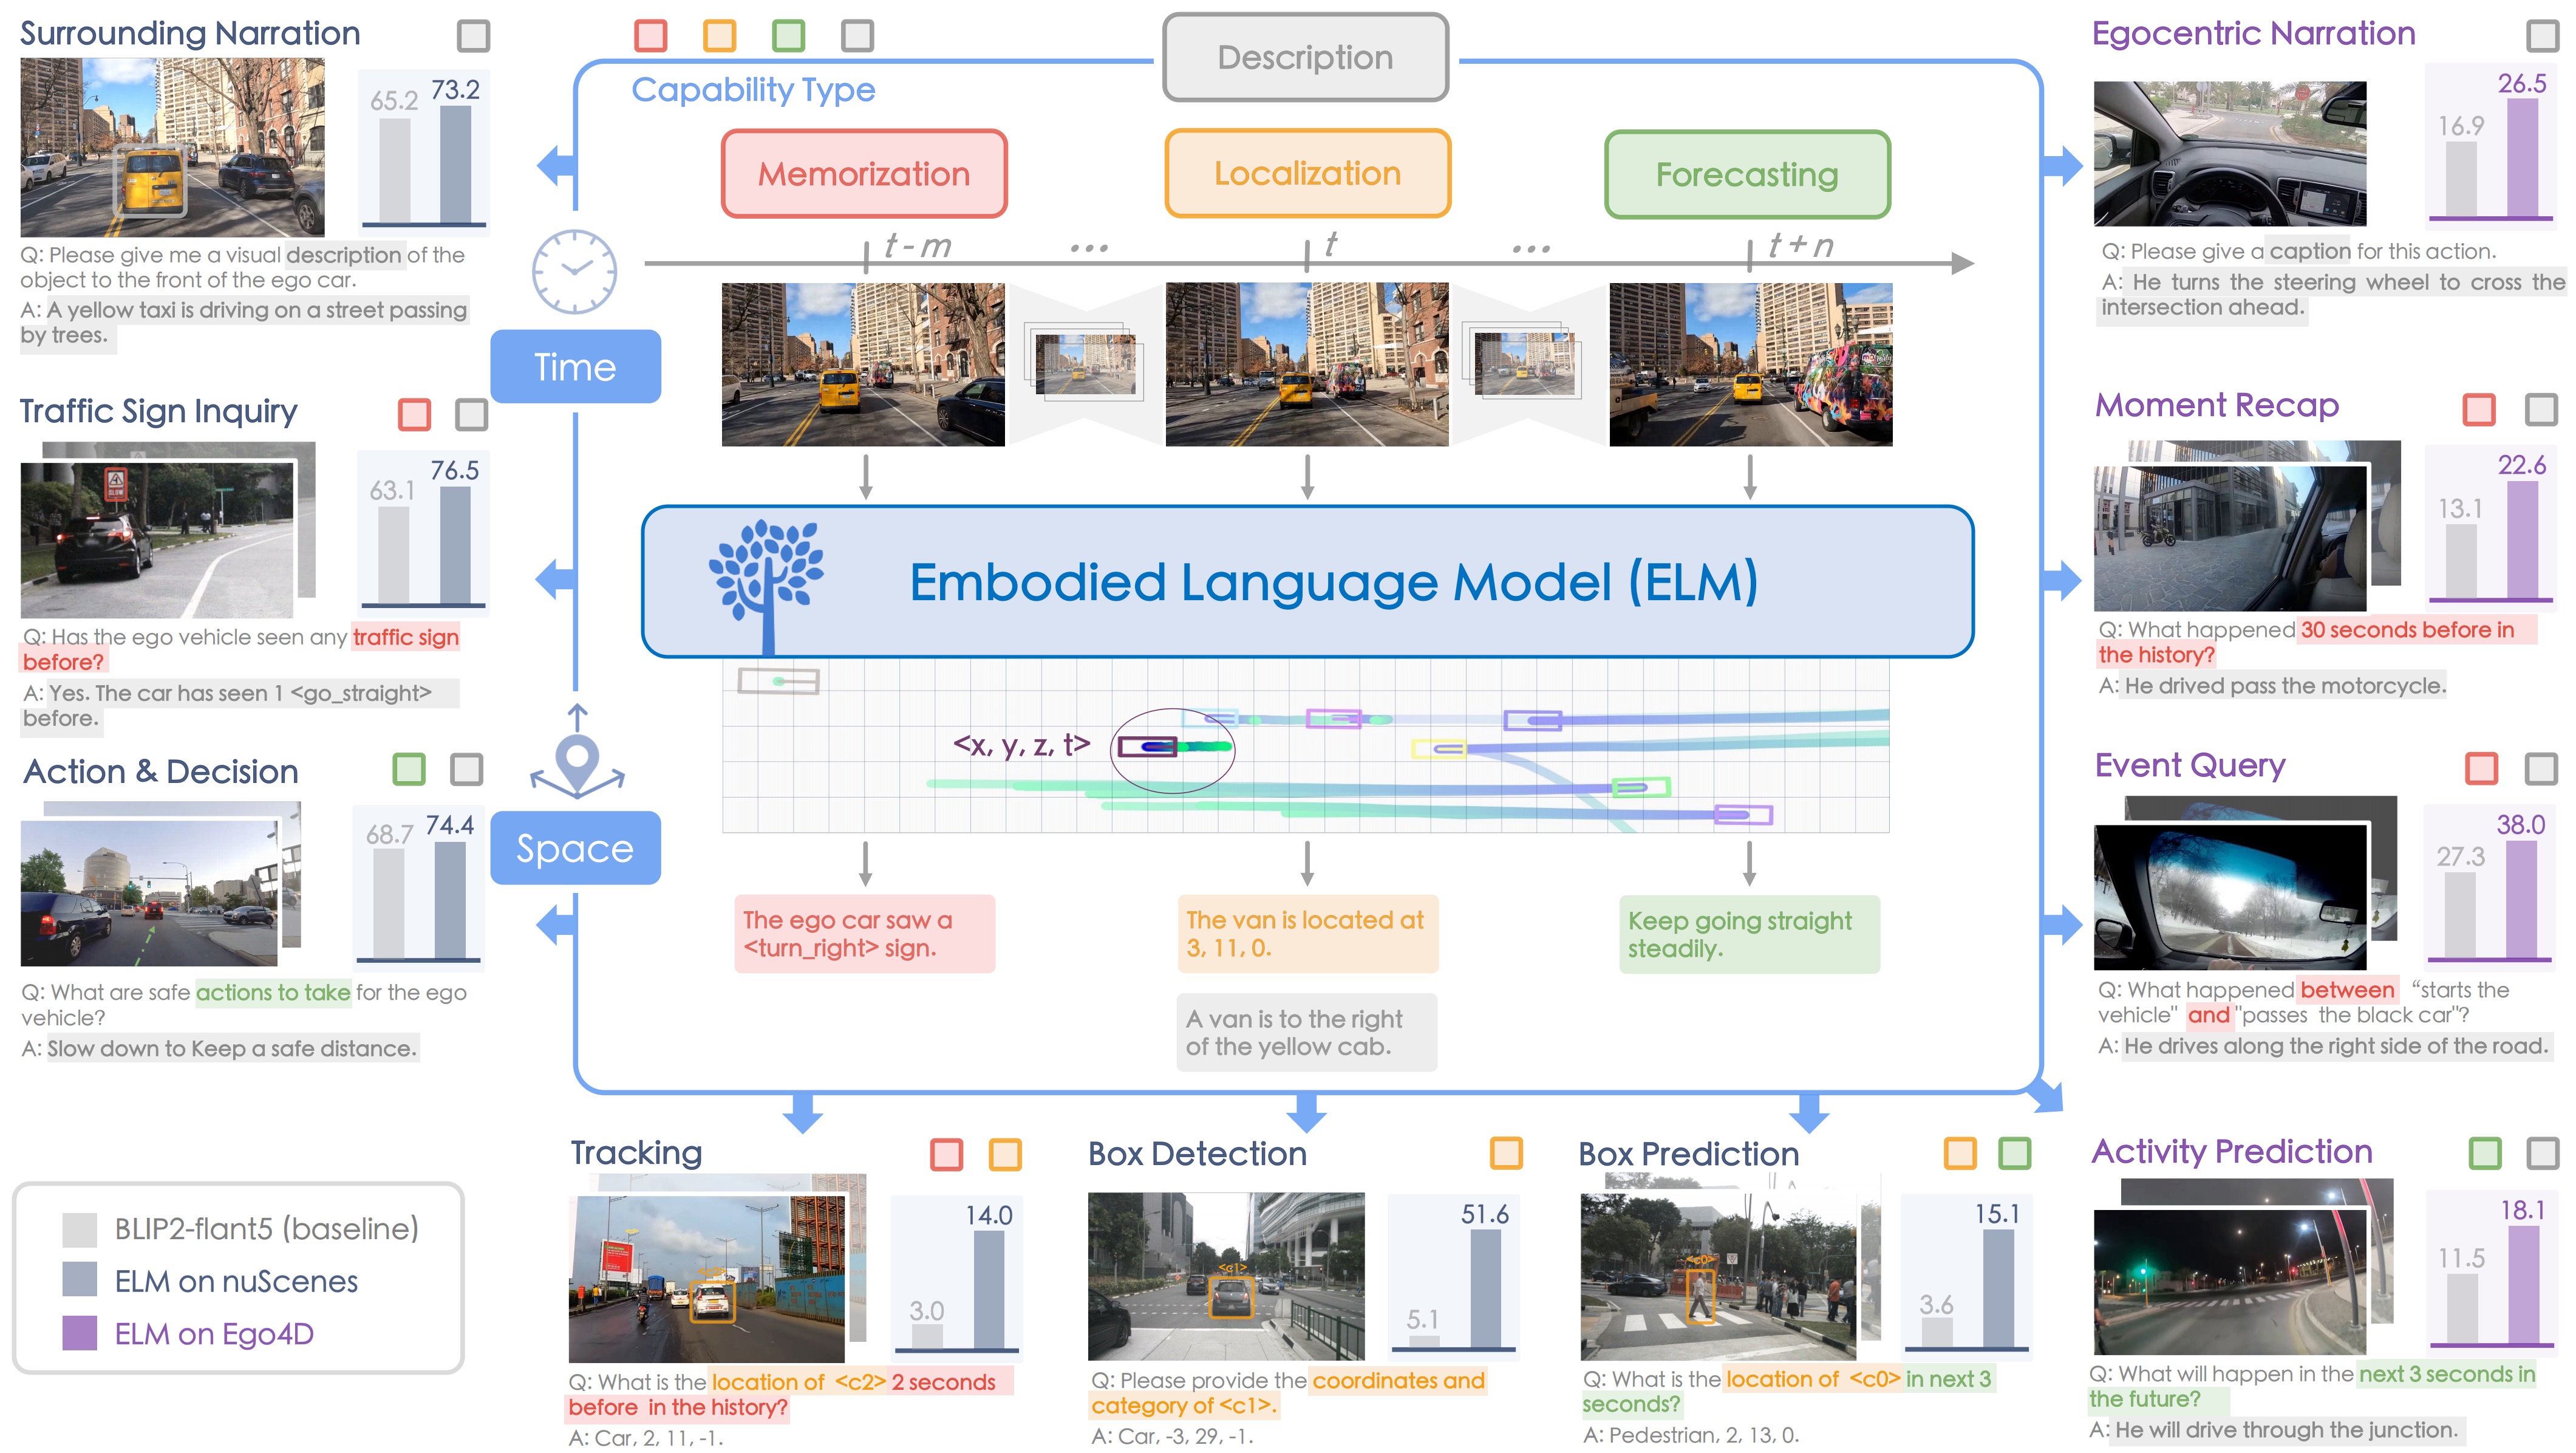
:fire: The first embodied language model for understanding the long-horizon driving scenarios in space and time.
:star2: ELM expands a wide spectrum of new tasks to fully leverage the capability of large language models in an embodiment setting and achieves significant improvements in various applications.

:trophy: Interpretable driving model, on the basis of language prompting, will be a main track in the CVPR 2024 Autonomous Driving Challenge. Please stay tuned for further details!
News
- :fire: Interpretable driving model is launched. Please refer to the link for more details.
[2024/03]ELM paper released.[2024/03]ELM code and data initially released.
Table of Contents
- Highlights
- News
- TODO List
- Installation
- Dataset
- Training and Inference
- License and Citation
- Related Resources
TODO List
- Release fine-tuning code and data
- Release reference checkpoints
- Toolkit for label generation
Installation
- (Optional) Creating conda environment
conda create -n elm python=3.8
conda activate elm
- install from PyPI
pip install salesforce-lavis
- Or, for development, you may build from source
git clone https://github.com/OpenDriveLab/ELM.git
cd ELM
pip install -e .
Dataset
Pre-training data. We collect driving videos from YouTube, nuScenes, Waymo, and Ego4D. Here we provide a sample of 🔗 YouTube video list we used. For privacy considerations, we are temporarily keeping the full-set data labels private. Part of pre-training data and reference checkpoints can be found in :floppy_disk: google drive.
Fine-tuning data.
The full set of question and answer pairs for the benchmark can be obtained through this 🔗data link. You may need to download the corresponding image data from the official nuScenes and Ego4D channels.
For a quick verification of the pipeline, we recommend downloading the subset dataset of DriveLM and organizing the data in line with the format.
Please make sure to soft link nuScenes and ego4d datasets under data/xx folder.
You may need to run tools/video_clip_processor.py to pre-process data first.
Besides, we provide some script used during auto-labeling, you may use these as a reference if you want to customize data.
Training
# you can modify the lavis/projects/blip2/train/advqa_t5_elm.yaml
bash scripts/train.sh
Inference
Modify the advqa_t5_elm.yaml to enable the evaluate as True.
bash scripts/train.sh
For the evaluation of generated answers, please use the script in scripts/qa_eval.py.
python scripts/qa_eval.py <data_root> <log_name>
License and Citation
All assets and code in this repository are under the Apache 2.0 license unless specified otherwise. The language data is under CC BY-NC-SA 4.0. Other datasets (including nuScenes and Ego4D) inherit their own distribution licenses. Please consider citing our paper and project if they help your research.
@article{zhou2024embodied,
  title={Embodied Understanding of Driving Scenarios},
  author={Zhou, Yunsong and Huang, Linyan and Bu, Qingwen and Zeng, Jia and Li, Tianyu and Qiu, Hang and Zhu, Hongzi and Guo, Minyi and Qiao, Yu and Li, Hongyang},
  journal={arXiv preprint arXiv:2403.04593},
  year={2024}
}
Related Resources
We acknowledge all the open-source contributors for the following projects to make this work possible:

PythonRobotics
AtsushiSakai·Python
用 Python 实现机器人算法的示例代码与配套教材,覆盖定位、建图、路径规划、控制等模块,适合边跑可视化动画边学自动驾驶与自主导航。
路径规划+4自动驾驶
30887+127.4k2026-11-09 20:03 UTC

OpenPCDet
open-mmlab·Python
基于 PyTorch 的激光雷达 3D 目标检测工具箱,统一了 PointPillar、PV-RCNN 等主流点云检测模型的训练与评测流程,省去自己搭框架的麻烦。
3D目标检测+4自动驾驶
5766+31.5k2025-10-08 10:56 UTC
mrpt
MRPT·C++
一套面向移动机器人和自动驾驶的 C++ 工具库,提供 SLAM、计算机视觉、地图构建、粒子滤波和运动估计等模块,省去从零搭建底层算法。
移动机器人+4自动驾驶
2175+16623.6.22026-11-07 22:34 UTC
AutonomousVehicleControlBeginnersGuide
ShisatoYano·Python
用 Python 仿真加开源教材一步步搭建自动驾驶系统,可在同一框架里替换对比定位、规划与控制算法,适合入门学习。
自动驾驶+4自动驾驶
1938+23212026-11-08 08:38 UTC