PyTorch 需按硬件与驱动版本单独选择构建,装错版本会跑不起来;部分能力要另装可选依赖组(如 onnx、faiss、visualization);示例脚本使用相对数据路径,需先 cd 进脚本目录再运行。
torch-rechub
datawhalechinaMIT活跃维护基于 PyTorch 的推荐模型训练框架,封装了 CTR 预估、生成式推荐等常用算法,开箱即用且方便扩展,支持昇腾 NPU 和 ONNX 导出。
A Lighting Pytorch Framework for Recommendation Models, Easy-to-use and Easy-to-extend.
v1.0.0发布于 2026-11-06 11:56 UTC1,241star +1 / 7 天162fork同步于 2026-11-10 23:50 UTC
pip install torch
pip install torch-rechub 硬件要求按 README 说明
支持 CPU、NVIDIA CUDA GPU、AMD ROCm GPU 和华为昇腾 NPU,需按设备选择对应 PyTorch 构建;README 未给出具体显存要求。
需要 CUDA支持 ROCm / AMD昇腾 / Ascend
轻量 PyTorch 推荐系统框架,30+ 模型开箱即用,十行代码搭出生产级推荐
基于 PyTorch 的推荐模型训练框架,封装了 CTR 预估、生成式推荐等常用算法,开箱即用且方便扩展,支持昇腾 NPU 和 ONNX 导出。
核心能力
- 内置 30+ 召回、排序、多任务与生成式推荐模型
- 统一数据加载、训练与评估流程,配置或命令行调参
- 支持导出 ONNX 模型用于生产部署
- 集成 WandB、SwanLab、TensorBoardX 实验追踪
- 可选 PySpark 大数据处理与 FAISS、Milvus 向量检索
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v1.0.0最新正式版2026-11-06 · 2026-11-06 11:56 UTC
What's Changed
🐛 Bug 修复 / Bug Fixes
- fix(matching): count shared feature fields in SENet towers by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/276
- fix(din): include dense context values in MLP input by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/280
- fix(data): bound negative sampling and handle exhausted catalogs by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/281
- fix(data): split full sequences before truncating histories by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/282
- fix(callback): initialize early stopping from the first finite score by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/283
- fix(trainers): persist best validation weights during training by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/284
- fix(layers): preserve batch dimension for single-item inference by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/286
- fix(serving): import optional backends only when selected by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/291
- fix(features): isolate parameters between model instances by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/288
- fix(features): restore per-feature embedding cache by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/294
- fix(sequence): mask padding and correct SINE normalization by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/287
- fix(trainers): simplify epoch learning-rate logging by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/290
- fix(metrics): keep essential GAUC, Top-K and LogLoss boundary fixes by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/289
- fix(generative): complete simple single-device training workflows by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/293
🔧 模型更新 / Models
- Add single-device in-batch DSSM training by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/272
- feat(matching): extend in-batch sampling across recall models by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/274
✨ 新特性 / Features
- feat(ranking): add opt-in in-batch negative sampling by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/275
- refactor: simplify ONNX quantization and preserve export compatibility by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/278
- refactor: simplify shared model visualization by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/277
- feat(trainers): configure batch loss and learning-rate progress by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/295
Full Changelog: https://github.com/datawhalechina/torch-rechub/compare/v0.9.0...v1.0.0
- v0.9.02026-09-14 · 2026-09-14 02:10 UTC
查看更新说明
What's Changed
🐛 Bug 修复 / Bug Fixes
- Fix HLLM embedding/vocab alignment; add generative data download workflow by @TyndaleLym in https://github.com/datawhalechina/torch-rechub/pull/241
- fix: 让 TIGER 示例可运行并新增 MovieLens 脚本 by @TyndaleLym in https://github.com/datawhalechina/torch-rechub/pull/245
- fix: 替换 4 处失效的奶牛快传数据链接(承接 #201) by @ksk2023 in https://github.com/datawhalechina/torch-rechub/pull/263
- fix: support min-mode early stopping by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/266
🔧 模型更新 / Models
- Align HSTU with Meta reference; fix training/eval correctness by @TyndaleLym in https://github.com/datawhalechina/torch-rechub/pull/244
- feat(mind): dynamic per-user interest count (issue #240) by @nsiddharth in https://github.com/datawhalechina/torch-rechub/pull/251
✨ 新特性 / Features
- 修改了census-Income,aliexpress,amazon-beauty,amazon-books,amazon-electro… by @Luxorion-12 in https://github.com/datawhalechina/torch-rechub/pull/252
📝 文档更新 / Documentation
- Update features.md by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/259
- Update docs files by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/260
New Contributors
- @TyndaleLym made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/241
- @ksk2023 made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/263
- @nsiddharth made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/251
Full Changelog: https://github.com/datawhalechina/torch-rechub/compare/v0.8.0...v0.9.0
- v0.8.02026-05-12 · 2026-05-12 06:02 UTC
查看更新说明
What's Changed
🐛 Bug 修复 / Bug Fixes
- fix docs by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/231
- Fix stray 'uv' in pip install command by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/239
🔧 模型更新 / Models
- Update DIEN docs, example and refactor AUGRU by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/229
- Refactor BST transformer; bump PyTorch to 1.10 by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/233
- Adjust embedding outputs and unwrap ONNX scalar by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/237
📦 依赖更新 / Dependencies
- CI: add twine check and update pyproject metadata by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/227
📝 文档更新 / Documentation
- Update docs images: banner and logo by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/225
- Add documentation diagrams and embed them by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/235
- Create CITATION.cff by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/236
- Improve tutorials: paths, features, DeepFM by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/238
Full Changelog: https://github.com/datawhalechina/torch-rechub/compare/v0.7.0...v0.8.0
- v0.7.02026-04-21 · 2026-04-21 03:20 UTC
查看更新说明
What's Changed
✨ 新特性 / Features
- Add workflow and script to auto-generate API docs by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/208
- Add dynamo ONNX export with fallback by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/212
- Fix MIND and ComiRec list-wise logits shape by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/222
🐛 Bug 修复 / Bug Fixes
- fix: 修复英文首页 Get Started 按钮 404 链接 by @happydog-intj in https://github.com/datawhalechina/torch-rechub/pull/205
- fix: 修复 docs/en/ 下所有 /en/ 前缀内部链接 404 by @happydog-intj in https://github.com/datawhalechina/torch-rechub/pull/206
📝 文档更新 / Documentation
- Consolidate README: English main, add Chinese by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/209
- Update README by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/213
- Revamp VitePress theme and docs navigation by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/214
- Update images of tutorials by @queenyn in https://github.com/datawhalechina/torch-rechub/pull/203
- Update custom.css by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/217
- Revise Quick Start and add model tutorials by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/218
- Update README images and add MIND list-wise docs by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/223
New Contributors
- @happydog-intj made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/205
Full Changelog: https://github.com/datawhalechina/torch-rechub/compare/v0.6.0...v0.7.0
- v0.6.02026-03-18 · 2026-03-18 07:51 UTC
查看更新说明
What's Changed
✨ 新特性 / Features
- fix data.py by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/192
- Update metric.py by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/194
- feat: add NPU optional dependency for Huawei Ascend support by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/196
- feat: add MMOE/ESMM notebook and training code by @Luxorion-12 in https://github.com/datawhalechina/torch-rechub/pull/200
🐛 Bug 修复 / Bug Fixes
- Update 00_QuickStart_CTR_DeepFM.ipynb && Update init.py by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/187
📝 文档更新 / Documentation
- docs: add model usage example documentation for 6 priority models by @sliortega295-ops in https://github.com/datawhalechina/torch-rechub/pull/185
- docs: add model usage example documentation for DIN, DIEN, BST, MIND, PLE (Batch 2) by @sliortega295-ops in https://github.com/datawhalechina/torch-rechub/pull/188
- add DSSM,DeepFM,DIN.ipynb by @queenyn in https://github.com/datawhalechina/torch-rechub/pull/199
🔧 模型更新 / Models
- Refactor BST transformer handling by @1985312383 in https://github.com/datawhalechina/torch-rechub/pull/195
New Contributors
- @sliortega295-ops made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/185
- @queenyn made their first contribution in https://github.com/datawhalechina/torch-rechub/pull/199
Full Changelog: https://github.com/datawhalechina/torch-rechub/compare/v0.5.0...v0.6.0
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。

Torch-RecHub: A Lightweight, Efficient, and Easy-to-use PyTorch Recommender Framework



English | 简体中文

Online Documentation: https://datawhalechina.github.io/torch-rechub/
Torch-RecHub —— Build production-grade recommender systems in 10 lines of code. 30+ mainstream models out-of-the-box, one-click ONNX deployment, letting you focus on business instead of engineering.
✨ Features
- Modular Design: Easy to add new models, datasets, and evaluation metrics.
- Based on PyTorch: Leverages PyTorch's dynamic graph and hardware acceleration capabilities. Supports CPU, NVIDIA CUDA GPU, AMD ROCm GPU, and Huawei Ascend NPU.
- Rich Model Library: Covers 30+ classic and cutting-edge recommendation algorithms (Matching, Ranking, Multi-task, Generative Recommendation, etc.).
- Standardized Pipeline: Provides unified data loading, training, and evaluation workflows.
- Easy Configuration: Adjust experiment settings via config files or command-line arguments.
- Reproducibility: Designed to ensure reproducible experimental results.
- ONNX Export: Export trained models to ONNX format for seamless production deployment.
- Cross-engine Data Processing: Support for PySpark-based data processing and transformation, facilitating deployment in big data pipelines.
- Experiment Visualization & Tracking: Built-in unified integration for WandB, SwanLab, and TensorBoardX.
📖 Table of Contents
- 🔥 Torch-RecHub - A Lightweight, Efficient, and Easy-to-use PyTorch Recommender Framework
🔧 Installation
Requirements
- Python 3.10+
- PyTorch 2.6+ (choose the CPU, NVIDIA CUDA, AMD ROCm, or Huawei Ascend NPU build for your device)
- NumPy
- Pandas
- SciPy
- Scikit-learn
Installation Steps
PyTorch builds are tightly coupled with your hardware, driver, and runtime versions. Before installing, check the official compatibility references for NVIDIA CUDA / PyTorch versions, Huawei Ascend NPU / PyTorch versions, and AMD ROCm / PyTorch versions.
Stable Version (Recommended):
# Install one PyTorch build matching your device
pip install torch                                                     # CPU
pip install torch --index-url https://download.pytorch.org/whl/cu126  # NVIDIA GPU (CUDA 12.6; choose a build matching your hardware)
pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

pip install torch-rechub
Latest Version:
# Install uv first (if not already installed)
pip install uv

# Clone and install
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub

# Install one PyTorch build matching your device
uv pip install torch                                                     # CPU
uv pip install torch --index-url https://download.pytorch.org/whl/cu126  # NVIDIA GPU (CUDA 12.6; choose a build matching your hardware)
uv pip install torch torch-npu                                           # Huawei Ascend NPU (requires torch-npu >= 2.5.1)
uv pip install --index-url https://repo.amd.com/rocm/whl/gfx1151/ "rocm[libraries,devel]" torch torchvision torchaudio  # AMD GPU (ROCm, gfx1151 = Ryzen AI Max+ 395/390/385)

uv sync
Optional Dependencies
Install an extra group with uv sync --extra <name> or pip install "torch-rechub[<name>]".
annoy: Adds Annoy-based approximate nearest neighbor indexing for retrieval serving.faiss: Adds FAISS-based vector indexing for high-performance retrieval experiments.milvus: Adds Milvus client support for external vector database serving workflows.bigdata: Adds PyArrow support for Parquet-based data loading and big-data preprocessing.onnx: Adds ONNX export, runtime inference, and model conversion dependencies.visualization: Adds model graph visualization support with TorchView and Graphviz.tracking: Adds WandB, SwanLab, and TensorBoardX integrations for experiment tracking.dev: Adds testing, linting, typing, and local development tooling.
🚀 Quick Start
Here's a simple example of training a model (e.g., DSSM) on the MovieLens dataset:
# Clone the repository (if using latest version)
git clone https://github.com/datawhalechina/torch-rechub.git
cd torch-rechub
uv sync

# Run matching example (cd into the script directory first, as scripts use relative data paths)
cd examples/matching
python run_ml_dssm.py

# Or with custom parameters:
python run_ml_dssm.py --model_name dssm --device 'cuda:0' --learning_rate 0.001 --epoch 50 --batch_size 4096 --weight_decay 0.0001 --save_dir 'saved/dssm_ml-100k'

# Run ranking example
cd ../ranking
python run_criteo.py
After training, model files will be saved in the saved/dssm_ml-100k directory (or your configured directory).
📂 Project Structure
torch-rechub/             # Root directory
├── README.md             # Project documentation
├── pyproject.toml        # Project configuration and dependencies
├── torch_rechub/         # Core library
│   ├── basic/            # Basic components
│   │   ├── activation.py # Activation functions
│   │   ├── features.py   # Feature engineering
│   │   ├── layers.py     # Neural network layers
│   │   ├── loss_func.py  # Loss functions
│   │   └── metric.py     # Evaluation metrics
│   ├── models/           # Recommendation model implementations
│   │   ├── matching/     # Matching models (DSSM/MIND/GRU4Rec etc.)
│   │   ├── ranking/      # Ranking models (WideDeep/DeepFM/DIN etc.)
│   │   └── multi_task/   # Multi-task models (MMoE/ESMM etc.)
│   ├── trainers/         # Training frameworks
│   │   ├── ctr_trainer.py    # CTR prediction trainer
│   │   ├── match_trainer.py  # Matching model trainer
│   │   └── mtl_trainer.py    # Multi-task learning trainer
│   └── utils/            # Utility functions
│       ├── data.py       # Data processing utilities
│       ├── match.py      # Matching utilities
│       ├── mtl.py        # Multi-task utilities
│       └── onnx_export.py # ONNX export utilities
├── examples/             # Example scripts
│   ├── matching/         # Matching task examples
│   ├── ranking/          # Ranking task examples
│   └── generative/       # Generative recommendation examples (HSTU, HLLM, etc.)
├── docs/                 # Documentation (VitePress, multi-language)
├── tutorials/            # Jupyter tutorials
├── tests/                # Unit tests
├── config/               # Configuration files
└── scripts/              # Utility scripts
💡 Supported Models
The framework currently supports 30+ mainstream recommendation models:
Ranking Models - 13
| Model | Paper | Description |
|---|---|---|
| DeepFM | IJCAI 2017 | FM + Deep joint training |
| Wide&Deep | DLRS 2016 | Memorization + Generalization |
| DCN | KDD 2017 | Explicit feature crossing |
| DCN-v2 | WWW 2021 | Enhanced cross network |
| DIN | KDD 2018 | Attention for user interest |
| DIEN | AAAI 2019 | Interest evolution modeling |
| BST | DLP-KDD 2019 | Transformer for sequences |
| AFM | IJCAI 2017 | Attentional FM |
| AutoInt | CIKM 2019 | Auto feature interaction learning |
| FiBiNET | RecSys 2019 | Feature importance + Bilinear |
| DeepFFM | RecSys 2019 | Field-aware FM |
| EDCN | KDD 2021 | Enhanced DCN |
Matching Models - 12
| Model | Paper | Description |
|---|---|---|
| DSSM | CIKM 2013 | Classic two-tower model |
| YoutubeDNN | RecSys 2016 | YouTube deep retrieval |
| YoutubeSBC | RecSys 2019 | Sampling bias correction |
| MIND | CIKM 2019 | Multi-interest dynamic routing |
| SINE | WSDM 2021 | Sparse interest network |
| GRU4Rec | ICLR 2016 | GRU for sequences |
| SASRec | ICDM 2018 | Self-attentive sequential |
| NARM | CIKM 2017 | Neural attentive session |
| STAMP | KDD 2018 | Short-term attention memory priority |
| ComiRec | KDD 2020 | Controllable multi-interest |
Multi-Task Models - 5
| Model | Paper | Description |
|---|---|---|
| ESMM | SIGIR 2018 | Entire space multi-task |
| MMoE | KDD 2018 | Multi-gate Mixture-of-Experts |
| PLE | RecSys 2020 | Progressive Layered Extraction |
| AITM | KDD 2021 | Adaptive Information Transfer |
| SharedBottom | - | Classic shared bottom |
Generative Recommendation - 3
| Model | Paper | Description |
|---|---|---|
| HSTU | Meta 2024 | Hierarchical Sequential Transduction Units, powering Meta's trillion-parameter RecSys |
| HLLM | 2024 | Hierarchical LLM for recommendation, combining LLM semantic understanding |
| TIGER | NeurIPS 2023 | T5-based generative retrieval for recommendation with semantic ID generation |
📊 Supported Datasets
The framework provides built-in support or preprocessing scripts for the following common datasets:
- MovieLens
- Amazon
- Criteo
- Avazu
- Census-Income
- BookCrossing
- Ali-ccp
- Yidian
- ...
The expected data format is typically an interaction file containing:
- User ID
- Item ID
- Rating (optional)
- Timestamp (optional)
For specific format requirements, please refer to the example code in the tutorials directory. The examples/ directory already includes sample datasets in each scenario subdirectory, which you can use directly for quick experimentation and debugging.
You can easily integrate your own datasets by ensuring they conform to the framework's data format requirements or by writing custom data loaders.
🧪 Examples
All model usage examples can be found in /examples
Ranking (CTR Prediction)
from torch_rechub.models.ranking import DeepFM
from torch_rechub.trainers import CTRTrainer
from torch_rechub.utils.data import DataGenerator

dg = DataGenerator(x, y)
train_dataloader, val_dataloader, test_dataloader = dg.generate_dataloader(split_ratio=[0.7, 0.1], batch_size=256)

model = DeepFM(deep_features=deep_features, fm_features=fm_features, mlp_params={"dims": [256, 128], "dropout": 0.2, "activation": "relu"})

ctr_trainer = CTRTrainer(model)
ctr_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
ctr_trainer.export_onnx("deepfm.onnx")
Multi-Task Ranking
from torch_rechub.models.multi_task import SharedBottom, ESMM, MMOE, PLE, AITM
from torch_rechub.trainers import MTLTrainer

task_types = ["classification", "classification"]
model = MMOE(features, task_types, 8, expert_params={"dims": [32,16]}, tower_params_list=[{"dims": [32, 16]}, {"dims": [32, 16]}])

mtl_trainer = MTLTrainer(model)
mtl_trainer.fit(train_dataloader, val_dataloader)
auc = ctr_trainer.evaluate(ctr_trainer.model, test_dataloader)
mtl_trainer.export_onnx("mmoe.onnx")
Matching Models
from torch_rechub.models.matching import DSSM
from torch_rechub.trainers import MatchTrainer
from torch_rechub.utils.data import MatchDataGenerator

dg = MatchDataGenerator(x, y)
train_dl, test_dl, item_dl = dg.generate_dataloader(test_user, all_item, batch_size=256)

model = DSSM(user_features, item_features, temperature=0.02,
             user_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             },
             item_params={
                 "dims": [256, 128, 64],
                 "activation": 'prelu',
             })

match_trainer = MatchTrainer(model)
match_trainer.fit(train_dl)
match_trainer.export_onnx("dssm.onnx")
# For two-tower models, you can export user and item towers separately:
# match_trainer.export_onnx("user_tower.onnx", mode="user")
# match_trainer.export_onnx("item_tower.onnx", mode="item")
Model Visualization
# Visualize model architecture (Requires: pip install torch-rechub[visualization])
graph = ctr_trainer.visualization(depth=4)  # Generate computation graph
ctr_trainer.visualization(save_path="model.pdf", dpi=300)  # Save as high-resolution PDF
👨💻 Contributors
Thanks to all contributors!

🤝 Contributing
We welcome contributions in all forms! Please refer to CONTRIBUTING.md for detailed contribution guidelines.
We also welcome bug reports and feature suggestions through Issues.
📜 License
This project is licensed under the MIT License.
📚 Citation
If you use this framework in your research or work, please consider citing:
@misc{torch_rechub,
    title = {Torch-RecHub},
    author = {Datawhale},
    year = {2022},
    publisher = {GitHub},
    journal = {GitHub repository},
    howpublished = {\url{https://github.com/datawhalechina/torch-rechub}},
    note = {A PyTorch-based recommender system framework providing easy-to-use and extensible solutions}
}
📫 Contact
- Project Lead: 1985312383
- GitHub Discussions
⭐️ Star History
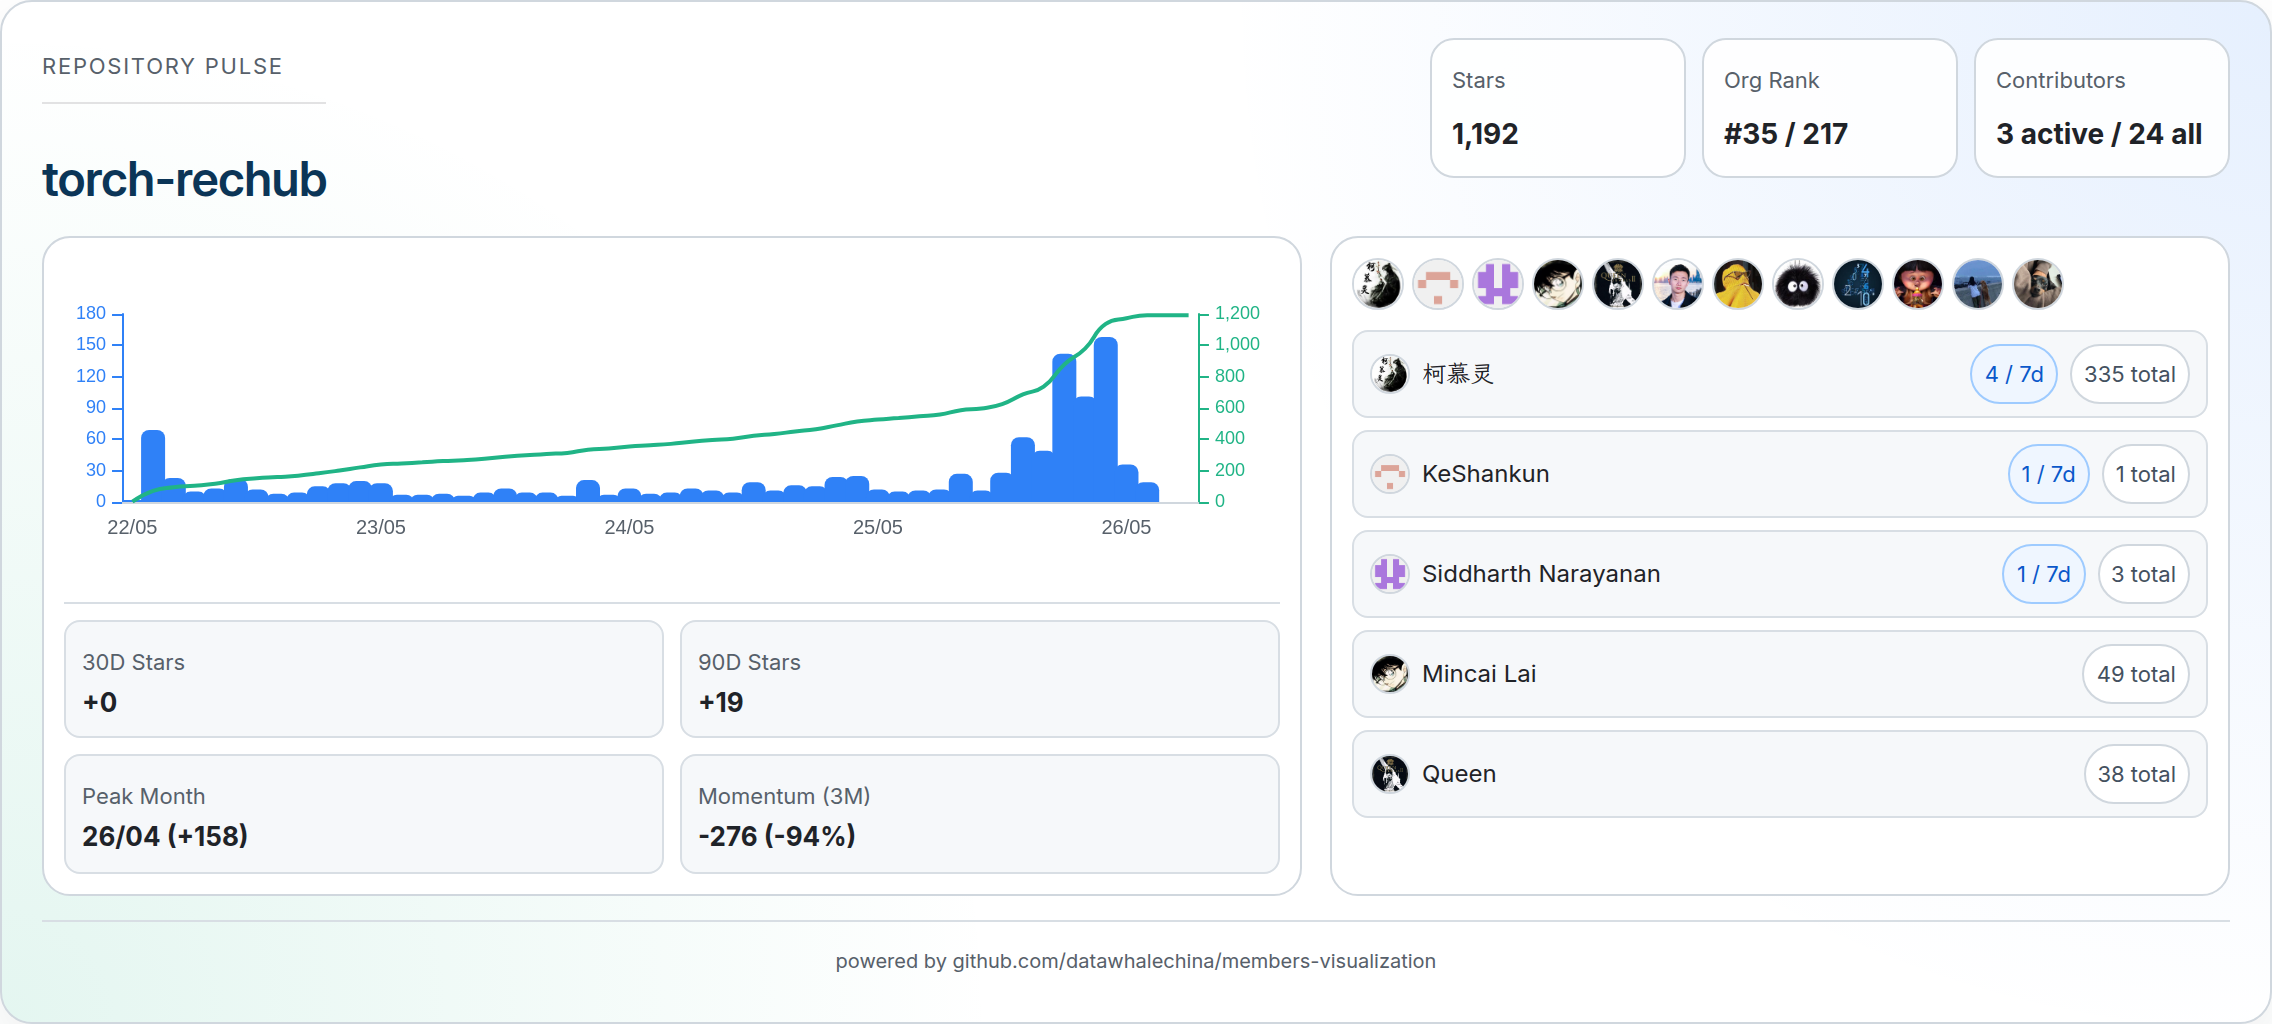
Last updated: [2026-08-03]

Paddle
PaddlePaddle·C++
飞桨核心框架,提供深度学习与机器学习的高性能单机及分布式训练能力,并支持跨平台部署,适合工业级模型开发。
深度学习框架+4国产 NPU进阶
24140+26.0kv3.4.02026-11-11 02:42 UTC
gpustack
gpustack·Python
统一管理 GPU 集群,调度 vLLM、SGLang 等推理引擎做高性能模型服务,还能按需开出可 SSH 登录的 GPU 实例。
GPU 集群管理+4国产 NPU
6017+20732v2.3.02026-11-10 14:54 UTC
mindspore
mindspore-ai·C++
华为开源的深度学习训练与推理框架,覆盖移动端、边缘和云场景,主打国产 NPU 生态适配。
深度学习框架+4国产 NPU
4723+47472026-10-28 08:28 UTC
vllm-ascend
vllm-project·Python
让 vLLM 推理引擎跑在华为昇腾 NPU 上的社区维护硬件插件,帮你在国产算力上部署大模型服务。
昇腾+4国产 NPU
3071+142.7kv0.30.02026-11-10 16:45 UTC