软件版本需严格对齐:Python 3.12、CANN 9.2.1、PyTorch 2.10.0、TorchNPU 2.10.0.post7,且 vLLM 版本须与 vllm-ascend 一致;需先具备昇腾 NPU 资源,README 建议通过 HiDevLab 申请;不同 vLLM 版本对应不同 releases 分支,选错分支可能不兼容。
README 未给出可直接复制的安装命令,请按官方 QuickStart 与 Installation 文档操作(https://docs.vllm.ai/projects/ascend/en/v0.30.0/installation.html) 硬件要求按 README 说明
需华为昇腾 NPU:Atlas 800I A2/A3 系列、Atlas 300I Duo、950PR&950DT 产品;系统限 Linux;README 未提及 CPU 运行或显存要求。
昇腾 / Ascend
让 vLLM 无缝跑在华为昇腾 NPU 上的社区维护硬件插件
让 vLLM 推理引擎跑在华为昇腾 NPU 上的社区维护硬件插件,帮你在国产算力上部署大模型服务。
核心能力
- 以硬件可插拔接口解耦昇腾 NPU 与 vLLM 集成
- 支持 Transformer、MoE、Embedding、多模态等主流开源模型
- 按 vLLM 版本维护 releases 分支,配套 CI 质量监控
- 提供 DeepWiki 知识库解读核心架构与源码
- 支持大规模专家并行(EP)部署
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- v0.30.0最新正式版2026-10-29 · 2026-10-29 14:07 UTC
v0.30.0 - 2026.10.29
This is the stable release of vLLM Ascend v0.30.0, built on the v0.29 release line and aligned with upstream vLLM v0.30.0 via the main2main pipeline. Building on v0.30.0rc1, this release integrates FlashMLA decode with DCP and DSpark, extends KV Pool layerwise pooling and PCP speculative decoding, hardens EPLB for the new quantization formats, and fixes the stability issues across attention, MoE, KV transfer, and Model Runner V2 execution reported during the RC cycle. It still focuses on the flagship models: DeepSeek V4.1, GLM-5.3, GLM-5.3-Flash, Qwen3.8-27B, DeepSeek V4-Flash/Pro, Kimi K3. Model or hardware combinations outside the scope declared in v0.30.0 are not part of the release claims. Please follow the official documentation to get started.
PR references marked with † were merged into the v0.30.0 release branch before v0.30.0rc1.
Notice: In this version, modelrunner still defaults to v1, but some models require v2 to be enabled for support. For specific information, please refer to the model tutorial. We plan to fully switch to Model Runner V2 in the next version.
Highlights
- DeepSeek V4.1: Added DeepSeek V4.1 support on Model Runner V2, enabled torch.compile, and sped up startup via in-place rotary embedding, reused filtered RoPE lookups, and removed redundant DSV4.1 indexer/SP copies; added the TurboQuant 4-bit latent KV cache for DSA sparse models (DeepSeek V4 Flash; A2/A3 only), including packed KV cache in the V1 runner; fixed ModelSlim-quantized DSV4 weight layout and added AscendStore preparation for V4.1, and packaged attention operators (QLI/QSLI/MQSMLA) with DSL. #17927 #16899 #17726 #17676 #18026 #18081 #16548 #16978 #17067 #17165 #17483 #16973†
- GLM-5.3: Enabled sparse SFA C8 (INT8 packed KV cache) for GLM-5.3-Flash and indexer MXFP4 for GLM-5.2, added the TurboQuant 4-bit latent KV cache for GLM-5.2/5.3 SFA (A2/A3 only), fixed GLM MRV2 issues and GLM-5.2 DSpark sequence lengths/per-request FIA bounds, fixed GLM-5.3-Flash small slot page inflation, and backported always-on reasoning for GLM-5.3. #17115 #17949 #18060 #17613 #17571 #17545 #17876†
- GLM-5.3-Flash: Added KV Pool support for non-layerwise pooling and Mamba in Mooncake layerwise, added layerwise memcache DRAM/SSD pooling, optimized Triton KPool and gated norm, supported GQA decode context parallelism and SFA-only DSA CP, and provided P/D and KV cache pool deployment guides. #16945 #17287 #17698 #17542 [#16478](https:/
- v0.30.0rc2pre-release2026-10-13 · 2026-10-13 15:24 UTC
查看更新说明
There is no code change in this release. It just contains a quick fix for Dockerfile to make the official Docker image build as expected. If you're using v0.30.0rc1 official docker image, please upgrade to v0.30.0rc2 instead. Otherwise, Please just ignore this release.
Highlights
- Upgrade CANN to 9.2.0_20260930220649 in Dockerfile to make sure the official Docker image build as expected.
Full Changelog: https://github.com/vllm-project/vllm-ascend/compare/v0.30.0rc1...v0.30.0rc2
- v0.30.0rc1pre-release2026-10-12 · 2026-10-12 13:46 UTC
查看更新说明
v0.30.0rc1 - 2026.10.12
This is vLLM Ascend v0.30.0rc1, a model-focused release built on the v0.29 release line and aligned with upstream vLLM v0.30.0 via the main2main pipeline. This release focuses on four flagship models: DeepSeek V4.1, GLM-5.3, GLM-5.3-Flash, and Qwen3.8-27B, and hardens the shared execution stacks they rely on (Model Runner V2, PCP/DCP parallelism, KV Cache Pool, and speculative decoding). Model or hardware combinations outside the scope declared below are not part of the release claims. Please follow the official documentation to get started.
Highlights
- DeepSeek V4.1: Added DeepSeek V4.1 support on Model Runner V2, enabled torch.compile, and sped up startup via in-place rotary embedding, reused filtered RoPE lookups, and removed redundant DSV4.1 indexer/SP copies; added the TurboQuant 4-bit latent KV cache for DSA sparse models (DeepSeek V4 Flash; A2/A3 only), including packed KV cache in the V1 runner; fixed ModelSlim-quantized DSV4 weight layout and added AscendStore preparation for V4.1, and packaged attention operators (QLI/QSLI/MQSMLA) with DSL. #17927 #16899 #17726 #17676 #18026 #18081 #16548 #16978 #17067 #17165 #17483 #16973
- GLM-5.3: Enabled sparse SFA C8 (INT8 packed KV cache) for GLM-5.3-Flash and indexer MXFP4 for GLM-5.2, added the TurboQuant 4-bit latent KV cache for GLM-5.2/5.3 SFA (A2/A3 only), fixed GLM MRV2 issues and GLM-5.2 DSpark sequence lengths/per-request FIA bounds, fixed GLM-5.3-Flash small slot page inflation, and backported always-on reasoning for GLM-5.3. #17115 #17949 #18060 #17613 #17571 #17545 #17876
- GLM-5.3-Flash: Added KV Pool support for non-layerwise pooling and Mamba in Mooncake layerwise, added layerwise memcache DRAM/SSD pooling, optimized Triton KPool and gated norm, supported GQA decode context parallelism and SFA-only DSA CP, and provided P/D and KV cache pool deployment guides. #16945 #17287 #17698 #17542 #16478 #17990 #17987 #17773 #17946
- Qwen3.8-27B: Supported non-contiguous KV cache in hybrid linear-attention models, respected per-layer KV cache dtype and kept KV cache contiguous for paged attention, restored C8 V scales on hybrid cache page reassignment, restored Mamba block tables before deferred PP postprocessing, added the FLA NPU backend for GDN prefill, and f
- v0.27.1rc1pre-release2026-09-29 · 2026-09-29 11:55 UTC
查看更新说明
v0.27.1rc1 - 2026.09.24
This is the first release candidate of v0.27.1 for vLLM Ascend, aligned with upstream vLLM v0.27.1. This model-focused release adds MiniMax-M3 support on Atlas 800 A3 and 950DT Products, and new DeepSeek-V4-Flash support on 950DT Products. Other models and hardware combinations, such as Atlas 800 A2, were not sufficiently validated for this release. Models and hardware combinations outside this declared scope are not part of the v0.27.1rc1 release claim. Please follow the official documentation to get started.
Highlights
- MiniMax-M3 on Atlas 800 A3 and 950DT Products: Added BF16, W8A8, and ModelOpt-compatible MXFP8 serving paths, with optimized MSA index-score, top-k, FlashDecoding, tensor-parallel communication, and the 950DT Products FP8 sparse-attention path. #14412 #14539 #13142 #13987 #15897 #15926
- DeepSeek-V4-Flash on 950DT Products: Added the validated DSpark serving path, including DSpark integration with DSA-CP and SparseFlashMla-based BF16 KV sparse attention. Eligible compressor, indexer, sparse-attention, DSpark, and local DSA-CP metadata is built asynchronously on Model Runner V1. #13249 #13506 #13716 #15776
- Speculative-decoding and serving stability: Hardened sequence-length boundaries, empty-context handling, draft-state publication, rejection sampling, request token validation, and distributed MemCache initialization. #16513 #16720 #17276 #16215 #16161 #17308
Features
- Added a ModelOpt-compatible MXFP8 path for MiniMax-M3. With
--kv-cache-dtype fp8, MSA and index caches use native FP8 E4M3 while dense GQA layers use BF16 unless explicitly configured otherwise. #14412 #15897 #15926 - Added DeepSeek-V4-Flash DSpark on 950DT Products, including DSA-CP integration and SparseFlashMla-based BF16 KV sparse attention. #13249 #13506 #13716
- Added DeepSeek-V4-Flash layerwise KV-cache reuse support for physical layers with multiple main cache specifications. #17081
- Integrated vLLM StartPlan so repeat startups can reuse measured KV-cache budgets and graph-capture results. #15654
- Integrated the GMM-SiTU operator for supported MoE paths. #15871
Hardware and Operator Support
Model Supported hardware in v0.27.1rc1 Release scope MiniMax-M3 Atlas 800 A3 and 950DT Products W8A8 on Atlas 800 A3 and W8A8C8 on 950DT Products; two-node 1P1D serving and KV Cache Pool deployment DeepSeek-V4-Flash 950DT Products W4A8C8; two-node 1P1D DSpark serving and KV - v0.23.0.post12026-09-22 · 2026-09-22 02:47 UTC
查看更新说明
v0.23.0.post1 - 2026.09.21
This is the first post release of vLLM Ascend v0.23.0. It includes the fixes, dependency updates, CI changes, and documentation updates merged into the v0.23.0 release branch after the v0.23.0 tag. Please follow the official documentation to get started.
Bug Fixes
- Fixed stale KV-cache writes during DP-aligned dummy runs by invalidating per-KV-group slot mappings before attention metadata construction. #15362
- Fixed MTP overlay prefix-cache precision on Atlas 300I DUO and kept W8A8 MXFP8 transformed buffers stable across RL weight reloads in ACL Graph mode. #14336 #13905
Other Changes
- Pinned the KV Pool dependencies to
memfabric_hybrid==1.2.0andmemcache_hybrid==1.2.0. #14352 - Consolidated installation guidance, GLM-5/5.2 and Kimi-K3 deployment instructions, PD and 310P notes, release metadata, navigation titles, English comments, and Chinese translations. #15449 #14242 #14338 #14634 #14698 #14713 #14906 #15998 #16106 #14382 #14387 #14436 #14579 #14684 #15534 #16202
- Added release-branch nightly and weekly model configurations and installed
concurrent-log-handlerin release images. #14559 #14645 #14739 #16191
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。

Latest News 🔥
- [2026/10] We released the new official version v0.30.0! Please follow the official guide to start using vLLM Ascend Plugin on Ascend.
- [2026/08] We released the new official version v0.23.0! Please follow the official guide to start using vLLM Ascend Plugin on Ascend.
- [2026/05] We released the new official version v0.18.0! Please follow the official guide to start using vLLM Ascend Plugin on Ascend.
- [2026/02] We released the new official version v0.13.0! Please follow the official guide to start using vLLM Ascend Plugin on Ascend.
- [2025/12] We released the new official version v0.11.0! Please follow the official guide to start using vLLM Ascend Plugin on Ascend.
- [2025/09] We released the new official version v0.9.1! Please follow the official guide to start deploying large-scale Expert Parallelism (EP) on Ascend.
- [2025/08] We hosted the vLLM Beijing Meetup with vLLM and Tencent! Please find the meetup slides.
- [2025/06] User stories page is now live! It kicks off with LLaMA-Factory/verl/TRL/GPUStack to demonstrate how vLLM Ascend assists Ascend users in enhancing their experience across fine-tuning, evaluation, reinforcement learning (RL), and deployment scenarios.
- [2025/06] Contributors page is now live! All contributions deserve to be recorded, thanks for all contributors.
- [2025/05] We've released the first official version v0.7.3! We collaborated with the vLLM community to publish a blog post sharing our practice: Introducing vLLM Hardware Plugin, Best Practice from Ascend NPU.
- [2025/03] We hosted the vLLM Beijing Meetup with vLLM team! Please find the meetup slides.
- [2025/02] vLLM community officially created vllm-project/vllm-ascend repo for running vLLM seamlessly on the Ascend NPU.
- [2024/12] We are working with the vLLM community to support [RFC]: Hardware pluggable.
Overview
vLLM Ascend (vllm-ascend) is a community maintained hardware plugin for running vLLM seamlessly on the Huawei Ascend NPU.
It is the recommended approach for supporting the Ascend backend within the vLLM community. It adheres to the principles outlined in the [RFC]: Hardware pluggable, providing a hardware-pluggable interface that decouples the integration of the Ascend NPU with vLLM.
By using vLLM Ascend plugin, popular open-source models, including Transformer-like, Mixture-of-Experts (MoE), Embedding, Multi-modal LLMs can run seamlessly on the Ascend NPU.
For detailed information on supported models and features, please refer to the support matrix.
DeepWiki
DeepWiki is a dynamic knowledge base collaboratively maintained by the community and AI, designed to provide you with deeper technical insights beyond conventional documentation. If official documentation serves as a "quick start" guide to help you get going, the DeepWiki is your technical companion for "deep understanding". Here, you can explore: core architecture and design principles, key source code interpretations, technical context, and decision-making logic.
Whether you are a performance tuner looking to deploy vLLM-Ascend in production or a contributor aiming to build upon it for secondary development, DeepWiki offers invaluable references for you. Welcome to explore now and join us in delving deep into the technical core of vLLM-Ascend.
Prerequisites
- Hardware: Atlas 800I A2 series, Atlas 800I A3 series, Atlas 300I Duo, 950PR&950DT Products
- OS: Linux
- Software:
- Python == 3.12
- CANN == 9.2.1 (For Ascend HDK version, please refer to the Release Notes)
- PyTorch == 2.10.0, TorchNPU == 2.10.0.post7
- vLLM (the same version as vllm-ascend)
Accessing Ascend NPU
If you need to access Ascend NPU computing resources for development or testing, please visit the HiDevLab - Online Development page on the HiDevLab platform to apply for and use them.
Getting Started
Please use the following recommended versions to get started quickly:
| Version | Release type | Doc |
|---|---|---|
| v0.30.0 | Latest stable version | See QuickStart and Installation for more details |
| v0.23.0 | stable version | See QuickStart and Installation for more details |
Branch
vllm-ascend has a main branch and a dev branch.
- main: main branch, corresponds to the vLLM main branch, and is continuously monitored for quality through Ascend CI.
- releases/vX.Y.Z: development branch, created alongside new releases of vLLM. For example,
releases/v0.13.0is the dev branch for vLLMv0.13.0version.
Below are the maintained branches:
| Branch | Status | Note |
|---|---|---|
| main | Maintained | CI commitment for vLLM main branch and vLLM v0.32.0 tag |
| releases/v0.13.0 | Maintained | Only bug fixes are allowed, and no new release tags anymore. |
| releases/v0.18.0 | Maintained | CI commitment for vLLM 0.18.0 version |
| releases/v0.23.0 | Maintained | CI commitment for vLLM 0.23.0 version |
| releases/v0.30.0 | Maintained | CI commitment for vLLM 0.30.0 version |
| rfc/ | Maintained | Feature branches for collaboration |
Please refer to Versioning policy for more details.
Contributing
See CONTRIBUTING for more details, which is a step-by-step guide to help you set up the development environment, build and test.
We welcome and value any contributions and collaborations:
- Please let us know if you encounter a bug by filing an issue
- Please use User forum for usage questions and help.
Weekly Meeting
- vLLM Ascend Weekly Meeting: https://tinyurl.com/vllm-ascend-meeting
- Wednesday, 15:00 - 16:00 (UTC+8, Convert to your timezone)
License
Apache License 2.0, as found in the LICENSE file.

Paddle
PaddlePaddle·C++
飞桨核心框架,提供深度学习与机器学习的高性能单机及分布式训练能力,并支持跨平台部署,适合工业级模型开发。
深度学习框架+4国产 NPU
24140+26.0kv3.4.02026-11-10 09:44 UTC
gpustack
gpustack·Python
统一管理 GPU 集群,调度 vLLM、SGLang 等推理引擎做高性能模型服务,还能按需开出可 SSH 登录的 GPU 实例。
GPU 集群管理+4国产 NPU
6009+20730v2.3.02026-11-10 14:54 UTC
mindspore
mindspore-ai·C++
华为开源的深度学习训练与推理框架,覆盖移动端、边缘和云场景,主打国产 NPU 生态适配。
深度学习框架+4国产 NPU
4723+47472026-10-28 08:28 UTC
cube-studio
data-infra·Python
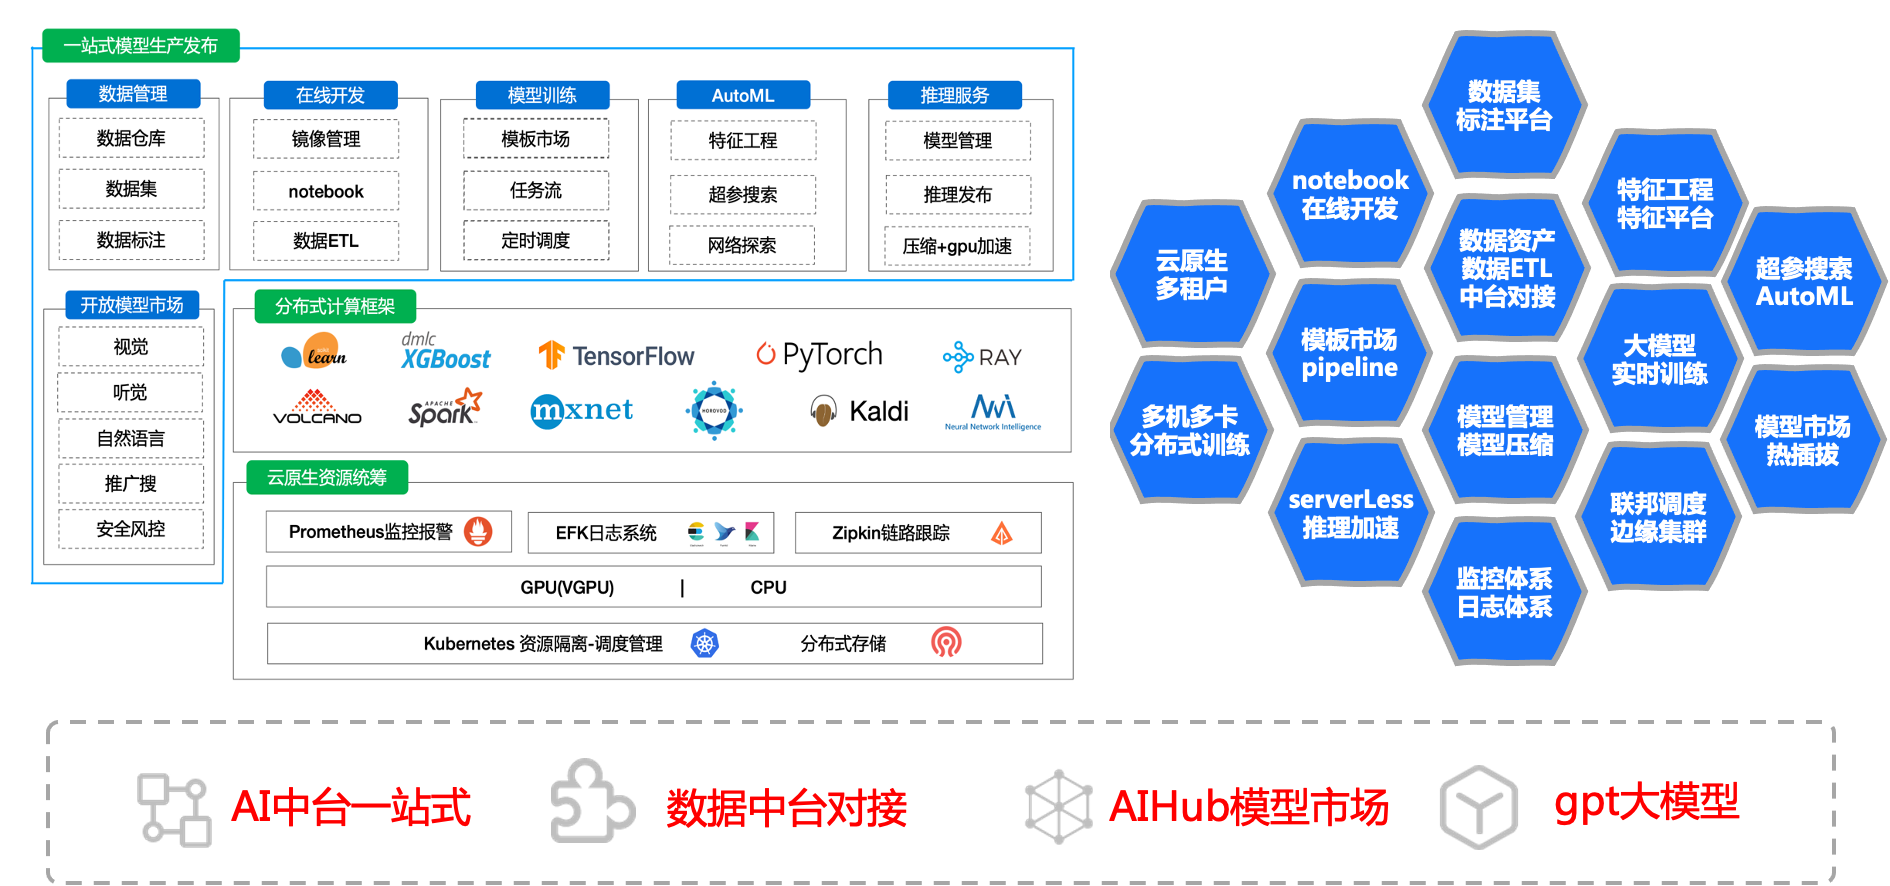
开源云原生一站式机器学习与大模型平台,覆盖拖拉拽 pipeline 编排、多机多卡训练、推理服务和 MaaS,支持昇腾等国产异构算力调度。
云原生AI平台+4国产 NPU
2604+8224v2026.09.012026-10-12 12:57 UTC