PyPI 上分 aimet-torch 和 aimet-onnx 两个包,按框架分别安装;从源码构建需在 Docker 环境中进行;部分高级技巧仅支持 PyTorch,如 OmniQuant 不支持 ONNX。
aimet
qualcomm活跃维护面向已训练神经网络模型的量化与压缩库,提供剪枝、量化等高级技术,帮助在部署前压缩模型体积、降低推理开销。
AIMET is a library that provides advanced quantization and compression techniques for trained neural network models.
2.43.0发布于 2026-10-30 05:21 UTC2,744star +1 / 7 天477fork同步于 2026-11-10 11:43 UTC
pip install aimet-torch
pip install aimet-onnx 硬件要求按 README 说明
README 未说明显存或 GPU 型号要求,仅提到量化后模型可部署到手机、笔记本等边缘设备,并给出在 Qualcomm Hexagon DSP 上比 Kryo CPU 快 5x-15x 的对比。
高通开源的模型量化与压缩工具库,帮你在几乎不掉精度的情况下把训练好的模型压到 INT8 上端侧
面向已训练神经网络模型的量化与压缩库,提供剪枝、量化等高级技术,帮助在部署前压缩模型体积、降低推理开销。
核心能力
- 提供 PTQ 后训练量化,含 Calibration、AdaRound、SeqMSE 等技巧
- 支持 QAT 量化感知训练,可量化 RNN、LSTM、GRU 等循环模型
- 用 Spatial SVD 与通道剪枝做模型压缩,并自动选择逐层压缩比
- 用 Data-Free 量化免训练数据完成 INT8 量化
- 提供权重范围与逐层压缩敏感度的可视化分析
容易踩的坑
内容由模型根据 README 生成,可能不完整或不准确,以官方文档为准。看原文 README
- 2.43.0Version 2.43.0最新正式版2026-10-30 · 2026-10-30 05:21 UTC
-
New Features
-
ONNX
- Support bfloat16 graphs in
QuantizationSimModel, including calibration, SeqMSE, AdaScale, AdaRound, AMP, cross-layer equalization, BatchNorm folding, SpinQuant, QuantAnalyzer, layer output dumping, PSNR/lite-mp evaluation, and LoRA adapters inaimet_onnx.peft(ff4f611, 901c4cf, 76e0b47, 28ace30, 36190d4, bea0d4e, fee0d31, 66e6e3b, 606ee2f, 46bbd5d, a3f7904, cfa85a5, c507684, e4092b7, e572b36, 7b28de8) - Quantize
Ifbranches inQuantizationSimModelbehind the subgraph flag (e4f515b, 3019fd1, 6a25cb6)
- Support bfloat16 graphs in
-
-
Bug fixes and Improvements
-
ONNX
- Redesign
aimet_onnx.experimental.lora: adapters are now prepared withaimet_onnx.peft.load_lora_adaptersinstead ofprepare_lora_onnx, and quantized with a smaller, renamed helper set (f371064) - Skip unsafe encoding tying through
Split(980d9d7) - Refactor
to_onnx_qdq()helpers to use theonnx_irAPI and fix a missing helper export (fd36575, f909daf) - Don't optimize frozen quantizers in AdaScale (9ca2127)
- Add
strictoption toencodings_to_onnx_qdqto skip unmatched encodings instead of raising (78f0907) - Tie
Scanbody inputs to their boundary quantizers (94ad369)
- Redesign
-
Torch
- Fix clipped QDQ scale gradients with zero-point shifts (aa91641)
-
Common
- Upgrade onnxsim to 0.7.0 (4867813)
- Windows (x64/arm64) and macOS
aimet-onnxwheels are now available on PyPI (81d3a20) - Update quantization recipe docs for Gemma 4 and Qwen3-VL (af9c406)
- Pin
torch<2.15andtorchvision<0.29.2in released wheels to avoid pulling CUDA 13 builds incompatible with CUDA 12.x drivers (cd33832)
-
-
- 2.42.0Version 2.42.02026-10-18 · 2026-10-18 23:31 UTC
查看更新说明
-
New Features
-
ONNX
- Add experimental support for quantizing
Scanbodies inQuantizationSimModel, including export and tied boundary quantizers (98862fd, 0b7790c, b1f9dcd) - Support
Scanmodels in SeqMSE and AdaScale (96708be, e4f5c5c) - Support Mamba2 in
analyze_llm_topology(d62b91b) - Add
strictoption toset_param_typeto skip incompatible quantizers (6f1416e)
- Add experimental support for quantizing
-
Common
- Add analysis pass support to GenAI Lab (d6e86ea)
- Add predicated-experts MoE adaptation for Qwen3-MoE and Qwen3.5-MoE to GenAI Lab (6b8e298)
- Enable subgraph quantization for ONNX
QuantizationSimModelin GenAI Lab (594ebe8)
-
-
Bug fixes and Improvements
-
ONNX
- Always save models with external data regardless of size (fe922f8)
- Fix stale quantization axes when loading encodings (bbaeb29)
- Preserve runtime reduction axes and patch
cumsumsupport in AdaScale's ONNX to torch conversion (db50a5c, c300055) - Keep
Splitsizes inline in SeqMSE's saved model (f69c5d6) - Align LLM configurator with GenAI Lab (64dcabd)
-
Torch
- Preserve zero-point shift in SeqMSE candidate encodings (5a979d8)
- Fix SpinQuant visual merger rotation compensation (dcd291d)
- Apply encoding post-processing to canonical
QuantizeLinear-DequantizeLinearpairs during ONNX export (e25d511) - Synchronize
precomputed_zero_point's device with offset (ee5ca3c) - Quantize
Qwen3MoeTopKRouterpre-softmax logits to match the transformers 4.x gate (5e9e565) - Fix
CallbackFuncimport in quant_analyzer notebook (26e7eca)
-
Common
- Fix import-time assertion error with onnx<1.18 (3c937bc)
- Delete unused legacy quantsim config files (093e72f)
- Use
configure_llmAPI in GenAI Lab (bbb2c97) - Fix Qwen 3.5 export on transformers >= 5.15 in GenAI Lab (1d669a6)
- Export dynamo backbones with one
torch.exportmode per torch version in GenAI Lab (7d13097) - Rename GenAI Lab linear-attention state I/O to
conv_state/recurrent_state(e078c16) - Fix GenAI Lab relative imports (6c0d5d3)
- Document v2.1.0 encoding spec and fix broken AdaScale/SpinQuant doc snippets (38dc892, 191d51b)
-
-
Deprecations
-
ONNX
- Move
adascale,spinquant,llm_topologyandllm_configuratorout ofaimet_onnx.experimentalinto top-levelaimet_onnx. The oldaimet_onnx.experimental.*import paths still work but emit a deprecation warning, and will be removed in AIMET 2.45 (94a2319)
- Move
-
Torch
- Move
adascaleandspinquantout ofaimet_torch.experimentalinto top-levelaimet_torch. The oldaimet_torch.experimental.*import paths still work but emit a deprecation warning, and will be removed in AIMET 2.45 (6360e0c) - Deprecate
save_encodings_to_json,load_encodings,load_and_freeze_encodings,set_and_freeze_param_encodingsandload_encodings_to_simin favor ofQuantizationSimModel.quantizer_state_dictandtorch.nn.Module.load_state_dict(c34cf34) save_checkpoint,load_checkpoint,check_accumulator_overflowandcompute_encodings_for_simsare deprecated and will be removed in AIMET 2.44 (c34cf34)
- Move
-
-
- 2.41.0Version 2.41.02026-10-05 · 2026-10-05 21:38 UTC
查看更新说明
-
Bug fixes and Improvements
-
ONNX
- Fix encoding propagation across the
Padop (5f80b04) - Fix AdaScale silently overriding per-quantizer weight bitwidth (4591f60)
- Remove quantizers from the
onnx_irmodel instead ofModelProtoduring export (6a6824d)
- Fix encoding propagation across the
-
Torch
- Fix stale
ConnectedGraphproducts when an op output feeds the same consumer twice (db7a805) - Use a trivial encoding when an uninitialized quantizer receives an empty input (5561564)
- Restrict power-of-two scales to MXFP4 instead of all FP4 quantizers (065e5a0)
- Fix stale
-
Common
- Add compatibility with onnx 1.23.0 (88b4cb6)
-
-
- 2.40.0Version 2.40.02026-09-21 · 2026-09-21 19:34 UTC
查看更新说明
2.40.0
-
New Features
- ONNX
- Add
encodings_to_onnx_qdqto convert an ONNX model plus encodings into a QDQ model (fcfc439) - Add
session_options_kwargsargument toQuantizationSimModelto set onnxruntime session options (c173926) - Accept an explicit
LlmTopologyinapply_spinquantandapply_adascale(00c6089, c548be0) - Enable FP8 (
float8e4m3fn,float8e5m2) quantization simulation on both CPU and CUDA, completing FP8 support alongside ONNX QDQ export (644c7bd)
- Add
- Torch
- Implement
set_weight_quantizer_to_nvfp4_int8API (05cc606)
- Implement
- ONNX
-
Bug fixes and Improvements
-
ONNX
- Fix calibration state restoration in
QuantizationSimModel(df58875) - Analyze LLM topology and run SpinQuant on
onnx_irinstead ofConnectedGraph(23633b1, 7b9aef6, 092a9dc) - Add all kv-cache inputs/outputs to
LlmTopology(68e24d2) - Drop ignored
connected_graphparameter fromget_decoder_block_boundaries(2d71c85) - Auto-upcast fp16 AdaScale blocks to bf16 (1f03b7c)
- Default to using all float outputs in
make_psnr_eval_fn(5c41452)
- Fix calibration state restoration in
-
Torch
- Fix device mismatch upon
.to()for qmodules with pre-quantized parameters (4111e41) - Fix fp4-int8 dynamo export bug (68588d4)
- Fix device mismatch upon
-
Common
- Exclude depthwise Conv/ConvTranspose from supergroups and fix false negatives in depthwise conv detection (7729c97, 2a6b723)
- Publish a single wheel per platform instead of
+cpu/+cuXXXvariants to the GitHub release (4fc12d8)
-
-
- 2.39.0Version 2.39.02026-09-08 · 2026-09-08 20:37 UTC
查看更新说明
2.39.0
-
New Features
- ONNX
- Support tuple of
(param_type, act_type)in the LiteMP API (64ecf7e)
- Support tuple of
- Torch
- Implement NVFP4 JSON encoding export (b0c8d15)
- Implement NVFP4 ONNX QDQ export (ddcc3d1, 86fe90e)
- Implement LPBQ export in v2.1.0 encoding format (607c5dc)
- ONNX
-
Bug fixes and Improvements
-
ONNX
- Fix loading encodings to fp16 sims (bb616e9)
- Fix matmul exception rule triggering with float16 input (20440b5)
- Avoid protobuf 2GB serialize+reparse cap when duplicating shared ONNX initializers (7e31da0)
- Place online SpinQuant R1 rotation at the final residual for models with no lm_head (03e40db)
-
Torch
- Fix quantsim init failure for models with an int-to-float Cast op (217d66d)
- Derive ONNX channel/block axis safely from input shape during export (796046c)
- Reduce memory footprint of the
_decompose_prequantized_tensorearly-exit check and full grid search (e04d5ca, b2ef967) - Remove
input_dtypefrom LPBQ JSON encoding v2.1.0 (99d637b)
-
Common
- Derive FP8 scales from the raw observed range instead of the quantization-grid-snapped range (058e4d5)
-
-
用户点评
登录用户的真实使用记录,可按版本和硬件筛选共 0 条
还没有人点评。第一个说出真实体验的人最有价值。

AI Model Efficiency Toolkit (AIMET)
AIMET is a software toolkit for quantizing trained ML models.
AIMET improves the runtime performance of deep learning models by reducing compute load and memory footprint. Models quantized with AIMET facilitate its deployment on edge devices like mobile phones or laptops by reducing memory footprint.
AIMET employs post-training and fine-tuning techniques to minimize accuracy loss during quantization and compression. AIMET supports models from the ONNX and PyTorch frameworks.

AIMET is designed to work with PyTorch and ONNX models.
You can find models quantized with AIMET on Qualcomm AI Hub Models - a collection of optimized and quantized models.
Why AIMET?

- Advanced quantization techniques: Inference using integer runtimes is significantly faster than using floating-point runtimes. For example, models run 5x-15x faster on the Qualcomm Hexagon DSP than on the Qualcomm Kyro CPU. In addition, 8-bit precision models have a 4x smaller footprint than 32-bit precision models. However, maintaining model accuracy when quantizing ML models is often challenging. AIMET solves this using novel techniques like Data-Free Quantization that provide state-of-the-art INT8 results on several popular models.
- Supports advanced model compression techniques that enable models to run faster at inference-time and require less memory
- AIMET is designed to automate optimization of neural networks avoiding time-consuming and tedious manual tweaking. AIMET also provides user-friendly APIs that allow users to make calls directly from their PyTorch pipelines.
Please visit the AIMET on Github Pages for more details.
Quick Start
aimet-onnx and aimet-torch is available on PyPI.
Check our Quick Start to get started with latest AIMET package.
Build from source
To build the latest AIMET code from the source, see Build, install and run AIMET from source in Docker environment
Supported Features
Post-Training Quantization(PTQ)
Check out guide to get started on PTQ technique.
Following table summarizes basic technique such as Calibration to advanced techniques such as SeqMSE and Adaptive Rounding(AdaRound) that you can use with AIMET.
| Technique | ONNX | PyTorch | What does it do? |
|---|---|---|---|
| Calibration | ✅ | ✅ | Computes Quantization parameters |
| AdaRound | ✅ | ✅ | Rounds quantized weights |
| SeqMSE | ✅ | ✅ | Optimizes encodings for each layer |
| BatchNorm Folding | ✅ | ✅ | Folds batchnorm to bridge the gap between simulation and on-target |
| Cross Layer Equalization | ✅ | ✅ | Rescales the weight to reduce range imbalance |
| BatchNorm re-estimation | ✅ | ✅ | Re-estimates batchnorm statistics |
| AdaScale | ✅ | ✅ | Learns per-weight scales via blockwise optimization to minimize quantization error |
| OmniQuant | ❌ | ✅ | Optimizes quantized weights |
| SpinQuant | ✅ | ✅ | Reduces activation outliers via Hadamard rotations |
Quantization Aware Training(QAT)
AIMET supports Quantization Aware Training(QAT) via aimet-torch.
If you want to use both QAT and some of the advanced PTQ techniques from AIMET, we recommend the following workflow:
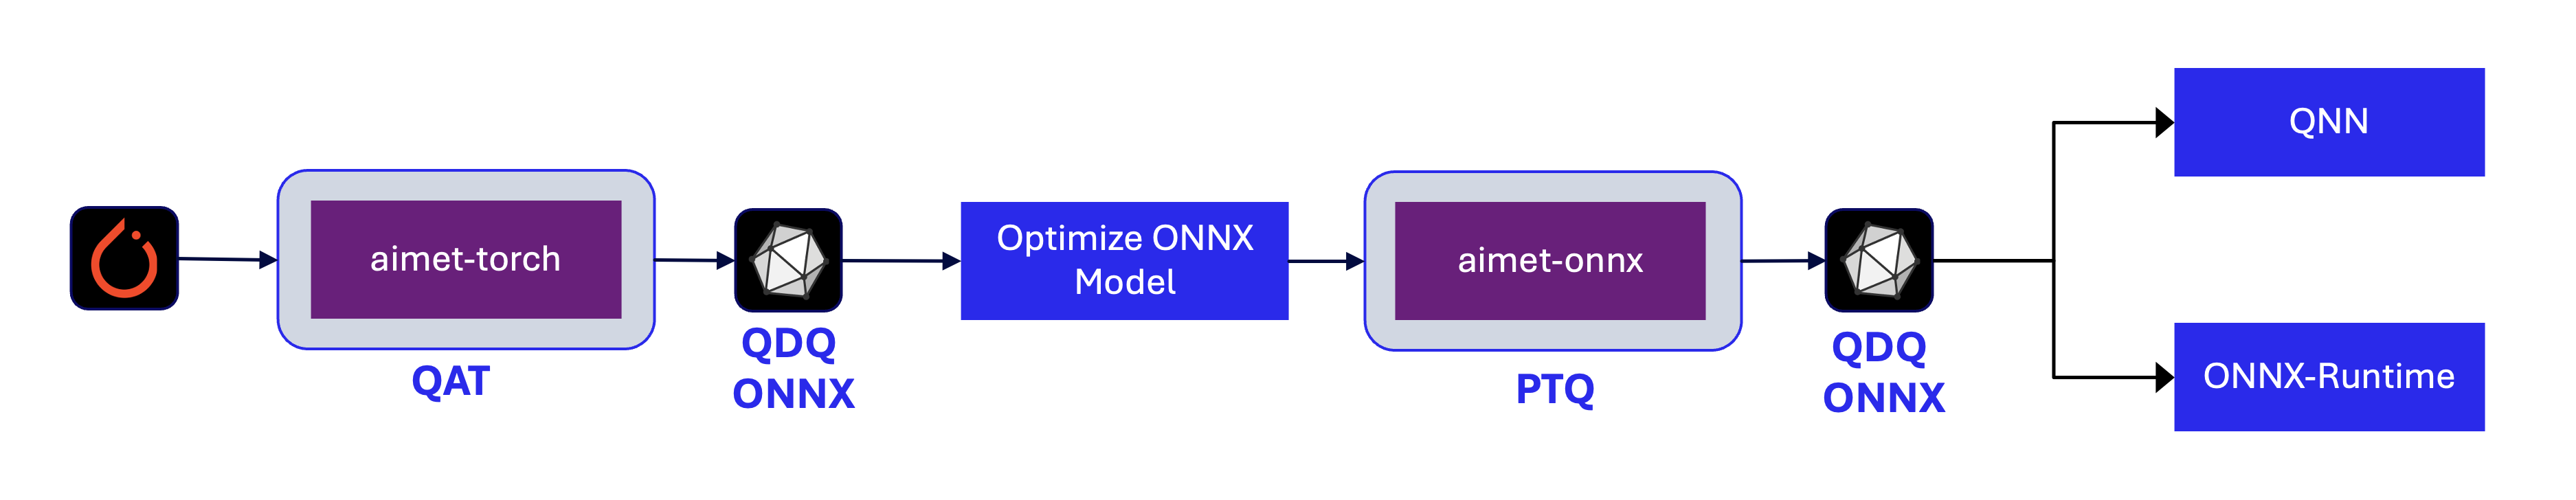
Check detailed QAT guide here
Model Compression
- Spatial SVD: Tensor decomposition technique to split a large layer into two smaller ones
- Channel Pruning: Removes redundant input channels from a layer and reconstructs layer weights
- Per-layer compression-ratio selection: Automatically selects how much to compress each layer in the model
Visualization
- Weight ranges: Inspect visually if a model is a candidate for applying the Cross Layer Equalization technique. And the effect after applying the technique
- Per-layer compression sensitivity: Visually get feedback about the sensitivity of any given layer in the model to compression
Results
AIMET can quantize an existing 32-bit floating-point model to an 8-bit fixed-point model without sacrificing much accuracy and without model fine-tuning.
The DFQ method applied to several popular networks, such as MobileNet-v2 and ResNet-50, result in less than 0.9% loss in accuracy all the way down to 8-bit quantization, in an automated way without any training data.
Resources
Contributions
Thanks for your interest in contributing to AIMET! Please read our Contributions Page for more information on contributing features or bug fixes. We look forward to your participation!
Team
AIMET aims to be a community-driven project maintained by Qualcomm Innovation Center, Inc.
License
AIMET is licensed under the BSD 3-clause "New" or "Revised" License. Check out the LICENSE for more details.
headroom
headroomlabs-ai·Python
在工具输出、日志、文件和 RAG 片段进入 LLM 前先做压缩,编码 Agent 省约 20% token,JSON 省 60-95%,答案不变。提供库、代理和 MCP 服务器三种用法。
上下文压缩+4量化
79284+2396.2kv0.43.12026-11-10 05:22 UTC

llmfit
AlexsJones·Rust
一条命令就能从数百个模型和供应商里筛出适合你硬件配置的本地大模型,省去逐个试跑和查显存的麻烦。
本地推理+4量化
38870+1432.5kv1.1.202026-11-10 10:03 UTC
PaddleNLP
PaddlePaddle·Python
基于飞桨的 NLP 与大模型开发库,提供丰富模型库,覆盖 BERT、ERNIE、LLaMA 等,支持分布式训练、压缩和文档智能等任务。
大模型开发库+4量化
129863.0krl-v1.0.02026-05-23 02:54 UTC

bitsandbytes
bitsandbytes-foundation·Python
让大模型在普通显卡上跑起来的 PyTorch 量化库,支持 8-bit 和 4-bit 权重压缩,也是 QLoRA 微调背后的核心依赖。
量化+4量化
85369440.50.22026-11-02 14:36 UTC